# Openship documentation
URL: https://openship.io/docs.md
Deploy applications, operate your infrastructure, and build integrations with Openship.
Openship builds and deploys applications from Git repositories, local folders, generated files, and app
templates. Run workloads on your machine, a connected server, or Openship Cloud.
## Start here
## Find a task
| Task | Read |
| --- | --- |
| Deploy from Git or a folder | [Deployment guides](/docs/guides#deploy) |
| Configure domains, secrets, and storage | [Application configuration](/docs/guides#configure) |
| Inspect logs, back up data, or fix a failure | [Operations](/docs/guides#operate) |
| Move projects or an installation | [Migration guides](/docs/guides#move) |
| Learn the dashboard | [Dashboard guide](/docs/dashboard) |
| Call HTTP endpoints | [API reference](/docs/api) |
| Connect an AI tool | [MCP guide](/docs/mcp) |
## Key concepts
An **organization** owns projects and grants access to its members. A **project** holds source and
configuration. A **deployment** is one build and release of that project. A **service** is a workload
inside a project, such as an application or database.
See [core concepts](/docs/getting-started/core-concepts) for environments, runtimes, servers, and domains.
---
# MCP
URL: https://openship.io/docs/mcp.md
Let AI clients like Claude drive your Openship instance as tools, over the Model Context Protocol.
import { Step, Steps } from 'fumadocs-ui/components/steps';
**MCP (Model Context Protocol)** is a standard way for AI clients — Claude, Cursor, VS Code Copilot, and
others — to call an app's features as *tools*. Point one of those clients at Openship and it can list your
projects, kick off deployments, check logs, add domains, and more — using the exact same permissions you'd
have yourself.
The important part: it's not a second, looser door into Openship. **Every tool call re-runs the full auth
and permission stack**, so an agent can only ever see and do what its credential is allowed to — nothing more.
Everything below is set up under **Settings → MCP**. That tab shows the exact endpoint for *your* instance,
a per-client "add" recipe (Claude Code, Codex, Cursor, VS Code, Claude Desktop, Windsurf, Zed), and the list
of clients you've already connected.
## The endpoint
There's one endpoint, and it's the same on self-hosted and Openship Cloud:
```
POST /api/mcp
```
So on your instance that's `https:///api/mcp`. A few things worth knowing up front:
- It's a stateless **Streamable-HTTP JSON-RPC 2.0** endpoint — request in, response out.
- It's **`POST`-only**. A `GET` returns `405` (there's no server→client stream to open).
- **No batching** — send one JSON-RPC message per request, not an array.
You rarely type this URL by hand. **Settings → MCP** shows it pre-filled and gives you a copy button.
## Connect a client
There are two ways to authenticate, and most clients pick one for you. Use the tab that matches your client.
Openship is a standards-compliant **OAuth 2.1** MCP server, so capable clients need nothing but the URL.
### Paste the endpoint into your client
Give the client your endpoint — `https:///api/mcp`. In Claude Code that's one command:
```bash
claude mcp add --transport http openship https:///api/mcp
```
Codex registers the server and authorizes it as two commands:
```bash
codex mcp add openship --url https:///api/mcp
codex mcp login openship
```
Other clients take it through their own UI; **Settings → MCP** has the exact snippet for each one.
### Approve it in the browser
For most clients this happens on the first connect: a browser window opens by itself. With Codex it's the
explicit `codex mcp login openship` above — the server is registered without it, but every call comes back
unauthorized until you run it.
Either way, that browser page is where you **choose what the client may do** — read-only or full control,
and either all resources or a specific set of projects, servers, and repositories. No credential to copy
or paste.
### You're connected
The client can now call tools within exactly the scope you approved. The connection shows up under
**Settings → MCP → Connected clients**, where you can disconnect it at any time.
Your choices are stored as the client's grant — the same grant model as a scoped [personal access
token](/docs/api/tokens). The client can never exceed what you granted, or what you can access yourself.
The Codex **CLI, desktop app, and IDE extension** all read the same local MCP configuration, so adding
Openship once covers all three. Restart any of them that were already running — they read the config at
startup.
A **hosted** Codex task is a different environment. It doesn't inherit your machine's MCP config, and it can
only reach `https:///api/mcp` if that environment has network access to your instance. For a
private or LAN-only self-hosted Openship, it won't — the endpoint has to be reachable from wherever the agent
actually runs. Openship Cloud, or a self-hosted instance on a public hostname, is reachable; a
`localhost`/private-network endpoint is not. See [remote access](/docs/getting-started/installation) for
exposing an instance deliberately.
For clients without OAuth support — or when you want a fixed, narrowly-scoped credential in a config file —
authenticate with a **personal access token** as a bearer credential. There's no separate MCP credential.
Create the token under **Settings → Tokens** (see the [Tokens API](/docs/api/tokens)), then drop the endpoint
and token into your client's config:
```json
{
"mcpServers": {
"openship": {
"url": "https:///api/mcp",
"headers": { "Authorization": "Bearer opsh_pat_…" }
}
}
}
```
For Claude Code, add the header on the command:
```bash
claude mcp add --transport http openship https:///api/mcp \
--header "Authorization: Bearer opsh_pat_…"
```
Mint a **read-only** or **scoped** token for agents rather than handing over your full access. A read-only
token limits the agent to read tools; a scoped token confines it to exactly the projects, servers, and
repositories you grant — even below your own role.
## Every call is re-checked
This is the heart of the security model, and it's why MCP access is as safe as your token:
- Authenticating once resolves your **capability**, but that's used only to **filter `tools/list`** — so a
client isn't shown tools its token could never use.
- The real gate runs on **every `tools/call`**: the endpoint builds an internal request, forwards your
bearer, and dispatches it through the same routes, validation, auth middleware, and per-resource permission
check as a normal HTTP call.
A read-only token can only reach GET tools. A scoped token sees tools enabled by its grants, including
collection tools when it has the matching wildcard permission. A grant to one project does not authorize
listing every project. And if a `tools/call` touches something outside that scope, it comes back
`404` — the scope doing its job. For the full protocol details (JSON-RPC methods, negotiation, error codes),
see the [MCP API reference](/docs/api/mcp).
The **organization boundary** applies to MCP exactly as it does to a browser session: because every call
runs through the same per-resource permission check, an MCP client acts only within organizations you
belong to and can never reach another org's projects, servers, or secrets — a resource outside your
membership comes back `404`, just as it would in the dashboard. See [Isolation](/docs/security/isolation).
## Which tools map to which API
To see your **workspace ID**, ask the agent to call `get_permissions_workspaces` with no arguments.
Openship calls it `organizationId` in the API. The result lists workspace names and IDs, including empty
workspaces, and identifies the current workspace and any credential binding.
When installing an app or deploying Compose, pass the chosen `organizationId` alongside `body` on each
tool call. The server uses that exact workspace. If several destinations are available, the agent's
instructions tell it to clarify the destination before creating resources. See
[workspace selection](/docs/api/mcp#discover-and-select-a-workspace) for examples.
Tokens and OAuth connections created today are bound to one organization. To target another, authorize
the connection or create a token in that workspace. Selecting an ID cannot widen a credential's scope,
and it does not move an already installed app between organizations.
Tools aren't a separate feature set — each one **maps onto a permission-tagged REST route**, and the tool name
is built from that route's method and path. So `get_projects` is `GET /api/projects`, `post_domains` is
`POST /api/domains`, and `patch_projects_by_id` is `PATCH /api/projects/:id`. Call `tools/list` to see the
exact set your token can use.
Not every route is a tool: a route becomes one only when it **opts in**, so the set is a curated slice of the
API rather than the whole surface. Each exposed tool also carries two hints a client can surface —
`readOnlyHint` (the tool only reads) and `destructiveHint` (it deletes or tears something down) — so an agent
UI can flag a destructive call before it runs.
| Tool name (examples) | REST route | Reference |
|---|---|---|
| `get_permissions_workspaces` | `/api/permissions/workspaces` | [Workspace discovery](/docs/api/permissions#list-workspaces) |
| `get_projects`, `patch_projects_by_id` | `/api/projects` | [Projects API](/docs/api/projects) |
| `get_deployments`, `post_deployments_build_access` | `/api/deployments` | [Deployments API](/docs/api/deployments) |
| `get_projects_by_id_services`, `post_projects_by_id_services` | `/api/projects/:id/services` | [Services API](/docs/api/services) |
| `get_domains`, `post_domains` | `/api/domains` | [Domains API](/docs/api/domains) |
| `get_github_repos` | `/api/github` | [GitHub API](/docs/api/github) |
| `get_analytics` | `/api/analytics` | [Analytics API](/docs/api/analytics) |
| `get_notifications_channels` | `/api/notifications` | [Notifications API](/docs/api/notifications) |
| `get_settings`, `patch_settings_build_mode` | `/api/settings` | [Settings API](/docs/api/settings) |
| `get_projects_by_projectId_backup_policies`, `post_backup_policies_by_policyId_run` | `/api/backups` | [Backups API](/docs/api/backups) |
| `get_cloud_status` | `/api/cloud` | [Cloud API](/docs/api/cloud) |
| `get_system_servers_destinations` | `/api/system/servers/destinations` | [Desktop folder → Cloud](/docs/api/mcp#deploy-a-desktop-folder-on-cloud) |
| `get_jobs`, `post_jobs_by_key_run` | `/api/jobs` | [Jobs guide](/docs/guides/jobs) |
| `get_apps_catalog`, `post_apps` | `/api/apps` | [App catalog](/docs/api/apps) |
| `get_updates`, `post_updates_scan` | `/api/updates` | [Updating Openship](/docs/guides/updating) |
The `tokens`, `auth`, and `mcp` modules are hard-blocked from ever becoming tools — a full-access MCP token
can't mint itself a fresh credential or escape its own scope. Manage tokens and connected clients from the
dashboard or the [Tokens API](/docs/api/tokens), not from an agent.
The [generated MCP catalog](/docs/api/mcp-tools) publishes the current tool names, descriptions and
HTTP-only boundaries directly from the routes. The [cluster and scaling guide](/docs/guides/mcp-clusters-and-scaling)
covers private networking, automated k3s setup, application replica changes, recovery and cleanup.
Manual replica scaling is supported; metric-driven autoscaling and live worker joining are not implemented.
## Guided flows
Some tasks are a chain of calls in a specific order — deploying a repo, uploading a folder, installing a
catalog app. The server ships a small set of **prompts** (`prompts/list` / `prompts/get`) that spell those
chains out step by step, referencing the exact tools to call. Compatible clients surface them as
slash-commands or starters, so an agent can pick a flow and follow it rather than reverse-engineering the
order from the flat tool list. See the [MCP API reference](/docs/api/mcp#guided-flows-prompts) for the full
catalog.
## Verify from the terminal
To confirm a token works and see what it can do, ask for the tool list:
```bash
curl -s https:///api/mcp \
-H "Authorization: Bearer opsh_pat_…" \
-H "Content-Type: application/json" \
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list"}'
```
This returns exactly the tools that token is allowed to call.
## Troubleshooting
There's no bearer credential, or it's expired or revoked. The response includes a `WWW-Authenticate` header
so OAuth clients can start discovery; if you're using a static token, mint a fresh one under
**Settings → Tokens** and update your client config.
Expected. This is a request/response server with no server→client stream, so `GET /api/mcp` isn't supported.
Always `POST` your JSON-RPC message.
`tools/list` worked but a specific `tools/call` reports `404` — that's the token's scope working as intended.
It wasn't granted that resource. Re-authorize the client (or mint a token) with the resource included.
## Manage connected clients
Every OAuth client you've approved is listed under **Settings → MCP → Connected clients**, tagged with its
access level (read-only or full control) and how many resources it can reach. **Disconnect** revokes the
client's issued tokens immediately and drops its consent, so it has to re-authorize next time. The same list
and controls are available programmatically via the [Tokens API](/docs/api/tokens).
## Related guides
---
# Migrate from Coolify, Dokploy, or Dokku
URL: https://openship.io/docs/guides/migrate-from-coolify-dokploy-dokku.md
Move an existing self-hosted server onto Openship without redeploying from scratch — Openship scans your running Docker containers and adopts them in place, with a zero-downtime path and server-to-server moves.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Already running apps on **Coolify**, **Dokploy**, or **Dokku**? You don't rebuild them on Openship. Openship
**scans the Docker containers already running on your server and adopts them in place** — reusing the exact
image that's live right now, with no rebuild and, on the same server, no data move. It's a guided, one-click
import, and your workloads keep serving while it happens.
Every other platform here only deploys **new** workloads. Openship can point at a server's **existing**
running containers, read their domains and volumes, and take them over — including taking over the
`:80/:443` reverse proxy from Coolify/Dokploy/Dokku, rollback-safe.
## How the import works
Openship models the move as a short, reversible pipeline:
1. **Scan** *(read-only — nothing is changed)* — over SSH, Openship enumerates **all** containers, volumes,
and networks on the server (not just ones it owns), reads their compose config, and joins your existing
proxy's vhosts to each container by published port to recover its **current domains + SSL**.
2. **Adopt** *(records only)* — it creates a `services` project mirroring the running containers. Each
adopted service carries the container's **current image and no build context**, so Openship re-runs
exactly what's live and **never rebuilds**. Services come in **unexposed**, so routing is untouched at
import time.
3. **Take over the edge** *(later, opt-in, rollback-safe)* — when you add a domain, Openship journals your
old proxy's state, disables it, installs its **OpenResty** edge, and re-registers your vhosts + certs. If
anything fails — or the box reboots mid-way — it rolls back automatically.
4. **Cut over** *(opt-in, confirmed)* — only when you say so does it stop and remove the *old* containers.
Your source volumes are never touched.
## Before you start
Don't stop Coolify/Dokploy/Dokku's proxy *before* scanning — Openship reads your live domains and
certificates from it. You'll retire it later, and Openship does that step for you (and can roll it back).
- Migration is **self-hosted only** and needs `server:write` on the source (and target, for server-to-server).
- **Connect the source server to Openship over SSH first** (Servers → Add server). Your apps and their proxy
stay running throughout.
- You can safely stop the old platform's **control-plane app** at any time — your running app containers and
their proxy don't depend on it. Leave the *proxy* up until the takeover step.
## Migrate a server (step by step)
### Connect the server and scan
Add the server over SSH, then start the import. Openship scans it read-only and lists what it found — each
container with its recovered domain(s), ports, and volumes. (On a large or slow server, use the streaming
scan so the client doesn't time out.)
### Pick workloads (3-step wizard)
The wizard walks **select → link source → domains**. Your reverse proxy (Traefik / nginx / Caddy / …) is
**automatically excluded** from the workload set and left running untouched — Openship never adopts or
blind-stops it during import.
Review the detected proxy and discovery notices before proceeding. Traefik routes are matched by the
container's private network address as well as published ports, so services do not need a host port to keep
their domains. Imported environment values are saved in each service's **Environment** tab. With reuse in
place, edits are saved for the next environment reapply or redeploy; the existing container keeps running
with its current values.
### Choose a volume strategy — this decides downtime
This is the important choice:
- **Reuse in place** *(same server, default)* → **attach-live**: the running container is adopted as-is,
its records rebuilt from the live container, the current image reused. No move, no recreation.
**→ zero downtime.**
- **Copy**, or **any server-to-server move** → **deploy path**: originals are stopped for a consistent
volume copy, then a fresh deploy is verified to "ready." **→ a real downtime window** (polled up to ~20 min).
The preview may conservatively warn about "downtime" even for the zero-downtime reuse case. The **reuse
in-place** strategy is genuinely zero-downtime for the workload — the container is never stopped.
### Take over the domains + edge
When the migration includes domains, Openship prepares the target edge during migration. It shows which
existing sites belong to the selected project and services, then asks for confirmation before replacing
the proxy. Choosing **Migrate sites & take over** journals the old configuration, installs OpenResty on
`:80/:443`, and imports the existing sites and certificates, including sites outside the selected project.
If takeover fails, Openship attempts to restore the previous proxy and reports the recovery outcome.
Selected domains are attached to their migrated services and re-applied from the live containers. Existing
certificates are reused and pending verification is retried immediately. Routes that cannot be reproduced
are reported in discovery notices; review those before taking over. If routing or TLS still needs attention,
the migration keeps a warning and does not automatically remove the old deploy-set containers.
With reuse in place, your containers keep running. Requests can be interrupted briefly while `:80/:443`
moves from the old proxy to OpenResty. Copy and cross-server migrations also have the downtime described above.
### Verify, then cut over and remove the old platform
Confirm everything serves through Openship. Then run **cutover** (explicit, token-confirmed): it stops and
removes only the *old* deploy-set containers — **never your source volumes**. Once you're happy, remove
Coolify/Dokploy/Dokku entirely; Openship now owns the box.
Cutover **stops and removes the old workload**, so don't run it until the Openship-managed app is fully healthy:
it loads and serves traffic, your **data is intact** (sign in, open a record, check volumes/uploads and any
database), and every service is `RUNNING`. Cutover leaves your **source volumes untouched**, so the old
deploy-set stays as a fallback until you're certain. If anything's off — missing data, a service that won't
start, routing/TLS wrong — **don't cut over**; leave the old containers running and
[open an issue on GitHub](https://github.com/oblien/openship/issues) and we'll help.
## Server-to-server migration
Moving a whole stack from one host to another is the same flow, with the data streamed across:
- Named volumes and movable app-data mounts stream **A → B** directly (same daemon: a `tar → tar` copy; across
daemons: a gzip stream). System paths (`/proc`, `/sys`, `/var/lib/docker`, sockets, …) are never copied.
- Openship **refuses to overwrite a non-empty same-named volume** on the target, so you can't clobber data.
- Server-to-server always uses the **deploy path** (a downtime window), and it **can't move locally-built
images** — those have no registry to pull from on B, so take them over **in place on their current server**
instead.
## Why the architecture is different
Two things are worth understanding, because they're where Openship genuinely diverges from the others:
- **A programmable OpenResty edge.** Routing runs on OpenResty with a **database-driven, reload-free
per-route rules engine** — per-route rate limiting, IP/CIDR + country + user-agent bans, method/CIDR/country
allow-lists, and hotlink protection — pushed live into a shared dictionary with **no nginx reload and no
Redis**, plus built-in request/bandwidth analytics and a live log stream. Coolify and Dokploy expose Traefik
middlewares and Dokku exposes nginx templates that can approximate these rules; Openship's difference is that
it's a managed, reload-free, per-route surface — **not** that it does more at the protocol level (see the
honest caveats below).
- **A real desktop mode.** Openship ships a **native desktop app** that runs the entire control plane — API,
dashboard, embedded database, in-process jobs — **bound to loopback on your own machine**, with no-login
access granted only to same-machine (kernel-verified) callers and **nothing left running after you quit**.
It's the isolated, solo way to drive your servers; the always-on `openship up` CLI service is a separate mode.
## Honest comparison
All four are open-source, Docker-based, self-hosted PaaS tools, and they share most of the baseline. We're not
going to pretend otherwise — **migrate for the differences, not the essentials.**
**Shared essentials (all four do these):** git-push / webhook auto-deploy · Dockerfile builds · automatic
Let's Encrypt TLS with auto-renew · one-click databases · scheduled S3 backups · multi-server over SSH · REST
API + scoped tokens · a CLI · rollbacks · per-event notifications · **and an official MCP server** (Coolify's
is read-only, Dokploy's covers the full API, Openship's is write-capable). "Has an MCP server" is **not** a
reason to switch.
**The full picture** — differentiators in **bold**; `✓` built-in · `~` partial / manual / paid · `✗` not
available. Where a competitor leads (Coolify's 280+ catalog, Dokploy's HTTP/3, Dokku's zero-downtime default,
buildpack breadth), it's marked honestly.
**Deploys & builds**
| | Coolify | Dokploy | Dokku | Openship |
|---|:---:|:---:|:---:|:---:|
| Git push / webhook auto-deploy | ✓ | ✓ | ✓ | ✓ |
| Dockerfile & prebuilt-image deploy | ✓ | ✓ | ✓ | ✓ |
| **Source never passes through an always-on control plane** | ✗ cloned on the server | ✗ zip → server | ✗ push → host | **✓ desktop → target direct** |
| Docker Compose / multi-service | ✓ | ✓ | ✗ | ✓ |
| Buildpacks (Nixpacks / Heroku) | ✓ | ✓ | ✓ | ~ auto stack-detect |
| Rollback to a previous release | ✓ | ✓ | ✓ | ✓ |
| Per-PR preview environments | ✓ | ✓ | ~ | ~ |
| Zero-downtime *new* deploys | ~ health-gated | ~ health-gated | ✓ default | ~ health-gated |
**Servers & migration**
| | Coolify | Dokploy | Dokku | Openship |
|---|:---:|:---:|:---:|:---:|
| Multi-server over SSH | ✓ | ✓ | ~ K3s | ✓ |
| Server health / resource monitoring | ~ | ✓ | ~ plugin | ✓ |
| Fine-grained server access grants | ✗ | ~ ent. | ✗ | ✓ |
| **Adopt existing running containers** | ✗ | ✗ | ✗ | **✓** |
| **Server-to-server move (with data)** | ✗ | ✗ | ✗ | **✓** |
| **Leave management, keep apps + data running (re-importable)** | ✗ delete prunes managed containers | ✗ delete tears down | ✗ `apps:destroy` removes | **✓ record-only, re-adoptable** |
| **Relocate the whole instance into managed cloud — and back** | ✗ control-plane only | ✗ control-plane only | ✗ no managed cloud | **✓ instance dump → Cloud, reversible switch-back** |
| **Take over an existing reverse proxy** | ✗ | ✗ | ✗ | **✓** |
**Networking & edge**
| | Coolify | Dokploy | Dokku | Openship |
|---|:---:|:---:|:---:|:---:|
| Automatic Let's Encrypt TLS | ✓ | ✓ | ✓ | ✓ |
| Unlimited custom domains + wildcards | ✓ | ✓ | ✓ | ✓ |
| HTTP/3 (QUIC) | ✗ | ✓ | ✗ | ✗ |
| CDN / response caching | ✗ | ✗ | ✗ | ✗ |
| **Per-route rate limiting** | ~ Traefik mw | ~ Traefik mw | ~ nginx | **✓ UI, reload-free** |
| **IP / CIDR ban + allow-lists** | ~ mw | ~ mw | ~ nginx | **✓ UI** |
| **Country (geo) blocking** | ✗ | ✗ | ~ GeoIP module | **✓ built-in ** |
| **Bad-user-agent + hotlink protection** | ~ mw | ~ mw | ~ nginx | **✓ UI** |
| **Built-in request analytics** (traffic, status codes, top paths, geo) | ✗ add-on | ✗ add-on | ✗ | **✓** |
| **Live per-route request-log stream** | ~ proxy logs | ~ proxy logs | ~ files | **✓** |
| Resource metrics (CPU / memory / bandwidth) | ~ basic | ✓ | ~ plugin | ✓ |
The edge is where the gap is widest: every route gets **per-route rate limiting, IP/CIDR + country + user-agent
bans, and hotlink protection** from a UI (pushed live, no nginx reload), plus **built-in traffic analytics**
— requests, status codes, top paths, and **geo/country breakdowns** — and a **live per-route request-log
stream**. Coolify and Dokploy give you Traefik middlewares and bolt-on Grafana/Plausible; native
country-level blocking and built-in request analytics aren't there. (Honestly: it's *not* a CDN or WAF — no
HTTP/3, caching, or OWASP rules.)
**Data, team & platform**
| | Coolify | Dokploy | Dokku | Openship |
|---|:---:|:---:|:---:|:---:|
| One-click databases | ✓ 8 | ✓ 6 | ✓ 16 | ✓ catalog |
| Scheduled S3 backups + restore | ✓ | ✓ | ~ per-DB | ✓ |
| Volume backups | ~ | ✓ | ~ | ✓ |
| One-click app catalog | ✓ **280+** | ✓ | ~ community | ✓ curated |
| Teams / organizations | ✓ | ✓ | ~ Pro | ✓ |
| Fine-grained RBAC + audit log | ~ coarse | ~ ent. | ✗ | ✓ |
| Scoped API tokens (PAT) + CLI | ✓ | ✓ | ~ Pro | ✓ |
| Scheduled jobs / cron | ✓ | ✓ | ~ plugin | ✓ |
| Web dashboard | ✓ | ✓ | ✗ Pro | ✓ |
| MCP for AI agents | ✓ read-only | ✓ full-API | ~ community | ✓ write + re-auth |
| **Native desktop app — no always-on daemon, loopback isolation** | ✗ | ✗ | ✗ | **✓** |
| **Built-in full mail server** | ✗ | ✗ | ~ community | **✓** |
| **Self-hosted + managed-cloud from one instance** | ✗ control-plane only | ✗ | ✗ | **✓ Cloud runs the workload** |
The defensible reasons to move are the bold rows: **adopting what's already running**, **moving stacks between
servers with their data**, **leaving without lock-in** (a record-only removal drops just Openship's record and
leaves your apps + data running on your box, re-importable later) or **relocating the whole instance into
Openship Cloud and back**, **taking over your existing proxy**, the **programmable edge**, the **built-in mail
server**, and the **self-hosted + cloud hybrid** where the cloud target actually runs your workload (unlike a
managed control plane that still leans on your own servers). None of the other three can adopt a running stack,
move one with its data, or hand it back to you still running — every "migration" is a manual rsync-and-redeploy
or a community script.
Two more are structural rather than feature checkboxes. **Desktop mode has no always-on daemon** — the control
plane runs on your laptop only while the app is open, so nothing sits in the background burning resources; the
other three all need a control-plane server running around the clock. And in that mode **your source is never
uploaded to a control plane**: the desktop reads your folder straight off disk, or the target server clones from
your git using your forwarded credentials, so the code goes disk-or-git → server directly. Coolify clones on the
Coolify server, Dokploy takes a zip upload, and Dokku takes a `git push` — in every case your code lands on a
long-lived control-plane box first. (For a self-hosted Openship instance the trade-off is the same as theirs —
this edge is specific to desktop mode.)
## Honest caveats
- **Zero-downtime is narrow, not blanket.** Only a **same-server "reuse in place"** import is truly
zero-downtime. Same-server "copy" and **every** server-to-server move stop the originals for a consistent
copy and verify a fresh deploy (up to ~20 min) — a real window. The edge takeover briefly interrupts
`:80/:443` while OpenResty installs.
- **The edge is programmable access rules + analytics — not a CDN and not a WAF.** There's no HTTP/3, no
brotli, and no response caching layer; the rules are a built-in ruleset (bans / allow-deny / hotlink /
method / rate-limit), not ModSecurity/OWASP CRS. It's also self-hosted-only — managed-cloud projects route
through the cloud edge, where rule coverage is still partial.
- **The mail server is a real mail server.** It's a genuine Postfix + Dovecot stack — so DNS/DKIM/SPF setup,
deliverability, and ongoing mail ops are yours to run. The others sidestep this by not offering mail at all.
- **Catalog breadth isn't the pitch.** Coolify's 280+ one-click services is the largest catalog here; Openship
leads on the *migration and edge* story, not template count.
## Next steps
---
# Updating Openship
URL: https://openship.io/docs/guides/updating.md
Keep your Openship up to date — the one-click desktop updater, the CLI update command, and how the always-on service picks up a new release.
import { Step, Steps } from 'fumadocs-ui/components/steps';
New versions of Openship come out from time to time — bug fixes, new features, the occasional security
patch. Updating is how you get them. Think of it like the update button on your phone: Openship checks
whether there's a newer version, and if there is, it swaps the old one out for the new one.
Openship gets these updates in one place only: the project's **public GitHub releases**. It **pulls** that
information — it asks GitHub "is there anything newer?" Nothing is ever pushed to your install, and no
Openship-run server can reach in and change your app. You stay in control of when (and whether) you update.
- **Automatic updates are off by default.** Openship tells you when an update exists; it doesn't install
it behind your back (the desktop app can, if you turn that on).
- **Where it all lives:** the dashboard shows update status under **Settings → Instance → Updates**.
- This only appears for people who run their own Openship — the **desktop app** and **self-hosted servers**.
On Openship Cloud there's nothing for you to update; we handle it.
## Where updates live
Open **Settings** and choose the **Instance** tab. Scroll to the **Updates** section. It shows:
- Which version you're on now, and whether a newer one exists — either **"You're on the latest version"**
or **"Openship _x.y.z_ is available"**.
- A **Check now** button to ask GitHub again right away (Openship also checks on its own).
- A **View changelog & releases** link that opens the product changelog on the Openship website.
- Toggles for **Automatic updates** (desktop only) and **Update & security notifications**.
## Updating
How you update depends on how you run Openship. Pick your case.
The desktop app updates itself — you just say yes.
If the updater reports **"Redirect was cancelled"**, download the fixed **0.8.2 or
newer** installer from [GitHub releases](https://github.com/oblien/openship/releases).
Quit Openship and replace the application without deleting its application data.
Your local projects, servers and settings are preserved. Critical advisories use
the same downloader, so marking an update critical does not repair these older
installed versions. Server/CLI updates are unaffected by this desktop bug.
### Wait for the update notice
When a new version is out, a notice slides in at the **top of the dashboard**: *"Openship _x.y.z_ is
available."* It sits just above the page, so you don't have to go looking for it.
### Press Update now
Click **Update now**. The notice turns into a progress bar and shows **"Downloading Openship _x.y.z_"**
with a percentage as it pulls the new version down.
### Let it restart
When the download finishes, the bar reads **"Installing — Openship will restart"**. The app replaces itself
with the new version and reopens on its own. That's it — you're on the new release. 🎉
In **Settings → Instance → Updates**, turn on **Automatic updates** and the desktop app will download and
install new releases for you, without waiting for a click. It's off by default so you decide when your app
changes.
A self-hosted server (installed with the CLI) updates from the terminal. The `openship update` command
updates the CLI — which bundles the API server — to the latest release.
### Run the update command
```bash
openship update
```
Openship checks GitHub, and if there's a newer version it updates itself in place. If you used the
**install script** (the default), it re-downloads the checksum-verified release bundle and swaps it in —
refreshing the Node runtime first if a release ever needs a newer one. If you installed the **npm package**
instead, it reinstalls with your package manager (**bun** if you have it, otherwise **npm**). If you're
already current, it just says so and stops.
### Restart the service on the new version
Updating swaps out the files, but the server that's already running keeps running the old version until you
restart it. Bring it up again:
```bash
openship up
```
This restarts the persistent service on the new release and fetches the matching dashboard automatically.
Check without changing anything:
```bash
openship update --check
```
It tells you your current version and whether a newer one is available — then exits. It installs
nothing.
Installed the npm package? Force a specific package manager if you need to (ignored for install-script
installs, which always update from the verified release bundle):
```bash
openship update --via npm # or: --via bun
```
## About the always-on service
If you started Openship with `openship up`, it runs as a **persistent service**: it starts again when the
machine reboots and restarts itself if it ever crashes. That keeps your apps online.
What it does **not** do is change versions on its own. It keeps running whatever version it started with, so
after `openship update` you re-run `openship up` to restart it on the new release (and `openship stop` to
take it down). See [Installation](/docs/getting-started/installation) for the full service commands.
## Troubleshooting
Openship pulls updates straight from GitHub, so the check needs internet access — and GitHub limits how
often an address can ask. Wait a moment and press **Check now** again, or run `openship update` later. If it
keeps failing, reinstall by hand with the same install method you used originally (see
[Installation](/docs/getting-started/installation)).
`openship update` either re-downloads the verified release bundle (install-script installs) or reinstalls
the global package with bun or npm. If that step errors, it prints the exact command to run by hand — copy
it and run it yourself. Then restart with `openship up`.
A Compose install keeps its generated secrets only in `~/.openship/compose/.env`. If an update can't read that
file while the database volume is still present, it stops **without changing anything** rather than generating
values that couldn't work — most often because it ran as a different user (`sudo` reads `/root/.openship`). Re-run
as the user that owns the install, or restore the file (the previous one is kept at `.env.bak`). Full steps:
[Troubleshooting → openship up refuses to regenerate secrets](/docs/troubleshooting#symptom-openship-up-refuses-to-regenerate-secrets).
The running server hasn't been restarted yet. On a self-hosted server, run `openship up` again to restart on
the new version. On the desktop app, fully quit and reopen it if it didn't relaunch on its own.
## Related guides
---
# Auto-deploy on push
URL: https://openship.io/docs/guides/auto-deploy.md
Make Openship rebuild and ship your app automatically every time you push to GitHub — from the dashboard or the terminal.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Once your app is deployed, you don't want to click "Deploy" by hand every time you change something. **Auto-deploy** fixes that: you push your code to GitHub as usual, and Openship rebuilds and ships it for you. Think of it like a doorbell — every time you push, GitHub rings the bell, and Openship answers by shipping the new version.
That doorbell has a name: a **webhook**. A webhook is just a little message GitHub sends to Openship the instant you push, saying "new code is here" — so Openship can start building without you lifting a finger.
- A project that's already **linked to a GitHub repository** (see [Deploy from GitHub](/docs/guides/deploy-from-github)).
- A way for GitHub to reach Openship. That's either **Openship on a public web address**, or a **verified domain** on the project for direct delivery. More on this below — Openship tells you which one applies.
## Turn it on from the dashboard
### Open the project's Source tab
Go to your project and open the **Source** tab. Under **Source Repository** you'll find the deploy triggers for this repo.
### Flip on Auto Deploy
Find the **Auto Deploy** card and switch its toggle on. When it's on, the card reads **Enabled** and "Pushes trigger deployments automatically". When it's off, it reads **Disabled** and "Deployments must be started manually".
That's the whole thing — from now on, every `git push` to your deploy branch rebuilds and ships automatically.
### If Openship asks for a webhook endpoint
Sometimes Openship can't be reached from the public internet on its own (for example, you're running it on your laptop or a private network). When that's the case, you'll see an **Enable auto-deploy** notice telling you to set a webhook endpoint.
The fix is the **Webhook Endpoint** card. Pick one of your project's **verified domains** from the "Select domain..." menu. GitHub will then deliver push events straight to that domain. To stop using it later, open the same menu and choose **Clear selection**.
This card only appears once the project has at least one **verified** domain. If you have none yet, you'll see just the **Enable auto-deploy** notice — attach and verify a domain first (see [Custom domains](/docs/guides/custom-domains)), then come back and the card will be here. The menu only ever lists domains that belong to this project and are verified.
### Check the status
The **Webhook** card shows whether GitHub is actually reaching Openship: **Active** (or **Direct**, when it's going through your chosen domain) means events are getting through; **Inactive** means the webhook isn't set up or isn't responding yet. After your next push, this is the card to glance at.
## CLI
Everything above works from the CLI too. You'll need the project's ID — run `openship project list` to find it.
```bash
# Turn auto-deploy on
openship project git auto-deploy --enable
# Turn it off again
openship project git auto-deploy --disable
# Deliver webhooks to a verified project domain (for private instances)
openship project git webhook-domain deploy.yourapp.com
# Stop using that domain
openship project git webhook-domain --clear
```
## How the webhook gets wired (the short version)
You don't have to think about this, but here's what happens under the hood so nothing feels like magic. Openship picks the simplest delivery route that works for your setup:
- **Public Openship** — if your Openship API has a public web address, turning on Auto Deploy registers a webhook on your repo that points at `…/api/webhooks/github`. GitHub calls it on every push.
- **Verified domain** — if you set a Webhook Endpoint, GitHub delivers instead to `https:///_openship/hooks/github`, which routes to Openship. This is the option for private or laptop installs.
- **GitHub App** — on Openship Cloud or with your own self-hosted App, push events arrive through the App automatically; there's no duplicate per-repo webhook to manage.
In every case, Openship starts a fresh build from the commit you just pushed — the same build you'd get by clicking Deploy.
## Troubleshooting
You'll see an **Enable auto-deploy** notice, and the error reads *"Set a webhook domain or expose this Openship API on a public URL to enable auto-deploy."* GitHub has no way to reach Openship yet. Either put Openship on a public address, or set a **Webhook Endpoint** domain on the Source tab (see step 3).
The domain you picked isn't verified yet, so Openship won't route webhooks to it. Verify the domain first ([Custom domains](/docs/guides/custom-domains)), then select it again.
This means Openship couldn't add the webhook to your repository — usually because your GitHub connection doesn't have **admin** access to that repo. Reconnect GitHub and make sure the repository is included with full access, then toggle Auto Deploy again.
Check the **Webhook** status card on the Source tab. If it says **Inactive**, delivery isn't reaching Openship — revisit the webhook endpoint above. Also confirm you pushed to the project's **deploy branch**; pushes to other branches are ignored.
If another deployment is running, the new push is reported as a **failed** delivery,
with the reason in the project's webhook events. Wait for the running deployment
to finish or cancel it, then **Redeliver** the failed event from GitHub's webhook
delivery history. GitHub does not automatically redeliver failures. Openship
accepts a retry of the same failed delivery ID and remembers projects already
handled by that delivery, so only the remaining projects are retried. It also skips
a commit that is already building or live. A successful delivery remains deduplicated.
## Related guides
---
# Openship Actions
URL: https://openship.io/docs/guides/actions.md
Run GitHub-compatible workflows on connected servers and temporary Cloud runners.
Actions runs repository CI and standalone automation on Openship's authorized
destinations. Workflows can be linked to projects or run independently. Jobs can
schedule an application command or invoke a saved workflow, with the same Actions
execution, topology and logs.
## Workflow sources
Select a repository and Openship discovers its workflows. The file's location
selects its integration automatically; the editor, destinations, capacity limits
and run history stay together.
- **`.github/workflows/`:** GitHub coordinates the workflow and its Checks, secrets,
environments, artifacts and caches. Official runners on your selected Openship
destinations execute jobs routed to them. This supports reusable workflows,
releases, tags and protected environments.
- **`.openship/workflows/` or Standalone:** Openship schedules the YAML and runs
jobs with act, using its scoped credentials and configured storage. The
compatibility limits below apply to these independent workflows.
## Run only in Openship
Store the workflow in `.openship/workflows/ci.yml`. GitHub ignores this directory:
using GitHub's YAML syntax does not start GitHub Actions. Openship discovers the
file, schedules its declared triggers and executes jobs on your allowed runners.
This also works when GitHub Actions is disabled for the repository.
1. Add the file to the repository. When moving CI from GitHub, move the file out
of `.github/workflows/`; leaving a copy there keeps its GitHub triggers active.
2. Open the project's **Actions** tab, select the repository and import the file.
3. Choose the runners, access policy and notifications, then save.
4. Run it manually or push a commit matching its `on: push` rules. Automatic GitHub
events require a connected App subscribed to those events and a reachable webhook.
For example, this workflow checks out a private repository and runs its Node tests
on an allowed Linux runner with Git and Node available:
```yaml title=".openship/workflows/ci.yml"
name: CI
on:
push:
branches: [main]
workflow_dispatch:
permissions:
contents: read
jobs:
test:
runs-on: [self-hosted, openship, linux]
steps:
- uses: actions/checkout@v4
- run: node --test
```
Private checkout uses a repository-scoped App token. Publishing results needs the
App's **Checks: write** permission. An Openship Check on a commit is a status report;
it does not create a GitHub Actions run. Follow execution and live logs in Openship.
The independent-workflow compatibility limits below still apply.
## Use GitHub-coordinated workflows
Files in `.github/workflows/` require runner-management access: a GitHub App with
**Actions: write** and **Administration: write**, or a suitable repository token.
Existing App installations may need to approve these permissions. Editing workflow
files also needs **Contents: write** and **Workflows: write**; new Openship App
manifests request them for the editor. Configure secrets and variables in
GitHub's repository or organization settings.
To route jobs to Openship, use explicit labels:
```yaml
runs-on: [self-hosted, openship, linux, x64]
```
For a connected Mac, use `macos` and its actual CPU architecture. A plain
`ubuntu-latest` job remains on GitHub-hosted runners. Add a Cloud size label such as
`openship-linux-2` when selecting a specific allowed profile.
A GitHub runner registration belongs to the repository and may receive any matching
job, including reusable-workflow jobs. Openship checks the actual assigned workflow,
requester and approval before starting workflow code. Configure that policy in the
**Access** step; a matching label alone does not grant permission.
## Add a runner
Open **Actions → Runners → Add runner** and choose a destination:
- **Existing server:** select a connected or managed application server. Set
per-job CPU, memory and parallel limits to leave capacity for its applications.
The server keeps its existing billing.
- **Dedicated server:** create a managed server through the shared server and plan
dialog, then configure it as a runner. Its normal server subscription applies.
- **Temporary Cloud runners:** choose a disposable VM profile using your prepaid
Actions balance. Each executed job gets a VM, which is removed after cleanup.
Openship probes the selected server's OS, architecture, Git, Node and Docker
capabilities before enabling a runtime.
- **Linux containers:** use a runner image with the tools your workflow needs.
Docker and service-container actions require Docker on the destination.
- **Native Linux:** use the server's installed toolchain with Git and Node available.
- **Native macOS:** use a connected Mac with Git and Node installed. Native mode
is selected by default, even when the Mac also has Docker. Jobs execute
as the connected server user and share that user's filesystem and installed tools.
- **Temporary Cloud runners:** each job receives a disposable Linux VM. Its funding
is separate from managed application-server subscriptions.
The runner picker shows its execution OS, Docker/native mode and verified CPU
architectures. Expand **Environment & labels** to see the host version, default image,
per-job limits and routing labels. For example, an Ubuntu 24.04 host can use an
Ubuntu 22.04 default container image; these are separate environments.
New connected runners use their verified OS and architecture labels. The Ubuntu
image preset does not add `ubuntu-latest` or a version alias. Existing saved labels
remain intact. Add a custom routing label only when your workflow needs it; a label
does not select a different image or install tools.
Only run trusted code on persistent destinations. Enabling a native runner gives
its workflows the same host access as the connected user. Runner labels select
compatible capabilities; adding `macos` to a Linux runner does not make it a Mac.
The runner image is a default. Each job can use its own compatible Linux image with
`jobs..container`, including Debian, Alpine and language images. The image must
provide the shell and tools used by its steps; a minimal image does not include the
full GitHub-hosted toolchain. Container image options and registry credentials remain
available in YAML.
For container runners, **Enable CPU emulation** installs the missing QEMU/binfmt
support on the selected Docker host and verifies it by executing a foreign binary.
It requires server administration access. Existing working emulators are reused.
Normal capability checks do not install packages or register emulators. Use the
standard `x64` or `arm64` runner label to select a CPU; use a matrix for both:
```yaml
jobs:
test:
strategy:
matrix:
arch: [x64, arm64]
runs-on: [self-hosted, openship, linux, "${{ matrix.arch }}"]
container: alpine:3.22
steps:
- shell: sh
run: uname -m
```
The selected image needs a build for that architecture. QEMU can be slower than
native execution. `runner.arch` and `RUNNER_ARCH` describe the selected execution
architecture; native macOS jobs still need a real Mac.
**Allow Docker access** enables Docker build actions on a connected container runner;
enable it only for trusted workflows because it grants access to that server's Docker
daemon. Cloud job containers use the Docker daemon of their own private disposable VM.
They receive no provider credentials or access to other customers' machines.
## Connect a workflow
Open **Actions → Add workflow**, **Project → Actions**, or the Actions section in
the deployment wizard. These entry points share the same setup:
1. Select a repository and branch. Openship discovers files in `.github/workflows/`
and `.openship/workflows/` and previews their job dependencies as a topology.
Check several files or choose **Select all** to add them together. Select a
filename to preview it; each file keeps its own draft and undo history.
2. The canvas stays visible while you edit. Select a job to open its settings in the
right panel. Expand its canvas node to reveal a grid of step cards connected by
execution-order arrows; selecting a step opens its editor. **List** edits those
same steps inline on the left, without
duplicating them in the right panel. Jobs and steps expand independently, and
open steps stay open when switching views. Connect jobs to set dependencies
and select a connection to remove it. **List** and **YAML** show the same draft; undo and redo work across
views. **Job YAML** exposes matrix, services, conditions, permissions and step
inputs. Dependency cycles and deletion of referenced job outputs are rejected.
3. Use **Run settings** on the right to choose the required runners and configure
triggers. If no runner exists, the selector opens runner setup in a modal;
saving selects the new runner without leaving your draft. The current project
is linked automatically. The generic editor keeps extra project links under a
disclosure. Independent workflows also configure variables, secrets and artifact
storage here; GitHub workflows use their repository settings.
Runner destinations, enabled state and project links apply to the selected
files. Trigger edits apply to the file being previewed.
4. In **Access**, choose who can run and whether each run needs approval. Defaults
allow only your connected account, require approval for each run and block forks.
Choose specific GitHub users or repository collaborators with write access to
extend access. These settings apply to the selected files.
5. In **Checks**, review the connected GitHub account and the selected repository's
access. **Connect GitHub** or **Review access** opens setup without leaving your
draft; unavailable checks can be retried. GitHub workflows retain their original
Checks. Independent repository workflows need a GitHub App with **Checks: write**.
For notifications, choose **Add channel**, enter its destination and select
**Send test & use**. Failed verification stays retryable in the same dialog.
Select failures, successes or cancellations; notifications remain optional.
Choose required workflows in the project's **Deployment automation** tab.
6. Save the workflow. Canvas and trigger edits preserve unrelated YAML and
expressions. Before writing back to GitHub, review the changes and choose
**Commit and save**. `.openship/workflows` also offers **Save Openship copy**.
`.github/workflows` always runs committed YAML. A changed file on GitHub rejects
the commit instead of overwriting someone else's changes.
GitHub workflow management uses the instance's existing credential resolver: an
authorized local CLI login, personal token, or repository-scoped GitHub App
(including an App connected through Openship Cloud). A detected CLI login can
read repository information before you authorize it for management. Choose
**Review access → Change method → Use gh CLI** to select it explicitly.
Repository Actions and runner-management permissions still apply; signing into
GitHub alone does not grant them. Cloud uses the connected user's credentials or
App installation and never the Cloud host's CLI login. Independent Checks use a
GitHub App with Checks write access. Actions currently supports github.com, not
GitHub Enterprise destinations.
All selected files are validated before their workflow records and project links
are saved in one transaction. Retrying an import reuses existing records, retains
their settings and adds any new project links; it does not duplicate workflows or
start a run. Edit an already connected workflow from its Actions page to change
its saved configuration. Reviewed repository commits can trigger the repository's
normal automation, and are separate from the database transaction.
## Access and approvals
Access policies apply on both connected servers and Cloud destinations. **Only my
account** uses your connected GitHub identity for repository workflows and your
Openship identity for standalone workflows. Selected GitHub users are verified by
account ID; the original requester and anyone retrying a run must both be eligible.
With **Approve each run**, an Actions administrator with access to its destinations
reviews the commit, attempt and runners before any runner is allocated. Changing
the policy, destinations or execution settings requires a new review. A retry does
not inherit the previous attempt's approval. Open the run's **Approvals** tab to
review it; a yellow icon marks pending or blocked access. The tab explains blocked
access and links back to workflow settings without covering the job list or logs.
**Automatically allow eligible users** skips Openship's review for trusted runs.
GitHub's fork and protected-environment approvals still apply; the editor links
to repository settings. GitHub does not require approval for every collaborator
push by default. Choose per-run approval when you need that control. Eligible
fork runs always need Openship approval and a disposable Cloud runner.
Existing independent workflows keep their previous behavior until their access
settings are saved. Existing GitHub workflows without a policy require review
before Openship starts new runners. The official runner adapter verifies the actual
assignment through GitHub's local IPC protocol and fails closed if that protocol
becomes incompatible; it does not fall back to unchecked execution.
Workflow notifications use the existing notification queue, alongside account-wide
Actions subscriptions. A channel selected by both rules gets one queued notification
per run. Jobs that invoke a workflow share that identity. Failed enqueues are retried
before completion is settled, and delivery rechecks channel verification and resource
access. Notification choices are captured when the run is created; importing old GitHub
history does not send a backlog of alerts. No workflow commands, secrets or raw logs
are included in these notifications.
Choose **Standalone** for YAML without a repository. It supports manual runs,
schedules and authenticated webhooks without GitHub credentials. `actions/checkout`
in a standalone workflow needs an explicit `with.repository`.
**Repository updates** for `.openship/workflows` controls which definition future runs use.
Files in `.github/workflows` always use the definition from GitHub for that run:
- **Automatic:** use the workflow from the run's repository commit. Changes in Git
apply automatically.
- **Review first:** keep the YAML saved in Openship. **Check repository** loads the
latest file without replacing your saved definition or edited draft. Review the
differences, choose **Use repository version**, then save to approve it. Until
then, runs continue using the previously saved YAML.
Saving an Openship copy selects **Review first**. Changing the definition affects
future runs; existing runs retain their immutable snapshots.
```yaml
name: CI
on:
push:
branches: [main]
workflow_dispatch:
permissions:
contents: read
jobs:
build:
runs-on: [self-hosted, openship, linux]
strategy:
matrix:
node: [20, 22]
steps:
- uses: actions/checkout@v4
- uses: actions/setup-node@v4
with:
node-version: ${{ matrix.node }}
- run: npm ci
- run: npm test
complete:
needs: build
runs-on: [self-hosted, openship, linux]
steps:
- run: echo "All matrix jobs passed"
```
Every run records the resolved commit and workflow definition. Rerunning creates a
new attempt of that recorded revision. A controller restart resumes inspection of
the same worker; it does not replay a job whose start was already accepted.
The run page opens with a collapsible job-and-step list on the left and logs on the
right. Select a job for all its output, or a step for its recorded output. Jobs
expand independently. Switching to **Topology** keeps the same selection and logs;
use **Expand all**, **Collapse all**, zoom, fit or **Arrange workflow** to inspect
the connected steps. Independent jobs wrap across the graph rather than forming
one long column. A single job shows its step nodes immediately. The selected job,
step and view are preserved in the URL when you refresh or share the page.
Queued and waiting jobs keep their own status labels and use a yellow loading
indicator. Opening **Approvals** preserves the current job, step and log cursor.
Independent logs resume from their persisted cursor. For GitHub workflows, step
state is synchronized from GitHub, live logs open in GitHub, and completed logs and
artifacts are available in Openship. GitHub supplies a complete job log, so selecting
a step keeps that full output visible with a scope label.
GitHub owns the Check IDs and conclusions; Openship does not publish duplicate Checks.
## Triggers and Jobs
**When to run** edits the workflow's own `on` rules. It supports manual inputs,
push and pull-request branch/path filters, UTC Cron schedules and authenticated
webhooks. Expand a trigger to configure it. Branches and paths use removable
patterns: type a pattern and press **Enter** or **+** to add it. Choose **Only
matching** or **Except matching**; Openship preserves commas inside glob patterns.
**Paths & more filters** includes tags and pull-request event types. Each Cron
schedule has its own UTC input. Other events, including `workflow_call`, remain
visible and open the YAML editor without changing their definitions.
**Manual & Jobs** enables `workflow_dispatch`. Add string, number, boolean or choice
inputs with defaults and required values. The manual-run form and **Jobs → Run
workflow** use those same declared inputs. Jobs can run a workflow on a Cron
schedule, once, after another job succeeds or on a supported platform event.
Allowed runners and secrets remain configured on the workflow. Job history opens
the original Actions execution rather than a second copy of its logs or status.
For an independent workflow's authenticated webhook, enable `repository_dispatch` and optionally restrict
event types. The workflow details show its dispatch endpoint. Call it with an
Openship API token authorized to run that workflow:
```http
POST /api/actions/workflows/WORKFLOW_ID/dispatch
Authorization: Bearer YOUR_OPENSHIP_TOKEN
Content-Type: application/json
{
"eventType": "release",
"clientPayload": { "version": "1.2.3" },
"idempotencyKey": "release-1.2.3"
}
```
The workflow receives these values in `github.event.action` and
`github.event.client_payload`. Keep the token in the caller's secret store and
reuse the same idempotency key when retrying one delivery. This is Openship's
authenticated dispatch API; it does not subscribe to GitHub App
`repository_dispatch` deliveries. The caller must be able to reach the instance. For `.github/workflows`, send
`repository_dispatch` events to GitHub's repository dispatch API instead. Openship's Run button and Jobs schedules use GitHub's `workflow_dispatch` endpoint.
## Project deployment rules
In **Project → Actions**, create a workflow or open **Deployment automation** to link
existing workflows and select:
- **Manual deployments:** workflows run independently; deployment starts when requested.
- **Deploy on push:** use the project's existing automatic deployment pipeline.
- **Deploy after Actions pass:** require all selected workflows to pass for the
exact pushed commit before entering that same deployment pipeline.
Required workflows must be enabled, belong to the project's repository and run
on every push to its deployment branch. Path-filtered workflows can be linked as
optional checks. Required checks need a reachable control plane and an authenticated
repository push webhook. Independent Checks additionally require a connected GitHub
App to publish results. GitHub-mode deployment gates wait for the original GitHub
push run; they do not dispatch another run. Manual deployments remain available.
Pending requests and failed checks appear in the project's Actions tab. Retrying
uses the saved commit and one deployment receipt; duplicate deliveries or a
controller restart do not create another accepted deployment. Newer commits,
changed rules and a new manual deployment supersede pending approvals. Pull-request
runs and manual workflow runs do not approve automatic push deployments.
The deployment wizard saves its selected workflow links and rules before starting
the initial deployment. If rule setup fails, it keeps the draft for retry. The
initial deployment remains an explicit manual deployment; the selected automatic
policy applies to subsequent pushes.
## GitHub events and checks
For independent workflows, a connected GitHub App receives signed push and pull-request events and publishes
Checks on the commit. Each job uses a token scoped to its repository and declared
permissions. Stored personal credentials are not substituted for an unavailable
App token. GitHub installation tokens normally expire after one hour; token refresh
inside a running job is not currently supported.
Independent scheduled workflows run while the controller is online, at intervals of at least
five minutes. Missed schedules are not replayed after downtime. For Desktop, keep
it running or [move the control plane to a server](/docs/guides/migrate-control-plane).
Schedules in `.github/workflows` are managed by GitHub. Openship must be online to provision
and register its runners. Signed `workflow_run`/`workflow_job` events request a fresh
API read; periodic reconciliation also recovers missed events. Event payloads alone
cannot mark a run successful.
Use `.openship/workflows/` when you want scheduling independent of GitHub. If a workflow script deploys the application
itself, use manual project deployment mode to avoid also requesting an automatic
deployment after its checks pass.
Independent fork runs require explicit approval and disposable runners. Their workflow comes
from the trusted base revision, while checkout can use the pull-request merge
commit. They receive no stored secrets, write credential or shared cache access.
Authorization is rechecked during execution; revoking the originating user's
access prevents further authorized work.
Fork approvals and protected-environment approvals for `.github/workflows` still
follow GitHub repository policy. Openship also requires its own approval and a
disposable Cloud runner for eligible fork runs. Forks never run on connected
persistent servers, including Macs. `pull_request_target` is also treated as untrusted.
## Artifacts and cache
Files in `.github/workflows` use GitHub's artifact/cache service, retention and storage billing.
Download links are fetched with repository authorization and returned as short-lived
signed links; credentials are never forwarded to the download host.
For independent workflows, select an existing backup destination for artifacts and cache. Cloud requires an
S3-compatible destination; self-hosted instances can also use a local destination.
Workflow code never receives the destination's storage credentials.
The API implements the protocols used by `actions/upload-artifact@v4`,
`actions/download-artifact@v4` and `actions/cache@v4`. One object is limited to
1 GiB, with 20 GiB of reserved and retained objects per organization. Artifact
retention defaults to seven days and can be set up to 30 days. Expired objects are
removed by the controller's cleanup loop.
Runners must be able to reach the instance's public API. Set
`OPENSHIP_ACTIONS_RUNTIME_URL` when it differs from `OPENSHIP_PUBLIC_URL`; preserve
the artifact API and `/twirp` proxy routes. Runtime URLs use short-lived tokens
scoped to one organization, run and job.
## Independent reusable workflows
Use `jobs..uses` to call a YAML file in `.openship/workflows/` or
`.github/workflows/`. Local calls use the caller's immutable commit. Remote calls
use `owner/repository/path@ref`; Openship resolves the ref and saves every called
source before approval. A later tag change cannot alter an approved attempt.
```yaml
jobs:
gate:
uses: ./.openship/workflows/test.yml
with:
enabled: false
version: 22
secrets:
registry_token: ${{ secrets.REGISTRY_TOKEN }}
```
The called file declares `on: workflow_call`, typed inputs, accepted secrets and
outputs. Its jobs select their own allowed runners and appear in the same run,
with logs, Checks and cancellation. Boolean and number inputs retain their types.
Permissions can stay the same or narrow at each call. Secrets must be forwarded
explicitly; `secrets: inherit` is permitted only within the same owner.
Nesting is limited to 10 workflow levels, 50 called files, 2 MiB of combined source
and 256 total concrete jobs. Protected environment settings remain unsupported
in independent mode.
## Openship OIDC
Independent jobs can request an identity with `permissions: {id-token: write}`.
Publish the controller at a stable HTTPS origin reachable from runners and the
external service. Configure that service to trust
`https://your-controller/api/actions/oidc` as its issuer. Discovery is available at
`/api/actions/oidc/.well-known/openid-configuration`; RSA verification keys are at
`/api/actions/oidc/jwks`.
The job receives the standard `ACTIONS_ID_TOKEN_REQUEST_URL` and
`ACTIONS_ID_TOKEN_REQUEST_TOKEN` environment variables. Actions using the standard
OIDC toolkit can request a token with their required audience. Credentials such as
AWS or Azure trust policies must allow this Openship issuer; GitHub-specific
issuer policies do not grant access automatically.
Restrict the provider's trust to the organization, repository, ref and workflow
identity. A normal repository subject is
`openship:organization::repo:/:ref:refs/heads/main`.
A workflow edited in Openship includes `:source:override` in its subject and sets
`openship_workflow_modified`, so it cannot impersonate the repository's committed
workflow. Claims also identify the run, job, destination and immutable called
workflow source (`job_workflow_ref`, `job_workflow_sha`).
Tokens expire within five minutes. Issuance rechecks approval, actor access,
runner access and cancellation; fork jobs receive no OIDC capability. The
instance's signing key is encrypted in its database and included only in a full
instance transfer, preserving its key when credentials are transferred securely.
Keep the issuer address stable when moving a control plane. An archive that omits
credentials retains public verification metadata but cannot issue new tokens;
restore an archive containing the signing credentials to use that issuer.
## Cancellation and limits
Cancel stops the remote execution and then cleans its resources. A runner remains
busy until cleanup succeeds. Cloud workers also have a provider TTL as a fallback;
an unreachable controller does not leave a VM running indefinitely.
Independent workflows support up to 256 concrete jobs after matrix expansion. A job defaults
to a 60-minute timeout and can request up to 360 minutes. Logs are bounded at
8 MiB per job. Settled run history is retained for 30 days, with runs referenced
by retained artifacts or retry attempts protected from early removal.
Independent workflows support reusable workflows and Openship-issued OIDC.
Protected environments and attestations require GitHub-coordinated workflows;
independent mode rejects those features before dispatch. Openship-managed destinations
currently support Linux and macOS; Windows and GitHub Enterprise Server are not
available. Official runner registrations execute one job and expire after six hours;
idle registrations are removed after ten minutes. Choose a runner image with the
official runner's dependencies, or use the Ubuntu preset. The official runner's
container runs as the connected server user's UID and GID; steps that need root
require a server connected as root.
GitHub dispatch and rerun POSTs have durable command receipts. If GitHub accepts a
request but its response is lost, Openship does not send the POST twice. Refresh
Runs or open GitHub before deliberately starting another run.
## Cloud Actions funding
**Actions → Budget** provides a separate prepaid balance for temporary VMs and
transfer. Add $5, $20, $50 or $100, complete the hosted payment, and return to see
its verified status. Runner setup retries automatically if the provider is
unavailable; it does not buy another deposit. Once ready, choose the Cloud runners
in your workflow's allowed destinations.
| Runner | RAM | Temporary disk |
| ------ | ------ | -------------- |
| 2 vCPU | 4 GiB | 40 GiB |
| 4 vCPU | 8 GiB | 80 GiB |
| 8 vCPU | 16 GiB | 160 GiB |
All sizes share two concurrent Cloud jobs per organization. You can select a size
with `runs-on: [self-hosted, openship, linux, openship-linux-2]`, `openship-linux-4` or
`openship-linux-8`, provided that profile is allowed for the workflow.
The page shows live provider rates and estimated VM minutes for your deposit.
Estimates assume full CPU and memory use, before transfer or disk I/O. Actual
charges follow measured CPU time, memory and combined uploads/downloads. VM
preparation, failed steps and cleanup can consume credits; queued jobs use no VM.
This is prepaid usage, not a fixed number of execution minutes or a subscription.
Your displayed balance comes from Oblien. Recent usage may appear with a delay.
Workers stop when the provider marks the balance exhausted. Add funds and rerun
the workflow to try again; an interrupted attempt is not silently restarted.
Independent artifacts and caches use your configured storage destination; GitHub
mode uses GitHub storage. Connected servers
run workflows without spending this Cloud Actions balance.
---
# Add an app
URL: https://openship.io/docs/guides/add-an-app.md
Write the catalog JSON that makes a one-click Openship app, built up field by field from a bare service to a complete submission — plus how to ship it as a pull request or upload it privately to your own organization.
Openship's **Apps** tab is a catalog of one-click installs. Each entry is a JSON file that describes
the containers, how they wire together, which secrets to generate, how it gets exposed, and what
the user sees once it is running. The same entry powers its public [app page](/apps), with optional
feature summaries and a Markdown article.
This page walks through writing one from scratch. Every field is catalogued in the
[App catalog JSON reference](/docs/reference/app-catalog); here we build a real app end to end.
| | Curated catalog entry | Custom app |
|---|---|---|
| How | A **pull request** adding `catalog/.json` | Upload JSON in your dashboard, or `POST /api/apps/custom` |
| Who sees it | Everyone, on every instance | Only your organization |
| Reviewed | Yes, by a maintainer | No — always marked unverified |
| Good for | An app the whole community wants | Your own internal stack, or trying an idea out |
Both use the **same format** and the **same strict validation**, so everything below applies either
way. [Jump to the custom-app path](#upload-a-custom-app-no-pull-request) if you are not opening a PR.
## What a pull request contains
Submit `packages/core/src/apps/catalog/.json` and the regenerated `catalog.json`. Optionally
include a Markdown article and a logo asset.
```
packages/core/src/apps/catalog/umami.json ← the app you wrote
packages/core/src/apps/catalog/articles/umami.md ← optional public overview
packages/core/src/apps/catalog.json ← regenerated (a drift test fails CI without it)
apps/dashboard/public/app-logos/umami.svg ← only if the logo is not on simpleicons
apps/web/public/app-logos/umami.svg ← the same bundled logo for the public page
```
See [Public app pages](/docs/reference/app-catalog#public-app-pages) for `marketplace.features`
and `marketplace.articleFile`. Both apps use the shared `AppLogo` renderer in `packages/ui`;
add a bundled brand mapping there when the logo is unavailable from the existing sources.
### The bar it has to clear
The catalog is **curated, not open-ended** — installing an app never runs arbitrary third-party code.
Expect review on exactly these points:
- **Open-source only.** A well-known project with a public source repository, so anyone can see what
it is before installing.
- **Official or reputable images, pinned.** The project's own published image at a pinned version
(`postgres:16-alpine`, `qdrant/qdrant:v1.18.3`) — never an unpinned tag or an unknown publisher.
Prefer the published image with environment settings, mounted configuration files and a startup
command. A small setup script alone does not require building a new image on the customer's server.
- **Secure defaults.** Credentials auto-generated, never plaintext defaults. Publicly-exposed admin
UIs require auth.
- **Fully auditable.** The JSON is the whole truth — images, ports, env, volumes, all in one small
file. Nothing fetched from a private source.
## Build it up
We will add **Umami**, a self-hosted analytics app that needs a Postgres database. Each step below is
one decision; the [complete file](#the-complete-file) is at the end.
Start the file with `"$schema": "https://openship.io/app.schema.json"`. Your editor then autocompletes
field names and flags bad **values** — an invalid `category`, a wrong `type`, a missing required
field. It cannot flag a misspelled field *name*, because unknown keys are deliberately ignored rather
than rejected, so lean on the autocomplete.
### 1. Identity, and the app itself
`id` is a stable kebab-case slug and the filename must match it. Start with `available: false` so the
app appears as *coming soon* and cannot be installed while you are still working on it.
```json
{
"$schema": "https://openship.io/app.schema.json",
"available": false,
"id": "umami",
"name": "Umami",
"description": "Privacy-focused web analytics — a lightweight, self-hosted alternative to Google Analytics.",
"kind": "template",
"logo": "umami",
"category": "analytics",
"tags": ["analytics", "privacy", "statistics"],
"framework": "docker-compose",
"services": [
{
"name": "umami",
"image": "ghcr.io/umami-software/umami:postgresql-v2.11.3",
"ports": ["3000:3000"],
"exposedPort": 3000,
"exposed": true,
"restart": "unless-stopped"
}
]
}
```
`kind: "template"` means "instantiate these services" — the normal case. (`kind: "flow"` exists only
for apps with a bespoke built-in wizard, like the mail stack, and declares no services.)
### 2. Add the database, and share the generated password
Umami needs Postgres. Add it as a second service — and remember that **the service name is the
hostname**: `umami` reaches the database at `umami-db` on the project network.
The password must never be a plaintext default. Declare it as a `configField` with
`generate: "secret"`, and Openship mints a random value at install that the operator never types.
The interesting part is getting that one generated password into **two** places — the database's own
`POSTGRES_PASSWORD`, and the connection string the app reads:
```json
"services": [
{
"name": "umami-db",
"image": "postgres:16-alpine",
"environment": { "POSTGRES_DB": "umami", "POSTGRES_USER": "umami" },
"secretEnv": ["POSTGRES_PASSWORD"],
"volumes": ["umami_db_data:/var/lib/postgresql/data"],
"healthcheck": { "test": "pg_isready -U umami", "interval": "5s", "retries": 10 },
"restart": "unless-stopped"
},
{
"name": "umami",
"image": "ghcr.io/umami-software/umami:postgresql-v2.11.3",
"ports": ["3000:3000"],
"exposedPort": 3000,
"exposed": true,
"dependsOn": ["umami-db"],
"environment": {
"DATABASE_TYPE": "postgresql",
"DATABASE_URL": "postgresql://umami:{{config:POSTGRES_PASSWORD}}@umami-db:5432/umami"
},
"secretEnv": ["DATABASE_URL", "APP_SECRET"],
"restart": "unless-stopped"
}
],
"configFields": [
{ "key": "POSTGRES_PASSWORD", "service": "umami-db", "label": "Database password",
"generate": "secret", "secret": true },
{ "key": "APP_SECRET", "service": "umami", "label": "App secret",
"help": "Signs session tokens. Auto-generated.", "generate": "secret", "secret": true }
]
```
Three things worth understanding here, because they are where most authoring mistakes happen:
- **`{{config:KEY}}`** inlines a generated value into any `environment` string. That is how one
password ends up inside `DATABASE_URL` on a *different* service.
- **`secretEnv`** lists env keys on that service which are secrets — forced encrypted and never
written as plaintext, whether the value came from `environment` or from a `configField`.
`DATABASE_URL` is listed because it *embeds* a secret.
- **`dependsOn` + `healthcheck`** is how you make the app wait for a real, ready database rather than
just a started container.
Use `{{config:KEY}}` when one generated value belongs in another service's env string. Use
`generateGroup` when two separate **`configFields`** must receive the *same* generated value — for
example a database's `MYSQL_ROOT_PASSWORD` and an app's own `database__connection__password`. Give
both fields the same `generateGroup` and they always match.
### 3. Choose how it gets exposed
`endpoints` is what the install wizard asks the operator about. Omit it and Openship derives one
`http` endpoint per exposed service — fine here, but declaring it lets you label it properly:
```json
"endpoints": [
{ "service": "umami", "port": 3000, "label": "Dashboard", "kind": "http" }
]
```
Use `kind: "tcp"` for a raw port with no domain, such as a database that should not be
domain-routable. `defaultMode` preselects an exposure and `allowedModes` restricts the choices.
Public hostnames come only from the operator's routing choice at install. An app that nobody routes
installs **port-only**, which is the correct outcome for a database or an internal tool.
### 4. What the user sees after install
This is the part that separates a good submission from a bare one. `connection` becomes the
post-install **Connection card** — the URLs and keys the user actually needs:
```json
"connection": {
"title": "Umami",
"description": "Sign in to the dashboard, then add a website to get its tracking snippet.",
"outputs": [
{ "id": "dashboard", "label": "Dashboard", "source": "publicUrl:umami",
"kind": "url", "recommended": true }
],
"firstLogin": {
"username": "admin",
"password": "umami",
"note": "Change this immediately after the first sign-in."
}
}
```
- **`source`** must be `env::`, `publicUrl:[:]`, or `template:…`.
- **`kind: "url"`** adds an open-in-new-tab action next to the value.
- **`secret: true`** masks a value behind a reveal action — use it for any credential.
- **`envKey`** prefills the handover when a user wires this app into another project.
- **`firstLogin`** is for **static** credentials the image ships with (Umami's `admin` / `umami`).
Those are fixed values, not resolved from a running service, which is why they cannot be `outputs`.
### 5. Day-2 settings
`settings` renders a curated form instead of leaving the user to edit raw env. Anything with
`installStep: true` is *also* collected during install:
```json
"settings": [
{
"id": "tracking",
"label": "Tracking",
"description": "How the tracker behaves on your sites.",
"fields": [
{ "key": "DISABLE_TELEMETRY", "service": "umami", "label": "Disable telemetry",
"type": "boolean", "trueValue": "1", "falseValue": "0", "default": "0",
"requiresRedeploy": true },
{ "key": "TRACKER_SCRIPT_NAME", "service": "umami", "label": "Tracker script name",
"type": "text", "advanced": true, "requiresRedeploy": true }
]
}
]
```
If the **user types it**, it is a `setting` (with `installStep: true` to collect it during install).
If the operator **never types it** — a generated secret, a signed key, a derived default — it is a
`configField`, which is resolved server-side and never rendered as an input. See
[the comparison table](/docs/reference/app-catalog#two-field-systems).
### The complete file
Everything above, assembled — this is exactly what the PR adds:
```json
{
"$schema": "https://openship.io/app.schema.json",
"available": false,
"id": "umami",
"name": "Umami",
"description": "Privacy-focused web analytics — a lightweight, self-hosted alternative to Google Analytics.",
"kind": "template",
"logo": "umami",
"category": "analytics",
"tags": ["analytics", "privacy", "statistics"],
"framework": "docker-compose",
"services": [
{
"name": "umami-db",
"image": "postgres:16-alpine",
"environment": { "POSTGRES_DB": "umami", "POSTGRES_USER": "umami" },
"secretEnv": ["POSTGRES_PASSWORD"],
"volumes": ["umami_db_data:/var/lib/postgresql/data"],
"healthcheck": { "test": "pg_isready -U umami", "interval": "5s", "retries": 10 },
"restart": "unless-stopped"
},
{
"name": "umami",
"image": "ghcr.io/umami-software/umami:postgresql-v2.11.3",
"ports": ["3000:3000"],
"exposedPort": 3000,
"exposed": true,
"dependsOn": ["umami-db"],
"environment": {
"DATABASE_TYPE": "postgresql",
"DATABASE_URL": "postgresql://umami:{{config:POSTGRES_PASSWORD}}@umami-db:5432/umami"
},
"secretEnv": ["DATABASE_URL", "APP_SECRET"],
"restart": "unless-stopped"
}
],
"configFields": [
{ "key": "POSTGRES_PASSWORD", "service": "umami-db", "label": "Database password",
"help": "Auto-generated. Also inlined into the app's DATABASE_URL.",
"generate": "secret", "secret": true },
{ "key": "APP_SECRET", "service": "umami", "label": "App secret",
"help": "Signs session tokens. Auto-generated.", "generate": "secret", "secret": true }
],
"endpoints": [
{ "service": "umami", "port": 3000, "label": "Dashboard", "kind": "http" }
],
"settings": [
{
"id": "tracking",
"label": "Tracking",
"description": "How the tracker behaves on your sites.",
"fields": [
{ "key": "DISABLE_TELEMETRY", "service": "umami", "label": "Disable telemetry",
"help": "Stop Umami sending anonymous usage data upstream.",
"type": "boolean", "trueValue": "1", "falseValue": "0", "default": "0",
"requiresRedeploy": true },
{ "key": "TRACKER_SCRIPT_NAME", "service": "umami", "label": "Tracker script name",
"help": "Rename the tracker script to dodge ad blockers, e.g. \"stats\".",
"type": "text", "advanced": true, "requiresRedeploy": true }
]
}
],
"connection": {
"title": "Umami",
"description": "Sign in to the dashboard, then add a website to get its tracking snippet.",
"outputs": [
{ "id": "dashboard", "label": "Dashboard", "source": "publicUrl:umami",
"kind": "url", "recommended": true }
],
"firstLogin": {
"username": "admin",
"password": "umami",
"note": "Change this immediately after the first sign-in."
}
}
}
```
The image tag above is illustrative. Check the project's releases and pin the version you actually
tested.
### Going further
Two fields worth knowing for richer apps, both covered in the reference:
- **[`prepare`](/docs/reference/app-catalog#prepare)** runs a command **inside** a service container
after start — never a host shell — and can capture its stdout into an env var. This is how an app
creates a first bucket or mints an admin key. Must be re-run safe, or gated with `once`.
- **[`provides` / `requires`](/docs/reference/app-catalog#provides-and-requires)** wire apps to each
other: `provides` advertises a connectable bundle (an S3 endpoint plus its keys), and `requires`
declares something this app needs from another project, which the wizard offers a picker for.
`packages/core/src/apps/catalog/minio.json` is a good real example of both.
### Build a service instead of pulling an image
Every service so far has pulled a prebuilt `image`. Some apps can't — the upstream ships a base image
that still needs extra packages and a provisioning entrypoint baked in (Neon's compute node is the
canonical case). For those, give the service a **`build`** instead of an `image`: an inline Dockerfile
plus its build-context files, which Openship materializes and `docker build`s on the deploy host at
deploy time. Set **exactly one** of `image` or `build` per service.
```json
{
"name": "compute",
"build": {
"dockerfile": "FROM ghcr.io/example/base:1.2.3\nRUN apt-get update && apt-get install -y curl jq\nCOPY compute/start.sh /start.sh\nRUN chmod +x /start.sh\nENTRYPOINT [\"/start.sh\"]\n",
"files": [
{ "path": "start.sh", "content": "#!/bin/sh\nexec my-server --config {{config:SERVER_MODE}}\n" }
]
}
}
```
The one thing to get right: **COPY sources are prefixed by the service name**. Each buildable service
is materialized under a subdir named after it inside one shared context, so a `files[].path` of
`start.sh` on service `compute` is copied as `COPY compute/start.sh …`, not `COPY start.sh …`.
`{{config:KEY}}` resolves in both `dockerfile` and `files[].content`; a Dockerfile `ARG` is fed from
the project's build env (declare it as `environment` / a `configField`, no separate args map). Full
rules in **[Building an image](/docs/reference/app-catalog#building-an-image)**.
## Give it a logo
`logo` is an id resolved by the shared `AppLogo` component in `packages/ui/src/AppLogo.tsx`:
- **On [simpleicons](https://simpleicons.org)?** Set `logo` to the slug (`"umami"`, `"ghost"`,
`"grafana"`) and you are done.
- **Not there, or the mark renders wrong?** Drop an SVG at
both `apps/dashboard/public/app-logos/.svg` and `apps/web/public/app-logos/.svg`, then add
a `BRAND_LOGO` entry mapping the id to it. Apps without a usable mark receive a fallback.
## Regenerate and validate
The bundle imports one merged artifact, so regenerate it and run the catalog test:
```bash
cd packages/core
bun scripts/gen-catalog.ts # rewrites src/apps/catalog.json from catalog/*.json
bunx vitest run src/apps/catalog.test.ts # asserts sync + every app passes the full schema
```
The test checks the merged file is in sync **and** that your entry passes validation — required
fields, valid `category`, and every [referential rule](/docs/reference/app-catalog#validation) (each
`service` reference resolves, each `output.source` is well-formed, and so on).
Order in `catalog.json` is preserved from the existing file (curated, featured-first); a **new** app
is appended alphabetically, so reorder it by hand if you want it featured earlier.
### Preview your local changes
Run the API with `NODE_ENV=development` and open the app's install page. Development uses the
regenerated catalog from your checkout for both the form and installation. GitHub's published
catalog does not replace local changes, so you can preview an unpublished layout or template.
Regenerate `catalog.json` after each edit as shown above.
## Ship it
Set `"available": true` once it deploys cleanly end to end. Until then it shows as *coming soon* and
install is refused server-side, not just hidden in the UI.
In production, the runtime catalog is the bundled copy overlaid by a live fetch of `catalog.json`
from the repo, on a 10-minute TTL. So your app appears on instances that are already running — gated per-entry by
[`minEngine`](/docs/reference/app-catalog#stability-and-versioning). If your definition uses a
capability that only shipped in a given release, set `minEngine` to it: older instances then show a
guided *Requires Openship ≥ X* card instead of failing the install.
## What the user sees on install
Four named phases, rendered as a stepper:
| Phase | Meaning |
|---|---|
| **Preparing images** | Pulling or building. Skipped for pull-only apps. |
| **Starting services** | Creating and starting the containers. |
| **Finishing setup** | Your `prepare` steps. Present only if the app declares any. |
| **Live** | Done — the Connection card is available. |
You can label your own `prepare` steps in that third phase with `title` and `description`.
## Checklist
- [ ] **Open-source** app; **official or reputable** image **pinned** to a version.
- [ ] `catalog/.json` created, `id` matches the filename, kebab-case.
- [ ] Services wire by name; one service `exposed` with an `exposedPort`.
- [ ] Secrets use `generate` with `secret: true` — no plaintext credentials anywhere.
- [ ] Env that *embeds* a secret (a connection URL) is listed in `secretEnv`.
- [ ] Anything the user types is an `installStep` setting, not a `configField`.
- [ ] `connection` gives the user the URLs and keys they need, with `secret: true` on credentials.
- [ ] Logo resolves — simpleicons slug, or matching bundled assets plus a shared `BRAND_LOGO` entry.
- [ ] `bun scripts/gen-catalog.ts` run and `catalog.json` committed.
- [ ] `bunx vitest run src/apps/catalog.test.ts` passes.
- [ ] `minEngine` set if the definition uses a recently added capability.
- [ ] `available: true` only once it deploys cleanly end to end.
## Upload a custom app (no pull request)
The same JSON, kept private to your organization and needing no review. In the dashboard open
**Apps → Add a custom app**, paste or upload the file. Or over the API:
```bash
curl -X POST https://your-host/api/apps/custom \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H 'Content-Type: application/json' \
--data @umami.json
```
It runs through the **same strict validation** as the curated catalog and installs through the normal
services pipeline, with the same in-container boundary as any project you deploy yourself — no new
privilege. Four rules are enforced:
- **Always unverified.** Trust comes from provenance, never the file: `verified` and `available` are
set by the server, so a JSON claiming `"verified": true` is ignored.
- **`kind` must be `template`.** Flow apps point at built-in wizards and cannot be uploaded.
- **The `id` cannot shadow a built-in.** Curated apps always win.
- **It must validate**, with the offending detail returned in the error.
## See also
- [App catalog JSON](/docs/reference/app-catalog) — every field, in detail
- [Apps API](/docs/api/apps) — catalog, install, custom apps, settings, connection
- [Compose / multi-service](/docs/guides/compose-multi-service) — the engine an app deploys through
---
# Connect your own server
URL: https://openship.io/docs/guides/custom-servers.md
Add one of your own machines over SSH and let Openship install everything it needs to run your apps.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Openship can run your apps on a machine you already own — a cheap VPS, a spare box, a rented cloud
server. You hand Openship the address and a way to log in over **SSH** (the standard secure way to
control a remote computer from a terminal), and it does the rest: it connects, checks what's already
installed, and sets up the missing pieces for you.
Think of it like hiring a mover who also assembles the furniture. You give them the keys to the new
place; they show up, bring the tools, and get the room ready. You don't have to install anything by
hand.
- A **self-hosted** Openship (connecting your own servers is a self-hosted feature — on Openship Cloud we run the machines for you).
- A server you can reach over SSH — Ubuntu, Debian, or a similar Linux works well.
- A way to log in: an **SSH key**, a **password**, or your machine's **SSH agent**.
- That's it. You do **not** need to pre-install Docker or anything else — Openship installs what's missing.
## Steps
### Open the Servers page and start adding
In the dashboard, open the **Servers** page and press **Add Server**. (If this is your first server,
the empty page has an **Add Your First Server** button that does the same thing.)
### Fill in the SSH connection form
This is the "who am I connecting to, and how" screen. The fields:
- **Server Name** — an optional label like `Production` or `Staging`, just so you can tell servers apart. Leave it blank and Openship uses the IP address.
- **Connection** — choose **Direct SSH** or **Cloudflare Access** for an existing Access SSH application.
- **Server IP Address** — the address of your machine, e.g. `203.0.113.10`.
- **Port** — the SSH port. Almost always `22` (the default).
- **Username** — the user to log in as. Usually `root`.
- **Authentication** — pick one:
- **Password** — type the server's password.
- **SSH Key** — give the path to your private key file (like `~/.ssh/id_ed25519`) and, if the key has one, a passphrase.
- **Agent** — use the SSH agent already running on the machine that hosts Openship (like VSCode does). No password or key needed here, but that host must already be allowed to log in to the server.
There's an **Advanced** section too, for a **Jump Host** (a bastion server you must hop through first)
and **Extra SSH Arguments** — you can ignore both unless you know you need them.
For Cloudflare Access, enter the application's hostname (`ssh.example.com`) and your server's SSH
credentials. Complete the Cloudflare login on the same machine and under the same OS user that runs
OpenShip. Windows desktop includes the Cloudflare client. For a self-hosted instance or macOS/Linux,
install `cloudflared` on the machine running the API, or set `OPENSHIP_CLOUDFLARED_PATH` to its absolute
path. A containerized API needs the client and its authentication inside the container. The server's
SSH port stays behind the Cloudflare Tunnel; you do not need to expose port 22 publicly for this route.
The CLI uses the same connection setting:
```bash
openship server add --name Production --host ssh.example.com --ssh-transport cloudflare --auth-method agent
```
Press **Test Connection** first. Openship tries to log in and reports back without saving anything. A
green **Connected** means your details are right. Fix any red message before moving on — it saves you
guessing later.
When the test passes, press **Save & Continue to Setup**.
### Choose how to set the server up
Once the server is saved, Openship offers two ways to install what's needed:
- **Automatic Setup** — one click. Openship checks the server and installs everything missing for you.
- **Step-by-Step Setup** — you review each component and choose what to install, seeing detailed status first.
If you're new, pick **Automatic Setup**.
### Watch the core components install
Openship now connects over SSH and installs what your apps need to run. You'll see each piece light up
as it finishes, with a live log you can expand.
Setup installs the **core** components first — the ones the server can't run apps without:
- **Docker** — the container runtime that actually runs your apps.
- **Git** — used to pull your source code.
The routing and certificate tools aren't installed now. Openship adds them **automatically later**, the
first time a deployment actually needs them — you never install them by hand:
- **OpenResty** — the reverse proxy that routes web traffic to the right app. Added the first time an app needs a public web address.
- **Certbot** — provisions free HTTPS certificates from Let's Encrypt, so your sites get SSL. Added the first time an app needs HTTPS.
- **rsync** — fast file transfer, added when a build is made elsewhere and copied to the server.
Once any of these is installed, it shows up on the server's **Components** tab (below), where you can
re-check, reinstall, or remove it. When setup finishes, you land on the server's own page.
## What's on the server page
Each server gets its own page, split into tabs. From here you can see how it's doing and manage it.
- **Overview** — live stats for the machine: CPU, memory, disk, uptime, and load, plus a quick list of which components are healthy.
- **Components** — the health list for this server. **Re-check** re-runs the checks, **Install Missing** installs any core components the server still needs, and each installed component can be reinstalled or removed.
- **Security** — request **rate limiting** (see below) and a **port-exposure scan** that lists which ports are listening and flags any bound to a public interface vs loopback-only.
- **Terminal** — a live SSH shell right in the browser, so you can poke around the server without leaving Openship. Up to 3 shells at once.
- **Ports** — port forwarding (**desktop app only**, see below).
The header also has **Edit** (change the connection details) and, in the "…" menu, **Remove Server**
(which clears the stored SSH credentials and settings).
### Rate limiting (Security tab)
Rate limiting caps how many requests a single visitor can make per second, so one noisy client (or a
bad bot) can't swamp your apps. It's applied at the OpenResty level for the whole server.
Set **Requests / second** to turn it on. Openship picks a sensible **burst** allowance automatically
(a small buffer for short spikes), or you can set your own under **Advanced**. You can also add
**Whitelisted IPs** — addresses or CIDR ranges (like `10.0.0.0/8`) that skip the limit entirely.
Loopback (`127.0.0.1`, `::1`) is always whitelisted. Setting requests per second back to `0` removes
the limit.
### Port forwarding (Ports tab, desktop only)
If you run Openship as the **desktop app**, the **Ports** tab lets you reach a port on the remote
server as `localhost` on your own computer — the same idea as VS Code's port forwarding. Enter the
**remote port**, optionally a **local port** (leave blank to auto-pick), and start the forward. It's
bound to loopback only and stays active just while it's running. This tab is hidden outside the
desktop app.
## CLI
Everything above works from the CLI. You must be logged in (`openship login`) and on a self-hosted
Openship.
```bash
# Add a server (this validates the connection, then saves it)
openship server add \
--name production \
--host 203.0.113.10 \
--user root \
--auth-method key \
--key-path ~/.ssh/id_ed25519
# List your servers to grab the id you'll need below
openship server list
# See what's installed on that server
openship server check
# Install the missing pieces, streaming the logs live
openship server install --component docker git openresty --follow
```
You can also test a connection without saving it, watch live stats, or manage rate limiting:
```bash
# Try credentials without creating a server entry
openship server test-connection --host 203.0.113.10 --user root --auth-method key --key-path ~/.ssh/id_ed25519
# Stream live CPU / memory / disk stats (Ctrl-C to stop)
openship server monitor
# Set a rate limit of 50 req/s (use --rps 0 to remove it)
openship server rate-limit --rps 50 --burst 20
```
The installable components are `docker`, `git`, `openresty`, `certbot`, and `rsync`.
## Troubleshooting
Openship couldn't open an SSH connection. Check that the machine is powered on, that its SSH service
is accepting connections on the port you entered (usually `22`), and — if it's behind a firewall or
NAT — that the host is reachable from where Openship is running. The server page shows this as a
**Can't reach** banner with the exact host and port.
Openship reached the server but the login was refused. The key or password you saved doesn't match
what the server allows in its `~/.ssh/authorized_keys`. Open **Edit** on the server and fix the
credentials, then run a health check again. If you chose **Agent**, make sure the host running Openship
actually has a working key loaded for that server.
Open the **Components** tab and expand the install log — the last red lines say why. Common causes are
no internet access on the server or a package manager that's busy or locked. Fix it on the server, then
press **Re-check** and **Install Missing** to retry just the parts that failed.
The Security tab reads its settings from OpenResty. If OpenResty isn't installed (or isn't reachable)
you'll see a "couldn't read" message. Install OpenResty from the **Components** tab first, then return
to **Security**.
## Related guides
---
# Database migrations & stateful safety
URL: https://openship.io/docs/guides/database-migrations.md
Safely back up and migrate a persistent database (MySQL/Postgres) volume around a deploy — using Openship's pre-deploy backup trigger and post-deploy jobs.
If a service in your project has a **Docker volume** (MySQL, Postgres, Redis, Qdrant…), two things about
deploys are worth understanding:
1. A container's `docker-entrypoint-initdb.d` scripts only run on **first initialization** — i.e. when the
volume is empty. Once the volume has data, those scripts never run again, so you **cannot** rely on them
to apply a schema migration to an existing database.
2. On a full-stack deploy, a stateful container may be **recreated**. Its named volume is preserved (the
data survives), but recreate is still a high-stakes moment for production.
Openship gives you two building blocks to make this safe — a backup *before* the deploy and a migration
*after* it — plus a way to avoid touching the database at all.
## Don't touch the database on an unrelated change
The simplest safety measure: only deploy the services that changed. A backend code change shouldn't
recreate your database container.
```bash
openship deploy --service-ids api,web
```
Services you don't name carry forward on their existing containers, untouched. See
[Compose / multi-service](/docs/guides/compose-multi-service).
## Back up before every deploy (rollback safety net)
Create a **backup policy** for the stateful service and enable its **“trigger on pre-deploy”** option.
By default, Openship **waits for every backup run to succeed before building or starting the new
release**, including when a previous build is reused. This keeps startup migrations from overlapping
the dump's database locks. The existing deployment remains in place while the backup runs.
- Set it up in **Backups** (see [Backups & restore](/docs/guides/backups-restore)); pick an S3/volume
destination and turn on the pre-deploy trigger.
- Deployment logs show each backup's status, elapsed time and uploaded bytes, with progress updates
every 30 seconds. Long backups continue automatically; **Stop deployment** remains available.
- Once all backup workers have finished cleanup, a failed backup opens the deployment decision dialog:
**Retry backup** retries the failed sources; **Continue without backup** explicitly bypasses them
for this deployment; **Stop deployment** ends the attempt. A policy that could not start uses the
same dialog. The decision and backup progress remain in the deployment logs. Skipping does not
disable the policies or turn a failed run into a restore point.
- Without a response, the dialog times out and stops deployment (five minutes by default, configurable
with `OPENSHIP_PROMPT_TIMEOUT_MS`). A missing/unreadable backup or a worker still running at the
six-hour ceiling **stops the deploy without offering a bypass**: its database locks may still be held.
- Runs are grouped as `pre_deploy` in backup history. Project policies wait for every service's run.
- PostgreSQL dumps must exit successfully. A dump smaller than **1% of the median of up to three recent
comparable successful backups** is rejected before it becomes a restore point. Comparisons use the
same policy, destination, service, database and compression format. If a reduction of more than 99%
is intentional, verify the database and create a new policy to establish a fresh baseline. This
size check complements regular restore testing; it does not replace it.
## Run a migration after the deploy
For applying a schema/data migration to an **existing** volume, use a **Job** that fires when the deploy
finishes:
1. Go to **Jobs** (see [Scheduled jobs](/docs/guides/jobs)) and create a **command** job.
2. Set its trigger to the **“Deploy succeeded”** event.
3. Point the command at your migration tool. Examples:
**Postgres** (dbmate / Flyway / plain psql):
```bash
# a one-shot migrator container on the same network as your db service
docker run --rm --network \
-e DATABASE_URL="postgres://user:pass@db:5432/app" \
ghcr.io/amacneil/dbmate:latest up
```
**MySQL** (apply a versioned file):
```bash
docker run --rm --network \
mysql:8 sh -c 'mysql -h db -u user -ppass app < /migrations/0007.sql'
```
The safe sequence is: **pre-deploy backup** (automatic, if the policy toggle is on) → new version deploys →
**post-deploy migration job** runs against the now-updated volume. If the migration fails, restore the
`pre_deploy` snapshot from the backup history.
## What Openship does NOT do (yet)
There is no built-in **gating** pre-deploy migration step that blocks the app from starting until a
migration completes — the post-deploy job runs *after* the new container is live. If your app strictly
requires the schema to be migrated before it boots, run the migration as its own deploy step in your image
(e.g. an entrypoint that runs `migrate` then `exec` the app) or keep the app tolerant of a brief
migration window. A first-class gating pre-deploy hook is on the roadmap.
---
# Connect to Cloud & migrate
URL: https://openship.io/docs/guides/cloud-connect-migration.md
Link the copy of Openship you run yourself to Openship Cloud, move a single project up or bring it home, and (at a high level) open your instance up to a whole team.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Openship can run in two places. One is **your own instance** — the copy you installed and manage yourself.
The other is **Openship Cloud** — the managed version, where we run the servers, SSL, and the global network
for you. Think of it like a workshop: you can build things in your own garage, or rent a fully-equipped bench
at a shared makerspace. This guide is about connecting the two, and moving work between them.
There are three separate things people mix up, so let's name them up front:
- **Connecting** — link your instance to a Cloud account so cloud features light up. Nothing moves.
- **Promoting a project** — take one existing project and hand it to Cloud to run. It moves.
- **Team-mode migration** — turn your whole single-user instance into a shared, multi-user setup.
- Your own Openship instance, up and running (you can see the dashboard). The **Cloud** settings tab only
appears on self-hosted instances — on Cloud itself there's nothing to connect.
- To be the **workspace owner**. Connecting and disconnecting Cloud is an owner-only action.
- An Openship Cloud account. You sign in — or create one — in the window that opens during the connect step, so you don't need one beforehand.
## Connect your instance to Openship Cloud
This links your instance to a Cloud account. Existing Cloud projects, apps and managed servers appear
alongside your local resources. Connecting does not move projects or duplicate their settings.
### Open the Cloud settings
In the dashboard, go to **Settings** and choose the **Cloud** tab from the left. You'll see a card that says
**Connect to Cloud** with a **Connect to Openship Cloud** button.
### Sign in and give consent
Press **Connect to Openship Cloud**. A window opens on Openship Cloud and asks you to sign in.
Review the account and active **Organization** on the consent screen before pressing **Authorize**.
Use **Switch** beside the account to sign in with another account, or beside Organization to choose
another workspace. Switching keeps the connection request and requires you to authorize again.
If organizations cannot be loaded, use **Try again**; the connection stays unauthorized.
When the window closes, the card flips to a green **Connected** badge showing the Cloud account you linked.
After connecting, your projects still run where they were. Opening a Cloud project uses its Cloud settings,
history and operations through your instance. Local projects keep their local settings. Managed server
purchases and billing stay in Cloud. To move a project, see the next section.
### Disconnecting
On the same card, **Disconnect** unlinks the account. Running workloads continue on their servers, but
this installation cannot manage Cloud resources or start new work through that connection until you
reconnect. Cloud inventory refreshes immediately, and any explicit local server links remain visible
with their connection unavailable. Repositories using the shared Cloud GitHub connection also require
reconnection.
## Move one project to Cloud (and back)
Once connected, you can hand a single self-hosted project to Cloud to run — this is called **promoting**. You
can also pull a cloud project back down to your own instance — **bringing it home**.
This is the important boundary. **Once a project lives on Openship Cloud, Cloud owns it** — the cloud copy is
the one true copy. Your instance keeps a pointer to it and acts as a gateway in front of it, so it still shows
up in your dashboard, but the real project lives on Cloud. Bringing it home reverses that and makes your
instance the owner again. For the full picture, see [Cloud as source](/docs/architecture/cloud-as-source).
Today this move is done from the **CLI**. Both directions are self-hosted-only, and your instance must be
connected to Cloud first (from the section above).
```bash
# Promote a project up to Openship Cloud (Cloud runs it from now on)
openship project transfer to-cloud
# Bring a cloud project back to your own instance
openship project transfer to-self-hosted
```
You can find a project's id with `openship project list`. Under the hood these call
`POST /api/projects/:id/transfer/to-cloud` and `.../to-self-hosted`.
## Keep your instance online for a team
Choose **Settings → Instance → Move to a server**. Select your own server or a connected
managed Cloud server, then choose API-only access through Desktop or API + dashboard.
Your workspaces and credentials move together while existing apps stay on their servers.
The Team tab links to this same flow; there is no separate migration chooser.
Moving a control plane is separate from transferring a project to Openship Cloud. Your
Cloud-owned projects continue to be managed by Cloud, and the transferred Cloud connection
keeps them accessible from the relocated instance.
See [Move your Openship instance](/docs/guides/migrate-control-plane) for prerequisites,
recovery, and moving the latest data back to Desktop. Team members can connect their own
Desktop without becoming instance administrators.
## Troubleshooting
The **Cloud** tab only shows on a self-hosted instance. If you're already using Openship Cloud, there's
nothing to connect — cloud features are on by default. If you *are* self-hosting and still don't see it, make
sure you're signed in as the workspace **owner**.
A `transfer` or a Cloud migration ran before the instance was linked. Connect first in **Settings → Cloud**
(you must be the owner), then run the command again.
The sign-in or consent step didn't finish. Press **Connect to Openship Cloud** again and complete both the
sign-in and the **Authorize** step in the popup. If your browser blocks pop-ups, allow them for the dashboard
and retry.
## Related guides
---
# Scheduled jobs
URL: https://openship.io/docs/guides/jobs.md
Run commands on connected or managed servers, with schedules, retries, logs and notifications.
Jobs run commands or saved Actions workflows on a **schedule**, once, on demand,
or after an event. Find them under **Jobs** in self-hosted Openship and Openship Cloud.
Every run is recorded — when it last ran, whether it succeeded, how long it took,
and its output.
## Built-in jobs
Self-hosted installations also show the system jobs Openship runs for you.
Cloud maintenance is managed privately by the platform; Cloud customers see
their own command jobs and authorized backup schedules.
| Job | What it does | Default schedule |
|---|---|---|
| SSL certificate renewal | Renews Let's Encrypt certificates before they expire | daily |
| Orphaned resource cleanup | Reclaims leftovers from a failed teardown | hourly |
| Backup retention prune | Deletes backups past their retention window | daily |
| Audit log prune | Trims old audit entries per your retention setting | daily |
| Deployment reconcile | Settles deploys interrupted by a connection blip | every 10 min |
An instance administrator can **change the schedule**, **enable/disable** it,
**Run now**, and see its **run history**. You can't delete a built-in job (it's
part of Openship) — disable it instead.
## Your own jobs
Need a nightly database dump, a cache warm, or a cleanup script? Create a custom
job:
1. In **Jobs**, click **New job**.
2. Give it a **name**, pick the **server** it runs on, enter the **command**, and
a **schedule** (cron).
3. Save. It runs on that schedule, and you can **Run now** any time.
While a job runs you can watch its **live output**, and every run is kept in
history with its result.
### Run a workflow
Choose **Run workflow** in the new-job form, or **Schedule with Jobs** from an
Actions workflow. Select an enabled workflow with `workflow_dispatch`, fill its
declared inputs, and choose a schedule or event. Runner selection, secrets and
storage remain on the workflow; Jobs controls when it starts.
History and notifications use the original Actions run. Open that execution to
see its dependency graph, step logs and cancellation controls. Success dependencies
fire after the workflow completes and its worker cleanup finishes. Replayed timer
or dependency deliveries reuse their execution identity. Disabling or revoking
access to the workflow prevents new authorized execution.
See [Openship Actions](/docs/guides/actions) for runner setup, triggers and project
deployment rules.
### Choosing a Cloud server
Select an existing managed server to share its resources with your projects,
or click **Add a dedicated server** to create a server with its own subscription.
The same job form supports both. You can also select several servers to run the
command on each one.
Jobs use the selected server's capacity and usage allowance. The server must be
running and its subscription and balance must allow new work. A job does not
provision or resume a server automatically. **Run now** opens the server's plan
options if billing prevents execution; scheduled attempts record the failure
in run history. Provision or resume a paid server from **Servers** when needed.
Commands execute on the server itself. To run a temporary container task, use
`docker run --rm ` on a server with Docker available. Jobs have
the server's command privileges, so configuring or reading a job requires
administration access to all its targets as well as Jobs permissions.
## Schedules (cron), in plain terms
A schedule is a standard 5-field cron string:
```
┌───────── minute (0–59)
│ ┌─────── hour (0–23)
│ │ ┌───── day of month (1–31)
│ │ │ ┌─── month (1–12)
│ │ │ │ ┌─ day of week (0–6, Sun=0)
* * * * *
```
| Cron | When |
|---|---|
| `0 3 * * *` | every day at 03:00 |
| `*/15 * * * *` | every 15 minutes |
| `0 * * * *` | every hour, on the hour |
| `0 2 * * 0` | every Sunday at 02:00 |
| `30 4 1 * *` | 04:30 on the 1st of each month |
Openship validates the cron when you save and shows the **next run time**.
Triggering a job manually with **Run now** is saved in history just like a
scheduled run, marked as manual — so you always have a full record.
## CLI
Use `openship job` (alias `jobs`) with your Cloud or self-hosted connection context:
```bash
openship job list
openship job create --name weekly-sync --server \
--command 'cd /srv/app && npm run db:sync' --cron '17 4 * * 1'
openship job get
openship job update --no-enabled
openship job update --enabled --cron '0 3 * * *'
openship job run --follow
openship job runs --limit 10
openship job logs --follow
openship job delete --yes
```
Jobs also work with `openship --native-config job ...` through the native SDK.
Use the job **key** from `list` or `create`, not its database ID. For a one-time
job, pass `--schedule once --at `. For manual execution only, pass
`--schedule manual`. Recurring jobs use `--cron`.
Both `create` and `update` accept `--file ` containing a JSON Jobs API body.
Use it for `workflowId` and `inputs`, or `env`, `secrets`, `serverIds`, `retry`, `timeoutMs`, `dependsOn`,
`triggerEvents`, or `notifyConfig`, or to supply the entire job configuration.
Explicit flags override file values. Updates send only supplied fields. Keep
files containing secrets private. The API encrypts secrets at rest.
`--json` returns API data without the envelope. Followed runs emit JSON events.
Without `--follow`, `run` returns a custom run ID immediately. With `--follow`,
the CLI waits for the outcome and exits nonzero on failure or an interrupted
stream. Built-in jobs return their summary directly. `logs` without `--follow`
shows stored output, or the full run record with `--json`.
---
# Persistent storage & object storage
URL: https://openship.io/docs/guides/persistent-storage.md
Keep the files your app writes — pick the paths that survive a redeploy, or connect an S3 bucket so uploads live outside the container entirely.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Every deploy replaces your app with a fresh copy. That's what makes deploys safe to repeat — and it's also
why a file your app wrote yesterday is gone today unless you tell Openship to keep it. This page covers the
two ways to do that: **persistent storage** for paths on the machine, and **object storage** for a bucket
that lives outside your app altogether.
- **Uploads that users must never lose** → object storage (a bucket). It also keeps working if you run more
than one copy of your app.
- **A cache, a SQLite file, a framework's own scratch directory** → persistent storage (a path).
- **A real database** → neither. Add a database service and connect it (see
[Multi-service projects](/docs/guides/compose-multi-service)).
## Persistent storage (paths that survive a deploy)
Openship already knows what some frameworks write. A Laravel app keeps `storage/` with no configuration at
all, because that's where Laravel puts uploads, sessions, cache and its logs. Open **Configuration →
Persistent storage** to see what your project keeps.
### Open Configuration → Persistent storage
The card lists the paths currently kept. It also tells you WHERE the list came from: *"Framework defaults for
this stack"* means Openship chose it, *"Set for this project"* means you did.
### Press Edit and list the paths, one per line
A plain path is relative to your app:
```
storage
public/uploads
```
You can also give a full mount if you want to control the volume name or use a directory on the host:
```
uploads:/app/public/uploads
/srv/app-data:/app/var
```
### Save, then deploy
Storage changes apply on the **next deploy** — the running container keeps the mounts it started with.
To go back to the framework's own defaults, press **Use framework defaults**. To keep nothing at all, save an
empty list — that's a real choice, and Openship won't quietly re-add the defaults.
You can declare the same thing in your repo instead, so a fresh deploy of the same code gets it automatically:
```json title="openship.json"
{
"volumes": ["storage", "uploads:/app/public/uploads"]
}
```
### Things worth knowing
- **The first deploy seeds the directory.** Whatever your app ships at that path (Laravel's `storage/`
skeleton, for instance) is copied in, so the app doesn't start against an empty directory.
- **Later releases don't refresh it.** That's the point — it's your data now, not the image's. So don't list
a path that also contains code. Laravel's `database/` directory holds migrations as well as the SQLite
file, which is why Openship keeps `storage/` and not `database/`.
- **Volume names are scoped per project.** Two projects that both keep `storage` never share one volume.
- **Multi-service projects** declare mounts per service instead — see the Services tab, or
`services[].volumes` in `openship.json`.
- **Openship Cloud has no volumes.** A declared path is reported and skipped there; use object storage.
## Object storage (an S3 bucket)
A path on the machine stops data loss, but it doesn't scale: run two copies of your app and each one gets its
own uploads directory, which shows up as files that exist for some visitors and 404 for others. A bucket is
shared by every copy and outlives the machine.
Openship connects a bucket to your app's own filesystem configuration, so you don't have to hunt for the
right variable names. A Laravel app gets `FILESYSTEM_DISK=s3` plus the `AWS_*` variables its S3 disk reads; a
Django app gets the `AWS_STORAGE_BUCKET_NAME` / `AWS_S3_*` names django-storages reads; anything else gets
neutral `S3_*` names.
### Open Configuration → Object storage and press Connect
### Choose where the bucket comes from
**An installed MinIO app** — if you've installed MinIO from the Apps catalog, pick it here. Its endpoint and
keys are filled in for you, and your app joins its private network, so the traffic never leaves the box. The
bucket MinIO created on install is prefilled.
**An external provider** — Amazon S3, Cloudflare R2, Wasabi, Backblaze B2, DigitalOcean Spaces, or any other
S3-compatible service. Enter the endpoint (not needed for Amazon S3), region, bucket, and the access key +
secret.
### Press Test & connect
Openship writes, reads and deletes one throwaway object before saving anything. If the bucket doesn't exist
or the keys are read-only, you find out here — not the first time a user uploads a file.
The card then shows the bucket, the provider, and exactly which variables were set. It applies on the next
deploy. **Disconnect** removes those variables again — only the ones the connection added, never anything you
set by hand.
The keys are stored as encrypted environment variables on the project, the same place all your secrets live.
There's no second copy anywhere, and deleting the connection deletes them.
### Using the bucket from your code
Once connected, your framework's normal file API writes to the bucket — `Storage::put(...)` in Laravel,
`default_storage` in Django. For other stacks, read the `S3_*` variables the card lists and hand them to your
S3 client of choice.
---
# Deploy from GitHub
URL: https://openship.io/docs/guides/deploy-from-github.md
Connect a GitHub repository and put it online — the step-by-step way and the one-command way.
import { Step, Steps } from 'fumadocs-ui/components/steps';
This is the most common thing people do with Openship: take some code that lives on GitHub and make it a
real, working website with its own address. Think of it like this — your code is a recipe, and Openship is
the kitchen that cooks it and serves the meal. You point Openship at the recipe once, and it does the rest.
- An Openship account (you're already in if you can see the dashboard).
- A GitHub repository with your app in it.
- That's it. You do **not** need Docker, a server, or any config files — Openship figures those out.
## Steps
### Connect your GitHub account (once)
Openship needs permission to read your repository. You only do this one time.
Go to **Settings → Git** and choose a GitHub connection method. A GitHub window may open asking "do you allow
this?" — say yes. When it closes, you're connected.
On a self-hosted instance you're never forced through Openship Cloud. **Settings → Git** offers:
- **Openship Cloud GitHub App** — the managed App (short-lived tokens, great for remote-server deploys).
Optional; it needs an Openship Cloud connection.
- **Your own self-hosted GitHub Apps** — use the one-click manifest flow or register one or more existing
GitHub/GitHub Enterprise Apps in the dashboard, then use installation tokens without Openship Cloud or PATs. See
[Self-hosted GitHub App](/docs/guides/self-hosted-github-app).
- **Manual** — connect with your **own** GitHub identity, no Openship in the middle:
- **`gh` CLI on the instance** — press **Log in with GitHub**; if the instance has `gh` authenticated
it's picked up immediately, otherwise run the shown `gh auth login` on the box and the page detects it
automatically.
- **Your own GitHub OAuth/App (device login)** — set **`GITHUB_CLIENT_ID`** (a public client id from a
GitHub App/OAuth app *you* register, with device flow enabled) and **Log in with GitHub** shows a
one-time code + `github.com/login/device` link right in the UI — no terminal, no Openship client id.
- **A clone token** — or just add a personal access token under **Clone credentials**.
Pick whichever fits; Openship never substitutes its own GitHub identity for yours on a self-hosted box.
### Pick the repository you want to deploy
Open the **Library** page (the "New project" button takes you here too). Choose the **Repositories** tab —
you'll see a list of your GitHub repos. Click the one you want.
### Choose where it should run
Openship asks where to run your app. Pick the one that fits:
- **Local** — on this computer (great for trying things out on the desktop app).
- **Server** — on one of your own connected servers.
- **Cloud** — on Openship Cloud, where we run it for you.
If you're just starting, the default choice is fine — you can move it later.
### Check the settings and press Deploy
Openship shows a summary: which framework it detected, the build command, and the web address it will use.
For most apps you don't change anything here.
Press **Deploy**.
See a field you don't recognize? Leave it. Openship's detected defaults are correct for the large majority
of apps — you only override things when you have a specific reason.
### Watch it go live
You land on the build screen, which streams the logs live — like watching the oven through the glass door.
When it finishes, you get a link. Click it, and your app is online. 🎉
## Turn on auto-deploy (optional but great)
By default you deploy when you choose to. If you'd like Openship to **redeploy every time you push to
GitHub**, turn on auto-deploy:
Open your project → **Source** tab → switch on **Auto-deploy**. From now on, every `git push` to your
deploy branch rebuilds and ships automatically.
## GitHub deployment Checks
GitHub-backed projects report their deployment result and individual service results on the
deployed commit by default, on both self-hosted Openship and Openship Cloud. This requires a
connected GitHub App with **Checks: Read and write** access to the repository. A clone token
alone does not enable this integration.
Open **Project → Source → GitHub deployment checks**, or use the same control in the deployment
wizard. Turn reporting off, or expand **Customize checks** to select the overall result,
all services, specific services, and whether to include failure details. These settings apply
to new deployment attempts. Turning reporting off also closes pending Checks from an active attempt.
Checks show queued, running and completed outcomes, including failed builds, cancellations and
partial service failures. Each links to its deployment in Openship. Failure details are redacted
summaries visible to people who can read the repository; full build logs are not attached.
Delivery retries in the background if GitHub is unavailable and never blocks the deployment.
Connection problems appear beside these settings.
Check names include the project and environment: `Openship / / `.
Service Checks append ` / `. If a GitHub repository rule requires an older
`build:` Check, select the new name after its first report.
GitHub's **Re-run** action retries the recorded commit. A service Check retries that service;
the overall Check retries the project. The instance must be reachable by GitHub webhooks to
receive this action. Reporting results itself only needs an outbound GitHub connection.
These deployment results are separate from workflow Checks required before deployment. Configure
those in [Project Actions](/docs/guides/actions).
## CLI
Everything above works from the CLI too:
```bash
# Create a project pointing at your repo
openship project create --name my-app --git-owner your-name --git-repo my-app
# Ship it
openship deploy
# Optional: redeploy on every push
openship project git auto-deploy my-app --enable
```
## Troubleshooting
Your GitHub connection didn't finish, or Openship has no permission for that repo. Go back to
**Settings → General**, disconnect, and connect again — and when GitHub asks which repositories to grant,
make sure your repo is included.
Open the build screen and read the last few red lines — that's the real reason. Most first-time failures
are one of: a missing build command, a missing environment variable, or the app listening on the wrong
port. See [Troubleshooting → Deployments](/docs/troubleshooting/deployments) for the fixes.
## Related guides
---
# Teams & members
URL: https://openship.io/docs/guides/teams-members.md
Invite other people into your Openship workspace, give them the right role, and understand the difference between your personal space and a shared team.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Openship starts out as a space for one person: you. But most real work happens with other people —
a teammate who deploys the app, a designer who just needs to look, a co-founder who owns the whole
thing with you. This guide shows how to bring people in and decide what each of them can do.
Think of your workspace like a shared office. You can hand someone a key (invite them), and each key
opens different doors (their **role**). Some keys open everything; some only open one room.
- An Openship account with a workspace you can see in the dashboard.
- The **email address** of the person you want to invite.
- You must be the **owner** or an **admin** of the workspace to invite people. (More on roles below.)
## Invite someone
If you use Desktop locally, open **Settings → Instance → Move to a server** first.
Choose **Use through Desktop** for an API-only installation, or **Desktop + browser**
to publish the dashboard too. Desktop stays connected to the same remote data,
and invitations and webhooks use that server while your computer is offline.
See [Move your control plane](/docs/guides/migrate-control-plane).
For an API-only instance, the invitation page explains how to open Desktop and
paste the invitation link into **Settings → Instance → More instance options → Connect to an instance**.
The recipient signs in with their own account, accepts the invitation, and joins
the team with their assigned role. The team appears in the organization switcher.
### Open the Team settings
In the dashboard, go to **Settings** and choose the **Team** tab from the sidebar. This page lists
everyone who currently has access, plus any invitations that haven't been accepted yet.
### Press "Invite member"
Click **Invite member** in the top-right. An inline **Invite a member** panel expands on the page.
Only owners and admins can invite people. If you're a plain member, the button is hidden — ask an
owner or admin to send the invite for you.
### Enter their email and pick a role
Type the person's **email** address. Then choose a **role** — one of the cards below the email box.
Each role is explained in the next section; **Member** is the usual choice for a teammate who will
build and deploy.
### Send the invite
Choose **Email** to send through the instance's configured mail service, or **Copy link**
to share the invitation yourself. Both options invite the same email address with
the selected role. When email is unavailable, **Copy link** is selected for you.
Press **Send invite** or **Create invite link**. The panel shows the shareable link,
and the invitation stays under **Pending invitations** until it is accepted or revoked.
In **Email** mode, the delivery menu shows which mail service will send the invite.
Use your configured mail service or, when connected, Openship Cloud. The panel links
to setup if the selected service is unavailable. Copyable links use the instance's
published address, including when you manage it from Desktop.
## What each role can do
A role is just a bundle of permissions. Openship has four, from most powerful to least:
- **Owner** — the person who created the workspace. Can do everything, including changing other
people's roles and removing members. You can't invite someone straight in as owner — but an owner
can promote an existing member to owner later, from the role dropdown on the Team tab.
- **Admin** — everything a member can do, **plus** manage members (send and cancel invites, remove
people). On Openship Cloud, admins can also manage billing.
- **Member** — full read and write access to everything in the workspace: create projects, deploy,
edit environment variables, and so on. A member **cannot** manage other people.
- **Restricted** — starts with **no** access. When you invite a restricted member you pick exactly
which resources (specific projects, servers, and so on) they're allowed to reach. Use this for
someone who should only touch one or two things.
Owner, Admin, and Member are **coarse, high-trust roles**. A **Member** can deploy, create and
**delete** projects and servers, run jobs, manage domains, and read and write environment variables —
nearly everything an Admin can, minus managing people and reading the audit log. The roles differ only
in a narrow band (billing is owner-only; the audit log is owner/admin). So add someone as **Member or
Admin only if you'd trust them with near-admin control** of the workspace.
For a collaborator who should be limited to specific things, use the **Restricted** role with
per-resource grants, or hand out a **scoped / read-only [access token](/docs/security/permissions#access-tokens-follow-the-same-rules)**.
Those are the paths that actually enforce *read vs write vs admin* and confine access to specific
projects or servers — fine-grained, per-action limits for the standard roles are still on the roadmap
(**beta**), so treat a team organization as a **trusted-collaborator** workspace for now.
This is about permissions *inside* one workspace. **Between** organizations, isolation is enforced — one
org can never see or touch another's projects, servers, or secrets (see [Isolation](/docs/security/isolation)).
Only the **owner** can change someone's role. On the Team tab, each member (except you) has a role
dropdown next to their name — pick a new role and it applies right away. Owners and admins can also
**remove** a member with the trash icon; Openship asks you to confirm first. You can't change or
remove yourself.
Giving a member access to a **server** (when inviting, or by editing their access on the Team tab) is a
bigger deal than a role change: on that server they can reach every deployment and its **data**, the apps
running on it, injected **secrets/env vars**, a live **terminal**, and any **GitHub tokens** used for its
deploys. Because of that, Openship shows a **confirmation** that spells out exactly what the new access
exposes before it takes effect. Grant server access only to people you trust with everything on that box.
For the full rules on how permissions and per-resource access are enforced, see
[Permissions & roles](/docs/security/permissions).
## Accept an invite
This is what the *invited* person does after you send it.
### Open the invitation link
Open the link from the email or the person who invited you. It opens a page that says
**You're invited** (or **Join [workspace name]** once you're signed in).
### Sign in or create an account
If you're not logged in yet, the page offers **Sign in** and **Create account**. Use the **same email
address the invite was sent to** — Openship checks that they match.
On self-hosted Openship, the instance administrator can create a brand-new user through this
invitation page. Workspace admins can invite users who already have an account, but they cannot mint
new instance accounts; ask the instance administrator to send the first invitation in that case.
### Press Accept
Once signed in with the right email, the page shows the workspace name and the role you're joining as,
with **Decline** and **Accept** buttons. Press **Accept**. You'll see **You're in**, and Openship
sends you to the dashboard for that workspace.
## Personal vs team workspaces
Every Openship workspace is called an **organization**. When you first sign up, Openship creates a
**personal workspace** just for you — your own projects, servers, and domains, with no one else in it.
You have two ways to work with other people:
- **Invite them into your personal workspace.** Fine for a small group — everyone shares the same
projects and servers. Use the **Invite member** button described above.
- **Create a separate team organization.** A clean, shared space that stays isolated from your
personal projects. On the Team tab (while viewing your personal workspace) you'll see a **Create a
team organization** card — press **Create team**, give it a name, and Openship switches you into the
new shared workspace. Its projects and members are completely separate from your personal ones.
You can belong to more than one organization and switch between them. A team organization has its own
members and roles, exactly as described above.
If it's just you and one or two trusted people, inviting into your personal workspace is simplest. If
you want a shared space that isn't tangled up with your own experiments — or you expect the group to
grow — create a team organization.
## Troubleshooting
The invite was sent to one email but you're signed in with a different one. Sign out, then sign back
in (or create an account) using the exact address the invitation was sent to. If you've lost the link,
ask an owner or admin to copy it from **Pending invitations** or send a fresh one.
Check the spam folder first, then check the instance's selected mail service.
You can copy the existing link from **Pending invitations** and send it directly;
there is no need to create another invitation. For new invitations, choose **Copy link**
if email delivery is unavailable.
Usually this means you don't have permission (only owners and admins can invite) or the person is
already a member. Confirm your own role on the Team tab, and check the **Active members** and
**Pending invitations** lists to see if they're already there.
## Related guides
---
# Sleep mode & resources
URL: https://openship.io/docs/guides/sleep-mode-resources.md
Set optional container resource limits and choose whether your app sleeps when idle or stays on.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Projects share their server's available CPU and memory by default. You can add container limits
to control how much an individual app can use, and choose whether it sleeps when idle or stays on.
These settings do not change your code or resize the server. On Openship Cloud, the subscription
sets the server's purchased capacity separately.
- A project you've already deployed (see [Your first deployment](/docs/getting-started/first-deployment) if not).
- For the CLI examples, the `openship` command installed and logged in.
- The **project ID** for the CLI/API bits. Run `openship project list` to find it.
## The two settings, in plain words
- **Resources** — optional ceilings on the **vCPU** (processing power) and **RAM** (working memory)
an app can use within its server. **Full capacity** adds no container cap; other projects share
the available capacity. Server storage and paid capacity are managed separately.
- **Sleep mode** — what happens when your app is idle:
- **Auto Sleep** (the default) — the app stops when no one is using it and wakes up on the next request.
Cheaper to run, and Openship wakes it instantly, so visitors don't wait.
- **Always On** — the app never stops. Highest availability, but it's running (and costing) around the clock.
Start with **Auto Sleep**. It's the recommended default and right for the large majority of apps. Switch to
**Always On** only if you have a specific reason — for example a background job that must keep running, or an
app that can't tolerate the brief wake-up on the very first request after a quiet spell.
## Set resources
Optional container limits live below the server selector in **Machine Power** on the deployment
settings page. Existing projects also expose Machine Power in their settings. The API uses the
same values. The Cloud subscription controls the server's capacity separately.
Connected and managed servers default to **Full capacity**: a container uses the server's available
CPU and RAM, shared with its other projects. Select a preset or **Custom** only when you need an
additional per-container limit. Choosing a limit does not change the server's plan or disk size.
Builds also have no additional CPU or memory limits unless you configure them.
Cloud admission prevents an uncapped build from overlapping another build on the same
server; configured build limits can share capacity. Builds do not provision a second VM.
### Start a deploy and choose Openship Cloud
Begin a deployment as usual. When you reach the "Where do you want to deploy?" choice, pick **Openship
Cloud**. Select your server; runtime and **Machine Power** settings appear below it, with a preview
and **Continue** on the right.
### Keep full capacity or add a limit
**Full capacity** is selected by default. Choose **Customized** beside it to reveal the
presets and custom limits. Pick a preset or save custom values before continuing; the
choices stay visible. Selecting **Full capacity** again clears the limits and hides them:
| Limit | vCPU | RAM |
|---|---|---|
| **Micro** | 0.25 | 256 MB |
| **Low** | 0.5 | 512 MB |
| **Medium** | 1 | 1 GB |
| **High** | 2 | 2 GB |
| **Extra large** | 4 | 8 GB |
**Custom** edits CPU and RAM inline. Enter `0` in a dimension to leave it uncapped; Save applies
the choice and Cancel retains the previous selection. Positive limits must fit the selected server.
### Deploy
Continue to the app configuration, then deploy. Any selected container limits apply when it starts.
Any existing project has a **Machine Power** card. On a single app it's under
**Configuration**; on a multi-service (compose) project it's on the **Services** tab, since that
project shape has no single-app Configuration.
The card shows the target machine's detected capacity in its header, and offers:
- **Full capacity** — the default on connected and managed servers. The container shares the host’s available capacity.
- **Micro / Low / Medium / High / Extra large** — the same presets Openship Cloud offers. A preset larger than the
machine is greyed out rather than silently unhonored.
- **Custom** — type your own vCPU and MB. `0` in either field means no limit for that dimension, so
you can cap memory while leaving CPU free.
Limits apply when the container is **recreated**, so redeploy for a change to take effect. The card
says so inline. Every deploy also logs the limits it applied (`Resource limits: 2 vCPU · 4 GB`, or
`no limits (machine capacity)`), so a cap is never invisible.
A service in a compose project can override the project value for itself — see
[per-service limits](#per-service-limits-compose).
Update an existing project's resources with a `PATCH` to its resources endpoint. All paths are under `/api`
on your instance (for example `https://your-host/api/...`). Authenticate with a personal access token in the
`Authorization` header — create one from **Settings → Tokens** or with `openship token create`. See
[Authentication](/docs/security/auth) for the full token model.
You can set **production** resources for your live app and **build** resources for compilation.
Sizes are given as `cpuCores`, `memoryMb`, and `diskMb`. On Openship Cloud, build CPU/RAM
are optional upper limits. Only configured values become Docker limits; omitted or zero
dimensions remain uncapped. Send `{"build": null}` to remove the additional build limits. A saved build cap does not change production resources.
```bash
curl -X PATCH https://your-host/api/projects/PROJECT_ID/resources \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"production": { "cpuCores": 1, "memoryMb": 1024, "diskMb": 16384 },
"build": { "cpuCores": 2, "memoryMb": 2048, "diskMb": 16384 }
}'
```
You can also send `{"tier": "medium"}` instead of explicit numbers, or `{"tier": "unlimited"}`
to remove the caps on either server type.
`0` means **no limit**. A non-zero `cpuCores` must be at least 0.25 and `memoryMb` at least 128; the
UPPER bound is the target machine's own capacity, not a fixed number — so a large self-hosted box is
usable in full. Managed server storage is controlled by its subscription, not the project's
`diskMb` field. Resource fields are optional; omitted dimensions have no additional container cap.
`GET /api/projects/PROJECT_ID/resources` reads the current values, and also reports the detected
machine `capacity` when available, plus `requiresLimit: false` for connected and managed hosts.
Openship Cloud also returns `buildMode`: `automatic` or `custom`. In automatic mode, the
returned build CPU/RAM values are zero and Docker receives no additional build limits.
Cloud reservation accounting stays separate from those container settings.
## Per-service limits (compose)
In a multi-service project the project-wide value applies to **each** service container — it's a
per-container cap, not a budget split across them.
A single service can override it. Openship reads a compose file's own limits, in either spelling, and
applies them over the project value **field by field** — so a service that declares only memory keeps
the project's CPU setting:
```yaml
services:
api:
image: my/api
mem_limit: 4g # short form
cpus: 2
worker:
image: my/worker
deploy: # swarm form — also honored
resources:
limits:
memory: 8G
cpus: "1.5"
```
The same override is available declaratively in `openship.json` under
[`services[].resources`](/docs/reference/openship-json#services-compose).
Importing an existing Docker container reads the caps it's actually running with — including one you
applied by hand with `docker update --memory` — so adoption doesn't quietly reset them.
## Set sleep mode
Sleep mode has two values: `auto_sleep` (the default) and `always_on`. Set it from the CLI or the API.
```bash
# Let the app sleep when idle (the default, cheapest)
openship project sleep-mode PROJECT_ID auto_sleep
# Keep it running around the clock
openship project sleep-mode PROJECT_ID always_on
```
Don't know your project ID? `openship project list` shows every project with its ID.
```bash
curl -X POST https://your-host/api/projects/PROJECT_ID/sleep-mode \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{ "sleep_mode": "always_on" }'
```
`sleep_mode` must be `auto_sleep` or `always_on`. (You can also change it alongside resources by sending a
`sleepMode` field to `PATCH /api/projects/PROJECT_ID/resources`.)
Sleep mode matters for apps with a running process (a server or API). A purely static site has nothing to put
to sleep — it's just files being served — so the setting has no visible effect there.
## Troubleshooting
A cap larger than the target machine is refused with the real numbers, e.g.
`Memory limit 8192 MB exceeds the machine's 2048 MB`. Lower the value, or use `0` / the `unlimited`
tier to remove the cap. A non-zero value below the workable floor is refused too (`at least 0.25
cores`, `at least 128 MB`). If Openship couldn't reach the machine to read its capacity, no ceiling is
enforced at all — the value you send is accepted as-is.
The mode must be exactly `auto_sleep` or `always_on` — nothing else. Check the spelling (both use an
underscore), and make sure the project ID is right. `openship project list` confirms both.
That's expected — **Always On** keeps the machine running 24/7. If you don't need constant availability,
switch back with `openship project sleep-mode PROJECT_ID auto_sleep` and the app will sleep when idle again.
## Related guides
---
# Managed Cloud servers
URL: https://openship.io/docs/guides/cloud-workspaces.md
Share one subscribed Docker host across projects, with measured usage and independent billing.
Choose a plan and deploy. Openship Cloud creates and manages a server for your
projects automatically, including Docker and routing through Oblien. You do not
need to connect SSH credentials or install an edge proxy.
## Deploy to your managed server
New Cloud accounts start with **Production**, a shared Docker server. Complete
checkout in Billing and setup starts after the provider confirms payment. The
server is selected automatically when it is your only destination. Install a
catalog app, deploy a repository or upload source files using the normal flow.
Cloud uses the same Docker engine as self-hosted deployments. Services,
environments, logs, volumes, backups and rollback artifacts belong to their
projects. Execution runs inside your managed server; edge routing uses Oblien.
Open **Servers** when you want usage, component health, listening ports, terminal access,
network settings or operation logs. This is optional administration, not a setup checklist. Cloud
shows supported capabilities, without SSH setup, edge installation or host
component maintenance.
You can add another managed server with an independent subscription. Projects
select it through the same `serverId` used for connected servers. Changing a
server name does not move its workloads; moving projects requires an explicit
migration. Provider workspace IDs remain internal provisioning and billing
identities.
Choose **Docker** for isolated services, catalog apps and Compose stacks.
Compatible source applications can choose **Direct** to run as a supervised
process on the same server. Sidecars still use Docker. Both choices share the
subscription's capacity; an additional server has its own subscription.
Self-hosted SSH servers keep their existing setup and management controls.
## Use Cloud from self-hosted Openship
Connect your Openship Cloud account in **Settings → Cloud** or **Servers → Add
server**. Your existing Cloud projects, apps and managed servers appear alongside
local resources. A server already linked to this installation appears once.
You can purchase another server from the same dashboard; its subscription and
provisioning stay in Cloud.
Cloud-owned projects keep their settings, deployment history and operations in
Cloud. Viewing them does not create local copies. For a local project, selecting
a managed server verifies your access and creates an execution link using the
same destination picker as your SSH servers. Deployments, jobs, logs, terminals
and backups use the existing application flow.
Cloud records linked local projects so a host cannot be deleted while another
installation still uses it. Connections are pinned to the Cloud account and
organization. Switching accounts refreshes the inventory; existing execution
links require their original account. Locally scoped automation credentials can
use explicitly granted links, but do not inherit the owner's Cloud inventory.
## Understand capacity and usage
The server page separates **provisioned capacity** from **live usage**. A
100 GB disk is a capacity ceiling, not a claim that your application stores
100 GB. The disk breakdown measures project containers, named volumes and
managed bind data, with a separate shared total for images, build cache and
system files. Measurements can be temporarily unavailable; the UI shows an
unknown value instead of substituting reserved capacity.
CPU and memory settings limit individual containers. They do not reserve
another machine. New offers let one service use the full purchased CPU and
memory pool, while all services still compete for the actual host resources.
The operating system and Docker also use some memory and disk. New managed-server
offers do not cap project or service counts; their workloads share the server's
resources. Saved subscription terms remain unchanged. See current offers on the [pricing page](/pricing).
Source builds run on the server using measured available CPU and memory.
An optional build size is an upper limit; automatic sizing uses current
headroom. Host activity is coordinated so simultaneous builds or a resize do
not each assume the same free resources. If too little memory is available,
stop an idle service or upgrade the server and retry. Image-only installs
do not create a source builder.
New monthly plans cover the server's CPU, RAM and storage for the full paid
period. Applications and builds share that capacity without a second compute-credit
allowance. Older metered subscriptions keep their saved terms until you explicitly
change plans. Optional managed proxy transfer and backups are separate from
monthly compute. See [Cloud billing](/docs/guides/billing).
## Upgrade and recover
1. Open Billing for the server and choose **Change plan**.
2. Review the provider's amount due now, effective date, resource changes and
affected projects, then confirm the restart.
3. Complete any payment. Pure capacity upgrades apply after payment; resource
reductions and billing-model changes wait for renewal, even if the price rises.
4. The operation waits for active work, records the running applications,
resizes the host and restores them. If the server's projects changed after
review, use **Apply plan capacity** to review the restart again.
Allow for downtime during a host resize. Intentionally stopped services stay
stopped. A failed operation retains its logs, reason and recovery checkpoint;
retry it from the server page. Disk capacity cannot be shrunk in place.
Moving to a smaller disk requires a separate data migration.
Provisioning and resize operations survive an API restart. Transient failures
have a displayed retry time; a settled failure requires an explicit retry.
A billing connectivity error alone does not cancel an active subscription.
Interrupted commands must finish or be confirmed stopped before another operation
changes the server. Retry the original operation to recover it. If the server's
Docker bridge itself crashes during a change and cannot confirm the result,
Openship keeps the server locked for that operation. The error directs you to
restart the managed server through the provider console and retry. This recovery
can interrupt all applications on the server; Openship does not restart it
automatically to clear the lock.
## Terminal and networking
Docker servers expose a host terminal through the same authenticated terminal
interface as connected servers. Oblien allows one host terminal socket per
server; a second session is refused until the existing session closes. Service
terminals use Docker and remain independent. Terminal activity has idle and
maximum-lifetime limits.
The **Networking** tab controls outbound internet access through Oblien. The
confirmation explains that disabling it affects downloads, builds and external
integrations for all projects. Published ports and domains stay in each project's
routing settings, so a server setting cannot overwrite their rules. Provider
private-link and edge configuration is managed automatically.
## Delete safely
Deleting a project in a shared server removes that project's resources and
preserves the server and its other projects. The normal project deletion
choice still controls whether persistent volumes are removed. An application
rollback reuses project artifacts; it never restores or deletes the whole host.
Removing projects does not cancel a server's subscription. Open the server's
**Manage subscription** link (also available in its deletion confirmation), then
choose **Cancel subscription → Stop renewal** in Billing. The confirmed end date
shows when the paid period finishes; no server or project data is deleted by
stopping renewal.
To delete a server, first remove or migrate its projects and wait for its
subscription to end. Deletion is blocked while a paid period or unresolved checkout
remains. Provider removal must be confirmed before Openship removes workspace
ownership. Billing records remain with the payment provider. Cancellation by
itself does not delete project data.
The [server API](/docs/api/servers) exposes the same lifecycle to the SDK and MCP.
---
# Billing (Openship Cloud)
URL: https://openship.io/docs/guides/billing.md
Monthly managed servers, resource coverage, plan changes and payment history. Self-hosted Openship stays free.
Billing applies to **Openship Cloud** resources. Your own servers remain free to
manage; a linked self-hosted installation can also buy and manage Cloud servers.
## Monthly managed servers
Each [managed Cloud server](/docs/guides/cloud-workspaces) has its own subscription.
A monthly plan covers the purchased CPU, RAM and disk for the full paid period.
There is **no second compute-credit allowance** and no compute top-up to keep a
paid monthly server running. CPU is shared capacity, not exclusive physical cores.
| Plan | Per month | vCPU | RAM | Disk |
| --- | --- | --- | --- | --- |
| Hobby | $5 | 1 | 2 GiB | 40 GiB |
| Starter | $20 | 2 | 8 GiB | 128 GiB |
| Pro | $39 | 4 | 16 GiB | 250 GiB |
| Scale | $99 | 8 | 32 GiB | 600 GiB |
The [pricing page](/pricing) and `GET /api/billing/plans` publish the current offers.
Choose **Custom** to set CPU, RAM and disk and review a monthly quote before
checkout. Custom uses the same managed-server subscription and payment flow.
A server can have at most 12 vCPU. Enterprise terms are available through sales.
An account without a plan has no included Cloud compute.
Openship owns retail prices. Oblien verifies resource availability, payment and
paid-through coverage. Renewals retain saved terms; changes to the public catalog
do not alter a purchased contract. Existing metered subscriptions are not
converted automatically and continue to show their saved allowance in Billing.
## Sharing your server
Apps and source builds share the server's CPU, RAM and disk. A project can use the
full available capacity; the operating system, builds and other projects also
need room. Container limits do not reserve another VM or disk. Image-only installs
do not create a source builder, and undeployed drafts do not use service slots.
There is no monthly build-time cap on these monthly offers.
The server page separates purchased capacity from measured CPU, memory and disk
usage, including a project disk breakdown. An unknown measurement stays unknown.
A provisioned disk size is not the amount of data stored on it. Add another
subscribed server when you need a separate resource pool.
Every server plan includes unlimited team members without a per-seat charge.
## Coverage and separate services
**Overview** shows the billing mode, coverage status and paid-through date.
**Usage** shows recorded resource usage; monthly servers show CPU time instead
of compute-credit spend. A recorded usage comparison uses the contract's saved
PAYG rates. It is not a promised cash saving or a new charge for monthly compute.
Monthly servers include managed internet transfer. Billing shows the provider's
available allowance (or **Unlimited**) and usage for the current period. This
covers Git clones, package downloads and other managed internet traffic; public
app-route traffic and backups are separate. Exhausting transfer cannot end a
confirmed paid month of CPU and RAM.
The **Prepaid PAYG** pricing preview shows Openship resource tiers separately
from credit packages. **Tier 1**, **Tier 2** and **Tier 3** describe the combined
CPU, RAM, storage and server limits for a PAYG pool. The tier tabs show the credit
purchase threshold and the pool's capacity. These numbers stay fixed while you
configure a server. Credit
purchases unlock tiers; spending credits does not lower an unlocked tier.
Selecting a tier or package in the preview does not grant it.
Customize CPU, RAM and storage to estimate one server's hourly cost at full CPU
usage. Servers share the tier's pool allowance. If a configuration exceeds the selected pool,
the preview keeps your inputs and offers a larger tier that fits when available.
The credit card shows which tier the selected package would unlock. Resource
rates and the credit conversion come from the provider's published catalog:
active CPU time, reserved RAM time, and retained provisioned storage.
CPU time is measured in **vCPU-hours**, separately from elapsed time online.
Four allocated vCPUs averaging 25% activity consume one vCPU-hour in one elapsed
hour. Two such hosts consume two vCPU-hours during that same hour. The estimator
shows the configured server's hourly resource usage at full CPU activity. Lower CPU
activity reduces CPU usage; reserved RAM and storage continue to accrue usage.
The estimate leads with dollars per hour and the equivalent credit deduction,
with a visible CPU, RAM and storage breakdown. Open **Balance estimate** for the duration range from
100% CPU activity to idle CPU, including RAM and storage at both ends. These are
usage scenarios, not a guaranteed number of days or a required monthly deposit.
PAYG estimates use the published resource rates throughout the displayed period.
Balance duration is prepaid funds divided by usage cost; monthly host prices
do not set a ceiling on the estimate. Optional proxy transfer, taxes and storage
retained after compute ends are separate.
Purchases are not available yet. Selecting PAYG does not switch an existing
monthly server, buy credits or debit a wallet.
## Managing your plan
| Tab | What it does |
| --- | --- |
| **Overview** | Current plan, resource coverage, billing period and renewal controls. |
| **Usage** | Recorded usage over the selected period. |
| **Plans** | Compare upgrades, review other plans, or customize resources. |
| **Top-ups** | Available only for eligible saved metered subscriptions. |
| **Payments** | Unfinished checkouts, plus invoices and payment methods through the selected server's Stripe portal. |
Choose the managed server to inspect its own billing. **Get server** starts a
separate subscription; it does not replace the selected server's plan. New
customers see plan selection without empty usage or payment-history tabs.
Choose **Review change** to see Oblien's amount due now, prorated adjustment,
effective date and the projects that may restart. Upgrades apply after confirmed
payment. Resource reductions and billing-mode changes wait for renewal, even
when their retail price is higher. The returned preview is authoritative.
Usage and already purchased top-ups remain attached to their existing terms.
Pending changes stay visible in the subscription card. Complete payment there,
or cancel a pending change when allowed. Cancel a pending change before stopping
or resuming renewal. Retries use the same financial operation.
After payment, the shared server worker applies the approved resources and
restarts affected projects. If the server changed since review, **Apply plan
capacity** asks for a fresh restart confirmation. An existing disk can grow but
cannot shrink in place. Choose Custom to keep the disk while reducing CPU or RAM,
or migrate to a smaller server.
First subscriptions use hosted checkout. The return page checks the specific
payment and provider fulfillment; a successful browser redirect does not grant
coverage. Pending, refunded and failed payments remain distinct.
Choosing a preset on the public Pricing page opens Cloud checkout for that plan
after sign-in. You do not need to select it again. If an offer is no longer
available, Cloud shows the current plans instead. Refreshing or retrying that
purchase reuses its server and payment attempt.
If a checkout was left open, **Pending payments** in the Billing header lets you
resume its original payment or cancel an unpaid checkout. Cloud uses the provider’s
checkout cancellation capability, with capacity-quote cancellation retained for
older provider deployments.
This remains available before a server has a paid plan. A pending cancellation
keeps the purchase tracked until confirmed; a payment that completes meanwhile
opens its verification status instead of another checkout. Confirmed cancellation
or expiry lets you choose a new plan and remove an unused, unpaid server.
If cancellation cannot be verified, refresh the payment status. If this payment
has no supported cancellation, complete it or wait for expiry before selecting
another plan; removing its local record would leave its payment link active.
## Cancellation and retained storage
Canceling renewal keeps the current paid period. You can resume renewal before
it ends. Compute stops after coverage expires unless renewal is confirmed;
a manual suspension can also stop a server during a paid period.
Cancellation does not delete data. The provider's initial tariff retains disks
for at least 30 days with no automatic deletion. Retained provisioned storage
is billed at the saved rate after compute coverage ends, until those disks are
actually deleted. The minimum retention review date does not stop those charges.
Billing shows the contract's retention terms and any amount due. Contact
[support](/support) if a storage payment needs attention.
## Credit warnings and recovery
Credit warnings apply to saved metered subscriptions, not monthly capacity
contracts. When applicable, a compact notice in the bottom corner identifies
the server and can be opened or dismissed. Top-ups increase that subscription's
metered allowance without increasing its CPU, RAM or disk limits.
A top-up cannot restart an ended or past-due subscription. Restore its payment
first. Checkout waits for provider confirmation before showing new credits.
The warning refreshes when you return to the dashboard and every minute while
visible. Notifications follow the user's preferences; email needs a verified
address and a working mail connection.
See the [billing API](/docs/api/billing) for the operations behind these screens.
---
# Cloudflare Tunnel ingress
URL: https://openship.io/docs/guides/cloudflare-tunnel.md
Publish custom domains through a server-owned Cloudflare Tunnel, with optional Cloudflare Access policies and ownership-checked cleanup.
Use this when your self-hosted server receives web traffic through `cloudflared`
instead of open inbound web ports. Openship can manage each custom hostname's
tunnel rule, proxied DNS CNAME and optional Cloudflare Access application.
This works on self-hosted installations and SSH servers controlled from Desktop.
Openship Cloud managed servers keep their existing Cloud routing. This integration
publishes project domains; it does not expose the Openship control plane or create
anonymous `trycloudflare.com` quick tunnels.
## Before connecting
- Add the deployment server to Openship and make sure its edge proxy is working.
- Use a domain in an active Cloudflare DNS zone.
- Save a Cloudflare API token in **Settings → Credentials**, or add one inline during setup.
Scope it to the required account and zones with **Zone:Read**, **DNS:Edit** and
**Cloudflare Tunnel:Edit**. Add **Access: Apps and Policies:Edit** if using Access.
- For Access, first create a reusable **Allow** or **Service Auth** policy in Cloudflare.
Openship references that policy; it never deletes the reusable policy.
- Allow the connector's outbound connections to Cloudflare. The tunnel normally
uses port `7844` over UDP or TCP. No public inbound web port is required.
Openship administrators configure the connection. Resource-scoped tokens also need
administrative access to the selected server and write access to a domain they change.
A saved DNS-only token needs its Tunnel/Access permissions updated before use here.
## Connect the server
Open **Servers → your server → Security → Cloudflare Tunnel**.
1. Choose a saved credential and its Cloudflare account.
2. Choose an existing named tunnel, or create a new one.
3. Choose **Use an existing connector** if `cloudflared` already runs on this server.
It must connect the selected tunnel to this server, because hostname rules target
the local edge at `http://127.0.0.1:80`. Advanced settings can change that edge port.
4. Alternatively, choose **Install connector on this server**. Automatic installation
supports Linux x86-64 and ARM64 with root or passwordless sudo. It prefers a
hardened systemd service and uses a pinned, nonprivileged Docker container when
systemd is unavailable or too old. The container mounts a token file, never the Docker socket.
5. Choose whether new custom domains should use this connection automatically, and
optionally select their default reusable Access policy.
6. Connect, then wait for **Configured**. Setup errors remain visible with **Retry setup**.
Only remotely managed named tunnels are supported. A tunnel managed by a local
configuration file must be converted in Cloudflare first. Openship leaves existing
rules and the final catch-all rule intact. It refuses conflicting or shadowing
rules instead of taking them over.
## Publish domains
With automatic enrollment enabled, new custom domains added from the deployment
wizard, project or service domain forms join the tunnel. The form identifies this
server default before saving. Existing domains, free Openship subdomains and
manually configured external ingress stay unchanged.
For an existing custom domain, open its **External ingress → Manage** action and
connect it to the server's tunnel. Choose an Access policy or leave protection off.
The project must have a deployment before publication finishes.
Each exact hostname is independent. Multiple domains, service hostnames and a
`www` companion get separate DNS and tunnel entries, and their existing redirect
choices still apply. Wildcard enrollment is not supported: add exact hostnames, or
disable automatic enrollment before configuring a wildcard manually.
Openship prepares Access first, applies the project's HTTP edge route, then publishes
the tunnel rule and DNS. Cloudflare terminates public HTTPS; the local edge does not
request a certificate or redirect the tunnel's HTTP origin back to HTTPS. Protected
rules also require the Access audience at `cloudflared`.
The saved domain and its connection show the same persisted setup result. **Verify**
uses this workflow too. Failed work retries with backoff after an API restart; a
ready hostname receives a slower drift check. A provider outage cannot appear as
successful publication.
## Change or remove a connection
Changing server defaults affects future domains. Existing hostnames retain their
Access policy until you change it in that domain's **Manage** dialog.
Disconnecting a hostname removes its owned DNS record, tunnel rule and Access
application. Its domain remains in the project using external ingress, so configure
another ingress path or remove the domain. Moving a project to another server
requires disconnecting the old hostname connection before connecting the new one.
Deleting a domain queues the same cleanup even if its project has been removed.
Disconnecting the server tunnel stops new enrollment and drains its hostnames before
removing the connector installed by Openship and any tunnel created by that setup.
An existing tunnel or connector you supplied is retained. Cleanup must finish before
removing its saved credential or server.
Foreign DNS records or Access applications are never adopted, even when they point
to the same destination. If an owned object was edited elsewhere, Openship stops and
shows a conflict for review instead of overwriting or deleting it. Tunnel updates
are serialized inside Openship, but Cloudflare's configuration write has no shared
lock with its dashboard: avoid editing the same tunnel there during reconciliation.
Whole-instance exports retain the ownership ledger and encrypted credentials.
Individual project transfer is blocked while its domains are bound; disconnect them
first so another instance cannot inherit incomplete cleanup ownership.
## SDK, API and CLI
Use the existing `dns` namespace in both remote and native SDK clients. Ingress
payloads carry saved credential IDs, never API tokens. For example:
```ts
const setup = await client.dns.connectIngress({
serverId: "srv_your_server",
credentialId: "cred_your_cloudflare_credential",
accountId: "your_cloudflare_account_id",
name: "Production ingress",
tunnelId: "your_remotely_managed_tunnel_id",
connector: "existing",
defaultForDomains: true,
});
await client.dns.listIngressConnections({ serverId: "srv_your_server" });
await client.dns.getDomainIngress({ domainId: "dom_your_domain" });
await client.dns.setDomainIngress({
domainId: "dom_your_domain",
connectionId: setup.id,
accessPolicyId: null,
});
```
The HTTP entry point is `/api/dns/ingress`. Consult the [DNS API reference](/docs/api/dns)
for discovery, defaults, retry, disconnection and domain operations.
The same operations are available through the CLI:
```bash
openship dns ingress list --server srv_your_server
openship dns ingress discover discovery.json
openship dns ingress connect connection.json
openship dns ingress defaults defaults.json
openship dns ingress retry igc_your_connection
openship dns ingress domain get dom_your_domain
openship dns ingress domain set domain.json
openship dns ingress disconnect igc_your_connection --yes
```
JSON files use the SDK operation inputs. `domain set` requires `--yes` when
`connectionId` is `null`. See the [CLI reference](/docs/cli) for command details.
Cloudflare documents [tunnel configuration](https://developers.cloudflare.com/cloudflare-one/networks/connectors/cloudflare-tunnel/)
and [Access policies](https://developers.cloudflare.com/cloudflare-one/access-controls/policies/).
---
# Compose & multi-service apps
URL: https://openship.io/docs/guides/compose-multi-service.md
Run an app that's really several pieces at once — web, worker, database — from a docker-compose file or added by hand, and keep every service in sync.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Some apps aren't one thing — they're a team. A website out front, a background **worker** doing slow jobs,
and a **database** holding the data. Think of a restaurant: the dining room, the kitchen, and the pantry are
three separate stations, but together they're one restaurant. Openship calls a set of services that run
together a **stack**, and it can run the whole stack for you.
Each service in the stack is its own little box (a **container**) with its own image, ports, storage, and
settings — but you manage them all from one place: the project's **Services** tab.
- A project in Openship. A stack is just a project that has more than one service.
- Your services either come from a **`docker-compose.yml`** file in your repo, or you **add them by hand** in
the dashboard. Both are covered below.
- Nothing else — no Docker knowledge required to add a service from the catalog.
## Where your services live
Open your project and choose the **Services** tab. You'll see one row per service. Each row tells you, at a
glance:
- The service **name** (e.g. `web`, `worker`, `db`).
- A **Public** or **Internal** badge — Public means it has a web address people can visit; Internal means
only the other services can reach it (a database is almost always Internal).
- A **status** dot: **Running**, **Stopped**, **Starting**, **Failed**, or **Disabled**.
Click any row to open that service's full screen. Repo updates preserve your explicit edits and apply
other changes automatically — see [how Compose changes merge](#when-the-repo-and-your-edits-disagree-drift).
## How services get into a stack
There are two ways, and you can mix them.
### 1. From a `docker-compose.yml` file
If your repo has a compose file, Openship reads it and turns **each service in the file into a service row** —
its image (or a build context and Dockerfile), ports, volumes, environment, command, restart policy,
`depends_on` links, and healthcheck. From then on those rows are what Openship deploys.
Openship tracks the compose fields it models: `image`, `build`, `dockerfile`, `ports`, `depends_on`,
`environment`, `volumes`, `command`, `restart`, and `healthcheck`. Everything else in your file — `networks`,
build args, labels, `profiles`, comments — is left untouched: Openship neither reads it nor rewrites it.
#### Compose file in a subfolder
Openship looks for the compose file at the project root. If yours lives somewhere else — say
`deploy/docker-compose/docker-compose.yml` — open **Compose file** in the deploy wizard and enter
the path, then hit **Scan**. Openship re-reads the repo and picks up the services it declares. You
can give either the file or the folder that holds it, and the filename doesn't have to be the
standard one (`stack.yml` works).
Relative `build:` contexts are resolved the way compose resolves them — against the compose file's
own folder — so a file in `deploy/docker-compose/` can use `build: ../../api` to build the `api`
directory at the repo root.
#### What `build:` means
`build:` is the docker build **context**: the directory docker builds from. `COPY` and `ADD` paths in
that service's Dockerfile are relative to it, `dockerfile:` is looked up inside it, and the
`.dockerignore` that applies is the one in that directory — exactly as `docker compose build` behaves.
Use `build: .` when the service really does build from the repo root.
Two consequences worth knowing:
- A service whose `build:` directory has no Dockerfile fails with a clear error. It does not fall back
to a Dockerfile elsewhere in the repo — that would build a different image under this service's name.
- Compose `build.args` and `build.target` are not modelled. Build arguments come from the service's
environment variables instead (each is passed as a `--build-arg`).
#### BuildKit
Modern Dockerfile syntax — `RUN --mount=type=cache`, `# syntax=` directives, heredocs — needs BuildKit.
Openship uses it automatically for a Dockerfile that requires it when it builds against a Docker socket,
and on a remote server whenever that host's Docker CLI has the `buildx` plugin. If a build fails with
`the --mount option requires BuildKit`, install the plugin on the build host (the `docker-buildx-plugin`
package, or Docker's official packages) and redeploy. The build log names which builder it used.
To keep it in the repo instead of setting it per project, declare it in
[`openship.json`](/docs/reference/openship-json):
```json
{ "composePath": "deploy/docker-compose/docker-compose.yml" }
```
The wizard field wins if you later change it there — the config file seeds the value, your edit is
what deploys.
Edits you make in the dashboard are stored by Openship and used on every deploy. Your `docker-compose.yml` is
never changed. If you want the file itself to reflect a change (so a teammate or a fresh clone sees it), edit
the file in your repo and push.
#### Database access during a Next.js build
If `next build` reports `getaddrinfo ENOTFOUND db`, followed by an error such as
`Failed to collect page data for /api/hours`, code evaluated during the build tried to resolve
the `db` hostname. Check the named route and its imported helpers for database initialization.
Use `"dependsOn": ["db"]` in `openship.json` (or `depends_on: [db]` in Compose). This orders
container startup; it does not start Postgres before image builds or attach the builder to the
services' network. Even an already-running database is not automatically reachable by its
service name from the builder.
For a route that needs data only when handling a request, move Payload initialization into the
existing `GET` or `POST` handler, or a helper called by that handler. Next.js can import route
modules during the build, so `export const dynamic = 'force-dynamic'` alone does not prevent
module-level `await getPayload(...)` or an eagerly created initialization promise from running.
Check imported helpers and configuration for the same side effects.
For example, this Next.js 15 / Payload 3 handler initializes Payload when a request arrives.
It assumes an `hours` collection; when adapting your own route, keep its existing authentication,
query options, access checks, and response shape:
```ts
import config from "@payload-config";
import { getPayload } from "payload";
export const dynamic = "force-dynamic";
export async function GET() {
const payload = await getPayload({ config });
const result = await payload.find({
collection: "hours",
overrideAccess: false,
});
return Response.json(result);
}
```
`overrideAccess: false` applies the collection's access rules; retain any existing authenticated
user context in your own queries. Keep the runtime connection string pointing at `db:5432`
when both running services share the project network.
If a page intentionally queries data during static generation, deferring an API handler will
not remove that requirement. Supply a data source reachable from the build environment, or
change that page to load its data at request time if that matches the application.
### 2. Added by hand
Any project can get extra services from a built-in catalog of common images — databases, caches, search,
queues, storage, and more — or from any Docker image you name.
### Open the Add Service dialog
On the **Services** tab, press **Add Service**.
### Pick a service
You land on a catalog. Browse a category on the left (Databases, Caches, Search, Vector & AI, Queues &
Streams, Object Storage, Auth & Identity, Mail & SMTP, Runtimes), search by name, or choose **Custom image**
to type any image tag yourself. Click the one you want.
### Fill in the details
Openship pre-fills what it can. Check these:
- **Service name** — short and unique within the stack (e.g. `db`).
- **Ports** — the port(s) the container listens on, comma-separated (e.g. `5432`).
- **Image** — the Docker image and tag (e.g. `postgres:16-alpine`).
- **Persistent volumes** — optional `name → path` pairs so data survives restarts.
- **Environment variables** — settings the service needs.
- **Routing** — leave it **Internal only** (the right choice for databases and background workers), or switch
it to **Publicly exposed** to give the service its own web address — a free subdomain or your own custom
domain.
Press **Add service**.
### It deploys automatically
If the project already has a live deployment, adding a service **redeploys** the project so the new container
actually starts — you'll see a "deploying…" message. If the project has never been deployed yet, the service
is just **saved**, and you deploy the project yourself to bring it up.
### Re-syncing after the compose file changes
You don't normally sync by hand — on every deploy Openship **re-reads the current Compose source** (the
repository for GitHub projects or `localPath` for local projects) and reconciles it against your service rows
automatically. GitHub pushes use the same path and skip the scan only when the changed-file list proves the
Compose file was untouched. From the terminal you can also force a sync from a specific file:
```bash
# Rebuild the stack's service rows from a compose file.
# Services in the stack but NOT in the file are removed — you'll be asked to confirm.
openship service sync --project my-app ./docker-compose.yml
```
`openship service sync` shells out to `docker compose config` to parse and validate the file, so Docker
Compose v2 must be installed where you run the command. If `docker` isn't found, the sync stops with a clear
message.
## Opening a service
Click a service row to open its screen. Across the top is a row of tabs:
- **Overview** — read-only facts, each shown only when it applies: **Network** (the internal address other
services use to reach this one, the container ports, the published host port, the current IP, and the
container ID — shown as a **Workspace ID** on Openship Cloud), **Configuration** (restart policy, command,
depends-on), and **Volumes**.
- **Terminal** — a live shell inside the container. It only opens while the service is **Running** ("Start the
service to open a shell." until then).
- **Logs** — the service's output, streamed as it happens.
- **Environment** — the service's environment variables. Edit them and press **Save environment**.
- **Settings** — the build and runtime fields you can change: name, image (or a build context and Dockerfile),
ports, depends-on, volumes, command, restart policy, and an optional healthcheck — plus the enable toggle,
the lifecycle buttons, and **Delete**. (Environment variables have their own **Environment** tab.)
- **Backup** — schedule and run backups. This tab shows only for compose services (the stateful containers),
not for source-built sub-apps.
## Start, stop, restart
The lifecycle buttons live on the service's **Settings** tab. Which ones appear depends on the state:
- **Running** → **Stop** and **Restart**.
- **Stopped** → **Start**.
- **Disabled** (never started) → **Enable & start**, which turns the service on and deploys it.
- **Enabled** with a live deployment → **Redeploy**, which rebuilds **only this service** and leaves the rest
of the stack running.
There's also **Disable Service** / **Enable Service** (a disabled service is skipped on deploy) and
**Delete** (tears the service down).
Open the service → **Settings** tab → press **Start**, **Stop**, or **Restart**.
```bash
openship service start --project my-app db
openship service stop --project my-app db
openship service restart --project my-app db
# See what's actually running
openship service containers --project my-app
```
Target a service by its name or its `svc_…` id.
## When the repo and your edits disagree: drift
On each deploy Openship merges the current Compose source with your saved service configuration,
comparing each field against the previously imported version:
- **base** — the compose values it last read in,
- **yours** — the service's current values (including your dashboard edits),
- **theirs** — what the repo file says right now.
| Repo changed? | You edited it? | What Openship does |
| --- | --- | --- |
| no | — | keeps your values |
| yes | no | **applies the repo's value** automatically |
| yes | yes | **keeps the edited field** and applies the other repo changes |
| new service in the repo | — | adds it automatically |
| removed from the repo | no | removes it only if it has no saved environment |
| removed from the repo | yes | keeps it until you explicitly delete it |
Routine Compose changes do not require **Accept upstream** or **Keep mine** before redeploying.
Saved project and service environment values remain in place. A key omitted from the repo is retained
as a local override, and an unresolved expression cannot replace the only saved value for that key.
Remove a saved variable explicitly from the environment editor when you no longer need it.
If an older version left a pending review, the next deploy reconciles it automatically. The legacy
resolution actions remain available: **Accept upstream** applies source configuration while preserving
saved environment values; **Keep mine** retains the current configuration.
Redeploy the project to apply current source changes. You can also resolve a review left by an older
version from its existing banner.
```bash
# Accept a legacy source review; saved environment values are preserved
openship service drift accept --project my-app web
# Keep your edits and stop flagging the change
openship service drift keep --project my-app web
```
## Ports & volumes: cloud vs self-hosted
How ports and volumes behave depends on **where** the stack runs:
- **Self-hosted / your own server (Docker):** full compose semantics. `host:container` port mappings are
published on the host, and volumes (named or bind mounts) are mounted.
- **Openship Cloud:** only the **container** port matters — it's routed to your domain through the edge
proxy, and a published *host* port is ignored. **Docker volume mounts don't apply.** A cloud service's data
lives on its workspace disk, which survives restarts but is **not** carried across a rebuild unless you turn
on backups.
Compose port publishing and Openship-managed domain routing are separate
ownership boundaries. A domain is changed only when you explicitly configure a
project/service endpoint in Openship; an unrelated Caddy, nginx, or Traefik
vhost is never inferred from `ports` and is never rewritten. For an
Openship-managed domain on the same server, redeploy keeps its tracked host port
pinned so the route cannot silently move to a different upstream.
You'll see this in the interface too. When you set the stack up in the deploy wizard, a cloud project **greys
out the published (host) port and the volume fields** and notes that only the container port is routed.
Stateful images — databases like Postgres, MySQL, MariaDB, MongoDB, Redis or Elasticsearch, and any service
that declares a volume — get an amber reminder that their data isn't kept across a rebuild unless you turn on
backups. Later, on the **Services** tab, a cloud service's **Overview** shows a **Workspace ID** in place of
the Container ID.
## CLI
Every service action has a CLI command. All of them target a stack with `-p / --project` (id, slug, or name)
and a service by name or `svc_…` id.
```bash
openship service list --project my-app # list the services
openship service get --project my-app db # show one service's config
openship service create --project my-app cache \
--image redis:7 --port 6379 # add a service by hand
openship service sync --project my-app ./docker-compose.yml
openship service start --project my-app web # start / stop / restart
openship service logs --project my-app web --follow # stream logs
openship service env set --project my-app web KEY=value # set env vars (--secret, -e )
openship service drift accept --project my-app web # resolve drift
openship service delete --project my-app cache # remove a service
```
## Troubleshooting
Adding a service saves it, but a container only starts on a deploy. If the project already had a live
deployment, Openship redeploys for you; if it didn't, open the project and deploy it (or use the service's
**Enable & start** button on its Settings tab).
The sync command uses Docker Compose v2 to read your file. Install Docker (which includes `docker compose`)
on the machine where you run the command, then try again. You can always add or edit services in the
dashboard instead.
Redeploy to reconcile it with the current source. Your explicit overrides remain in effect and other
repo changes apply automatically. A genuinely missing required variable still needs a value in the
environment editor; the deployment error identifies its service and key.
## Related guides
---
# Move your Openship instance
URL: https://openship.io/docs/guides/migrate-control-plane.md
Move control between Desktop and a server while keeping your projects, credentials and deployment ownership.
Moving an instance changes **where Openship manages your infrastructure**. Your apps and
volumes keep running on their existing servers. All workspaces, users, server connections,
projects, credentials, deployment history and backup settings travel together.
Use **Settings → Instance → Instance location**. Moving requires an instance administrator;
being the owner of an organization alone does not grant access to other organizations' data.
Openship Cloud's shared SaaS control plane cannot be moved this way.
## Desktop to a server
1. Choose **Move to a server**.
2. Select a connected server with the normal server picker. A managed Openship Cloud server
is also a destination, using its existing subscription and execution connection.
3. Choose **Use through Desktop** to install only the API, or **Desktop + browser** to install
the API and dashboard. Both need a reachable HTTPS address for webhooks and remote clients.
4. Choose a custom or free address. A custom domain must point to the destination server;
a free address uses that server's Cloud routing connection.
5. On a fresh Desktop, choose **Continue** to set your account email and password. Your selected
server, access mode and address stay in the same dialog. Account creation does not start the move.
6. Review and confirm. Openship deploys its normal API service with persistent database storage,
verifies the receiving API and version, then transfers the instance.
The interface remains on your Desktop and connects to the new API. Work continues on the
server when Desktop closes. Team invitations, jobs and webhooks use the active server.
Team settings and a disabled push-to-deploy switch offer **Move to a server** when the
instance needs a reachable address. These shortcuts open the same destination setup.
An instance that already has a public address does not need to move; if its Openship app
only needs a domain, Team settings links directly to that domain setup.
Both ends must run the **same compatible Openship release**. The destination must be able to
pull its API/dashboard images. An older image is rejected before the source is paused.
## Use an existing instance
These are different actions:
- **Connect to an existing instance** is visible beside **Move to a server** on Desktop and uses a remote instance without copying its data. Enter its
public URL or a team invitation link, then sign in with your account. A separate **Use a connection code**
option accepts a code from your own signed-in account. Your separate local instance pauses;
**Return to local instance** resumes it.
- **Move to a server → Existing instance** replaces the destination's data.
On the destination, open **More instance options → Move an instance here → Create receive code**.
Confirm replacement and create the code, then paste it into **Receive code from the destination** on the source.
Confirm the move there too. A recovery snapshot is saved before replacement.
An active server shows **Connect a Desktop**, **Move to another server**, and **Move to Desktop**
as direct buttons. Connecting and moving use different codes: a connection code signs in as
the user who generated it; move and receive codes authorize an instance transfer. Creating
a transfer code reserves the handoff but does not copy or replace data by itself.
For either an API-only installation or one with a dashboard, enter `https://ops.example.com`.
Desktop locates the API on that same host. Existing `/api/proxy` addresses still work.
Codes expire after ten minutes and must only be shared with the intended instance/device.
Connecting Desktop does not remove a server's dashboard. **Use through Desktop** installs an
API-only destination when moving to a connected server; there is currently no in-place switch
that converts an existing API + dashboard installation to API-only. An existing API-only
installation can be connected to or receive a move using the same flow above.
Email/password and two-factor sign-in work inside Desktop. For a passkey or social sign-in,
sign in on the remote dashboard and choose **Settings → Instance → Connect a Desktop**. A paired
Desktop receives that user's permissions, not an instance administrator role. API-only
and full-dashboard invitation pages offer **Open in Desktop**. Confirm the instance address
in Desktop, then sign in and review the inviter, workspace and role before accepting.
Opening a link alone changes no membership. If Desktop does not open, copy the invitation
URL into the visible **Connect to an existing instance** button. A connection code is optional.
**Connect a Desktop** is available on hosted or connected instances. The code is for your
own device; invite another person through **Team** so they use their own account and permissions.
In **Settings → Team**, choose the recipient's email, role and resource access, then **Email**
or **Copy link**. Email uses the instance's configured mail service. Copy link also works
without a mail service, and always points to the remote instance when used from Desktop.
The recipient signs in or creates an invited account, accepts the invitation and enters that
organization. Other memberships on that instance remain available in the organization switcher. Links retain
their expiry, recipient binding and revocation controls in **Pending invitations**.
## Move back to Desktop
On a connected Desktop, choose **Move back to Desktop**. Openship transfers the **latest remote
data**, including work created since you moved. It does not reactivate an old local snapshot.
The source server retires before Desktop starts managing jobs and deployments.
If that instance manages apps on its own host, select its saved SSH connection in the
return dialog. The source verifies that it reaches the same host before any data moves.
You can also choose the visible **Move to Desktop** button on the server, confirm and choose **Create move code**,
then paste it into Desktop's **More instance options → Move an instance here → Paste move code** screen and confirm the move.
Desktop initiates the connection, so it does not need an
inbound public port.
This also works for an instance that started on a server and has never been connected to
Desktop, with or without a dashboard. The receiving Desktop's prior data is replaced only
after saving its recovery snapshot.
After returning, jobs depend on this computer being online. Update externally registered
webhook/callback addresses if the public address changes; a loopback Desktop cannot receive
public webhooks. The former API service and its storage remain until you remove them.
Choose **More instance options → Move to previous server** to send your latest data back there using the same
handoff. It reuses the API installation; it does not create another server or subscription.
## Local connections and credentials
Before moving, Openship checks for connections that cannot work from the destination:
- A source-local or loopback host needs a saved SSH connection to that **same host**. Openship
verifies its host identity and preserves server ids, container ids, routes and volumes.
- SSH-agent credentials need a saved private key or password. File-backed private keys are
carried using the existing credential export process.
- Local source folders need a Git repository. Local-folder backup destinations need a
reachable SFTP destination. Existing deployments with no server binding must be assigned
to a connected server first.
Credentials are encrypted in transit and resealed with the destination's encryption key.
SMTP, GitHub and Google integration configuration travels with the instance. Database URLs,
host paths, instance encryption keys and Cloud reseller authority do not replace the receiver's
own configuration. Browser sessions are invalidated; Desktop gets a new device session.
Passkeys remain tied to their original hostname, and external OAuth applications may need
updated callback URLs when that hostname changes.
## Interrupted moves
Openship pauses new control-plane changes and waits for running operations before taking the
snapshot. Your already-running app containers are not stopped. Requests arriving during the
handoff receive a retryable response; externally delivered webhooks may need redelivery.
Use **Resume move** after a network interruption or API restart. The saved journal prevents a
retry from importing over a newly active instance. Once the source has retired, it stays
inactive even if the activation reply was lost; there is no automatic fallback to stale data.
Before activation, **Cancel move** restores the receiver's saved recovery archive. Cancellation
needs the source's confirmation, so an unreachable peer may need to come back online first.
Recovery snapshots and the handoff capability are retained for thirty days. Resolve an
interrupted move within that window; older recovery requires operator assistance.
## Updating a hosted API
The active API project is protected from stopping or deleting itself. For an instance
installed by this flow, move control to Desktop, update the former API project's service
images through the normal deployment flow, and then choose **Move to previous server**.
CLI-installed instances continue to use `openship update` on their host.
## Backup and recovery files
**Settings → Instance → Backup & recovery** retains export/import for offline recovery and
selective project transfer. Current JSON exports include credentials in plaintext: protect the
file. Older encrypted archives still require their original password. A file import does not
retire another controller, so it is not a substitute for the live handoff above.
The CLI uses the same archive endpoints:
```bash
openship system data-transfer export --out openship-export.osx
openship system data-transfer import --file openship-export.osx --mode merge --yes
```
The export is written with private file permissions. `merge` retains destination records on
conflict; `wipe` replaces the destination's data and requires signing in as the imported owner.
Use these options for reviewed recovery or selective transfer. The earlier
`openship system migration start` command remains disabled; it does not run the handoff above.
See [Settings](/docs/dashboard/settings) for archive options and
[server-to-server migration](/docs/guides/server-to-server-migration) to move an application's
runtime and volumes instead of its control plane.
---
# Git authentication for private repos
URL: https://openship.io/docs/guides/git-authentication.md
How Openship authenticates the git clone when it builds your app — forwarding your local git identity, the server's own git, per-server tokens and SSH keys, and public repos.
import { Step, Steps } from 'fumadocs-ui/components/steps';
When Openship builds your app it has to **clone your repository first**. For a public repo that's free — no credentials needed. For a **private** repo, something has to prove it's allowed to read the code. This page explains every way that can happen, in the order Openship tries them, and how to turn each one on.
On Openship Cloud, connecting the GitHub App is all you need. On the desktop app, your local `gh` login is used automatically. This page is for the cases where a build says it **can't authenticate the clone** — almost always a private repo deploying to your own server.
## First, where does the clone run?
The single most important thing to understand: **a credential that works on your laptop doesn't automatically work on a remote build server.** Openship can clone in two places:
- **On this host** (your desktop app, or the Openship control plane) — then it transfers the built output to wherever the app runs.
- **On the build server itself** — the server clones directly, no upload. Best for big repos, and required for bare/Direct deploys.
A token that lives on your machine has to be *shipped* to the server to clone there — and Openship is deliberately careful about which credentials it will ship. That's why the answer to "how do I auth a private clone" depends on where the clone runs.
## The credential chain (server builds)
For a build that runs off this host, Openship tries these in order and uses the **first** one that works. Each is independent — a step is skipped when it doesn't apply, so the order only decides who wins when several are available.
| # | Credential | What it is | Ships a secret to the server? |
|---|---|---|---|
| 1 | **Forwarded git identity** | Your local `gh` login, tunneled to the server over SSH for the clone only | No — vended on demand, never written to disk |
| 2 | **The server's own git** | `gh`/credential-helper/SSH key already on the box | No — resolved locally on the server |
| 3 | **Per-server token or SSH key** | A GitHub token or deploy key you saved for that server | Yes — only to that one server |
| 4 | **Clone token / GitHub App** | A per-project or global clone token, or the App installation token | Yes — short-lived, repo-scoped |
| 5 | **Public repo** | No credential at all | Nothing to ship |
| 6 | **Clone on Openship + transfer** | Clone here, upload the source | No — the code never transits the server as a token |
If none of these produce a credential for a private repo, the build stops with an actionable message instead of hanging.
It's ranked by how little secret material moves. Forwarding (1) and the server's own git (2) ship **nothing** — so they win first. A stored token or key (3–4) does travel to the server, so it's used only when nothing ambient works. Cloning here and transferring the source (6) is the last resort that keeps every credential on this host.
## How to turn each one on
### Forward your git identity (recommended on desktop)
Turn on **Settings → Clone credentials → "Forward my git identity to build servers."** When a build runs on a remote server, Openship forwards your local `gh` login over the SSH tunnel just for that clone. Nothing is written to the server, and it's gone the moment the clone finishes.
This is a **single per-operator switch**, not a per-deploy checkbox — set it once and every server clone uses it. It applies to the desktop app (which has your local `gh` and an SSH tunnel to the server); it's inert where there's no local git identity to forward.
### Use the server's own git
If the build server is already logged in to GitHub, Openship uses that — no configuration in Openship at all. On the server, any one of:
```bash
gh auth login # GitHub CLI on the box
# — or a credential helper —
git config --global credential.helper store
# — or an SSH key on the account —
ls ~/.ssh/id_ed25519
```
Openship verifies the server can actually reach *your* repo before relying on this, so a box logged in as the wrong account is skipped rather than failing mid-build.
### Save a token or SSH key on the server
On the **Servers** page, open a server's **GitHub authentication** and add a device-flow token, a personal access token, or an SSH deploy key. That credential is used for clones that run on **that** server. Use this when the server has no ambient git and you don't want to forward from your machine — for example a headless CI box.
### Set a clone token (global or per-project)
**Settings → Tokens → GitHub clone credentials** stores a personal access token (classic `ghp_…` or fine-grained `github_pat_…`) used to clone private repos when the GitHub App isn't installed. Toggle **Use as default clone token** to put it in the chain. A **per-project** override (project → clone token) takes precedence over the global one for that project.
Give a classic token the `repo` scope, or a fine-grained token read access to the repos you deploy.
### Public repos need nothing
A public GitHub repo clones anonymously — no token, no forwarding, exactly like a public deploy on any platform. Openship confirms this by attempting the clone from the machine that will build, so a rate-limited API check never mislabels a public repo as private.
## Local vs server builds
- **Local build** (build on this machine, transfer the output): your local `gh` token is used directly and never leaves the machine.
- **Server build** (build on the target): a broad local token is **never** put into a clone URL and shipped off-host. That's exactly why forwarding (1) exists — it vends the identity over the SSH tunnel on demand instead of writing it to the server — and why a plain `gh` token isn't accepted as a shippable remote credential.
Cloud builds run inside the Cloud workspace and authenticate with the **GitHub App** installation token. Connect the App from **Settings → GitHub** and you're done — the forwarding/server-token steps above are for self-hosted server deploys.
## Related guides
---
# The edge
URL: https://openship.io/docs/guides/the-edge.md
Openship's built-in reverse proxy — how your apps get a public address and HTTPS, how you protect a route, where your traffic numbers come from, and how to take over a proxy that's already running on a server.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Every request from the internet has to land *somewhere* first, before Openship knows which of your apps it's
for. That somewhere is the **edge** — a reverse proxy that sits on ports `80` and `443` and acts as the front
door for the whole box. It answers the connection, sorts out HTTPS, works out which app the hostname belongs
to, forwards the request to that app's container, and counts it on the way past.
Most of the time you never think about it: `openship up` sets the edge up for you, and every deploy that has a
domain wires that domain into it automatically. You start caring about the edge directly in a few specific
moments — when you're moving an existing server across, when you want to route a bare hostname at a port, when
you need to rate-limit or block something, or when you're asking "where is my traffic actually coming from?"
Two different things run on a box, and it's worth keeping them straight. The **server** is Openship itself —
the API and dashboard, the control room. The **edge** is the public reverse proxy in front of your apps — the
front door. `openship up` installs both together; a visitor's request only ever touches the edge, never the
server.
## What the edge actually does
Four jobs, all on the request path:
- **HTTPS for free.** It terminates TLS and gets a Let's Encrypt certificate for each domain, so your apps are
served over `https://` without you managing certs.
- **Routing.** It maps each hostname to the right container — that's how ten apps share one server and one IP,
each on its own domain.
- **Protection.** Per-route rules — rate limits, IP/country bans, CIDR allow-lists — are enforced here, before a
request ever reaches your app.
- **Traffic counting.** Because it already sees every request, it tallies them (requests, bandwidth, countries,
top paths) at essentially no cost, and that's what fills the analytics you'll see later.
- A Linux server — the edge is a Linux reverse proxy. On macOS/Windows you can still *read* an edge's domains and
traffic from the CLI, but installing and taking over the proxy happens on the Linux box.
- Openship installed on that box (`openship up`). The edge comes with it.
- For anything that reads data on a CLI-installed instance, a login: run `openship login` once with a token
from the dashboard.
## Self-hosted vs Cloud
A self-hosted deployment uses an edge on your own server. Openship Cloud uses
a managed edge. Review these differences when moving a project between them.
| Feature | Self-hosted edge | Openship Cloud |
| --- | --- | --- |
| Proxy settings (`routingConfig.proxy`) | Supported, subject to validation and the proxy's capabilities. | New or changed nonempty proxy settings are rejected with `CLOUD_PROXY_SETTINGS_UNSUPPORTED`. Unchanged legacy settings may be carried forward; this does not make them supported. |
| Domain redirects | Applied through the server's edge configuration. | Applied through the managed Cloud edge. |
| Route rules: rate limits, IP/country access rules, and hotlink protection | Enforced by the OpenResty route-rule guard after the rules are successfully pushed. | The self-hosted route-rule push path skips Cloud projects. Saving a rule does not establish that equivalent protection is active on Cloud. |
| Live edge configuration inspection | Can compare saved proxy settings with the configuration served by a reachable server. | Self-hosted OpenResty inspection is unavailable; the report returns `reachable: false`. |
| Operator-defined trusted proxies and client-IP headers | Configured on the self-hosted edge, with the limitations below. | The self-hosted environment variables below do not configure the managed Cloud edge. |
### Real client IP and trusted proxies
IP-based rules need the visitor's real address. If another proxy sits in front
of a self-hosted edge, configure which proxy addresses it trusts:
- `OPENSHIP_EDGE_TRUSTED_PROXIES` adds trusted proxy addresses or CIDR ranges.
Only include proxies you control or trust to supply the client address.
- On bare or remote OpenResty installations,
`OPENSHIP_EDGE_REAL_IP_HEADER` selects the client-IP header when configuration
is generated. The default is `CF-Connecting-IP`.
- On containerized edges, the generated configuration adds trusted proxy
addresses but retains the header baked into the image. Setting
`OPENSHIP_EDGE_REAL_IP_HEADER` does not override that header.
Reapply routing after changing these settings. A reload alone does not
regenerate configuration.
### Moving a project between deployment types
Review proxy settings, route rules, and client-IP handling on the destination.
Verify that the intended protections are active after deployment; saved
configuration alone is not proof of enforcement.
Domain redirects are supported on both deployment types. Redirect targets
must belong to the same project, and redirect cycles are rejected. See
[Redirect one domain to another](/docs/guides/custom-domains#redirect-one-domain-to-another).
## Taking over a server that's already serving
This is the headline case. You have a server that's *already* running nginx, Apache, or Caddy on `:80/:443`
with real sites on it, and you want Openship to run the front door instead — without a flag day where nothing
is served.
The edge does this as a **migration**: it reads the existing proxy's sites, registers each one on the edge so
it keeps serving, and only then takes the ports. The whole thing is journaled and rolls back cleanly if a step
fails, so you never end up with neither proxy up.
### See what's there
On the server, ask the edge what it would import:
```bash
openship edge sites
```
It lists the reverse-proxy sites it found on the host — the hostnames and where each currently points.
### Take over and bring the sites across
```bash
openship edge migrate
```
That imports every site it just listed, then frees `:80/:443` and starts serving them from the edge. If you'd
rather *not* keep the old sites — you just want the ports — use `openship edge takeover` instead, which stops
the old proxy without importing anything.
When a foreign proxy is holding `:80/:443`, Openship raises the same "there's another proxy here — take over
and migrate its sites?" prompt **automatically** during `openship up` and in the bare `openship` control panel.
The commands above are the manual version of that same offer, for when you want to run it on demand.
## Putting a domain on the edge
Once the edge is running, giving an app a public hostname is one command. You can point a domain at an existing
project, or bind a fresh one straight to a local port:
```bash
# Point a host at a port on this box (creates a tracked project for it)
openship edge domains add app.example.com --port 8080
# Attach a host to an existing project (uses that project's port)
openship edge domains add www.example.com --project prj_123 --primary
```
Registering a domain also verifies its DNS and issues the HTTPS certificate for you. If DNS isn't pointing at
the box yet, the command prints the records to add and you re-run verification once they've propagated. The full
domain workflow — DNS records, verification, primary vs. redirect — lives in the
[Custom domains](/docs/guides/custom-domains) guide; `openship edge domains` is the edge-scoped view of it.
## Protecting a route
Rules are applied by the edge itself, so an abusive request is turned away before it costs your app anything.
Scope a rule to a whole project, one domain, or a path prefix, and combine as many conditions as you like into
one rule:
```bash
# 20 requests/second per client IP on the login path, allowing short bursts
openship edge rules add -p prj_123 --path /login --rate-limit 20 --burst 40
# Block two countries and a bad IP, answering with 403
openship edge rules add -p prj_123 --ban-country RU,CN --ban-ip 203.0.113.7 --block-status 403
# Only let an office network in; deny everyone else
openship edge rules add -p prj_123 --allow-cidr 198.51.100.0/24
openship edge rules list -p prj_123
```
Rate limits and country rules need the visitor's real address. If another proxy sits in front of the
self-hosted edge, it must pass the client IP through, and the edge must trust that proxy. See
[Real client IP and trusted proxies](#real-client-ip-and-trusted-proxies) for the edge configuration
and the differences between bare and containerized installations.
## Watching your traffic
This is the part that makes the edge something you *watch*, not just plumbing. Because it counts every request
as it passes, you get a traffic picture with no code and no cost to your visitors. There are two ways to see it.
**In the dashboard**, open the project's **Overview** tab for the rollup — Server Requests, Unique IPs, Avg
Response, Bandwidth Out, a traffic chart, and Top Paths — and the **Logs → Server** sub-tab for the individual
request lines. That's covered in [Logs & monitoring](/docs/guides/logs-monitoring).
**From the terminal**, the same numbers are three commands:
```bash
# Requests, bandwidth, and hourly periods
openship edge traffic -p prj_123
# Visitors, countries, and top paths for one domain
openship edge analytics -p prj_123 --domain app.example.com
# The recent raw request log — and follow it live
openship edge logs -p prj_123 --follow
```
**The edge counts; the control plane collects.** The proxy bumps counters in shared memory as each response
goes out — no database, no extra network hop, nothing a visitor waits on. A background job moves those totals
into the database every 30 minutes, and the commands and tabs above read them back. So a fresh app shows
nothing until it's had some traffic, and the newest few minutes may not be in the rollup yet.
## Prefer the full command reference?
Everything here is a task-level walkthrough. For the complete list of `openship edge` subcommands and every flag
— the interactive panel, `up`/`repair`, all the domain, rule, and analytics options — see the
[Edge & monitoring](/docs/cli/edge) CLI reference.
## Related guides
---
# Rollback & redeploy
URL: https://openship.io/docs/guides/rollback-redeploy.md
Undo a bad deploy in seconds, re-run one from scratch, and keep an old version safe forever — from the dashboard or the terminal.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Every project keeps a history of its deploys — like the version history in a document. If a new deploy
turns out broken, you don't have to panic or dig through code: you can flip the project back to a version
that worked. And when you just want to run the same thing again — after a fix, or to pick up the latest
commit — you redeploy. This guide covers both, plus how to "pin" a good version so it's always there to
fall back to.
- A project in Openship that has been deployed at least once.
- Nothing else — rollback and redeploy both work on deploys you already have.
## Find the deploy history
Open your project and click the **Deployments** tab. You'll see two things:
- At the top, a **Deploy Latest Changes** card with a **Redeploy Project** button — that's for shipping again.
- Below it, the **history**: every deploy this project has had, newest first, each on its own row.
Use the page controls below the rows to browse older deployments. Search and status filters apply to the
whole history, including deployments on other pages.
Each row shows the version (like `v3`), a status, the commit message, and small labels that tell you the
state of that version:
- **Active** — the version currently live and serving your site.
- **Snapshotted** — Openship still has this version's finished build saved, so rolling back to it skips the build entirely.
- **Pinned** — this version is kept safe forever and will never be cleaned up (more on this below).
## Roll back to a version that worked
### Open the version you want to return to
In the history, find the last row that was healthy. If it shows the **Snapshotted** label, Openship still has
its build saved and the rollback will be near-instant; if it doesn't, you can still roll back — Openship
rebuilds that version's commit for you. Either way it's the same menu item.
Click the **⋮** (three-dots) menu on that row.
### Choose "Rollback to this version"
Press **Rollback to this version**. Openship tells you which of the two routes it's about to take —
> Instant restore — reuses this version's retained image, no rebuild.
— or, if that build has since been cleaned up:
> Rebuild — this version's image is no longer on the host, so its commit is built again.
and reminds you what rollback does either way:
> This restores the application code only. Database and volume data are unchanged.
Confirm, and Openship brings that version back as a new entry in your history. Rolling back doesn't erase
anything: the version you rolled away from stays in the list, so you can roll forward again the same way.
When that version's build is still on the server, rolling back doesn't rebuild anything — Openship ships the
saved build again. Three things follow:
- **It's fast, with no long outage.** No waiting for a fresh build; your site is back in seconds instead of
the minutes a build takes.
- **It restores that version's settings too**, not today's. The environment variables, port, volumes and
resource limits that version ran with come back with it.
- **Only your code changes.** Your database and any saved files (volumes) are left exactly as they are.
Rollback rewinds the app, not your data.
If the build has been cleaned up, Openship rebuilds that version's commit instead. Slower — a real build runs
— but it lands you in the same place, so rollback is never a dead end.
Older Openship versions could replace credentials in saved Compose configuration with `***`.
Openship refuses to replay an affected snapshot before starting a deployment; your active release
stays in place. Today's service settings are not a reliable copy of that older release and are
never substituted silently. Choose an intact release, or redeploy the original source with the
required credentials to create a new restore point. New deployment snapshots preserve encrypted
configuration exactly while build logs continue to redact credentials.
Only two things disable it: the version is already **Active** (you're on it), or it never finished healthy.
A cleaned-up build no longer disables rollback — Openship rebuilds the commit instead.
If a version has neither a saved build nor a commit to rebuild from (a one-off manual deploy, say), the menu
says so. To make sure a version always stays instantly restorable, **pin** it — see below.
- **Several services?** Only the services whose build is missing get rebuilt. A service the deploy never
touched keeps running on the image it already has — so rolling back your app code doesn't restart your
database.
- **Static site?** The saved files for that version are what get restored; there's no image involved.
## Redeploy (run it again)
Redeploying builds and ships your project again. Reach for it after you push a fix, or when you want the
live site to pick up the newest commit.
On the **Deployments** tab, press **Redeploy Project**. Openship pulls the latest commit on your deploy
branch, reuses your project's current settings and environment variables, and creates a new version. There's
no setup screen — it just goes, and drops you on the build screen to watch.
The small caret (⌄) next to the button opens a couple of extra choices:
- **Refresh env** — redeploy so the app picks up environment-variable changes you just made.
- **Rebuild all** — rebuild every service instead of only the ones whose files changed. This choice appears
only for multi-service projects (a single-app project always rebuilds the whole app anyway).
To go back to a past deploy, use **Rollback to this version** on its row — Openship reuses its saved build
when it can and rebuilds its commit when it can't, so you don't have to know which.
To *force* a from-source rebuild of a specific commit even when its build is still saved, use the terminal:
`openship deployment redeploy --use-existing-commit` (below).
## How many versions stay instantly restorable
Open **Project → Advanced → Rollback history** to set the maximum number of past deployments whose
artifacts are kept. The default is **5**, inherited from the instance's default unless you set a project
override. Disk measurements are informational; they do not change this limit. The same setting is available
in the deployment wizard.
The active deployment and pinned deployments are kept in addition to this window. A multi-service deployment
counts once, even if it needs several images. Set the limit to **0** to keep only active and pinned releases.
Cleanup runs after deployments finish, when you save a limit, and when you unpin a deployment. The scheduled
**Deployment artifact cleanup** job retries failed cleanup and reconciles existing history; you can also run
it manually from Jobs. Cleanup waits for any running deployment worker to finish.
Older rows remain in the history but lose their **Snapshotted** label after their artifacts are reclaimed.
An image or file tree still needed by an active, pinned, or retained deployment stays on the host until its
last retained reference expires. Operator-managed and third-party registry images are not removed.
Rollback checks what is actually available. Expired source builds can be rebuilt from their recorded commit;
image releases can be pulled again from their recorded reference. Bare hosts without a restartable supervisor
unit rebuild from source. A release without either a usable artifact or a reproducible source cannot be restored.
## Pin a version so it's always there
If there's a known-good version you always want to snap back to instantly, **pin** it — pinned versions are
exempt from that cleanup and don't count against the window.
In a deploy row's **⋮** menu, choose **Pin**. That version becomes exempt from cleanup and stays instantly
rollback-restorable for as long as you keep it pinned. To lift it later, open the menu again and choose
**Unpin**.
You can pin up to **10** deploys per project. Pin your last reliable release before trying something risky —
that way rollback is always one click away, no rebuild required.
## CLI
Every action above works from the CLI. First list the deploys to get their IDs:
```bash
# List this project's deploys (newest first). The "active" column marks the live one.
# Run it inside your linked project folder, or target another with --project .
openship deployment list
# Look at one in detail (status, commit, url, whether it's pinned)
openship deployment get
```
Then act on one by its ID:
```bash
# Roll back to a previous deploy (pass the ID of the one you want to return TO)
openship deployment rollback
# Redeploy from an existing deploy — picks up the latest commit on its branch
openship deployment redeploy
# ...or rebuild that deploy's exact commit instead of the latest
openship deployment redeploy --use-existing-commit
# Pin a deploy so it's never cleaned up (add --off to unpin)
openship deployment pin
openship deployment pin --off
```
To simply ship the latest commit of the whole project (the terminal equivalent of **Redeploy Project**), run
`openship deploy` from the project folder. Use `openship deployment redeploy` when you want to re-run one
*specific* deploy from the history.
## Troubleshooting
You're trying to roll back to the version that's already live. Pick a *different* row from the history — the
one currently serving is marked **Active** and can't be rolled back to itself.
You can only return to a version that finished healthy. A deploy that failed or was cancelled isn't a valid
restore target — choose the last row that shows a ready/deployed status.
Remember rollback changes **code only** — it never touches your database or saved files. If the problem was a
bad data change or a migration, rolling back the code won't undo it. You'll need to restore your data from a
backup or fix it directly.
## Related guides
---
# Guides
URL: https://openship.io/docs/guides.md
Choose a task, follow the steps, and use the matching CLI or SDK reference when you need more detail.
New to Openship? Complete the [quickstart](/docs/getting-started/quickstart) first.
## Deploy
| Task | Guide |
| --- | --- |
| Deploy a repository | [GitHub](/docs/guides/deploy-from-github) or [Git URL and templates](/docs/guides/deploy-template-or-url) |
| Deploy files from your machine | [Local folders](/docs/guides/deploy-local-folder) |
| Deploy code generated by an application | [Generated code and source files](/docs/api/sources) |
| Run an app and its supporting services | [Compose and multiple services](/docs/guides/compose-multi-service) |
| Deploy branches separately | [Preview environments](/docs/guides/preview-environments) |
| Deploy on push | [Automatic deployments](/docs/guides/auto-deploy) |
| Return to an earlier release | [Rollback and redeploy](/docs/guides/rollback-redeploy) |
## Configure
| Task | Guide |
| --- | --- |
| Declare configuration in your repository | [openship.json](/docs/guides/openship-json) |
| Set environment variables and secrets | [Environment variables](/docs/guides/environment-variables) |
| Add a hostname and HTTPS | [Custom domains](/docs/guides/custom-domains) |
| Keep data across deployments | [Persistent and object storage](/docs/guides/persistent-storage) |
| Set CPU, memory, and sleep behavior | [Resources and sleep](/docs/guides/sleep-mode-resources) |
| Clone private repositories | [Git authentication](/docs/guides/git-authentication) |
| Register a GitHub App | [Self-hosted GitHub Apps](/docs/guides/self-hosted-github-app) |
## Operate
| Task | Guide |
| --- | --- |
| Inspect traffic, logs, and health | [Logs and monitoring](/docs/guides/logs-monitoring) |
| Schedule commands | [Jobs](/docs/guides/jobs) |
| Protect and restore data | [Backups and restores](/docs/guides/backups-restore) |
| Connect an SSH server | [Custom servers](/docs/guides/custom-servers) |
| Manage the reverse proxy | [The edge](/docs/guides/the-edge) |
| Update Openship | [Updates](/docs/guides/updating) |
| Manage access | [Teams and members](/docs/guides/teams-members) |
| Run mail and webmail | [Email](/docs/guides/email-webmail) |
| Manage Cloud charges | [Billing](/docs/guides/billing) |
## Move
| Task | Guide |
| --- | --- |
| Import from another platform | [Coolify, Dokploy, and Dokku](/docs/guides/migrate-from-coolify-dokploy-dokku) |
| Move between servers | [Server-to-server migration](/docs/guides/server-to-server-migration) |
| Move Openship's own data | [Control-plane migration](/docs/guides/migrate-control-plane) |
| Connect or move to Cloud | [Cloud connection and migration](/docs/guides/cloud-connect-migration) |
| Run application schema changes | [Database migrations](/docs/guides/database-migrations) |
## Extend
Build a [catalog app](/docs/guides/add-an-app), integrate the [SDK](/docs/api/sdk), call the
[HTTP API](/docs/api), or connect an [MCP client](/docs/mcp).
---
# Server-to-server migration
URL: https://openship.io/docs/guides/server-to-server-migration.md
Import Docker applications into Openship Cloud or move them between connected and managed servers, with data transfer, progress and explicit cutover.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Openship migrates Docker applications, their images and their data through one workflow. You can import
an external server into **Openship Cloud**, move an existing project between managed servers, or move
between your own connected servers and managed servers from a self-hosted installation.
[Platform imports](/docs/guides/migrate-from-coolify-dokploy-dokku) and project moves use the same
transfer, deployment, verification and recovery steps. Managed destinations use the existing Docker
runtime; their connection and public routing are supplied by Openship Cloud.
## Before you start
- The source must run **Docker**. This flow does not move bare applications or Kubernetes workloads.
- You need write access to both servers and, for an existing project, the project itself.
- An external Cloud source needs a public SSH address and a password or uploaded private key. Openship
verifies SSH, pins the host key and encrypts the saved credentials. Private network addresses, SSH
agents, local key paths and jump hosts are unavailable for Cloud migration sources.
- The managed destination needs an active subscription and enough free disk for the images and data.
Openship checks and prepares it before stopping the source workloads.
- Plan a maintenance window and take an application backup. Source containers stop while data is copied
and the target is deployed. Downtime depends on data size, transfer speed and application startup.
Review the destination's DNS instructions. If your custom domain's DNS target changes, lower its TTL
in advance and allow existing caches to expire. A low TTL reduces the DNS delay; it does not eliminate
the data-transfer downtime or guarantee when every resolver updates. Managed domains use Cloud routing.
## Import into Openship Cloud
### Connect the source
Open **New project → Import existing project** and connect the external server. This is a
**migration-only connection**: it appears in the import picker, not in deployment destinations,
terminals or general server management. You can reuse it for another import and disconnect it afterward.
Disconnecting removes Openship's saved connection; it does not delete your external server or its data.
### Scan and review the application
Scan the source and select its Docker services. Review the discovered environment, images, volumes,
bind mounts and routes. Environment values are masked in the scan response. Source-side reverse proxies
are excluded from the application selection.
### Choose a managed destination
Use the same server picker as a normal deployment. Choose an existing managed server or create another
server with its own subscription. Cloud imports always land on a managed server; connecting a migration
source does not make external hosting a Cloud deployment option.
Review the storage preview and any conflicts. Existing target data is never overwritten silently.
Managed imports place data in storage owned by the imported project, including anonymous volumes and
file bind mounts.
### Transfer and deploy
Openship prepares the destination, records the source's running state, stops the selected workloads,
transfers their data and starts the normal deployment flow. Locally built Docker images can move too;
the image is saved on the source and loaded on the destination without a registry push or rebuild.
For external SSH → managed Cloud, the managed server can **pull directly from the source over SSH**.
Temporary SSH trust is scoped to the run and removed afterward. If no direct connection is available,
the workflow asks for an explicit relay choice; it does not silently proxy the transfer through your
control plane. Between endpoints without reachable SSH, the selected relay streams through the control
plane's existing adapters.
### Verify and finish
Inspect the target application, data, health and domain routing before confirming cutover. Removing
the original containers leaves their volumes on the source server. For an external cross-server
import, **Keep originals** restarts only the previously running source containers; their data is now
an independent copy. Same-server imports and moves of an existing Openship project leave the
originals stopped. Keep the old server until you have verified the application and its backups.
A failed or cancelled transfer before cutover restores the original placement and running state.
Recovery also handles interrupted workers. A **partial** run lists data that still needs attention:
review, retry or explicitly skip each item before cutover. Do not start both copies of a stateful
application against independently writable data.
## Move a project you already manage
Open the project's migration action and select another server. The same steps move the project while
preserving its identity. On self-hosted installations, connected SSH servers and linked managed servers
can be sources or destinations. Cloud destinations remain managed servers. Same-server imports can
attach existing containers instead of recreating them; cross-server moves must transfer their state.
## Transfer and cleanup
- Named and anonymous volumes, application bind mounts and reviewed extra paths use one storage plan.
System paths and sockets are excluded.
- Direct transfers use SSH and rsync, with retry support. Explicit relay uses the shared streaming
transfer adapters. A missing path becomes an actionable pending item.
- Rollback removes only target data created by that run and restores the source's recorded state.
If target cleanup needs a retry, it remains visible in the run.
- A source connection cannot be removed while migration or connection recovery still needs it.
- Reloading the page reopens the saved run; it does not start another migration.
## Next steps
---
# Preview environments
URL: https://openship.io/docs/guides/preview-environments.md
Make a separate, safe copy of your project from a git branch — so you can try changes before they reach your real site.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Say you have a project that's already live, and you want to try something risky — a new design, a big rewrite —
without breaking the version real people are using. An **environment** lets you do exactly that. Think of it
like a rehearsal stage set up right next to the main one: same script, same props, but the audience only ever
watches the main stage. You practice on the side, and only move things across when you're happy.
In Openship, each environment is its own copy of the project. It follows its own git branch and gets its own
web address, so your `production` site and a `preview` copy never step on each other.
- A project that's already set up in Openship (see [Deploy from GitHub](/docs/guides/deploy-from-github) if you don't have one yet).
- The project connected to **GitHub**, with more than one branch — an environment is built from a branch.
- A branch to point it at (for example a `staging` or `preview` branch).
## What "production" and "preview" mean
Two words show up a lot here. In plain terms:
- **Production** — the real thing. This is the copy your visitors see. It follows your main branch (usually
`main` or `master`).
- **Preview** — a practice copy. It follows some other branch, lives at its own separate web address, and can
have its own environment variables (its own secrets and settings). Break it all you like — production doesn't
notice.
Openship decides which type a new environment is by looking at its branch:
- A branch named `main` or `master` becomes a **production** environment.
- Any other branch becomes a **preview** environment.
- If you create one by hand without a branch, it's a **development** environment.
Each environment is a full, independent copy: its own address, its own variables, its own deploy history. What
they share is the build recipe — when you create one, Openship copies the original project's framework, build
commands, and settings so you don't set them up again.
## Automatic pull request previews
Open the source environment's **Git → Pull request previews**, then enable previews.
This applies to every supported Git-backed stack, including monorepos and Compose services.
Open, non-draft pull requests from the same repository targeting this environment's branch
get an isolated environment. Fork pull requests are excluded. Existing open pull requests
are discovered when you enable the setting.
Set project and service variables in **Environment → Preview** before enabling automation.
Only those values are copied into the new environment's own production variable set;
production variables and inline service secrets are not copied. Preview values are refreshed
on each new commit. Move variables out of install, build, start and lifecycle commands first.
Each environment inherits its source's build configuration when created, uses fresh named
volumes, and gets a distinct URL for each public service port. Workers do not get a public URL.
On a server, supply a **Preview base domain** such as `preview.example.com` and point its
wildcard DNS record at that server. HTTPS verification must succeed before deployment.
Leave the field empty to use managed domains when the deployment target supports them.
New commits deploy their exact SHA. Openship publishes deployment checks through the existing
GitHub Checks integration and can maintain one comment with the preview URL and deployment
link. The GitHub identity needs permission to read pull requests; comments also need write
access. Existing GitHub App installations may need to accept updated permissions.
Closing or merging a pull request, converting it to a draft, changing its base away from the
source branch, or disabling previews removes its environment and owned volumes. Cleanup retries
when the server is unavailable. Reopening an eligible pull request creates a fresh environment.
Delivery deduplication, leases, and periodic reconciliation recover missed webhooks and restarts.
Failures and pending cleanup are visible in the source environment's preview list.
Whole-instance transfers preserve preview ownership and pending cleanup. Disable previews and wait
for cleanup before transferring their environments individually. Portable configuration exports
clear preview automation and host-specific cache receipts; configure them on the destination.
Automation currently supports Docker, direct-server and managed Cloud targets. Cluster targets,
host bind mounts, shared host/container namespaces, and generated service files or inline Dockerfiles
require a separate preview template and are rejected during setup. They cannot silently reuse
production infrastructure. Standard repository Dockerfiles and Compose files are supported.
## Create an environment from a branch
You do this from the project's page, using the **environment switcher** — the little pill at the top that shows
the current environment's name and its branch.
### Open the project and find the switcher
Go to your project. At the top you'll see a rounded button showing the current environment (for a brand-new
project this just reads **Production** with your main branch next to it). Right beside it is a small **+**
button for adding a branch.
### Press + and pick a branch
Click the **+**. Openship reads your repository and lists its branches, with a **Search branches** box at the
top to filter a long list. Click the branch you want to base the new environment on.
Openship creates a fresh copy of the project tied to that branch and drops you onto its page. That's it — you're
now looking at the new environment.
The name is filled in for you from the branch (a branch called `feature/new-home` becomes "Feature New Home").
Nothing you have to type.
### Deploy the new environment
The new environment starts empty — creating it doesn't deploy anything yet. Deploy it the same way you deploy
any project: open it and press **Deploy**. When it finishes, this copy has its own live web address, separate
from production.
### Switching between environments
Once you have more than one, click the switcher pill to see the full list. Each row shows the environment name
and its branch, with a check mark next to the one you're viewing. Click any row to jump to that copy of the
project — its own deploys, logs, and variables.
### Creating one by hand (no branch)
At the bottom of the Add-branch panel there's a **Manual environment** option. Use it when you want an
environment that isn't tied to a specific branch yet — you give it a name (and, optionally, a **Branch label**)
and press **Create**. This makes a *development* environment.
## CLI
If you deploy from the CLI, the `deploy` command has an `--env` flag that tells Openship which environment a
deploy is for. It applies that environment's variables and records the deploy under it.
```bash
# Deploy the project your folder is linked to, as production (this is the default)
openship deploy
# Deploy as a preview instead — uses your preview environment's variables
openship deploy --env preview
```
`--env` accepts exactly `production` or `preview`. Anything else is rejected. If you leave it off, it defaults
to `production`.
Each environment you created in the switcher is its own project with its own ID. To deploy one of those copies
specifically, point the CLI at it with `--project`:
```bash
openship deploy --project --env preview --watch
```
`--watch` streams the build logs until it finishes, so you can see it go live right there in your terminal.
## Troubleshooting
The environment list is built from your GitHub branches, so the project has to be connected to GitHub and have
branches to show. If the list is empty, check that the project is linked to a repository. See
[Deploy from GitHub](/docs/guides/deploy-from-github) for connecting GitHub.
Openship couldn't find that branch in the repository. Make sure the branch actually exists on GitHub (and that
it's pushed, not just local), then try again.
Each environment under a project needs a unique name. If you already turned that branch into an environment,
switch to it from the pill instead of making a second.
Variables are per-environment — a preview copy doesn't automatically inherit production's. Open the preview
environment and add what it needs. See [Environment variables](/docs/guides/environment-variables).
## Related guides
---
# Deploy with openship.json
URL: https://openship.io/docs/guides/openship-json.md
Add a declarative openship.json to your repo so Openship builds and deploys it the same way every time — in the wizard and headlessly on push.
Committing an `openship.json` to your repo root makes your deploy **reproducible**: the framework,
build commands, env, domains, and scaling are declared in the repo instead of clicked through the
wizard each time. It's the same idea as `vercel.json` or `railway.toml`.
Openship still auto-detects everything — `openship.json` just **overrides** what you declare. So
you only add the fields you want to pin. The full field list lives in the
[reference](/docs/reference/openship-json).
## 1. Scaffold it
From your repo root:
```bash
openship config init
```
This writes a minimal `openship.json` with the `$schema` line (for editor autocomplete) plus any
package manager / build command it can detect locally. Open it and add what you need.
## 2. Declare your deploy
A typical server app:
```json
{
"$schema": "https://openship.io/openship.schema.json",
"framework": "nextjs",
"buildCommand": "pnpm build",
"port": 3000,
"runtime": "docker",
"env": {
"NEXT_PUBLIC_API_URL": "https://api.acme.com",
"DATABASE_URL": { "value": "postgres://…", "secret": true }
},
"domains": ["app.acme.com"]
}
```
- **Secrets** — wrap the value in `{ "value": "…", "secret": true }` so it's encrypted at rest.
- **Custom domain** — a dotted hostname is treated as custom; a bare label is a free subdomain.
- **Migrations** — add
[`releaseCommands`](/docs/reference/openship-json#release-commands) (e.g.
`["php artisan migrate --force"]`) to run them once per deploy, after the build and before
the new version goes live. A failure there fails the deploy and the old version keeps serving.
Single-app projects only for now: attaching a service routes the project onto the compose
pipeline, where the commands are logged and skipped.
- **Leave out** anything detection already gets right (most `installCommand`s, `outputDirectory`
for known frameworks, etc.).
A static site is just:
```json
{
"$schema": "https://openship.io/openship.schema.json",
"framework": "vite",
"buildCommand": "pnpm build",
"outputDirectory": "dist",
"productionMode": "static"
}
```
## 3. Validate
```bash
openship config validate
```
Fix any reported error (bad enum, out-of-range port, malformed service). Warnings (e.g. unknown
keys) are non-fatal. Use `--json` for machine-readable output in CI.
## 4. Deploy
Deploy as usual — [from GitHub](/docs/guides/deploy-from-github), a
[local folder](/docs/guides/deploy-local-folder), or the CLI. The wizard opens **pre-filled** from
your `openship.json`; you can still tweak anything before deploying.
Because [auto-deploy on push](/docs/guides/auto-deploy) and headless deploys run the same
resolution, a push to your deploy branch honors `openship.json` with no wizard at all — which is
the point: the repo describes its own deploy.
Detection runs first, then `openship.json` overrides field-by-field. If a deploy isn't picking up
a value, confirm the field name against the [reference](/docs/reference/openship-json) and re-run
`openship config validate`.
## Multi-service and monorepos
Declare `services` for a compose project, or `monorepo` to override detected sub-apps — see the
[reference](/docs/reference/openship-json#services-compose) for both. Note that `services` and
`monorepo` are alternatives to a single-app config, not additions to it.
---
# Custom domains, DNS & SSL
URL: https://openship.io/docs/guides/custom-domains.md
Add custom and wildcard domains, point DNS at your app, and set up HTTPS with a connected provider or manual TXT verification.
import { Step, Steps } from 'fumadocs-ui/components/steps';
When you first deploy, Openship gives your app a working web address for free. This guide is about the next
step: putting it on a name **you** own, like `app.example.com`, with the little padlock (HTTPS) turned on
automatically.
Here's the idea in plain terms. A **domain** is the name people type to reach your app. **DNS** is the
internet's phone book — it's how a name like `app.example.com` gets connected to the actual computer running
your app. **SSL** (that padlock) is what makes the address start with `https://` and keeps traffic private.
Openship handles the padlock for you; your only real job is adding a couple of entries to your domain's phone
book. This guide walks you through all of it.
- A project already deployed in Openship (see [Your first deployment](/docs/getting-started/first-deployment)).
- A domain you own, bought from a **registrar** (Namecheap, Cloudflare, GoDaddy, Google Domains, etc.).
- Access to that registrar's **DNS settings** — the page where you add records. That's where you'll paste
the two lines Openship gives you.
For a self-hosted server behind Cloudflare Tunnel, use [managed tunnel ingress](/docs/guides/cloudflare-tunnel) to publish custom hostnames and optionally protect them with Cloudflare Access.
For differences in proxy settings, route protections, configuration inspection,
and trusted proxies, see [Self-hosted vs Cloud](/docs/guides/the-edge#self-hosted-vs-cloud).
## Choose the primary hostname during deployment
In the deployment wizard, **Include www** adds the companion hostname. For
Cloud and self-hosted destinations, the hostname you typed stays primary and the companion
redirects to it with HTTP `301`. Under **Domain behavior**, choose either hostname
as primary, or **Serve both** to serve the app on both addresses.
The domain list shows which hostname redirects and where it sends visitors.
Redirect-only hostnames do not need a separate app port or static path. Existing
projects keep their current choice until you change it. Both hostnames still need
DNS records, verification and HTTPS.
The same choices are available for Cloud deployments opened through Desktop.
## Steps
### Open your project's Domains tab
Go to your project and open the **Domains** tab. This is home base for everything about addresses and HTTPS.
### Add your domain
Press **Add domain**. In the form that opens, choose **Custom domain**, then type the full address you want,
like `app.example.com`.
If your project runs a server, you'll also see a **Maps to port** field — this is which internal port the
domain sends traffic to. Openship pre-fills it with your app's port, so you can usually leave it.
There are two optional toggles:
- **Include www** — also claim the `www.` version of your domain. It becomes a domain in its own right: it
gets its own DNS record, its own **Verify**, and its own certificate, and by default it sends visitors on to
the bare domain with a `301` redirect (see [Redirect one domain to another](#redirect-one-domain-to-another)
if you'd rather have it the other way round, or have both serve the app).
- **External ingress & TLS** — turn this on **only** if your own edge (like a Cloudflare Tunnel or a load
balancer) already handles HTTPS. Most people leave it off. See [DNS setup, three ways](#dns-setup-three-ways)
below.
Because `www.example.com` is a separate domain, it needs a separate DNS record — Openship lists it alongside
the bare domain's in the next step. Skip it and `www` will stay Pending: it can't be verified, so it never gets
a certificate.
When the form is filled in, press the **Add domain** button at the bottom of the form to save it. (Yes,
it's the same label as the button you just clicked — the first one opens the form, this one saves it.)
Saving the domain just registers your intent. It stays **Pending** until you add the DNS records and verify —
that's the next two steps.
### Copy the DNS records Openship shows you
Right after you add the domain, a **DNS Records** panel appears with the exact entries to create at your
registrar. Each row has a **Type**, a **Host**, and a **Value**, and a **Copy** button next to it.
The panel shows the records for your deployment:
- A **routing record** (an `A` or `CNAME` — Openship picks the right one for you, see below) that points the
name at your app.
- On **Openship Cloud**, an ownership **TXT** record at `_openship-challenge.`.
Self-hosted HTTP verification does not need that record. Wildcard HTTPS uses a separate
`_acme-challenge` TXT value generated by the certificate authority; see [Wildcard domains](#wildcard-domains).
Copy each value exactly as shown — don't retype it, use the Copy button.
If Cloudflare hosts your DNS, choose **Connect a DNS provider** in this panel. An owner or admin can
add a token with **Zone:Read** and **DNS:Edit** for the relevant zones without leaving the deployment
setup. The connection is saved in **Settings → Credentials** and can be reused across the workspace.
Connecting verifies the token; it does not change DNS records.
Credentials belong to the instance where you connect them. For a Cloud project opened through a
linked local or desktop instance, connect the provider in the Cloud dashboard; local credentials
are not copied to Cloud.
For a saved domain, review the proposed additions or changes, then click **Auto-configure DNS**.
Existing values are shown before repointing a record, unchanged records are skipped, and conflicting
record sets are left for manual review. The record list refreshes after applying.
During a new deployment, you can connect the provider ahead of time. If the domain has not been saved
yet, deploy first and apply the records from its DNS settings afterward, or use **Manual DNS setup**
to publish them now. Cloudflare is currently the supported provider for automatic record writes;
other providers use the manual steps below.
### Paste them into your registrar
Open your domain registrar in another tab and find its **DNS** or **DNS records** page. Add each record from
Openship — matching the Type, Host, and Value. Save.
Registrars phrase it differently — you might see "Host", "Name", or "@". Paste the host exactly as Openship
shows it. If your registrar rejects `@`, it usually means "the root of the domain"; and a host like
`_openship-challenge` is added as a subdomain entry. When in doubt, copy Openship's value verbatim.
### Verify
Back in Openship, click **Verify** next to the domain. On a self-hosted or Desktop-connected server,
Openship obtains or reuses a certificate before reporting success. On Openship Cloud, it checks the
routing and ownership records, then requests managed HTTPS. A wildcard on your own server opens
**DNS-verified HTTPS**, where you choose a connected DNS provider or manual TXT verification.
After you save records at your registrar, they can take a few minutes — occasionally up to 48 hours — to
spread across the internet. If Verify doesn't work on the first try, wait a bit and click it again. Openship
also re-checks ordinary pending domains when the verification job is enabled. Manual TXT challenges wait
for you to publish the record and press **Check TXT & enable HTTPS**.
### Watch HTTPS turn on
The **SSL** status becomes **Active** after the certificate is installed. On your own server, verification
includes this step. On Openship Cloud, managed HTTPS can remain **Provisioning** after ownership is verified.
Once routing is configured and SSL is active, your app is reachable at `https://app.example.com`.
Certificates renew automatically with HTTP verification or a connected DNS provider. Manual TXT certificates
require a new TXT challenge at renewal; the domain details show when renewal is due.
## Wildcard domains
Add `*.example.com` to the project's **Domains** tab or the service's public routes. Openship
automatically selects DNS-01 for HTTPS; HTTP verification cannot issue wildcard certificates.
The wildcard certificate covers `app.example.com` and `api.example.com`. It does not cover
`example.com` or `deep.app.example.com`. Add the base domain separately if it should serve the app too.
Choose a concrete hostname for the project's primary address and for links you open in a browser.
On a self-hosted or Desktop-connected server, deploy the project, then open **DNS-verified HTTPS**
on the wildcard's card. The inline panel separates routing DNS from certificate verification:
1. **Point the domain at this server.** Add the displayed routing record, usually `A` with name `*`
and your deployment server's IP. You can also preview and apply it through a connected provider.
This record sends application traffic to the server; it is separate from the certificate TXT.
2. **Enable HTTPS.** Choose one of the methods below. Progress and **Certificate logs** stay in
the panel. Existing certificates remain installed if an attempt fails.
### Automatic provider
Connect **Cloudflare** from the DNS panel or **Settings → Credentials**, using a token with **Zone:Read** and **DNS:Edit** for
the relevant zone. Choose **Automatic provider**, then **Enable HTTPS automatically**. Openship
publishes the certificate challenge, waits for DNS, obtains the certificate and removes its temporary
TXT record. Keep the connection enabled so Openship can renew the certificate automatically.
The routing record still needs to point at the deployment server. A successful DNS certificate
challenge proves domain control; it does not prove that application requests reach the correct port.
### Manual TXT
Use this with any DNS provider when you do not want to connect an API credential:
1. Select **Manual TXT** and press **Get TXT record**.
2. Copy the exact **Name** and **Value** from the generated TXT card. For `*.example.com`, the full
name is `_acme-challenge.example.com`. In a provider that appends `example.com` automatically,
enter `_acme-challenge` as the name. For `*.apps.example.com`, enter `_acme-challenge.apps`.
3. Add that TXT value alongside any existing values at the same name. Do not replace unrelated
verification records. Wait for DNS propagation, then press **Check TXT & enable HTTPS**.
4. Once the panel says **HTTPS is ready**, remove only this attempt's TXT value if desired.
You can leave the page, reconnect, or restart Openship and return to the saved challenge. Retrying
an active attempt reuses its order. Complete it before the deadline shown in the panel; an expired
or invalid challenge needs a new attempt. **Cancel challenge** lets you discard the attempt or
switch methods. Installation that has already started must finish.
When the certificate is within 14 days of expiry, the domain details show that renewal needs attention.
Choose **Renew SSL**, publish the new TXT value and complete the check. Openship does not repeatedly
attempt unattended issuance for a manual domain. To enable automatic renewal, connect Cloudflare,
open the setup panel and choose **Automatic provider**.
Cloud projects and domains marked **External ingress & TLS** use their existing managed or external
HTTPS flow. The local TXT panel applies to certificates Openship installs on your own deployment server.
### SDK and MCP
The SDK and MCP use the same saved challenge and permission checks as the dashboard. With an initialized
SDK client and the saved domain's ID:
```ts
await client.domains.startDnsChallenge(domainId, { mode: "manual" });
const pending = await client.domains.dnsChallenge(domainId);
// Read status until it is "waiting", then publish pending.record in DNS.
if (pending?.status === "waiting") {
await client.domains.checkDnsChallenge(domainId, { attemptId: pending.id });
}
// Read status again for completion, errors and logs.
```
For renewal, start with `{ mode: "manual", force: true }`. To cancel, call
`client.domains.cancelDnsChallenge(domainId, { attemptId })`. The
[Domains API reference](/docs/api/domains) and [MCP tools reference](/docs/api/mcp-tools) list the equivalent
start, status, check and cancel tools. Read status while work is running; stop polling while waiting
for someone to publish DNS or after the attempt settles.
## Retry routing with logs
For a deployed project, open **Domains** and choose **Retry routing** from the warning banner, the
page action, or a domain's menu. This repairs the project's saved routes and checks pending domains
and HTTPS. A domain card whose backing record is missing also offers **Retry routing** directly.
The log viewer shows progress and the reason for any failure, including SSH connectivity and
certificate errors. Working domains retain their state when another domain fails. After the attempt,
the cards refresh from the server; the warning clears only when the checks succeed. Existing usable
certificates are reused.
Closing the viewer stops watching; an accepted repair continues on the server. If the connection
drops before completion, the viewer reports an unknown outcome and keeps the logs it received.
## DNS setup, three ways
Openship figures out which records you need based on where your project runs. You don't choose the first two —
they're picked for you. The records panel tells you which one applies.
Your project runs on your own server, so the domain points straight at that machine's public IP address.
| Type | Host | Value |
|---|---|---|
| `A` | `@` | your server's public IP |
The `A` record is guidance. Self-hosted verification obtains a certificate through ACME; it does not
compare public DNS with your server IP or require an ownership TXT record. The hostname must reach the
server for the selected ACME challenge to succeed.
Your project runs on Openship Cloud, so the domain points at a Cloud address using a `CNAME` (a "this name is
an alias for that name" record).
| Type | Host | Value |
|---|---|---|
| `CNAME` | `@` | an Openship Cloud target |
| `TXT` | `_openship-challenge` | a long verification string |
Openship confirms the `CNAME` and the TXT, then handles HTTPS for you.
For advanced setups where **your own edge already terminates HTTPS** — a Cloudflare Tunnel, a load balancer, or
another reverse proxy in front of Openship. Turn on **External ingress & TLS** when adding the domain.
| Type | Host | Value |
|---|---|---|
| `TXT` | `_openship-challenge` | a long verification string |
On **Openship Cloud**, add the TXT record above to prove domain ownership. On a **self-hosted instance**,
the operator already owns the server: no DNS record is requested or checked. Openship does not issue a
certificate in either case; the SSL status reads **External TLS**.
For a homelab behind **Nginx Proxy Manager**, point your internal DNS name at NPM and configure it to forward
to the Openship server reachable on your LAN or tunnel. NPM owns HTTPS. Choose **External ingress & TLS**
for the domain, then verify it. Your rotating home WAN address is not a verification requirement.
Clients outside your LAN still need a reachable address, VPN, or tunnel; private DNS alone does not provide
public access.
## Redirect one domain to another
Any domain on a project can send its visitors to another domain on the same project instead of serving the
app. Openship answers a `301` (or `302`, if you pick it) and keeps the rest of the URL, so
`https://www.example.com/pricing?ref=x` lands on `https://example.com/pricing?ref=x`.
Open your project's **Domains** tab, press **Edit**, and set **Redirect** on the domain you want to send
*away*. Pick the destination from the list — it only offers this project's own domains — and choose whether
it's permanent (`301`) or temporary (`302`). Choose **Serve the app here** to turn a redirect off again.
The two common uses:
- **Pick a canonical hostname.** `www.example.com` → `example.com`, or the reverse. This is what **Include www**
sets up for you (pointing `www` at the bare domain), and you can flip it either way. Without a redirect both
hostnames serve the same app, which search engines treat as duplicate content.
- **Move to a new domain.** Keep the old one verified and redirect it to the new one, so existing links and
bookmarks keep working.
It has to answer `https://` before it can redirect anyone, so it goes through the same setup as any other
domain. That's also why it keeps showing its own **Status** and **SSL** rows.
Two things Openship won't let you do, because both break the site rather than the setting: redirecting to a
domain outside the project (that would turn a domain you own into an open redirect for someone else's traffic),
and creating a loop — `A` → `B` → `A` would bounce every request until the browser gave up.
Self-hosted deployments apply redirects through the server’s edge configuration.
Openship Cloud applies the same redirect intent through its managed edge.
## Bring your own certificate
For setups where your upstream needs the **origin** to present a real certificate too — most commonly
**Cloudflare Full (strict)** — upload your own instead of using Let's Encrypt.
1. On a verified domain, open its menu and choose **Upload certificate**.
2. Paste the **certificate** (full chain, PEM) and the matching **private key** (PEM). A free
[Cloudflare Origin CA](https://developers.cloudflare.com/ssl/origin-configuration/origin-ca/) certificate
(15-year) is a great fit here.
3. Openship serves HTTPS from that certificate and stops running Let's Encrypt for this domain.
There's nothing for Openship to renew, so it watches the expiry and reminds you — upload a fresh certificate
before it lapses.
## CLI
The CLI supports ordinary domain creation and verification. The `add` command prints the DNS records and
the domain's ID; use that ID to verify. For manual TXT, use the dashboard, SDK, API or MCP lifecycle above.
```bash
# See exactly which records a domain will need (nothing is saved)
openship domain preview app.example.com
# Add the domain to a project (prints the records + the domain ID)
openship domain add app.example.com --project
# Once your DNS is in place, verify it
openship domain verify
# List a project's domains and their status
openship domain list --project
```
`openship domain records ` reprints the records for an existing domain, `openship domain primary
` makes a domain the project's main address, and `openship domain renew ` /
`openship domain verify-ssl ` manage the certificate. Full details are in the
[Domains API reference](/docs/api/domains).
## Troubleshooting
Read the failure message for the selected verification mode. Cloud failures identify the routing or ownership
record. Self-hosted failures identify the certificate challenge or server connection. For manual TXT, compare
the exact `_acme-challenge` name and value, then retry the saved challenge from **DNS-verified HTTPS**.
This is the most common hold-up and it's usually just time. DNS changes can take minutes, and occasionally up
to 48 hours, to spread worldwide. Save the records, then wait and retry Verify — Openship also re-checks
ordinary pending domains automatically when the job is enabled. Manual TXT waits for your check. Check for a
typo in the record name or a conflicting routing record. Remove conflicting routing records as needed, but keep
unrelated TXT values at the challenge name.
The certificate is still being issued, or a request to Let's Encrypt hasn't completed. Give it a minute, then
open the domain's **⋯** menu and click **Recheck SSL** — a quick, no-cost check that flips the status to
**Active** once the certificate is actually in place. If it never provisions, use **Renew SSL** to try again;
the error message will name the real reason.
They're two separate domains, so they're set up separately. Check the **Domains** tab: whichever one is still
**Pending** is missing its DNS record. Openship listed both records when you added the domain — open the failing
domain's DNS panel again, add the one it's asking for, then press its own **Verify**. A working apex tells you
nothing about `www`; each has its own record, verification and certificate.
On a self-hosted install, Verify streams the certificate request live and the log stays on screen whatever the
outcome — that log names the real cause (DNS not resolving, port 80 unreachable, a proxy answering `404`). Use
**Copy log** if you want to keep it, and **Try again** to re-run without closing the window.
## Related guides
---
# Deploy a local folder
URL: https://openship.io/docs/guides/deploy-local-folder.md
Put an app online straight from a folder on your computer — no GitHub required. The desktop picker, the browser upload, and the one-command CLI way.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Not everything lives on GitHub. Sometimes the code is just a folder on your laptop — one you cloned ages
ago, downloaded, or started from scratch. Openship can take that folder and put it online, no git remote
needed. Think of it like mailing a parcel instead of a letter: you hand over the whole box of files, and
Openship unpacks it, figures out what's inside, builds it, and gives you back a real web address.
- Openship up and running (you can see the dashboard). If not, start with [Installation](/docs/getting-started/installation).
- A folder on disk with your app in it — a website, an API, anything.
- You do **not** need Docker, a server config, or any special files. Openship reads your folder and works out the rest.
## What actually gets uploaded
Openship sends your **source files** — the code you wrote — and nothing else. The heavy, rebuildable stuff
is skipped: `node_modules`, `.git`, and build output like `dist` and `.next` never go over the wire. Your
dependencies get reinstalled fresh during the build, so leaving them behind is exactly what you want. It
keeps the upload small and your build clean.
The **desktop app** is the exception: it reads your folder straight from disk and uploads nothing at all.
## In the dashboard
Open the **Library** page (the **New project** button lands you here too) and choose the **Folder** tab.
What you see next depends on how you're using Openship. The **desktop app** can read a folder directly off
your computer. A **web browser** (talking to a self-hosted or cloud instance) can't peek at your filesystem,
so it uploads a copy of the folder instead. Pick the tab that matches you.
The desktop app runs on the same machine as your files, so it opens them straight from disk — nothing is
uploaded.
### Open the Folder tab and press Import
The **Folder** tab shows your **Local Projects**. The very first time it's empty — you'll see "No local
projects yet" and an **Import Project** button. Once you've added some, the panel lists them with an
**Import** button at the top for adding more.
### Pick your folder
A folder picker opens. Browse to your project folder and select it — that's all Openship needs.
On some setups the native picker isn't available. Instead you'll see an **Import from folder** form: type the
folder's full absolute path (like `/Users/you/projects/my-app`), or press **Browse**, then press **Scan**.
Openship shows the **Detected** stack and an editable **Project name** — press **Import Project** to add it to
your Local Projects list, then deploy it from there.
### Press Deploy and watch it go live
Openship takes you to the deploy screen with the detected stack already filled in — the framework, the
package manager, and the build and start commands. For most apps there's nothing to change. Press **Deploy**
and the build screen streams the logs live. When it finishes, you get a link — click it and your app is
online. 🎉
In a browser, Openship can't see your disk — so you tell it what you're deploying, then hand it the folder
and it packs and uploads a copy.
### Pick your stack
The Folder tab asks **"What are you deploying?"** Choose the tile that matches your app (for example Next.js,
Vite, or Express). This tells Openship which build environment to prepare.
### Drop in your folder
Drag your project folder onto the drop zone, or click to browse for it. The panel notes what gets left out —
`node_modules`, `.git`, and build output are skipped. Once it's picked, you'll see a summary line with the
folder name and how many files it contains.
### Press Continue
Openship packs the folder **in your browser** and uploads it, then takes you to the deploy screen. The button
shows a short **Packing folder…** then **Uploading…** while it works — bigger folders take a little longer.
### Press Deploy and watch it go live
On the deploy screen, press **Deploy**. The build screen streams the logs as it goes, and when it's done you
get a live link. 🎉
## CLI
The CLI does the whole thing in one command. Run `openship deploy --folder` to explicitly upload the current
directory. It packages that folder, uploads it, auto-detects the stack, creates the project
(or reuses one that already has the same name), and deploys it — the same pipeline as the browser upload
above.
```bash
# From inside your project folder:
openship deploy --folder --name my-app --watch
```
- `--name` sets the project's name (without it, the folder's name is used).
- `--watch` follows the build logs in your terminal until it finishes. Leave it off and Openship prints a
command to follow the logs later.
`--folder` also uploads files directly from a Git checkout. Without it, `openship deploy` in a Git
repository uses the Git flow. Outside Git, `--name` also opts into a folder upload for existing scripts.
Run from your app's source directory: uploading the temporary directory or any ancestor of it is refused
to keep staging archives outside the source tree. If `TMPDIR` is inside your app, set it elsewhere.
### Deploy to the same project again
Openship matches your folder to a project by **name**. Run `openship deploy --name my-app` a second time from
the same folder and it updates *that* project instead of making a new one — so repeat deploys just ship new
versions.
To pin the folder to one exact project — even if you rename it or forget the `--name` flag — link it once
with `openship init`:
```bash
openship init # pick a project to link this folder to
openship deploy --folder # uploads this folder to the linked project
```
`openship init` writes a small `.openship/project.json` file so later commands know which project this folder
belongs to. It links to a project that **already exists**, so create one first — with a folder deploy, or in
the dashboard — then run `openship init` to pin future deploys to it.
## Troubleshooting
Everything in the folder was on the skip list (like `node_modules` and `.git`), or you picked a folder with
no source in it. Choose the folder that actually contains your app's code — the one with your `package.json`
(or `go.mod`, `Cargo.toml`, and so on).
A web browser only gives Openship the folder's **name**, not its full location on disk. When the form asks
for a path, type the full absolute path (like `/Users/you/projects/my-app`) and press **Scan**. Or use the
desktop app, which can open the folder directly.
Open the build screen and read the last few red lines — that's the real reason. First-time failures are
almost always one of three things: a missing build command, a missing environment variable, or the app
listening on the wrong port. See [Troubleshooting → Deployments](/docs/troubleshooting/deployments) for fixes.
## Related guides
---
# Self-hosted GitHub Apps
URL: https://openship.io/docs/guides/self-hosted-github-app.md
Create and manage workspace-owned GitHub Apps for private repositories, direct webhooks, and short-lived clone tokens without Openship Cloud.
import { Step, Steps } from 'fumadocs-ui/components/steps';
A self-hosted Openship workspace can own one or more GitHub Apps end to end. App private keys and webhook
secrets are encrypted in the local database, GitHub sends webhooks directly to your instance, and builds use
short-lived installation tokens instead of a long-lived personal access token.
Use the dashboard's **Settings → Git → Self-hosted GitHub Apps** section. You can create a GitHub.com App
with the one-click manifest flow or register an existing GitHub.com/GitHub Enterprise Server App manually.
Neither flow requires an Openship Cloud connection or a separate GitHub OAuth login.
Each source belongs to the active Openship workspace. A workspace may register several Apps and install each
one on several GitHub users or organizations. The same GitHub owner can be covered by more than one source;
the source marked **Default** wins for new and existing project bindings when it has an active installation.
## Before you start
You must be a workspace owner and the instance must have a public HTTPS URL. Configure
`OPENSHIP_PUBLIC_URL=https://openship.example.com` (or the equivalent public URL setting) and restart the
instance. GitHub must be able to reach both URLs shown in the source form:
- Setup callback: `https://openship.example.com/auth/callback/github-app`
- Webhook endpoint: `https://openship.example.com/api/proxy/api/webhooks/github`
The dashboard disables App registration until Openship can resolve a configured public URL.
## One-click manifest setup (GitHub.com)
### Start in the dashboard
Open **Settings → Git**, choose **Create with GitHub**, give the source a recognizable workspace label, and
select **Continue on GitHub**.
### Review and create the App
Openship submits a private GitHub App manifest with these repository permissions:
- **Contents:** read
- **Metadata:** read
- **Pull requests:** read
- **Checks:** read and write
- **Commit statuses:** read and write
It subscribes to `push`, `pull_request`, `check_run`, and installation lifecycle events. Review the values on
GitHub and create the App. GitHub returns the generated private key, client secret, and webhook secret once;
the callback immediately encrypts them and never returns them to the dashboard.
### Choose repository access
After conversion, Openship opens the new App's installation page. Choose the GitHub user or organization and
either all repositories or selected repositories. The setup callback verifies the installation with that
specific App's private key before binding it to the originating Openship user and workspace.
The creation and installation links each use a separate, ten-minute, one-time state value. Replaying a state,
using it from another workspace, or substituting another App's `installation_id` is rejected.
## Register an existing App or GitHub Enterprise Server
Choose **Register existing App** and enter the values from the App's settings. For GitHub Enterprise Server,
also expand **GitHub Enterprise settings** and set both origins, for example:
```text
GitHub web URL: https://github.acme.example
GitHub API URL: https://github.acme.example/api/v3
```
Configure the App itself with the Setup URL and Webhook URL displayed by Openship. Give it the same permissions
and event subscriptions listed above, create a private key, and set a high-entropy webhook secret of at least
16 characters. Then provide:
- a workspace label and numeric App ID;
- the complete PEM private key;
- the matching webhook secret;
- the Client ID and client secret, if your App also uses them (installation-token auth does not require them).
Openship calls the selected GitHub API's `/app` endpoint with a signed App JWT before storing anything. A bad
App ID, key, or Enterprise API URL is rejected, and upstream error details are redacted from the response.
## Manage sources and installations
Each source card shows its App identity, health, installed accounts, endpoint, and whether it is the default.
From the card, a workspace owner can:
- install the App on another GitHub account or change its repository selection;
- verify the stored key and refresh App metadata;
- edit endpoints or rotate credentials (leave secret fields blank to keep their encrypted values);
- make the source the default; or
- delete the local source.
Deleting a source removes its encrypted credentials and installation bindings from Openship, but cannot
uninstall the App on GitHub. Use **Manage on GitHub** to uninstall it there. Projects are atomically rebound to
another active installation for the same owner when one exists; otherwise their App binding is cleared and
auto-deploy is disabled. GitHub access grants are retained only when another installation still covers that
owner.
GitHub suspension is reversible: Openship retains the binding but excludes it from token resolution until an
`installation.unsuspend` delivery restores it. Uninstall permanently removes the affected binding.
## Runtime behavior
- Repository browsing merges App-visible repositories with an optional local `gh`/token identity without
duplicating repositories.
- Every private clone token is minted directly from the App that owns the selected installation, limited to
the requested repository, and refreshed before GitHub's expiry.
- GitHub Enterprise REST requests and HTTPS clone URLs use that source's configured API and web origins.
- App-level push and check webhooks are verified against that source's secret. Push fan-out is additionally
restricted by the delivering installation id, preventing cross-workspace deployment.
- App-backed projects use the shared App webhook; Openship does not create duplicate repository webhooks.
- Commit statuses and check runs are written with the custom App's GitHub identity and branding.
## Legacy environment-based App
The process-wide `GITHUB_APP_ID`, `GITHUB_APP_SLUG`, `GITHUB_PRIVATE_KEY_BASE64`, and
`GITHUB_WEBHOOK_SECRET` configuration remains supported for existing installations. Dashboard-managed sources
take precedence for the workspace and are the recommended setup for new self-hosted Apps because they support
multiple Apps, rotation and health checks without restarting Openship.
Personal access tokens, per-server SSH keys, and `gh` remain optional fallbacks for repositories not covered by
an App. They are not required for a workspace-owned App installation.
---
# Deploy from a template or Git URL
URL: https://openship.io/docs/guides/deploy-template-or-url.md
Two quick ways to start a project without connecting your own GitHub — paste a public repo link, or pick a ready-made starter from the template grid.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Not every project starts from a repo you own. Sometimes you just want to put someone else's public
project online, or spin up a fresh app from a blank starter. Openship has two shortcuts for exactly that,
and neither one asks you to connect your GitHub account first.
Think of it like a library. You can borrow a book by its exact catalog link (**a Git URL**), or grab one
off the "new and popular" shelf that's already set up for you (**a template**). Both land you on the same
checkout desk — Openship's normal setup screen.
- An Openship account (you're already in if you can see the dashboard).
- For the **Git URL** path: the web address of a **public** GitHub repository.
- For the **Template** path: nothing at all — Openship provides the starter code.
Deploying a repo you *own* (including private ones)? Use [Deploy from GitHub](/docs/guides/deploy-from-github) instead.
## Import by pasting a Git URL
This is the fastest way to try out any public GitHub project — no account linking, no permissions to grant.
### Open the Git URL tab
Go to the **Library** page (the **New project** button lands you here too) and click the **Git URL** tab.
### Paste the repository link
Copy the project's page address from GitHub — the plain `https://github.com/owner/repo` link in your
browser's address bar — and paste it into the box. Then press **Import Repository**.
This box reads **public** repositories on **github.com**. You don't need to connect anything — Openship
just fetches the code. Private repos and other hosts won't work here; for those, connect your account with
[Deploy from GitHub](/docs/guides/deploy-from-github).
### Finish on the setup screen
Openship reads the repo and drops you on the same setup screen as any other deploy: it shows the framework
it detected, the build command, and the web address your app will get. From here, the steps are identical to
a normal GitHub deploy — [choose where it runs and press Deploy](/docs/guides/deploy-from-github#steps).
## Start from a template
No code yet? A template is a ready-made starter app that Openship hosts for you. Pick a framework and you
get a working project to build on — like starting a document from a blank template instead of an empty page.
### Open the Template tab
On the **Library** page, click the **Template** tab. You'll see a grid of framework tiles — things like
**Next.js**, **Astro**, **Express**, **Django**, and more.
### Pick a framework
Click the tile for the stack you want. That's the whole choice — Openship uses its matching starter as the
source, so there's nothing to paste or fill in.
### Finish on the setup screen
Just like the URL path, you land on the standard setup screen with everything pre-filled. Review it if you
like, then [choose where it runs and press Deploy](/docs/guides/deploy-from-github#steps).
When the build finishes, you get a live link to your brand-new app.
## CLI
The Git URL path is really just "make a project pointing at this owner and repo." You can do the same from
the CLI — split the link's `owner` and `repo` out of `github.com/owner/repo`:
```bash
# For https://github.com/openship/example → owner = openship, repo = example
openship project create --name my-app --git-owner openship --git-repo example
# Ship it
openship deploy
```
## Troubleshooting
Openship couldn't find an owner and repository in what you pasted. The box only accepts **github.com**
links shaped like `https://github.com/owner/repo`. This error usually means the link points at another
host (like GitLab or Bitbucket), or it's missing the owner or the repository name. Copy the address from
the repo's page on GitHub and try again.
Open the build screen and read the last few red lines — that's the real reason. Common causes are a missing
build command, a missing environment variable, or the app listening on the wrong port. See
[Troubleshooting → Deployments](/docs/troubleshooting/deployments) for fixes.
The Git URL box only reaches **public** code. To deploy a private repository, connect your GitHub account
first — see [Deploy from GitHub](/docs/guides/deploy-from-github).
## Related guides
---
# Environment variables & secrets
URL: https://openship.io/docs/guides/environment-variables.md
Give your app its settings and secrets — add them in the Configuration tab or the CLI, keep the sensitive ones masked, and apply changes without a full rebuild.
import { Step, Steps } from "fumadocs-ui/components/steps";
Most apps need a few pieces of information to run: a database address, an API key, a "am I in production?"
flag. Those are **environment variables** — little named settings your app reads when it starts. Think of
them as sticky notes you hand your app: `DATABASE_URL = ...`, `STRIPE_KEY = ...`. Openship keeps those notes
for you, hands them to your app every time it builds and runs, and hides the sensitive ones so nobody can
read them over your shoulder.
- A project you've already created in Openship (if not, start with [Deploy from GitHub](/docs/guides/deploy-from-github)).
- The names and values you want to set — for example `DATABASE_URL` and its connection string.
- Nothing else. Openship encrypts and stores the values for you.
## Add or edit variables in the dashboard
### Open the Configuration tab
Go to your project and open the **Configuration** tab. Find the **Environment variables** card and press
**Edit**. A panel opens showing the variables you already have (empty is fine — a brand-new app often has
none).
### Add a variable
Press **Add variable**. You get a row with two boxes: the **KEY** on the left (the name, like `DATABASE_URL`)
and the **value** on the right. Type both.
Add as many rows as you need. To remove one, press the trash icon at the end of its row.
### Mark the secret ones
Some values are sensitive — passwords, API keys, tokens. For each of those, press the **key icon** on the
row to **mark it as secret**. A secret's value is stored the same way, but from then on it shows as dots
(`••••••••`) instead of plain text, so it stays hidden whenever you reopen the editor.
Whether or not you mark a variable secret, Openship **encrypts every value before saving it**.
Marking a value secret adds the on-screen masking on top — it controls what *you* can see later,
not whether it's protected on disk.
Inline service environment values and build arguments are also encrypted, including their copies in
saved deployment snapshots and Compose drift baselines. Existing plaintext service configuration is
converted when the API or native engine starts after upgrading. Keep your `BETTER_AUTH_SECRET` with
your database backup: it is needed to read these values. To downgrade to a version from before this
protection, restore its matching database backup as well.
When moving to an installation with a different key, use **Settings → Data Transfer** with secrets
included. It re-encrypts the configuration for the destination. Transfers or recovery manifests that
omit secrets also omit inline environment, build arguments and protected service configuration; set
those values again before deploying.
### Save
Press **Save changes**. Openship only writes the rows you actually added, changed, or deleted — every other
variable is left exactly as it was. That's why a masked secret you didn't touch is never overwritten: you
never re-typed it, so it's never re-sent.
A saved change is stored right away, but the **running app keeps its old values until the next
deploy**. If something is already live, Openship offers a shortcut to push the change out
immediately — see [Apply without a full rebuild](#apply-without-a-full-rebuild) below. Otherwise
the new values take effect the next time you deploy.
## When your app sees these values
Project-level variables are available at **two moments**:
- **During the build** — so a value baked in at build time (for example a `NEXT_PUBLIC_...` setting in a
frontend) is there when the build runs.
- **At runtime** — so your running server can read them the normal way (like `process.env.DATABASE_URL`).
For a Dockerfile build, declare every value you consume with `ARG` (and copy it into `ENV` only when the
running image also needs it):
```dockerfile
ARG NEXT_PUBLIC_API_URL
ENV NEXT_PUBLIC_API_URL=$NEXT_PUBLIC_API_URL
RUN npm run build
```
The project environment is the shared build/runtime layer. A multi-service project's `services[].env`
is different: it belongs only to that service at runtime and is never leaked into an image build. In
`openship.json`, add `services[].buildArgs` when an image needs an explicit build-only value or when you
want to document which shared key it inherits:
```json
{
"env": { "NEXT_PUBLIC_API_URL": "https://api.example.com" },
"services": [
{
"name": "web",
"build": ".",
"buildArgs": { "NEXT_PUBLIC_API_URL": null, "BUILD_FLAVOR": "production" }
}
]
}
```
Here `null` means “inherit the same-named project variable”; a string is a per-image override. Values
declared in top-level `openship.json.env` become active project defaults automatically. A generic `.env`
file is only used after you choose **Import .env**.
Build arguments can remain visible in image metadata or build cache. Prefer runtime environment
variables for credentials. If a build genuinely needs a secret, use a dedicated BuildKit secret
flow rather than committing it to `openship.json` or baking it into the image.
## Service overrides and credential rotation
Open **Services → select a service → Environment** to see its effective saved
variables. The list includes Compose values, shared project variables and explicit
service overrides, with a source label on each row. Openship stores these values;
the list remains available when the deployment server is offline.
Editing an inherited value creates an override for that service. Saving changes
only the rows you edited; it does not copy the other inherited values into
overrides. Removing an override restores the inherited value, if one exists.
Remove inherited keys at their Compose or project source. Conflicting edits from
another session are rejected before anything is saved.
On a normal service deployment, the highest-priority value wins in this order:
1. A service-scoped variable from its environment editor.
2. A literal in that service's Compose `environment` or `openship.json` `env` map.
3. The project's environment, captured when the deployment starts.
Compose expressions such as `TOKEN: ${TOKEN}` resolve against the configured values;
they do not pin a previous scan's value. A rollback instead replays its captured
project values, including their precedence over present-day service overrides.
`openship project env set` warns when a changed or deleted key still has a service
override. The API and SDK return the same `warnings` array, and deployment logs name
keys whose service values win. These messages contain names only. Saving the project
value succeeds, but it cannot replace a service-owned credential. Update the service
value, or remove its override to inherit the project value, then deploy. Deleting a
project variable does not delete a service's copy.
For example, if `web` pins `TOKEN=old`, setting the project's `TOKEN=new` will warn
about `web`; a rebuild alone still uses the pinned value. In the service editor,
remove that override before relying on the project's rotated token.
## Reveal, hide, and replace a secret
Inside the editor, each value has an **eye icon** to show or hide it. A secret you saved earlier comes back
masked with the placeholder `•••••••• (set — type to replace)`. To change it, just type the new value over
the dots. To keep it, leave it alone — Openship keeps the stored value untouched.
## Production and preview values
Openship keeps variables **per environment**, so your test setup and your live setup can differ (a `preview`
build can point at a test database while `production` points at the real one). The three environments are
`production`, `preview`, and `development`.
The project editor manages **production** values. A service's Environment tab uses
its active deployment's environment, or production before the first deployment.
The CLI also supports `preview` and `development` through `--environment`.
These are variable sets within a project. Runtime isolation comes from selecting a separate
non-production project environment and deploying its project ID. Passing `--env preview` against
a production project is rejected; it cannot promote that preview onto the production runtime.
See [preview deployment](/docs/cli/deploy) for the complete flow.
## Download environment variables
In a service's **Environment** tab, choose **Download .env** beside **Upload .env**.
The file contains the listed variables and their real saved secret values. Downloading
does not reveal those secrets in the editor, save edits, or restart the service.
Unsaved edits shown in the editor are included in the download.
The file uses Compose-compatible `.env` quoting. **Upload .env** restores its literal
values, including dollar signs, quotes, and multiline values, without expanding variable references.
## Apply without a full rebuild
Rebuilding an app just to change a setting is slow — nothing about your _code_ changed. So when you save an
env change and the project is already deployed, the editor shows an **Apply (restart, no rebuild)** button.
Press it and Openship recreates the running container from the image it already built, with the new values
injected. No git clone, no build — just a quick restart. It's the fastest way to roll out a changed key or a
rotated secret.
From the terminal, `openship deploy --refresh` (shown below) applies environment
changes through a deployment without rebuilding.
For one service, open its **Environment** tab, press **Save**, then
**Apply environment changes** in the toolbar above the variables. It refreshes only
that service using the image already running on its target. The editor stays open
and shows completion after the service starts. This is a dedicated service action
(`POST /api/projects/:id/services/:serviceId/apply-env`); it creates no deployment or
build session. Docker gets a graceful stop, and the replacement retains the existing
ports, project network address, volumes, commands, and resource limits. If startup
fails, Openship restores the previous container and leaves the changes pending.
The toolbar offers Apply only when a comparison with the deployed container finds
saved changes, including removed variables. **Check running service** refreshes
that comparison. An unavailable server is reported as an unknown state, while the
saved variables remain editable.
For an older or migrated service, Docker may still hold variables that were never
saved in Openship. **Recover from running service** reads those missing values
from that service's container, excluding image defaults, and adds them to the
editor for review. Press **Save** to store them encrypted in Openship. Recovery
never overwrites an already saved value. Before applying, recover these values or
explicitly choose to remove them from the running service.
This action supports Docker services on a server or an Openship Cloud Docker
workspace. Legacy cloud workspaces and adopted containers on Docker's default bridge
require **Redeploy**. Namespace-sharing services must be refreshed together through
a deployment.
A normal **Restart** keeps the container's existing variables. When saved changes are
pending, Openship opens the service's **Environment** panel so you can apply them there.
Variables used during a build still require a rebuild.
## CLI
Everything above works from the CLI. Secret values always come back **masked** when you list them.
```bash
# List a project's variables (secrets show masked)
openship project env get
# Set one or more values (repeat --set for each)
openship project env set --set DATABASE_URL=postgres://... --set LOG_LEVEL=info
# Mark the values in this command as secret
openship project env set --set STRIPE_KEY=sk_live_... --secret
# Remove a variable
openship project env set --unset OLD_FLAG
# Target a different environment (defaults to production)
openship project env set --environment preview --set API_URL=https://staging.example.com
# Push the current env to the running app — no git pull, no rebuild
openship deploy --refresh
```
`env set` **merges**: it only touches the keys you name with `--set` and `--unset`, leaving everything else
in place.
For a multi-service (compose) project, each service has its own variables. Target the stack with
`-p` and the service by name:
```bash
# List a service's variables (secrets masked)
openship service env get web -p my-stack
# Set values for a service (KEY=VALUE pairs)
openship service env set web -p my-stack DATABASE_URL=postgres://... --secret
# Pick the environment (defaults to production)
openship service env set web -p my-stack -e preview API_URL=https://staging.example.com
```
The service command writes the whole environment at once, so it first reads the current values and
merges yours in. Because saved secret values can't be read back, if the service already has a
secret you didn't re-type, the command stops and asks you to re-specify it — or pass `--replace`
to drop every value that isn't in your command.
## Troubleshooting
Saving stores the value; the **running app** only picks it up on a deploy. Use **Apply (restart,
no rebuild)** (or `openship deploy --refresh`) to push it out now, or just redeploy.
That's on purpose — Openship never reveals a stored secret's value again, in the dashboard or the
CLI. If you need to change it, type a new value over the dots. If you've lost the original, set a
fresh one.
Your app expected a variable that isn't set yet. Add it in the **Configuration** tab (or with
`openship project env set`), make sure the name matches exactly — env names are case-sensitive —
then deploy again. See [Troubleshooting → Deployments](/docs/troubleshooting/deployments) for
more.
## Related guides
## Build-time variables and command migration
Saved project variables are supplied to install and build commands as well as runtime processes.
Service variables override the project values for that service. This applies across managed stack
builders, including Node/Bun, Python, PHP, Ruby and compiled stacks. A custom Dockerfile must declare
and consume its own build arguments. Browser-facing variables such as `NEXT_PUBLIC_*` and `VITE_*`
are compiled into client assets: rebuild after changing them, and never put secrets in them.
Build settings warn about embedded variables at the start of a command or after shell separators
such as `&&` and `;`. **Move to Environment** removes literal leading assignments and saves their
values in one transaction. Chained assignments require manual editing to preserve their scope.
Existing equal values are retained; conflicting values or concurrent command edits stop the migration.
Shell expansions and command substitutions require manual editing. Values are encrypted and masked;
warnings and audit records contain variable names only. The import wizard supports the same action
before the project is saved.
Before installation, managed builders inspect empty declarations in the selected app's `.env.example`
and warn about unconfigured names. This is advisory because an empty example can be optional.
The file is never executed. Compose required-variable expressions retain their existing blocking validation.
## Managed output and build caches
Next.js standalone builds use the generated manifest to locate the app server, preserve the complete
traced workspace, and copy `.next/static` and `public` beside that server. Default startup selects the
correct entry and working directory automatically. Nuxt uses its self-contained `.output` server through
the same stack registry. Other stacks keep their registered runtime commands; custom commands remain
authoritative. Invalid root directories fail before installation, and an invalid explicit Next standalone
server path is reported with instructions to clear the override.
Supported Docker builders use managed package and framework caches. Build settings detect legacy manual
cache mounts and offer **Use managed caches** only after a deployment succeeds with the corresponding
managed cache paths. Migration removes configuration mounts and retains existing volume data. Ordinary
application data mounts are excluded. Cache paths come from each package manager and stack definition,
so this also covers Python, PHP, Ruby, Go, Rust, Java and other registered builders.
Build logs report observed Docker layer cache hits and misses, the managed cache paths, and build-time
comparisons when previous timing is available. Layer reuse does not prove a package cache hit inside a
running build step. Unsupported builders keep their original cache behavior and manual mounts.
---
# Logs & monitoring
URL: https://openship.io/docs/guides/logs-monitoring.md
See what your app is doing — its runtime logs, its incoming web requests, and its traffic — and know exactly where to look when something breaks.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Once your app is online, the next question is always the same: *what is it actually doing right now?* Logs are
how you find out. Think of them like a diary the app keeps — every time it starts, prints a message, or handles
a visitor, it writes a line. When something goes wrong, that diary is the first place to look.
Openship gives you two kinds of diary and one big-picture view:
- **Runtime logs** — what your app itself prints (startup messages, errors, `console.log`). This is what you
want when the app is crashing or misbehaving.
- **Request logs** — a line for every web request that reached your app: who asked, for what page, and what
answer they got. This is what you want when you're asking "is anyone visiting?" or "why are people getting
errors?"
- **Analytics** — the same request data rolled up into totals and a traffic chart, so you can see trends
instead of individual lines.
- A project that has been deployed at least once (you can see it in the dashboard).
- For **runtime logs**: the app has to actually be running — a static site has no running process, so it has no
runtime logs to show.
- For **request logs and analytics**: some real traffic. A brand-new app with no visitors has nothing to show yet.
## Open the Logs tab
### Go to your project
From the dashboard, open the project you want to inspect. The project page has a row of tabs along the side —
**Overview**, **Services**, **Domains**, **Deployments**, **Source**, **Configuration**, **Logs**, and so on.
### Click **Logs**
This is your live window into the running app. Inside it you'll find two sub-tabs at the top: **Terminal** and
**Server**. The next two sections explain each one.
## Runtime logs — the **Terminal** sub-tab
The **Terminal** sub-tab is a live view of everything your app prints while it runs — the same output you'd see
in a terminal if the app were running on your own machine. If your code calls `console.log`, throws an error, or
prints a startup banner, it shows up here.
A few things worth knowing:
- **It streams by itself.** When you open the tab it starts tailing new lines automatically. A small green dot
and a **Stop** button tell you it's live; press **Stop** to freeze it, **Start** to stream again.
- **Search.** There's a search box at the top — type to highlight matches, press **Enter** / **Shift+Enter** to
jump between them.
- **Copy, Download, Clear.** The buttons on the right let you copy the visible logs to your clipboard, save them
to a `.txt` file, or clear the view.
If your project runs several services (a docker-compose stack, for example), a small **Runtime log target**
picker appears above the terminal. Choose the project runtime or a specific service to see just its output.
A static site is just files — there's no process running to print anything — so there are no runtime logs and
the **Terminal** sub-tab is hidden. On **Openship Cloud**, a static site still gets request logs, shown on a
single sub-tab labelled **Requests**. On a **self-hosted** static deploy there's no runtime to stream, so the
Logs tab simply reads *"No runtime logs."* That's expected, not a bug.
## Request logs — the **Server** sub-tab
The **Server** sub-tab (titled **HTTP Request Logs**) shows one line for every web request that reached your app.
Each line tells you:
- the **method** (GET, POST, …) and the **path** that was requested,
- the **status code** the app sent back (green for 2xx, blue for 3xx, amber for 4xx, red for 5xx),
- how long it took (**response time** in milliseconds),
- the visitor's **IP address** and country, the bytes in and out, and their browser (user agent).
Like the Terminal, this view is **live** — new requests appear at the top as they happen.
The colour is the quick tell. **Green (2xx)** means success. **Amber (4xx)** means the visitor asked for
something that isn't there or isn't allowed (a 404, say). **Red (5xx)** means *your app* errored while handling
the request — that's the one to chase, and the Terminal tab usually has the matching error.
If your project answers on more than one domain, a **domain switcher** appears in the header so you can look at
one domain's requests at a time.
## The bigger picture — analytics on the **Overview** tab
Individual request lines are great for "what just happened," but for "how's it doing overall" you want the rollup.
Open the project's **Overview** tab and you'll see it:
- **Stat cards** across the top: **Server Requests**, **Unique IPs**, **Avg Response** (average response time),
and **Bandwidth Out**.
- A **Traffic** chart showing requests over time.
- A **Top Paths** list — the pages and endpoints getting the most hits.
This is the same request data as the Server sub-tab, just counted up. Empty at first — it fills in as traffic
arrives.
## Where to look when something is wrong
A quick map so you don't have to guess:
- **The app won't start, or it's crashing** → **Logs → Terminal**. Read the last lines; the error is almost
always right there.
- **Visitors are getting errors** → **Logs → Server**. Look for red (5xx) lines, note the path, then check the
Terminal for the matching stack trace.
- **"Is anyone even using this?"** → **Overview** analytics.
- **The deployment itself failed** (it never went live) → open that deployment from the **Deployments** tab and
read its build log — that's a separate stream from the runtime logs above.
## When monitoring cannot connect
**Connection unavailable** means Openship could not observe the affected servers. Their current
workload health is **unknown**. For example, `ENETUNREACH` means the machine running Openship has
no usable network route to the target; it does not establish that the target's apps stopped.
Monitoring combines these explicit network failures into one notice with the affected server names.
Open **Technical details** for the original diagnostic.
A timeout or refused connection to one server stays a separate **Server unreachable** notice.
Previously confirmed workload failures remain visible through either kind of connection loss.
After restoring connectivity, press **Recheck**, or let the next enabled monitoring check run.
A successful observation clears the connection notice. Checking status does not restart services.
If your browser loses its connection to Openship, a shared connection notice warns that displayed
status may be out of date. This is separate from the connection between Openship and your servers.
## CLI
Everything above is available from the CLI too. First grab your project's ID with `openship project list`, then:
```bash
# Runtime (container) logs — what your app prints
openship project logs # recent lines
openship project logs --tail 200 # last 200 lines
openship project logs -f # follow / stream live
# HTTP request logs — every web request that hit the app
openship project server-logs # recent entries (JSON)
openship project server-logs --limit 200 # up to 200 entries
openship project server-logs --domain yourapp.com # one domain only
openship project server-logs -f # stream live
# A specific deployment's build/run log (grab the id with: openship deployment list)
openship logs # snapshot
openship logs --tail 100
openship logs -f # stream until the deployment finishes
```
`openship project server-logs -f` streams live on self-hosted projects. For Openship Cloud projects the CLI
prints the recent entries instead and points you to the dashboard for the live tail — the **Server** sub-tab
there streams cloud requests fine.
The commands above read one project. To manage the reverse proxy those requests pass through — a traffic
overview and per-domain analytics, route rules, registering domains on a port, or taking over a proxy
that's already on `:80/:443` — see [The edge](/docs/guides/the-edge) guide (or the
[`openship edge`](/docs/cli/edge) command reference).
## Troubleshooting
Either the app hasn't printed anything yet, or it isn't running. Make sure the deployment is live (check the
**Deployments** tab), then press **Start**. If the project is a **static site**, there's no Terminal at all —
on Openship Cloud use the **Requests** sub-tab; a self-hosted static deploy has no runtime logs to show.
Your app started and then quit. A non-zero exit code means it crashed — read the last few lines in the
**Terminal** tab, which hold the reason. The usual suspects are a missing environment variable, a failed
database connection, or the app listening on the wrong port. Fix it and redeploy.
Request logs are recorded at the edge, so two things have to be true: your app must be receiving **real
traffic** (open its URL in a browser to generate some), and the request-logging must be in place for that
deployment. If the panel shows an error, its hint — *"make sure the server has analytics scripts deployed"* —
points at that second case.
This means the project isn't running, so there's no live stream to attach to. Confirm the deployment is up
(`openship project list` shows its status), start it if needed, then try `openship project logs -f`
again.
## Related guides
---
# Clusters and scaling through MCP
URL: https://openship.io/docs/guides/mcp-clusters-and-scaling.md
Connect servers, scale applications and databases, share files, and recover data through the existing engine workflows.
Openship's MCP tools use the same HTTP routes, authorization and engine operations as the dashboard and SDK. Fetch the `cluster-and-scale` prompt for an ordered workflow, and use `tools/list` for the exact input schemas available on your instance. The [generated catalog](/docs/api/mcp-tools) lists every tool and explains the HTTP-only routes.
## What is supported
| Capability | Current behavior |
| --- | --- |
| Private networking | Register and verify an existing provider/private network, or prepare and apply an Openship-managed WireGuard network. |
| Compute clusters | Group registered servers on a private network, with revision-checked configuration. |
| Server setup | Durable prerequisite checks, installation, joining the selected hosts, networking verification, retry and owned-runtime removal. |
| Application scaling | Set 1–100 replicas for a single application or worker, without rebuilding its image. Project-owned shared files are supported. |
| Shared files | Keep two or three independent copies, mount across servers, expand, schedule external backups and restore into a new volume. |
| Recovery | Inspect logs and observed pods, retry failed setup, redeploy or roll back retained application images, and remove resources in dependency order. |
| Managed databases | PostgreSQL replicas, Redis shards, backups, recovery and imports into new databases, plus PostgreSQL 17-to-18 upgraded copies and explicit connection replacement. |
| Policy-driven autoscaling | **Not implemented.** CPU/traffic thresholds, automatic node provisioning and a continuous autoscaling controller are not available. |
| Live worker changes | **Not implemented.** Changing cluster membership requires removing its runtime first. |
| Compose application scaling | **Not supported by this cluster application path.** Node-local bind mounts and Docker private links also require separate migration. Managed databases have their own lifecycle. |
Kubernetes can replace failed application pods inside the prepared cluster. That recovery behavior does not provision new servers or implement an Openship autoscaling policy.
## Prerequisites and workspace
Use a self-hosted or desktop Openship controller with registered SSH-accessible Linux servers. Network and runtime changes require fleet administration and access to every selected server. A grant to only one server does not authorize a cluster-wide operation. These tools are unavailable on the hosted Cloud controller; a desktop controller may still manage remote servers.
Call `get_permissions_workspaces` first. Pass the chosen `organizationId` at the top level of **every** tool call. An organization-bound credential cannot select another workspace. A private network ID, compute cluster ID, runtime ID, project ID and deployment ID identify different resources.
For source builds, configure an image repository and [registry credentials](/docs/api/credentials) that all cluster nodes can use. The build server must be able to publish images, and every node must be able to pull them.
## 1. Inspect or prepare private networking
Start with `get_system_networks_capabilities`, `get_system_servers`, `get_system_networks`, and `get_system_compute_clusters`. Reuse suitable resources already present.
For **existing private networking**, call `post_system_servers_by_id_network_inspect` for each server. Use the actual private IPs, interface names and MTU in `post_system_networks`; registering a network does not create it at the cloud provider or open provider firewalls. Verify the returned network using its current revision:
```json
{
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "post_system_networks_by_id_verify",
"arguments": {
"organizationId": "org_example",
"id": "network_from_create",
"body": { "revision": 1 }
}
}
}
```
Poll `get_system_networks_by_id` until verification settles. Check its timestamp and per-host/peer report; a previous successful report is not continuous monitoring.
For **managed WireGuard**, call `post_system_networks_preparations` with a new UUID `requestId`, a name and selected members. Poll `get_system_networks_preparations_by_preparationId`. Once it is ready, follow its `operationId` to `get_system_networks_operations_by_operationId` and inspect the generated plan, host changes, firewall requirements and `planHash`.
Call `post_system_networks_operations_by_operationId_apply` with that operation ID and the exact `planHash`. Its schema exposes the supported apply/resume/rollback action. Poll the operation until it settles; an accepted response is not a finished network. For k3s, the connection policy must allow bidirectional access between every selected member.
If preparation needs different members or permissions, use its member-removal/connection-edit tools with the current `sequence`. Follow any replacement preparation or cleanup operation returned. Reusing the same `requestId` after a lost response recovers the same intent; changing the intent requires a new request ID.
The `/api/system/clusters` routes are compatibility aliases for private networking. MCP exposes the canonical `/api/system/networks` tools once.
## 2. Create the compute cluster and install k3s
Create a compute cluster on the prepared network:
```json
{
"jsonrpc": "2.0",
"id": 2,
"method": "tools/call",
"params": {
"name": "post_system_compute_clusters",
"arguments": {
"organizationId": "org_example",
"body": {
"requestId": "123e4567-e89b-42d3-a456-426614174000",
"name": "Production apps",
"networkId": "network_from_create",
"serverIds": ["server_a", "server_b"]
}
}
}
}
```
Use the returned cluster's ID and revision to start setup:
```json
{
"jsonrpc": "2.0",
"id": 3,
"method": "tools/call",
"params": {
"name": "post_system_compute_clusters_by_id_runtime",
"arguments": {
"organizationId": "org_example",
"id": "cluster_from_create",
"body": {
"revision": 1,
"requestId": "123e4567-e89b-42d3-a456-426614174001"
}
}
}
}
```
Poll `get_system_compute_clusters_by_id_runtime`. The response includes `status`, `sequence`, `generation`, per-host steps/logs, `error` and `verifiedAt`. Continue to deployment only after `ready`. Setup verifies host identities and prerequisites before installing, then verifies node readiness, pod traffic, service routing and internal DNS.
If setup becomes `failed` or `interrupted`, inspect the saved error, fix the prerequisite, and call `post_system_compute_clusters_by_id_runtime_retry` with the **latest** `sequence`. Retry preserves the saved version and operation intent. Poll before retrying a lost response; do not start a second setup merely because the first HTTP response was interrupted.
## 3. Select the target, then deploy
Create or select a single application through the normal [deployment flow](/docs/guides/deploy-from-github). Its instances must be safe to replace on another server. Read `get_projects_by_id_cluster` for its current `updatedAt`, then select the target:
```json
{
"jsonrpc": "2.0",
"id": 4,
"method": "tools/call",
"params": {
"name": "patch_projects_by_id_cluster",
"arguments": {
"organizationId": "org_example",
"id": "project_id",
"body": {
"clusterId": "cluster_from_create",
"stateless": true,
"expectedUpdatedAt": "2026-09-26T12:00:00.000Z",
"config": {
"replicas": 1,
"imageRepository": "registry.example.com/apps/web"
}
}
}
}
}
```
Replace the example timestamp with the value just returned. Saving the target does not deploy or migrate persistent data. Start `post_deployments_build_access` with `body.projectId`. Poll `get_deployments_by_id` and read `get_deployments_by_id_logs`. If work is waiting, inspect `get_deployments_by_id_pending` and answer only a decision actually offered by the run.
After deployment, inspect `get_projects_by_id_cluster`. Confirm observed ready/available pods, not only the configured replica count. `status:null` with an `error` means the controller could not observe the workload. Check `get_projects_by_id_pending_actions` and the domain tools for separate routing or TLS blockers. A controller SSH failure does not by itself prove the public application is down.
## 4. Scale up and down
Read cluster workload state immediately before each change. Pass its `activeDeploymentId` and `updatedAt` back as preconditions:
```json
{
"jsonrpc": "2.0",
"id": 5,
"method": "tools/call",
"params": {
"name": "post_projects_by_id_cluster_scale",
"arguments": {
"organizationId": "org_example",
"id": "project_id",
"body": {
"replicas": 3,
"expectedDeploymentId": "active_deployment_id",
"expectedUpdatedAt": "2026-09-26T12:05:00.000Z"
}
}
}
}
```
The response contains a new `deploymentId`. Scaling runs a configuration deployment using the active immutable image, without a source rebuild. Poll that deployment, then verify observed replicas and application routing. To scale down, repeat the same process with a lower count; zero replicas are not accepted.
A `409` means the saved project, active deployment or another operation changed. Read the latest state and review the intended change again. Do not discard concurrency guards or continuously resend stale arguments.
## 5. Recover and clean up
| Situation | Next action |
| --- | --- |
| Network preparation/apply failed | Read saved host errors and the operation's allowed resume/rollback choice. Use its current sequence/plan hash. |
| k3s setup/removal failed | Read runtime progress, fix the reported condition and retry with its latest sequence. |
| App deploy/scale failed | Read deployment logs and pending decisions; confirm the previous active release. Redeploy or use retained-image rollback as appropriate. |
| Runtime observation failed | Fix controller-to-server connectivity and read again. Do not reset working infrastructure to clear an observation error. |
| Rollback requested | Read `get_deployments_by_id_restore_plan` first. Call `post_deployments_by_id_rollback` on the retained release, then follow the newly created rollback deployment in project history. |
| Shared-storage setup failed | Inspect the saved step and error, fix the reported condition, then retry with the current sequence. Reconnecting does not retry a mutation. |
| Remove everything | Disconnect and remove dependent applications, databases and shared volumes; remove empty shared storage, then the owned runtime, empty compute cluster and unused network. |
Runtime removal uses `delete_system_compute_clusters_by_id_runtime` with `body.sequence`; **DELETE tools can require a JSON body**. Poll until `removed`. Cluster/network deletion uses their current `revision`. Managed networking must be removed through a reviewed removal plan. Dependency checks refuse deletion when owned workloads, retained database data or foreign resources still need the runtime.
## Share files and recover archives
After server setup, use `post_system_compute_clusters_by_id_storage` with a stable
request ID, at least two independent servers and reviewed empty directories. Poll
`get_system_compute_clusters_by_id_storage` until ready. Use its current sequence
with the retry tool if setup is interrupted. Configure an external backup destination
to retain recovery points outside the cluster.
Once the project selects this cluster, create a volume through
`post_projects_by_id_cluster_volumes`. Add its name and mount path to the project's
`config.mounts` and deploy. Use `get_projects_by_id_cluster_volumes` for observed
copy and attachment health. Growing a volume uses its current `resourceVersion`;
shrinking is unsupported.
Create an external backup with `post_projects_by_id_cluster_volumes_backup`, or
schedule hourly/daily backups through `patch_projects_by_id_cluster_volumes_backups`.
Read `get_projects_by_id_cluster_volumes_backups` for completion. These archives
remain discoverable after deleting the source volume. Restore into a new volume,
check the recovered files and explicitly attach it to a new app deployment.
Disconnect and redeploy before removing a volume. Removing empty shared storage
preserves external archives. Archive deletion is a separate action requiring its
exact name. Pause application writes when a consistent file backup requires it.
## Database and backup workflows
Fetch `cluster-database` for managed PostgreSQL/Redis operations. Database replicas are independent of application replicas. Database mutations use `expectedSequence`; creation uses a stable UUID `requestId`. Connection changes save environment values, and applying them requires a separate app redeploy.
To share a ready native PostgreSQL or Redis database, open its panel and select
**Use in a project**. Choose a consumer in the same organization and native
cluster. You need write access to both projects. OpenShip saves an encrypted
connection URL and an explicit database reference, then grants the consumer's
application namespace private access to the database port. The source project
keeps ownership of the database, backups and storage.
The existing SDK, HTTP and CLI connection operations use the same flow. Read the
source's `projects.getAppConnection(sourceProjectId)` and select an output with
`sourceDatabaseId`. Pass its `id` to `projects.createConnection(targetProjectId, input)`
or `projects.connectBundle(targetProjectId, input)` with `mode: "internal"`.
The [CLI connection commands](/docs/cli/reference/project/connections) accept
the same input as JSON. Credentials stay in secret environment values; copying a
private URL without creating a connection does not grant another native project access.
If a network-policy update fails, the operation reports failure. Retry with the
same inputs to reconcile the saved grant without duplicating it. Disconnect
revokes private access before removing the reference and its environment value.
Redeploy consumers to remove old connection values from their running releases.
Kubernetes network policies do not guarantee termination of established database
sessions. Database removal is blocked while a connection or a running managed
application still references it; moving a consumer to another destination requires
disconnecting its native database links first.
PostgreSQL and Redis backups use an eligible S3 destination. Observe native backup
completion before creating a **new** database with `restoreFrom.databaseId` and
`restoreFrom.backupName`. Redis snapshots are consistent per shard, rather than a
transaction across the whole cluster. Changing Redis shard count requires a
verified recent backup and `confirmRedisRebalance: true` after reviewing the change.
`get_projects_by_id_cluster_databases_imports` lists this project's eligible existing
Docker PostgreSQL and Redis backups. Create the new database with `importFrom.runId`,
`importFrom.artifactName` and a ready `clusterId`. You can stage it while the application
still runs on Docker; later select the same cluster for the app.
For a PostgreSQL 17-to-18 upgrade, create a separate database with `copyFrom.databaseId`
and its latest `expectedSequence`. The original remains available. Verify data in
the new database before replacing the application's connection. Replacing a managed
binding needs the source ID and sequence in `replace`, as well as the destination's
current sequence. Redeploy explicitly to apply the new environment.
Pause source writes and take a fresh recovery point before the final cutover.
Writes after a backup or upgraded-copy snapshot are not copied automatically.
For ordinary project/service volume backups, fetch `backup-and-restore` and follow the [backup guide](/docs/guides/backups-restore). The complete MCP flow covers destination preflight, policies, manual runs, retention protection, restore preparation, explicit apply and status. A batch can return multiple `runIds`; every run must finish. Preparing a restore never means data has been applied.
## Validation boundaries
The scaling release gate has separate application, shared-storage and database
journeys on disposable infrastructure. The application journey drives MCP requests
through auth, the engine, an image registry, Kubernetes and OpenShip Edge. The
storage journey uses Linux/systemd/SSH hosts for installation, shared writes,
backup/restore and disk-copy rebuilding. Database tests exercise real operators,
data, replica/shard changes, recovery, Docker imports and upgraded copies.
The latest native storage and database journeys have not completed local acceptance.
Focused checks and an earlier application pass do not establish production readiness.
The fixtures also do not prove provider firewalls, every Linux distribution, real
WireGuard provisioning, ACME or production failure domains. Run the native release
jobs and infrastructure acceptance before shipping.
---
# Backups & restore
URL: https://openship.io/docs/guides/backups-restore.md
Keep safe copies of your app's data, back it up on a schedule, and roll it back when something goes wrong — from the dashboard or the terminal.
import { Step, Steps } from 'fumadocs-ui/components/steps';
A backup is just a spare copy of your data, kept somewhere else, so that if today's copy gets lost or broken
you can go back to a good one. Think of it like photocopying an important document and leaving the copy in a
safe at another address — if the original burns, you still have the copy.
Openship does two jobs here. First, it copies your data to a storage place you choose (a **destination**).
Second, it does that on a schedule you set (a **policy**) so you never have to remember. And when you need it,
it puts a copy back (a **restore**).
- Openship up and running, and a project with at least one **service** that holds data (like a database).
- Somewhere to keep the copies — an S3 bucket, an SFTP server, an existing server, or a folder on disk. We set
this up in the first step below.
## Step 1 — Add a place to keep backups
Before Openship can back anything up, it needs to know **where** to put the copies. That place is called a
destination. You add destinations once, on the **Backups** page, and every project can then use them.
### Open the Backups page
In the left sidebar, click **Backups**. If you have no destinations yet, you'll see a "No backup destinations
yet" screen with an **Add Your First Destination** button. Otherwise, press **Add Destination** in the top
right.
### Pick the kind of storage
Openship asks which type of destination this is. Pick the one that matches what you have:
- **S3-compatible** — any S3-style bucket (AWS S3, Cloudflare R2, Backblaze B2, Wasabi, MinIO).
- **SFTP** — push copies over SSH to any host, using new credentials you provide.
- **Existing server** — reuse the SSH login from a server you've already added to Openship.
- **Local disk** — write to a folder on the machine running Openship. (Not available in cloud mode.)
### Fill in the details
The fields change depending on the kind you picked. Fill in what applies:
- **Name** — a label for you, like "Production R2".
- **Endpoint** — leave empty for AWS S3. For Cloudflare R2 it looks like
`https://.r2.cloudflarestorage.com`.
- **Region**, **Bucket**, and an optional **Path prefix** (a folder inside the bucket).
- **Access key ID** and **Secret access key** — the credentials for the bucket.
- **Name**, **Host**, **Port** (default `22`), and **User**.
- An optional **Path prefix** — the folder on the remote host to write into.
- Authenticate with either a **Password** or a **Private key (PEM)** (paste the key). Leave the password blank
when you use a key.
- **Name** and the **Server** to reuse — pick one of the servers already saved under **Servers**. Openship
reuses that server's SSH credentials, so there's nothing new to enter.
- An optional **Remote path** for where to store the copies.
- **Name** and an **Absolute path** — a filesystem path on the machine running Openship, like
`/var/backups/openship`.
This kind is disabled when Openship runs in cloud mode.
Keys and passwords are **encrypted at rest** — Openship stores them scrambled, not in plain text. When you
edit a destination later, secret fields show up blank; leave them blank to keep the stored value.
Press **Save destination**.
### Check that it works
Back on the list, each destination has a **Verify connection** button (the circular arrows icon). Click it —
Openship writes a tiny test file, reads it back, and deletes it. A green **Verified** badge means the login and
address are correct. Do this now, before you rely on it.
You can mark one destination as the **default** (the star / **Set as default** action). It's a handy label for
"the one I usually use" — you still pick a destination explicitly when you create a policy.
## Step 2 — Set a backup schedule
A **policy** is the rule that says "back this up, to that destination, on this schedule, and keep this many
copies." You set policies **per service**, inside the project.
### Open the project's Backup tab
Open your project and go to the **Backup** tab. You'll see your destinations, a list of the project's
**services**, and the recent backup runs.
### Create a policy for a service
Find the service you want to protect and press **Create policy**. (If that button is greyed out, you don't have
a destination yet — hovering it shows "Add a destination first." Go back and finish Step 1.) A panel opens with
these choices:
- **Destination** — where the copies go.
- **Schedule** — pick a preset (**Hourly**, **Daily**, **Weekly**, **Monthly**, or **Manual only**), or type
your own five-field cron expression. "Manual only" means it never runs on its own — you trigger it by hand.
- **Retain count** — keep the N most recent successful backups (older ones are pruned automatically).
- **Retain days** — drop backups older than N days.
- **Pre-deploy trigger** — when ticked, Openship also backs up automatically right before each new deploy goes
live. This is your safety net for bad deploys.
- **Pre-hook / Post-hook** — optional shell commands. A pre-hook runs *before* the copy is taken (databases
often use `pg_dump` here); if it fails, the run is aborted. A post-hook runs *after* upload for cleanup.
- **Webhook trigger** *(optional, advanced)* — generates a private URL you can `POST` to from an outside
scheduler or CI so something else can kick off this backup.
Press **Create policy**.
Retention runs after each successful backup, independently for each service in a project policy.
Protected copies remain exempt. A cleanup failure keeps the affected records for retry and does
not invalidate the new backup. The **Backup retention prune** system job provides a fallback;
new installations schedule it hourly at minute 29. Existing schedules remain editable in **Jobs**.
The dashboard sets a policy **per service**. From the terminal you can also make a **project-level** policy that
covers the whole project — just leave off `--service` when you run `openship backup policy create` (see below).
## Step 3 — Run a backup now
You don't have to wait for the schedule. On the **Backup** tab, any service that has a policy shows a **Backup
now** button — press it and the copy starts immediately.
A **Live backup** card appears at the top with real-time progress. The backup itself runs on the server, so it
keeps going even if you close the tab. When it finishes, the run shows up in **Recent backups** with a green
status and its size.
## Step 4 — Protect a copy from being deleted
Retention (the "keep N copies" rule) automatically prunes old backups to save space. If you have one copy you
never want deleted — say, the last known-good state before a big change — you can **protect** it.
In **Recent backups**, each successful run has a small lock icon. Click it to **Protect from retention**; the run
gets a **Protected** badge and pruning will skip it. Click again to **Allow retention to prune** and release it.
## Step 5 — Restore a backup
Restoring puts a saved copy back in place of the current data. It's the whole point of having backups — but it
**overwrites** what's there now, so Openship walks you through it carefully.
### Start the restore
In **Recent backups**, find a successful run and click its **Restore** icon (the circular counter-clockwise
arrow). The **Restore backup** wizard opens.
### Review
The first screen shows which backup you're restoring and warns that current data will be overwritten. Leave
**Protect the latest backup from retention prune** ticked (it's on by default) — this keeps the backup you're
restoring from safe from automatic pruning, so that known-good copy stays around. Press **Continue → Prepare**.
Restoring **overwrites** the current data, and Openship does **not** take a fresh backup of the live state for
you first — the "protect" tick above only shields the backup you're restoring *from*. If you might want today's
data back, run **Backup now** (Step 3) *before* you start the restore.
### Prepare (a safe check)
Openship downloads and verifies the backup at the destination to make sure it's actually usable. Nothing
destructive happens yet — your service keeps running normally during this step.
### Confirm
Once verified, you're asked to **type the service's name exactly** to confirm. This is the "are you really
sure?" gate, because the next step permanently replaces the current data. Type the name and press **Apply
restore**.
### Apply
The service stops briefly, the data is swapped in, and it restarts. Keep the window open until it says **Restore
complete**.
## CLI
Everything above works from the CLI. The base command is `openship backup`, with four groups: `destination`,
`policy`, `run`, and `restore`.
```bash
# 1. Add a destination (S3-compatible example) and verify it
openship backup destination create \
--name "Production R2" --kind s3_compatible \
--endpoint https://.r2.cloudflarestorage.com \
--bucket my-backups --region auto \
--access-key-id --secret-access-key
openship backup destination list
openship backup destination preflight
# 2. Create a daily policy for one service, keeping 7 copies
openship backup policy create \
--project --destination \
--service --cron "0 3 * * *" \
--retain-count 7 --pre-deploy
# 3. Run it now and watch it finish
openship backup policy run --follow
# 4. See runs, and protect one from pruning
openship backup run list --project
openship backup run protect # or --release to unprotect
# 5. Restore — a two-step, on-purpose flow
# 'restore' stages it and prints a restoreId + confirmation token…
openship backup run restore
# …then apply it with that token (this is destructive)
openship backup restore apply --token --follow
```
`backup run restore` only *prepares* the restore and hands you a confirmation token — it doesn't change
anything yet. You must run `backup restore apply` with that token to actually swap the data in. This mirrors the
"type the name to confirm" gate in the dashboard.
## Troubleshooting
Click **Verify connection** and read the reason it shows. The usual causes are a wrong access key or password, a
bucket or path that doesn't exist, or a host/port that isn't reachable. Fix the field and verify again — a
destination that can't verify can't back anything up.
That service has no destination to send backups to yet. Add and verify at least one destination on the
**Backups** page first (Step 1), then come back to the project's **Backup** tab.
Open the run in **Recent backups** — a failed run shows its error message inline. If you set a **pre-hook**, a
common cause is that command failing (for example a `pg_dump` that can't connect); a failing pre-hook aborts the
whole run on purpose, so the copy is never half-made.
There's no one-click undo — a restore overwrites the data in place, and Openship doesn't auto-capture the live
state beforehand. Your safety net is a backup taken *before* the restore: if you ran **Backup now** first (or an
earlier run still holds the state you want), open that run in **Recent backups** and **Restore** from it.
## Related guides
---
# Permissions & roles
URL: https://openship.io/docs/security/permissions.md
How Openship decides who can do what — organizations, the four roles, and per-resource grants, all enforced by one permission plane.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Every request into Openship passes through one gate — the **permission plane** — that answers a single question: *is this person allowed to do this thing to this resource?* Think of it like the front desk of a building: your keycard says which floors you can reach, and the desk checks it every single time, not just once at the door.
Access is decided by three things working together: which **organization** a resource belongs to, your **role** in that organization, and — for the tightest role — the specific **grants** you've been given.
Openship refuses to boot if any API route forgets to declare a permission. There is no "unprotected by accident" route — the safe default is enforced at startup, not left to reviewers to catch.
## Organizations
An **organization** (or "org") is the container that owns everything: projects, servers, domains, backups, billing. You're a **member** of one or more orgs, and your access is decided *per organization* — being an owner of one org says nothing about your role in another.
When you make a request, Openship figures out which org you mean from the `X-Organization-Id` header (the dashboard and other API clients set this) or, as a fallback, your session's default org. Every resource carries its own `organization_id`, so the platform can always trace a project or domain back to the org that owns it and check your membership there.
## The four roles
Your role in an org sets your baseline access. From most to least powerful:
| Role | What they can do |
|---|---|
| **owner** | Everything, including **billing**. Usually the person who created the org. |
| **admin** | Everything **except billing** — including managing members and invitations, and reading the audit log. |
| **member** | Full access — read, write, **and delete** — to **all resources except billing and the audit log**. Can't manage other members. |
| **restricted** | **No access by default.** Can only reach the specific resources they're explicitly granted. |
An **owner** holds the keys to the money — plans, payment, and cancellation. An **admin** runs the day-to-day: they can invite teammates, deploy, add domains, and read the audit log, but they can't touch billing. A **member** is a trusted teammate who ships work but doesn't manage the team or see billing. **Restricted** starts with an empty keyring and gets keys one at a time.
Owner, admin, and member are graded by resource **type**, not by action: a member has read, write, **and delete** across projects, servers, deployments, domains, jobs, and environment variables — the same as an admin apart from managing people and the audit log. Per-**action** (read vs write vs admin) and per-**resource** limits are enforced only through the **restricted** role and **scoped access tokens** described below. Treat member and admin as trusted, near-equal roles, and reach for a restricted member or a scoped token whenever you need real least-privilege. Fine-grained delegation for the standard roles is still maturing.
## Permission tags: `resource:action`
Under the hood, each route declares a short tag that names a resource and an action, like `project:read` or `domain:write`. Sub-resources add a middle segment — `project:service:write` means "edit a service that lives inside a project."
The **action** is the verb, and it lines up with the HTTP method:
| Action | HTTP method | Meaning |
|---|---|---|
| `read` | `GET` (one resource) | View a single thing by id. |
| `write` | `POST` / `PUT` / `PATCH` | Create or change something. |
| `admin` | `DELETE` (and other destructive actions) | Remove, reset, or otherwise destroy it. |
| `list` | `GET` (a collection) | List things in the org — no specific id. |
You'll see these tags in the [API reference](/docs/api) next to each endpoint, so you always know which action a call performs.
## Restricted members and resource grants
A **restricted** member is the interesting one. They start with zero access. To let them do anything, an owner or admin gives them **grants** — small records that say "this person may `read` / `write` / `admin` *that* resource."
Each grant lists one or more of these levels. When Openship checks an action, a higher level also satisfies the lower ones:
- **read** — view and list the resource.
- **write** — create and change it (this also satisfies a `read` check).
- **admin** — delete and fully manage it (this also satisfies `write` and `read`).
A grant targets a resource by its id, or uses a wildcard `*` to mean *every resource of that type in the org*. So a wildcard **write** grant on Projects lets someone deploy to all of them, while a single project id keeps them to just one.
### Grants flow downhill
You grant on a top-level resource, and the access **inherits down its tree** — you don't grant each child separately:
| Grant on a… | …also covers |
|---|---|
| **Project** | its deployments, domains, services, and environment variables |
| **Backup destination** | its backup policies, runs, and restores |
| **Server** | terminal access and runtime operations (logs, restarts, start/stop) on that server |
| **Mail server** | webmail, branding, and mail settings |
### What you can grant
The resource picker offers these grantable types:
| Type | Covers |
|---|---|
| **Projects** | Apps and everything inside them (deployments, domains, env vars). |
| **Servers** | Connected machines and their runtime/terminal access. |
| **Mail servers** | Email hosting and webmail. |
| **Backup destinations** | Where backups are stored, and their runs. |
| **Billing** | Plans and payment (owner-level territory). |
| **Audit log** | The record of who did what. |
| **GitHub orgs** | Every repo under one GitHub installation. |
| **GitHub repos** | A single repository. |
The picker adapts to your instance. A **self-hosted** instance shows Servers and Mail servers; **Openship Cloud** shows Billing in their place. Projects, Backup destinations, the Audit log, and GitHub are offered on both.
## Inviting people and setting roles
Team management lives under **Settings → Team**.
### Open the invite dialog
Go to **Settings → Team** and press **Invite member**. Enter the person's email address.
### Choose a role
Pick **Member**, **Admin**, or **Restricted**. (Owner is the org creator's role — you don't hand it out from the invite dialog.)
- **Member** and **Admin** get their access immediately on joining.
- **Restricted** opens a resource picker on the right, where you choose exactly what the invite unlocks.
### Send it
Openship emails a join link. When the invitee accepts, their membership is created and any pending grants are applied. You can always widen or narrow a restricted member's grants later from their row in the team list.
## Access tokens follow the same rules
For scripts, the CLI, and AI agents, you use a **personal access token** (a revocable, per-user key sent as `Authorization: Bearer opsh_pat_...`). A token resolves to your user and org and then obeys the exact same permission model a browser session does.
Tokens can be tightened two ways:
- **Read-only** — the token rejects every mutation (`POST`/`PUT`/`PATCH`/`DELETE`).
- **Scoped** — the token carries its *own* grants and is treated as a **restricted** principal, limited to exactly those grants **even if you're an owner**. A scoped token can never do more than it was scoped for.
This is deliberate: hand a scoped, read-only token to a script or agent and the worst it can do is read the handful of resources you granted — regardless of how much power your own account has.
## Denied looks like "not found"
When you try to touch something you're not allowed to, Openship returns **404 Not Found**, not 403 Forbidden.
A 403 quietly confirms the resource *exists* — you just can't see it. A 404 gives nothing away. This protects against **IDOR** (Insecure Direct Object Reference — guessing ids to probe for resources you shouldn't know about). If a project id isn't yours, the platform behaves as if it simply isn't there.
## Related guides
---
# Authentication
URL: https://openship.io/docs/security/auth.md
How you prove who you are to Openship — session cookies, personal access tokens, MCP OAuth, and desktop loopback mode.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Every request to Openship has to answer one question first: **who are you?** Openship accepts four
different ways to answer it, and which one applies depends on *where* the request comes from — a browser
tab, a script, an AI agent, or the desktop app talking to itself. This page walks through each one.
Every API route lives under **`/api`** on your instance — e.g. `https://your-host/api/projects`. The
same authentication rules apply to all of them; there is no unauthenticated back door. Access checks
after login are covered separately in [Permission model](/docs/security/permissions).
## The four ways in
| Method | What you send | When it applies |
|---|---|---|
| **Session cookie** | An httpOnly cookie the browser holds for you | The dashboard, in a normal browser |
| **Personal access token (PAT)** | `Authorization: Bearer opsh_pat_…` | The CLI, scripts, server-to-server, and MCP clients without OAuth |
| **MCP OAuth** | An OAuth 2.1 access token the client fetches for you | AI agents (Claude, Cursor, …) connecting to `/api/mcp` |
| **Zero-auth loopback** | Nothing — the request just comes from `127.0.0.1` | The desktop app, or a local single-user instance you opt into |
A single request uses exactly one of these. Openship checks for a `Bearer` token first; if there isn't
one, it looks for a session cookie; if there's neither, it falls back to the loopback path (and only if
that mode is turned on).
## Session cookies (the dashboard)
When you log in to the dashboard, Openship gives your browser a **signed, httpOnly session cookie**.
"httpOnly" means JavaScript running in the page cannot read it — so even if a bad script somehow ran on
the page, it couldn't steal your session. The browser sends the cookie automatically on every request;
you never handle it yourself.
The cookie name is prefixed with your instance mode — `openship.session_token` on a self-hosted install,
`openship-cloud.session_token` on Openship Cloud.
### Passkeys
On Openship Cloud or a self-hosted instance with local accounts, open **Settings → Security → Passkeys**
after signing in. Add a passkey using Face ID, Touch ID, Windows Hello, a password manager, or a
compatible hardware security key. Registration requires a recent session and a discoverable credential
so the login page can find it without a username. The private key stays with your authenticator;
Openship stores the public WebAuthn credential.
Choose **Sign in with a passkey** on the login page. If you enabled two-factor authentication, complete
that step before a session is issued. You can remove saved passkeys from Settings even in a browser
that cannot create them. Keep another sign-in method available before removing your last passkey.
Passkeys require HTTPS, except on localhost. They bind to the configured **dashboard** hostname and
browser origin, independently of the API host. Self-hosted public instances use `OPENSHIP_PUBLIC_URL`;
Cloud uses its dashboard runtime URL. Keep the hostname stable: moving to another domain requires
registering a passkey there. Use your password or social login to do that.
### Two-factor authentication
Open **Settings → Security → Two-factor authentication** on Openship Cloud or a self-hosted instance
using `OPENSHIP_AUTH_MODE=local` (including a VPS). No email delivery or additional provider is needed
for authenticator codes.
1. Choose **Set up 2FA** and confirm your current password. If you have only used social login, first
choose **Add password**; this requires a recent signed-in session and does not replace social login.
2. Scan the QR code with an authenticator app, or enter the setup key manually.
3. Enter the app's six-digit code. Protection starts only after this verification succeeds.
4. Copy or download your recovery codes and store them somewhere safe. Each code works once.
When 2FA is enabled, password, social, and passkey sign-in all require an authenticator or recovery
code before creating a usable session. Pending challenges expire after ten minutes. Browser handoffs,
invitations, and MCP authorization continue after verification. Password resets do not disable 2FA.
Use **Recovery codes** to replace your codes, or **Turn off 2FA** to disable protection; both require
your password. Replacing codes invalidates the old set. An enabled authenticator cannot be overwritten
by starting setup again: disable it explicitly first. Keep your authenticator or a recovery code
available; an email password reset is not a way to bypass the second factor.
These controls do not apply to account-free local mode. Instances that delegate sign-in to Openship
Cloud manage account security on Cloud rather than storing a separate local factor.
Authentication tables are added automatically during the normal database upgrade. Back up and retain
your installation's `BETTER_AUTH_SECRET`, which encrypts authenticator secrets and recovery codes.
An instance transfer must include credentials to preserve accounts with 2FA enabled; the destination
re-encrypts them with its own key. An incomplete factor restore is rejected before changing data.
Project-only transfers do not move account credentials.
If a request arrives with a `Bearer` header **and** an `Origin` matching one of the dashboard's trusted
browser origins, Openship rejects it (`401 BEARER_NOT_ALLOWED_FROM_BROWSER`). Bearer tokens are for
CLIs and servers; a token showing up from a browser tab is the signature of a stolen credential being
replayed, so the door is closed. The CLI sends no `Origin` header at all, which is why its tokens are
accepted.
## Personal access tokens (Bearer)
A **personal access token** (PAT) is a long string you send in the `Authorization` header to prove who
you are without a browser:
```
Authorization: Bearer opsh_pat_…
```
Every token looks like `opsh_pat_` followed by a 43-character random secret (256 bits of entropy).
Openship stores **only a SHA-256 hash** of it — the plaintext is shown to you exactly once, at creation,
and can never be retrieved again. A token always **acts as the person who created it** and carries that
person's role, unless you narrow it (see below).
### Create one
In the dashboard, open **Settings → Tokens** and use the **Personal Access Tokens** section. Copy the
token when it appears — that's the only time you'll see it.
From the terminal:
```bash
# A full-access token that acts as you
openship token create "my laptop"
# A read-only token that expires in 90 days
openship token create "ci-readonly" --read-only --expires 90
# A token scoped to one project (read + write only on that project)
openship token create "deploy-bot" --grant project:proj_123:read,write
openship token list # your tokens (never shows secrets)
openship token revoke
```
`openship login` stores a token so the CLI can send it on every call. Run it with `--token opsh_pat_…`
for a non-interactive login (handy in CI), or run it bare to open the token settings page and paste one in.
The stored token is only ever sent as a `Bearer` header — never as a cookie.
The request body behind the create call:
### Two ways to narrow a token
- **Read-only** — the token can call read endpoints but any mutating request is refused with
`403 TOKEN_READ_ONLY`. Great for dashboards, monitoring, and CI that only needs to look.
- **Scoped** — instead of acting with your full role, the token is confined to a specific list of
resources you grant it (a project, a server, a repository, …), each with `read`, `write`, or `admin`.
A scoped token acts as a **restricted principal**: it can do *less* than you, never more. You can only
grant access you already hold yourself — the server checks this before minting.
Each token is bound to the organization it was created in. If a request carries an `X-Organization-Id`
header naming a different org, it's rejected with `403 TOKEN_ORG_SCOPE`. An invalid or revoked token
returns `401 INVALID_TOKEN`.
## MCP OAuth (AI agents)
Openship is a standards-compliant **OAuth 2.1** server for the **Model Context Protocol (MCP)** — the
way AI agents call tools. An MCP-capable client (Claude, Cursor, …) points at `POST /api/mcp`, and the
handshake is automatic: the first unauthenticated request returns a `401` pointing at
`/.well-known/oauth-protected-resource`, the client registers itself, runs the **PKCE** authorize flow
(Proof Key for Code Exchange — a way to complete OAuth safely without a stored client secret), and you
approve it on a **consent screen** in your browser.
That consent screen is where you set the agent's limits — **read-only** and/or a specific set of
projects, servers, and repositories. Your choices are saved as the client's binding and enforced through
the exact same grant model as a scoped PAT. An OAuth token that somehow skips consent has **no binding,
and is therefore denied everything** — there is no "authenticated but unscoped" state.
You manage connected agents under **Settings → MCP**, where you can see each client and disconnect it
(which revokes its tokens immediately). Clients without OAuth support can instead authenticate with a
plain PAT as a bearer credential.
Endpoint URLs, client config snippets, and verification steps live on the [MCP page](/docs/mcp).
## Desktop / zero-auth loopback mode
The desktop app runs an API and a dashboard on your own machine, just for you. Forcing a login there
would be pointless friction, so it uses **zero-auth mode**: the API auto-provisions a single local admin
user (`Local User`, owner of a personal workspace) and treats local traffic as that user. No password,
no cookie to manage.
This is safe only because it is gated twice, and both gates must pass:
1. **Not CLI-managed or public.** Zero-auth is for the **desktop app only**. An instance started from the
CLI (`openship up` sets `OPENSHIP_REQUIRE_AUTH`) or served publicly (`--public-url` /
`OPENSHIP_PUBLIC_URL`) refuses zero-auth outright — it always requires a login.
2. **Opt-in.** The instance's auth mode must be `none`. This is the default for the desktop app; on any
other deployment it also requires the operator to set `OPENSHIP_ALLOW_ZERO_AUTH=true`.
3. **Loopback only.** The request must come from a loopback address (`127.0.0.1` / `::1`), read from the
kernel-reported TCP peer — **not** the `Host` header, which a client or a misconfigured reverse proxy
could forge. A request from anywhere else is rejected with `401`, even in zero-auth mode.
With `--public-url`, the dashboard's same-origin proxy runs **on the box**, so it reaches the API from
loopback — which would otherwise slip past the loopback gate (condition 3). The explicit CLI/public refusal
closes that hole, so a remote visitor can never land on the zero-auth path.
On a normal self-hosted install this path is never even reached: the auth mode defaults to `local`, so a
missing session is a plain `401`. Turning it on is a deliberate operator choice — auth mode `none` **and**
`OPENSHIP_ALLOW_ZERO_AUTH=true` — and even then the loopback check keeps it usable only from the machine
itself. A request arriving through a network reverse proxy carries the proxy's address as its TCP peer,
not loopback, so it is refused.
Openship recognizes three auth modes overall:
- **`none`** — zero-auth loopback, described above. Default for the desktop app only; never used by a
CLI-started or public instance.
- **`local`** — standard login required (email + password, configured OAuth, or a registered passkey via
[Better Auth](https://www.better-auth.com/)). Default for a fresh self-hosted install, and always used
for CLI (`openship up`) and public instances.
- **`cloud`** — the desktop app signs in with an Openship Cloud account instead of a local one.
A CLI or self-hosted instance has no public sign-up. The first admin (email + password) is created during the
`openship` guided setup, over an internal-token-gated, one-shot endpoint that a browser can't reach. After
that, add more users from **Settings → Team** in the dashboard.
If the session machinery itself errors (a database outage, a decryption failure), the request returns
`503 AUTH_UNAVAILABLE`. It does **not** quietly drop to the zero-auth path — a broken session check can
never be mistaken for "no login required."
## Cloud sign-in
Choosing **Continue with Cloud** (or connecting a self-hosted instance to Openship Cloud) runs a PKCE
handshake that mints a **cloud session** for the connecting owner. That session is stored **encrypted,
server-side only** — the browser never sees it — and org-scoped cloud calls act on the owner's behalf
through it. How that boundary is kept clean is covered in
[The local ↔ cloud boundary](/docs/security/cloud-boundary).
## Where credentials live
Openship keeps secrets where they're safest instead of copying them around:
- **PAT secrets** are stored only as a SHA-256 hash; the plaintext exists just once, in your clipboard.
- **Cloud sessions** are encrypted at rest on the instance and never exposed to the browser.
- The managed **Openship GitHub App private key** lives only on Openship Cloud. A self-hosted workspace may
instead register one or more Apps in Settings; each private key, client secret, and webhook secret is
stored in a versioned AES-256-GCM envelope and is never returned by the API. The legacy process-environment
configuration remains supported. Every App path mints short-lived, repository-scoped installation tokens.
- Per-project git tokens and environment secrets are encrypted at rest.
## Revocation
- **A token:** `openship token revoke `, or the **Revoke** button in Settings → Tokens. It stops
working on its next request.
- **An MCP client:** disconnect it under Settings → MCP — its issued tokens are revoked and the consent
is dropped, so reconnecting re-prompts.
- **A person:** removing a member ends their access; their session stops working on its next check.
- **A cloud link:** disconnecting an instance revokes its cloud session.
## Errors you might see
| Status & code | Meaning |
|---|---|
| `401 INVALID_TOKEN` | The bearer token is wrong, expired, or revoked. |
| `401 BEARER_NOT_ALLOWED_FROM_BROWSER` | A bearer token arrived from a dashboard browser origin — send it from a CLI/server instead. |
| `403 TOKEN_READ_ONLY` | A read-only token tried a mutating request. |
| `403 TOKEN_ORG_SCOPE` | The token is bound to a different organization than the one requested. |
| `401 Unauthorized` | No valid session, or a zero-auth request that failed the mode/loopback gates. |
| `503 AUTH_UNAVAILABLE` | The session check itself failed — retry; it never silently downgrades to no-auth. |
## Related guides
---
# Cloud boundary
URL: https://openship.io/docs/security/cloud-boundary.md
How a self-hosted instance talks to Openship Cloud without leaking local identity — proxied requests carry the owner's cloud session and nothing else.
When you connect the copy of Openship you run yourself to Openship Cloud, the two
stay cleanly separated. Think of it like a border crossing between two countries:
your instance is one side, the Cloud is the other, and every request that crosses
shows a single passport — the organization owner's cloud session — and carries
nothing from home. No local ID cards, no house keys, no return address.
- **Self-hosted instance** — the Openship you run on your own machine or server.
It is the single **control plane** and **permission plane**: the layer that
decides who may do what. Every request is checked here first.
- **Openship Cloud** — the hosted service at `https://api.openship.io`. It is the
**upstream authority** (the final say) for any project that lives on the Cloud.
- **Proxy** — when a request is for a Cloud-owned project, your instance *forwards*
it upstream instead of answering itself. That forwarding step is the boundary,
and it is where all the rules below apply.
## One gateway, one identity
All Cloud-project traffic goes through **one** place in the code and travels as the
organization owner's cloud session. Only requests that first pass your local
permission checks ever reach the Cloud — the proxy runs *after* the permission
gate, so there is no back door to the Cloud that skips local access control.
Who is the "owner"? Only the org owner can link a Cloud account (linking is guarded
by an owner-role check), and their session becomes the org's single cloud identity.
Every member's cloud action — deploy, analytics, domains, GitHub — runs under that
one identity, resolved the same way everywhere, so the dashboard and the deploy path
can never disagree about who is acting.
Proxying does not make a request invisible at home. The forwarding step runs *inside*
your local permission middleware, so the same local audit entry is written for a
proxied Cloud action as for a local one — your instance still records who did what,
even though the Cloud carries it out.
## What crosses the boundary — and what never does
When your instance proxies a request upstream, it rebuilds the request from
scratch. It forwards only:
- the HTTP **method** (`GET`, `POST`, …),
- the **path** and query string,
- the request **body** (for writes),
- the **Content-Type** header,
- an **Authorization** header holding the owner's cloud session token (added by
the transport layer, never taken from the incoming request).
Everything else is dropped on purpose. In particular, the proxy forwards **none**
of these:
| Never forwarded | Why |
|---|---|
| Local session cookies | Browser sign-in is local-only; the Cloud never sees it. |
| `X-Organization-Id` | The Cloud resolves the org from the owner's token, not a header. A local org id is meaningless upstream (local org id ≠ Cloud org id) and would be a footgun. |
| `X-Project-Source` and other client hints | Routing hints stay local. |
| `Host` / the original origin | The request is re-addressed to `api.openship.io`. |
A proxied request forwards **only method, path, body, and Content-Type**, plus the
owner's cloud bearer token. No local session, no local organization id, and no
local host ever cross. This rule is written down and enforced in the single proxy
module — the one place that forwards an inbound request to the Cloud backend.
## Your local id can't be smuggled upstream
Because `X-Organization-Id` is stripped, a caller cannot hand the Cloud a local
identifier and have it act on some other org's data. The Cloud works out which
organization a request belongs to entirely from the owner's bearer token: it looks
the token up in its own session table and derives the user — and therefore the org
— from that trusted server-side record. There is no field in a proxied request
that a local bug, or a local attacker, could set to point at someone else's cloud
data.
## No hybrids
- **A Cloud project has no local row.** Your instance keeps zero database records
for it; for a cloud project it is only ever a gateway. So a local bug or a botched
migration can't reach into Cloud-owned data — there is nothing local to corrupt.
- **A local (or server) project never runs on Cloud compute.** The two worlds do
not share execution.
- **Same 404 for a stranger's id.** Ask for a cloud project id that your org has no
link to, and you get the exact same "not found" as asking for a completely
foreign id — your instance won't even reveal that it exists. This closes an
**IDOR** (insecure direct object reference — guessing another tenant's id to read
their data).
## The stored credential
The only cloud secret your instance keeps is the owner's cloud session token. It is:
- **Encrypted at rest** — stored as AES-256-GCM (authenticated encryption)
ciphertext in the owner's settings row, and decrypted only server-side at the
moment of an outbound call.
- **Never exposed to the browser** — the dashboard never receives the token. It
lives server-side and is presented as a bearer only on the call that leaves your
instance. No client-side cookie or token is involved in cloud traffic at all.
- **Checked live** — "connected?" is answered by asking the Cloud, not by the token
merely existing on disk. A token the Cloud rejects with `401` on its identity
endpoint is cleared automatically; a transient `5xx` is not treated as a
disconnect.
On the Cloud side, linked-instance sessions can be **pinned** to the IP address and
User-Agent recorded when the session was created, using the `CLOUD_SESSION_PINNING`
setting. The default is `warn` — a mismatch is logged but the request is still
allowed; `off` skips the check entirely; `strict` rejects the request with `401` on
a mismatch. Strict mode catches a stolen token replayed from a different network or
client, at the cost of breaking users who switch carriers or VPNs.
## Related guides
---
# Isolation
URL: https://openship.io/docs/security/isolation.md
How Openship keeps deployments and projects apart — separate containers, per-project networks and volumes, and enforced resource limits.
Think of your Openship server like an apartment building. Every app you deploy gets its own unit: its own front door, its own electricity meter, its own mailbox. Neighbors can't wander into your unit, and one noisy tenant can't drain the whole building's power. This page explains the walls Openship puts up between your apps — what each one is, and how strong it is on each runtime.
## Scoping comes first
Before anything runs, access is decided by **organization** (a workspace that owns projects) and **project**. Every API request passes through one permission check, and an organization id from the client is only trusted if you're actually a member. So one team can never list, deploy, or tear down another team's projects. That control-plane boundary is covered in the [permission model](/docs/security/permissions); the rest of this page is about the walls between apps *at runtime*, once a deploy is live.
Everything Openship creates on a host is stamped with the project and deployment it belongs to, using Docker **labels** (key/value tags attached to a container):
- `openship.project` — which project owns it.
- `openship.deployment` — which specific deploy created it.
- `openship.service` — which service, for multi-service (compose) projects.
- `openship.build` — which build session produced a build image, so half-finished build artifacts can be reclaimed too.
These labels are how Openship reliably finds and cleans up only its own resources — for example, reclaiming a leftover container from a deploy that failed halfway, without touching anything else on the machine.
## One container per deployment
On the **Docker** runtime, each deployment runs inside its own **container** — a sandboxed box with its own filesystem, processes, and network view, isolated from the host and from other containers by the Linux kernel. Containers are named predictably so two never collide:
| What | Name pattern |
|---|---|
| Single-app deployment | `openship--` |
| A service in a compose project | `openship--` |
| Project network | `openship-` |
| Project-scoped named volume | `openship--` |
A single-app container publishes on a **random host port**, and Openship's built-in router (**OpenResty**, an nginx-based reverse proxy) forwards traffic to it — so nothing is exposed on a predictable port that another app could clash with.
## Per-project networks
For a project with multiple services (say a web app plus a database), Openship creates one private **bridge network** — a virtual LAN that only the containers attached to it can use — named `openship-`. Every service in that project joins it and can reach the others by service name, like `http://database:5432`.
Because each project gets its **own** network, a service in one project cannot address a service in another by name. And a service only opens a port to the outside world if it explicitly asks to — otherwise it's reachable only by its siblings inside the project network.
Two different projects can both have a service called `api` or `db` without any conflict — each name resolves only inside its own project's network.
## Per-project volumes
A **named volume** is a managed disk that Docker keeps around between restarts (databases use them so data survives a redeploy). The catch: if two projects both ask for a volume literally named `postgres_data`, plain Docker hands them the *same* disk — silent cross-project data mixing.
Openship prevents this by prefixing every named volume with the project: `openship--`. Two projects that both declare `postgres_data` get two separate disks that can never touch. Bind mounts (a specific host path you chose) and anonymous volumes are left exactly as written.
Services created before volume-scoping keep their original bare volume names. To protect them, Openship refuses to deploy a **new** project whose volume name is already in use by another project's container, and tells you to rename it — so no deploy can quietly adopt another project's data.
## Resource limits
Each deployment is given a budget so one app can't starve the others. A budget has three parts:
- **CPU** (`cpuCores`) — fractional cores, e.g. `0.5`, `1`, `2`.
- **Memory** (`memoryMb`) — a hard ceiling in megabytes.
- **Disk** (`diskMb`) — writable disk in megabytes.
Self-hosted projects are unlimited by default; explicit limits are bounded by the target
machine. Cloud requires a concrete allocation within the organization's purchased terms
and Oblien's effective limits. Resource presets include fractional CPU, down to 0.25 vCPU.
On Openship Cloud, builds use available CPU/RAM from the same pool as runtime, optionally
bounded by a saved build cap. Existing runtime allocations remain reserved. Build workers
are removed and temporary CPU/RAM is reconciled after the operation; a failed or pending
provider resize is not reported as released capacity. See [resource settings](/docs/guides/sleep-mode-resources).
For Docker containers, a configured memory limit is a hard cap; exceeding it can cause
an out-of-memory kill. Configured CPU limits use Docker CPU quotas, so an idle host does
not let a capped container exceed its assigned CPU budget. Cloud Docker builds enforce
their selected limits on a separate BuildKit worker container within the project workspace.
## How the runtimes compare
Openship can run your app three ways, and the isolation strength differs. Pick the tab that matches where you deploy.
The strongest isolation. Every deployment is its own container with:
- kernel-level separation from the host and other apps,
- a hard **memory** cap and a **CPU** weight, and
- a random published port fronted by the router — never a fixed port another app could grab.
Multi-service (compose) projects add a **private per-project network** and **project-scoped named volumes** on top of that. This is the recommended runtime whenever Docker is available.
For hosts without Docker, Openship runs your app **directly as a process** on the machine, supervised by systemd (Linux) or a lightweight `nohup` fallback (macOS). Each deployment gets its own release directory and its own supervised process (on Linux, a dedicated systemd unit named `openship-.service`).
This is lighter, but the walls are thinner: processes **share the host's filesystem, network, and users**, and this mode does **not** enforce CPU or memory caps. systemd additionally gives you automatic restart-on-crash and reboot survival; the `nohup` fallback does not.
Because bare processes share the host and aren't resource-capped, run only apps you trust on a shared bare host, and prefer the Docker runtime for anything multi-tenant.
On Openship Cloud, each deployment runs in its own isolated cloud **workspace** — a separate instance, not a shared box. You choose a size tier that maps to concrete CPU / memory / disk:
| Tier | CPU | Memory | Disk |
|---|---|---|---|
| micro | 0.25 | 256 MB | 4 GB |
| low | 0.5 | 512 MB | 8 GB |
| medium | 1 | 1 GB | 16 GB |
| high | 2 | 2 GB | 32 GB |
A **custom** tier lets you set exact values. See [the local ↔ cloud boundary](/docs/security/cloud-boundary) for how cloud and self-hosted stay separated.
## Related guides
---
# Architecture overview
URL: https://openship.io/docs/architecture/overview.md
A high-level map of how Openship fits together — the interfaces you drive, the API that runs everything, the platform adapters, and the shared packages.
Openship is one codebase that plays several parts. Think of it like a restaurant: there's the counter where you place an order (the things you click and type), the kitchen that actually cooks (the API), and the appliances the kitchen uses to do the work (the platform layer). This page is the map. The other architecture pages zoom into one area each.
Here's the whole thing on one screen:
```
You drive Openship three ways
┌───────────┐ ┌───────────┐ ┌───────────┐
│ Dashboard │ │ CLI │ │ Desktop │
│ (Next.js) │ │ (openship)│ │ (Electron)│
└─────┬─────┘ └─────┬─────┘ └─────┬─────┘
└───────────────┼───────────────┘
│ HTTP, under /api/*
┌─────▼─────┐
│ API │ the control plane
│ (Hono) │ projects · deployments · domains · env · auth
└─────┬─────┘
│ getPlatform()
┌─────▼──────┐
│ Adapters │ runtime · routing · SSL · system checks
└─────┬──────┘
┌──────────┼──────────┐
┌────▼───┐ ┌───▼────┐ ┌──▼──────┐
│ local │ │ server │ │ cloud │ where your app ends up
└────────┘ └────────┘ └─────────┘
```
## The control plane: the API
The **API** is the brain. It's a [Hono](https://hono.dev) app (a small, fast web framework) that owns everything that matters — projects, deployments, domains, environment variables, backups, and the permission model — and it stores that data in a database (see [Data ownership](/docs/architecture/data-ownership)).
Everything else in the picture is a way to *talk to* this API, or a tool the API *uses*. Nothing writes to the database directly except the API, and every piece of the UI reaches it over plain HTTP under `/api/*`. That single front door is why the dashboard, the CLI, and the desktop app always agree with each other: they're all reading and writing the same source.
The API accepts a browser session cookie (from the dashboard) or a bearer token (from the CLI and scripts). Same endpoints, same rules, whichever you use. See the [API overview](/docs/api) for the auth model.
## The three ways you drive it
All three interfaces are thin — they render screens and send requests. The real work happens behind the API.
- **Dashboard** — a [Next.js](https://nextjs.org) web app. This is the full graphical UI, built for teams, and what you see in most screenshots in these docs.
- **CLI** — the `openship` command you install from npm. It wears two hats: `openship up` can stand up a whole self-hosted instance on your machine — it bundles the API and fetches the dashboard for you — while everyday commands like `openship deploy` are a thin HTTP client that calls the same API endpoints the dashboard does. Great for self-hosting, scripting, and CI.
- **Desktop app** — an [Electron](https://www.electronjs.org) wrapper that shows the same dashboard and runs its own local copy of the API on your machine (only while it's open). You manage everything from a laptop with no always-on server; deploys go out to a server you connect over SSH, or to Openship Cloud.
Because they share the API, you can start a deploy in the dashboard and check on it from the CLI — it's one system, not three.
## The platform layer: adapters
When the API needs to *do* something to the outside world — build an image, start a container, wire up a domain, get an SSL certificate — it doesn't do it directly. It asks the **platform layer** (the `@repo/adapters` package). This is the "appliances" in the kitchen analogy, and it has three parts behind a single entry point:
- **Runtime** — builds and runs your app. There are three runtimes: **Docker** (your app runs in a container), **Bare** (your app runs as a plain process, lighter for small machines and the desktop), and **Cloud** (the work is handed off to Openship Cloud).
- **Infra** — routing and certificates. On self-hosted instances this is an OpenResty edge (an nginx-based server) for routing plus certbot for automatic Let's Encrypt HTTPS; in the Docker/Compose install the edge runs as a container on :80/:443 that the API drives. On cloud, Openship Cloud's edge handles it.
- **System** — prerequisite checks and setup (is Docker installed? is git present?). Self-hosted only.
At startup the API picks the right combination of these once, and the rest of the code just calls `getPlatform()`. For the full story of how a deploy resolves to a concrete runtime, see [Runtime model](/docs/architecture/runtime-model).
## Where an app ends up
A project deploys to one of three targets, and the platform layer above is what makes each one work:
- **local** — the instance's own machine.
- **server** — a server you've connected over SSH.
- **cloud** — Openship Cloud compute.
The target is chosen once per deploy and snapshotted, so the build, the routing, and any later rollback can never disagree about where the app lives.
## Shared packages
Openship is a monorepo. Common logic lives in `@repo/*` packages that every app reuses, so there's one implementation of each thing rather than four copies that drift apart.
| Package | What it holds |
|---|---|
| `@repo/core` | Pure shared logic — types, stack detection, constants, error classes. No side effects. |
| `@repo/db` | All database access, via [Drizzle ORM](https://orm.drizzle.team) over Postgres (or an embedded PGlite for zero-setup installs). Every query goes through typed repositories. |
| `@repo/adapters` | The platform layer described above: runtime, infra, and system. |
| `@repo/ui` | The shared React component library used by the dashboard and the marketing/docs site. |
| `@repo/onboarding` | The setup and first-run flow shared by the CLI, dashboard, and desktop. |
## One codebase, three roles
The same code runs as **Openship Cloud** (the managed SaaS), as a **self-hosted** instance on your own server, or as the **desktop** app. Configuration at startup decides which role an instance plays and which runtime it uses (for self-hosted, `DEPLOY_MODE=docker` or `bare`). Nothing is forked — the cloud and the version you self-host are literally the same source.
The one thing that changes with the role is *where data is canonical*. Local and server projects live entirely in your own instance's database; cloud projects are owned by Openship Cloud and your instance acts as a gateway in front of them. That split is the subject of the next two pages.
## Related guides
---
# Modules overview
URL: https://openship.io/docs/architecture/modules-overview.md
A tour of the backend modules that make up the Openship API — what each one owns, grouped by job, with a link to its reference page.
The API from the [architecture overview](/docs/architecture/overview) isn't one giant blob of code. It's split into **modules** — think of them as the departments of a company. Each department owns one area (projects, domains, backups…), and each is mounted at its own address under `/api`. Ask about domains? You talk to the domains department at `/api/domains`. Ask about backups? A different department, a different address.
Almost every request runs through the same front desk first: it's authenticated, and each route carries a **permission tag** (like `domain:write`) that says who's allowed to do it — so the rules are identical no matter which module you reach. A few doors are deliberately public: the [health](/docs/api/health) check is open, and incoming [webhooks](/docs/api/webhooks) prove who they are with a signature instead of a login.
Here you get one or two sentences per module — enough to know which door to knock on. Each module links to its own reference page with the exact endpoints, fields, and examples. Start with the [API overview](/docs/api) for the shared auth model.
## Building and shipping
The core pipeline: turn your code into a running app.
| Module | What it owns |
|---|---|
| [projects](/docs/api/projects) | The heart of everything. A **project** is one app Openship manages — its source (a GitHub repo, an uploaded folder, or a local path), its environment variables, its resource limits, and its settings. This module creates and configures them. |
| [deployments](/docs/api/deployments) | One **deployment** is a single attempt to build and run a project's current code. Starts a build, streams its logs, and handles what comes after: redeploy, rollback, restart, and cancel. |
| [services](/docs/api/services) | When a project has more than one moving part (a Docker Compose stack or a monorepo), each running piece is a **service**. Manage, start, stop, and configure each one on its own. Mounted under `/api/projects/:id/services`. |
| [images](/docs/api/images) | A searchable catalog of ready-made container images (databases, tools) you can drop into a project, sourced from the Openship Cloud image catalog. |
## Traffic and source
How your app is reached, and where its code comes from.
| Module | What it owns |
|---|---|
| [domains](/docs/api/domains) | Attaches web addresses to a project, previews and verifies the DNS records they need, and manages the HTTPS certificate. |
| [github](/docs/api/github) | Connects your GitHub account and lists your repositories, branches, and files so Openship can deploy from them. |
| [webhooks](/docs/api/webhooks) | The single inbound door for events from outside — a GitHub push (which can trigger a redeploy) or a Stripe billing event. It checks each event's signature instead of requiring a login. |
## Watching and staying informed
Knowing what your apps are doing, and hearing about it.
| Module | What it owns |
|---|---|
| [analytics](/docs/api/analytics) | Traffic and deployment statistics — request counts, status codes, top paths, deploy frequency and success rate — for the whole org or a single project. |
| [health](/docs/api/health) | A tiny, unauthenticated endpoint that reports the instance is alive and which version it's running. Used by load balancers and Docker health checks. |
| [notifications](/docs/api/notifications) | Where alerts come from and go to: the event categories, the channels you deliver on (email, webhook, Slack, in-app), and your per-event subscriptions. |
## People, access, and security
Who can do what, and a record of what they did.
| Module | What it owns |
|---|---|
| [permissions](/docs/api/permissions) | Team management and fine-grained access — who is in the organization, and exactly which resources each member may read or change (called **grants**). |
| [settings](/docs/api/settings) | Your organization's workspace preferences (build mode, deploy defaults) that sync across your devices. |
| [tokens](/docs/api/tokens) | **Personal access tokens** — the bearer keys the CLI and scripts use to talk to the API — plus the list of connected MCP clients. |
| [audit](/docs/api/audit) | A read-only log of who did what: every meaningful action, filterable by actor, event type, or resource. |
| [mcp](/docs/api/mcp) | A **Model Context Protocol** endpoint (MCP is a standard way for AI assistants to call tools). It exposes Openship's actions to agents — a client connects over OAuth or with a personal access token — and every call is gated by the very same permissions. |
## Cloud and billing
The managed-hosting option and what it costs.
| Module | What it owns |
|---|---|
| [cloud](/docs/api/cloud) | Links a self-hosted instance to Openship Cloud (connect, disconnect, list cloud workspaces) and, on the SaaS side, handles the sign-in handoff between the two. |
| [billing](/docs/api/billing) | Plans, subscriptions, and usage. The public plan list runs on every instance; Stripe-backed subscription management runs on Openship Cloud, and a self-hosted instance proxies to it. |
## Data protection
| Module | What it owns |
|---|---|
| [backups](/docs/api/backups) | Scheduled and on-demand backups of your projects' data — the schedules (**policies**), the individual backup **runs**, and **restoring** from them. |
## Self-hosted machinery
These modules only exist on a self-hosted instance — on Openship Cloud they're never loaded.
| Module | What it owns |
|---|---|
| [system](/docs/api/system) | The plumbing behind a self-managed instance: browsing the host filesystem, first-run setup, and connecting and managing your own servers over SSH (including installing the pieces each server needs). |
| [terminal](/docs/api/terminal) | An interactive shell into one of your connected servers over SSH, streamed live to the browser. |
| [mail](/docs/api/mail) | A wizard that installs and manages a full (iRedMail-based) mail server on one of your servers. |
## Related guides
---
# Cloud as source
URL: https://openship.io/docs/architecture/cloud-as-source.md
Cloud projects are owned by Openship Cloud; your self-hosted instance is a gateway in front of it — plus how projects promote up and come back home.
For a **Cloud-owned project**, Openship Cloud (our hosted service) holds the one true copy — the
**canonical** owner. Its record, deployments, domains, environment variables, and logs all live on the
cloud, and the cloud runs its builds and lifecycle. Your self-hosted instance keeps **no local copy** of
that project. Instead it acts as a **gateway** — a thin pass-through that forwards requests for that project
up to the cloud and hands you back the answer.
Think of it like a mailbox on your street. The letters aren't stored in the mailbox; the mailbox just
carries them to and from the real post office. Your instance is the mailbox; Openship Cloud is the post
office.
A project lives in **exactly one place** — fully local, or fully on the cloud. Never half in each. That is
the whole idea behind this page.
## A gateway, not a mirror
Openship deliberately never keeps two copies of the same project. A mirror would mean two sources of truth
that constantly drift apart and need reconciling — and a bug on your box could corrupt cloud data. A gateway
avoids all of that: there is nothing to sync, because there is only ever one copy.
Your dashboard can keep talking to your local API. Requests for a Cloud project are forwarded
upstream and returned through the gateway. SDK and CLI credentials fixed to an organization
must connect directly to that organization's API; a local scoped credential cannot borrow
its owner's Cloud session.
### Creating a project from Desktop
In the connected dashboard, selecting a managed Cloud server for a new catalog app or
Git project creates its configuration through the Cloud API. Capacity checks, installation
and subsequent project operations use that Cloud account and organization. The project,
services and routes are stored in Cloud; the desktop controller keeps no project copy.
An existing verified server link is translated to its canonical Cloud server ID.
Local folders, upload sessions and custom app definitions uploaded to this instance keep
their local controller because their source is available there. Existing local projects retain
their owner, even when they run on a linked managed server. Use an explicit transfer to move an existing project's ownership.
Credentials scoped to the local installation keep their existing execution path; connect
SDK and CLI clients directly to the Cloud API to create Cloud-owned projects.
A failed Cloud creation or capacity check remains an error. Openship does not fall back
to creating a local project or selecting a different Cloud account.
Forwarding does **not** skip your rules. The local permission plane gates every call — checking the caller's
role and access — *before* anything is proxied. Only then does the gateway forward the request.
## How the gateway knows where a project lives
For every project-scoped request, the local API decides "serve this from my own database, or forward it to
the cloud?" in this order:
1. **A local lookup.** A project ID present in the local database stays local, including
a row owned by another tenant. Local authorization still decides whether it is accessible.
2. **A cloud link.** No local row, but the caller's organization has a linked Cloud account?
The request may be forwarded after local permission and credential checks.
3. **Cloud authorization.** Cloud validates that the requested ID belongs to the linked
Cloud organization. An unknown or foreign ID remains a `404`.
4. **Otherwise, not found.** Without a link, an unknown ID is handled locally and returns `404`.
A client-provided `cloud` source hint cannot override a local record or grant Cloud access.
An explicit `local` hint can keep project requests on the local path.
If the cloud can't be reached while forwarding, you get a `503` with code `CLOUD_UNREACHABLE` — not a `404`.
That distinction matters: the project *does* exist, the cloud is just temporarily out of touch.
## Actions for Cloud-owned apps
Opening a Cloud project's **Actions** tab forwards its workflows, runs and deployment
rules to Cloud. Workflow and run detail requests, log cursors, artifacts and runner
changes follow the same ownership decision. The Actions workflow, project and runner
lists include both local and connected Cloud inventory; no Cloud records are copied
into your local database.
A workflow's projects and runners must belong to the same instance. An import or
policy that mixes local and Cloud targets fails before either side writes anything.
Cloud checks its own repository access, destinations and approval policy, and records
the mutation there. Local credentials scoped to this instance cannot borrow the
owner's Cloud session. Connect your SDK or CLI directly to Cloud when using a fixed
Cloud organization scope.
If Cloud cannot be reached, Actions reports a connection error instead of presenting
an empty list. Local project requests continue to use the local engine. On Cloud
itself, these operations run directly and never proxy back to Cloud.
## One cloud identity for the whole team
A cloud connection belongs to the **organization owner**, not to each person. When the gateway forwards a
call, it authenticates as the owner's Openship Cloud session (read server-side from encrypted storage — no
cookies or tokens ever travel from the browser).
So teammates do **not** each need their own cloud account. Your local instance decides *who is allowed* to
act (by their role), then proxies the action as the owner. Because the connection is org-owned, every member
sees the same "connected" state and the same list of cloud workspaces.
## Promote: sending a project up to the cloud
**Promote** moves a local project onto Openship Cloud so the cloud becomes its canonical home. Under the
hood it copies the project's whole **subgraph** (the project row plus everything attached to it —
deployments, domains, env, and so on) up to the cloud, and then removes the local rows so no shadow copy is
left behind.
There are two ways it happens:
- **Born on Cloud.** New catalog apps and Git projects created from the connected dashboard with a
managed Cloud server are created directly in Cloud. There is no local project to copy or delete.
- **Explicit transfer.** You can also promote on demand from the CLI or API (see
[Doing it yourself](#doing-it-yourself)).
Promote keeps the project's GitHub webhook. After promoting, a `git push` to the repo is forwarded to the
cloud copy and redeploys it *there* — so auto-deploy keeps working without any change on your side.
Bring-home reverses this: pushes are handled locally again.
Values encrypted with **your instance's** key (secret env vars) can't be decrypted by the cloud, so they're
stripped during promote. After a project is on the cloud, re-enter those secrets in the cloud project.
## Bring home: pulling a project back
**Bring-home** is the reverse: it exports the project's subgraph from the cloud, restores it into your local
database, clears the project's cloud link, and then tears down the leftover rows on the cloud side so a
future promote won't collide. From that moment the project is canonical-local again, and pushes to its
GitHub repo are handled locally instead of forwarded.
Bring-home moves the project's **data**. Reconnecting things like custom-domain DNS and bringing the app's
containers back up are operator follow-up steps, not part of the data transfer itself.
## What your box still does for a cloud project
For a Cloud-owned project, your local instance forwards operations to Cloud. A local project can
also use a verified managed server as its execution destination: the local controller owns its
configuration and orchestration, while the managed server and its billing belong to Cloud.
This supports local-folder sources and credentials scoped to the installation without giving
them the owner's Cloud account permissions. See [Runtime model](/docs/architecture/runtime-model)
for how a runtime target is chosen.
## On Openship Cloud itself
There's a neat symmetry here: **on the cloud service, every project is already canonical-local** — there is
nothing upstream to forward to. The exact same code runs on both sides; the gateway simply resolves
"local" when it *is* the cloud, so no request ever loops back on itself.
## Doing it yourself
Promote and bring-home are self-hosted-only actions, guarded by the `project:admin` permission. Your
organization also has to be **connected to Openship Cloud** first — a transfer on an unconnected org is
refused.
```bash
# Promote a local project up to Openship Cloud
openship project transfer to-cloud
# Bring a cloud project back to this instance
openship project transfer to-self-hosted
```
The matching API routes are `POST /api/projects/:id/transfer/to-cloud` and
`POST /api/projects/:id/transfer/to-self-hosted`. On promote, a transfer that copies up cleanly but can't
finish local cleanup returns a partial-success (`207`) so you can retry the cleanup — the cloud copy is
already authoritative.
- **`412`** — your org isn't connected to Openship Cloud yet.
- **`409`** — the project is already on the target side, *or* a leftover cloud copy / a name clash blocks the
promote. Openship never overwrites the other copy; it asks you to clean up or rename and retry.
- **`502`** — the cloud accepted the call but the transfer itself failed upstream.
## Related guides
---
# Runtime model
URL: https://openship.io/docs/architecture/runtime-model.md
The three places an app can run — this machine, your own server over SSH, or Openship Cloud — and how a build and deploy flow in each.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Openship can run your app in three different places. Think of your finished app as a meal: you can cook and
serve it in **your own kitchen** (this machine), send the recipe to a **friend's kitchen** (your own server),
or hand it to a **restaurant that cooks and serves it for you** (Openship Cloud). The food is the same — only
the kitchen changes.
You pick the kitchen when you deploy. Openship calls it the **deploy target**, and there are exactly three:
| Target | Where it runs | How Openship reaches it |
|---|---|---|
| **Local** | The same machine Openship itself is running on | Directly — no network hop |
| **Server** | Your own machine (a VPS, a box in a closet) | Over **SSH** (a secure remote connection) |
| **Cloud** | Openship Cloud, run for you | Openship's hosted API |
The target is a per-deploy choice. Deploy to your laptop today to try something, then redeploy the same
project to a real server or the cloud later — nothing about the app has to change.
## Two ways to run it: sandboxed or direct
For the two self-hosted targets (local and server), Openship also picks *how* the app runs on that machine.
This is the **isolation mode**, and there are two:
- **Sandboxed (Docker)** — your app runs inside a **container**: a sealed box with its own files and
dependencies, kept apart from everything else on the machine. This is the default.
- **Direct (bare)** — your app runs as a plain process on the machine, with no box around it. Lighter, but
it shares the machine's environment.
Sandboxed is the default everywhere because the isolation is worth it and the overhead is tiny. The one time
Direct earns its keep is on a very small machine — under about **2 GB of RAM** — where the container engine
would compete with your app for memory. Openship surfaces that as a note when you pick Direct, rather than
silently switching for you.
A Direct (bare) app is kept alive by the machine's own process supervisor — **systemd** on Linux,
**nohup** on macOS — so it restarts if it crashes or the box reboots. A Sandboxed app is kept alive by Docker.
## Build first, then hand off
Whatever the target, every deploy runs the **same two stages** in order.
### Build — turn source into something runnable
The build pipeline always runs the same steps: **prepare → clone → install → build**.
- **Prepare** gets the environment ready (installs the toolchain, transfers local files) — this is counted
separately so first-time setup doesn't inflate your build time.
- **Clone** fetches your code (skipped when you're deploying a local folder — the files are already there).
- **Install** runs your install command (e.g. `npm install`).
- **Build** runs your build command (e.g. `npm run build`) — skipped if the app doesn't need one.
### Deploy — start the new version and send traffic to it
Once the build succeeds, Openship starts the new version, waits for it, points your web address at it, and
then stops the old one. For Sandboxed and Cloud apps this happens **without downtime**: the old version keeps
serving until the exact moment traffic is repointed, so a failure before that moment leaves the old one
untouched. See [Zero-downtime and auto-revert](#zero-downtime-and-auto-revert) below.
*Where the build happens* is separate from *where the app runs*. For a server (or cloud) deploy you can build
on **This Machine** — the machine running Openship — and transfer only the finished output to the target, or
build **on the deploy target** itself. Openship suggests one based on your framework — for most stacks that's
**This Machine** — and you can change it per deploy or save a default under **Settings**. Building on This
Machine is faster when it's the more powerful box and spares a small target VPS a heavy build; building on the
target is best when the Openship machine has limited resources. In Cloud mode the build runs in the cloud
workspace by default, though a self-hosted box can build locally and upload just the output.
## The three targets, up close
**Local** runs your app on the very machine Openship is installed on — great for trying things out on the
desktop app or a single box.
- **Sandboxed** talks to the machine's Docker socket directly.
- **Direct** runs the process on the machine and supervises it with systemd or nohup.
Web addresses and HTTPS are handled by Openship's built-in router on that same machine (see
[Routing and certificates](#routing-and-certificates)).
**Server** runs your app on a machine you own, reached over **SSH** — the same secure connection you'd use
from a terminal. You add the server once — on the **Servers** page, or right in the deploy flow with **Add
your own server** — and Openship keeps a pooled connection to it, so repeat deploys reuse the same link
instead of dialing in fresh each time.
- **Sandboxed** drives the remote machine's Docker engine over an SSH tunnel.
- **Direct** runs shell commands on the server over that same SSH connection.
The router and certificate tooling are set up on *your* server, so traffic never detours through Openship.
If you choose the Server target but haven't added a machine, the deploy screen offers **Add your own server**
so you can connect one over SSH right there — and you can manage servers any time on the **Servers** page.
See [Deploy to your own server](/docs/guides/custom-servers).
**Cloud** hands the whole job to Openship Cloud — we build it, run it, route it, and handle HTTPS. Your app
gets a free `your-app.opsh.io` address out of the box, and you can add a custom domain on top.
A self-hosted Openship instance does **not** run the cloud pipeline itself; cloud projects are handled by
Openship Cloud directly. The one exception is the "build here, run there" path: your own machine can build the
app and upload the finished output to a cloud workspace to run.
## Routing and certificates
Once your app is running, something has to send visitors to it and serve HTTPS.
- **Self-hosted (local and server)** uses **OpenResty** (a build of the nginx web server) to route requests,
and **certbot** to get free HTTPS certificates from **Let's Encrypt** and renew them automatically.
- **Cloud** delegates routing, HTTPS, and static-file hosting to Openship Cloud's edge — there's nothing to
install or renew.
For attaching your own domain, verifying DNS, and managing certificates, see the
[Domains API](/docs/api/domains) and [Add a custom domain](/docs/guides/custom-domains).
## Zero-downtime and auto-revert
The deploy stage adapts to whether the new version can run **alongside** the old one:
- **Sandboxed and Cloud apps can overlap.** Each version gets its own container or workspace, so Openship
starts the new one, checks it, repoints traffic, and only *then* stops the old one. If anything fails before
the switch, the old version was never touched — it keeps serving, and the failed deploy simply doesn't take.
- **Direct apps can't overlap**, because the new process needs the same fixed port the old one is holding. So
Openship stops the old process, starts the new one, and — if the new one fails — restarts the old one to
bring you back. This path has a brief unavoidable gap while the port changes hands.
Deploys to the same machine are serialized with a lock, so two projects deploying at once can't clobber each
other's router config or shared state.
## Related guides
---
# Data ownership
URL: https://openship.io/docs/architecture/data-ownership.md
Where your data lives when you self-host, how to export and import everything so there's no lock-in, and how the desktop app guards the local data directory.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Openship is explicit about where every piece of data lives, because that's what makes self-hosting
trustworthy. When you run Openship yourself, your data sits in a database **on your own machine or
server** — and you can pack all of it into a single file and carry it somewhere else whenever you like.
Think of it like a filing cabinet you own: the folder is yours, the key is yours, and you can move the
whole cabinet without asking anyone.
## Where your data lives (self-hosted)
Local and server projects — and all of their deployments, domains, environment variables, and logs — live
only in your instance's database. Nothing about these projects is sent to Openship Cloud. If you never
connect a cloud account, your instance is completely standalone.
Openship picks the database based on what you configure:
| Mode | When it's used | Where the data sits |
|---|---|---|
| **PGlite (embedded)** | No `DATABASE_URL` and no `POSTGRES_*` set — the zero-config default, and what the desktop app uses | A folder on disk (a full PostgreSQL cluster, no separate server process) |
| **PostgreSQL server** | You set `DATABASE_URL`, or the `POSTGRES_*` / `PG*` variables — typical for a Docker Compose self-host | Your Postgres server (Openship connects with a normal connection pool) |
**PGlite** is PostgreSQL compiled to run *inside* the Openship process — same SQL, same tables, but no
database server to install or babysit. Every repository and service in Openship talks to a single unified
database type, so it never knows or cares which of the two is running underneath.
By default PGlite stores its data in **`~/.openship/data`** (outside your project folder, so it's never
committed to git). Set **`PGLITE_DATA_DIR`** to put it anywhere else. On a Docker Compose self-host you'll
usually point Openship at a real Postgres with `DATABASE_URL` (or `POSTGRES_HOST` / `POSTGRES_PASSWORD`)
instead. See [Installation](/docs/getting-started/installation) for the full set of options.
## Cloud projects live on the cloud
Cloud projects are canonical on Openship Cloud. Your instance holds no shadow copy; it reads and writes
them through the gateway. See [Cloud-as-source](/docs/architecture/cloud-as-source) for how that split
works and why there's never a divergent copy to reconcile.
## No lock-in: export and import everything
Because a self-hosted instance owns its data, Openship lets an **owner** dump the *entire* instance to one
JSON file and load it into another install. That's how you move between machines, back up before a big
change, or hand a project set to a teammate — no proprietary format, no export ticket, no waiting.
You can do it from any of three surfaces:
| Surface | How |
|---|---|
| **Dashboard** | **Settings → Instance**, the **Export** and **Import** cards (self-hosted, instance administrator only) |
| **CLI** | `openship system data-transfer export` and `openship system data-transfer import` |
| **API** | `POST /api/system/data-transfer/export` and `POST /api/system/data-transfer/import` |
### What's in the file
The export contains the instance or selected projects and their chosen dependencies. Secrets such as
environment values, access tokens, SSH credentials and backup keys are encrypted in the database.
Current downloads include selected secrets as **plaintext JSON**, preserving empty values. On import,
Openship encrypts those values with the destination's key.
Anyone who can read a current export can read its included credentials. The CLI creates the output
file with owner-only permissions and refuses to overwrite an existing file. Omit credentials with
`includeSecrets: false` in the export selection when they are not needed. Older encrypted exports
remain importable with their original passphrase.
### Import modes
When you import, you choose how it merges with whatever is already there:
- **Replace (wipe)** — clears the instance and loads the file wholesale. This replaces the current user and
session, so the dashboard reloads afterward to sign you in against the imported data. The CLI requires confirmation.
- **Merge** — inserts only rows that don't already exist, and re-hydrates secrets **only** for the rows it
actually added, so a row already on the destination is never clobbered.
### Move an instance to a new machine
### Export from the old install
Open **Settings → Instance**, review the export selection, then download the file. Your browser saves an `openship-export-…json` file. From the terminal it's:
```bash
openship system data-transfer export --out openship-export.json
```
### Import on the new install
Install Openship on the new machine, sign in as the instance administrator, then go to **Settings → Instance** and press
**Import from file…**. Pick the file and choose **Replace everything** for a clean
move, and confirm. Or from the CLI:
```bash
openship system data-transfer import --file openship-export.json --mode wipe --yes
```
### You're done
The new instance now holds your projects, settings, and any included secrets — re-encrypted
under the new install's key. Everything that pointed at the old machine still points at it, so redeploy when
you're ready.
The import endpoint accepts files up to **500 MB**. A larger export means a very large instance — split it
by moving individual projects instead (below), or import onto a full PostgreSQL-backed instance.
## Moving a single project
You don't have to move the whole instance to relocate one project:
- **Promote** (local → cloud): the project's data is copied to the cloud, then the local rows are removed.
- **Bring home** (cloud → local): the reverse.
A project is always in exactly one place, so there is never a divergent copy to reconcile.
## How the desktop app guards the local data directory
The desktop app runs the same Openship API and embedded database as a headless self-host, but bundled into
one clickable application. A few things keep that on-disk data safe:
- **A single-instance lock.** PGlite is single-process — if two processes opened the same data directory at
once, the database would be corrupted. Before opening, Openship atomically claims a `.lock` file
next to (never inside) the directory. A second copy waits briefly, then fails with a clear message rather
than racing in. The lock self-heals after a crash (a dead process's lock is reclaimed on next launch) and
refuses to open a directory locked by a *different machine*, so a synced folder can't quietly corrupt it.
- **Localhost only.** The bundled API and dashboard bind to `127.0.0.1` (loopback) on ports the app picks at
launch, not a fixed public port. Nothing on your data directory is exposed to the network by the app itself.
- **A private data folder.** The database lives in the app's own per-user data directory (chosen by the OS
for that app), separate from any project checkout.
- **Encrypted secrets at rest.** Secret columns are encrypted with a key derived from a per-install secret
that the app generates once and stores with owner-only file permissions.
The desktop database is the same format as every other self-host, so the **Export** flow above moves it to a
server, a Docker stack, or another desktop with no conversion step.
## Related guides
---
# Desktop app & local data
URL: https://openship.io/docs/troubleshooting/desktop-data.md
Fix desktop and self-hosted startup problems — the database lock, "can't reach the server", a stuck update — and find where your local data lives and how to recover it.
import { Step, Steps } from 'fumadocs-ui/components/steps';
This page is for people who run Openship **on their own machine** — the **desktop app**, or a self-hosted
install that uses the built-in database. If you're on Openship Cloud, none of this applies; we run the
database for you.
When you don't point Openship at a real Postgres, it uses **PGlite** — an embedded Postgres that keeps
everything in a single folder on disk. Only **one** Openship process may use that folder at a time. Most of
the problems below come from two processes trying to share it, or from that folder getting into a bad state.
If you run your own Postgres (the Docker Compose setup), the lock issues here don't apply to you.
## "Another Openship instance is already using the database"
Openship won't start. **Self-hosted or running from source**, the process exits on launch and your terminal
(or log) shows a message like:
> Another Openship instance is already using the database at `/…/data` (pid 12345). PGlite allows only one
> process per data directory; opening a second would corrupt it. Stop the other instance (e.g. quit the
> desktop app) and retry. If you are certain no Openship process is running, remove: `/…/data.lock`
On the **desktop app** you instead get a native dialog titled **“Openship failed to start”** whose body reads
*“Local services failed to start after 3 attempts.”* — the message above is the underlying cause, printed to
the app's console logs prefixed `[api]`.
**What it means (plain words):** the database folder can only be opened by one program at once, and
something is already holding it. Usually that "something" is another copy of Openship — a second window of
the desktop app, a `bun dev` you left running, or an older process that didn't shut down yet.
**How to fix:**
### Close the other one
Quit any other Openship you have open — a second desktop window, a terminal running `openship` or `bun dev`,
or a leftover process from an update. Then reopen the app.
### Give it a moment, then retry
If Openship *crashed* last time (rather than quitting cleanly), the lock heals itself on the next start once
it sees the old process is gone. It also waits a few seconds for a clean hand-off during restarts. Wait a
moment and launch again.
### Only if you're certain nothing is running — remove the lock
The message ends with the exact path of a lock file, named `.lock` (a sibling of your data
folder). If you're **sure** no Openship process is alive, delete that one file and start again. It's safe to
remove — it never contains your data. Do **not** delete anything inside the data folder itself.
A different wording — *"The Openship database … is locked by a process on a different host … PGlite data
directories cannot be shared across machines"* — means your data folder is on a network/shared drive that
another machine opened. PGlite folders can't be shared across computers. Move the data to local disk (or set
[`PGLITE_DATA_DIR`](#where-your-local-data-lives) to a local path), and remove the lock file it names only
if that other host is truly done with it.
## "Cannot reach the server" / "fetch failed" on start
The window opens but stays blank or throws a red toast reading **“Cannot reach the server. Make sure the API
is running.”** In logs you may see the raw Node message `fetch failed`. Sometimes instead you get the
**“Openship failed to start”** dialog saying *"Local services failed to start after 3 attempts."*
**What it means (plain words):** the desktop app runs two things for you behind the scenes — the **API** and
the **dashboard** — each on its own port picked at launch. This message means the dashboard came up but the
API isn't answering yet. Most often it's simply still booting; occasionally the API crashed on startup, and
the most common reason it crashes is the database lock from the section above.
**How to fix:**
1. **Wait a few seconds.** On the first launch after an install or update the API has to run database
migrations before it answers. The app polls for it — give it up to a minute.
2. **Check it isn't really the lock error.** If you also see "already using the database," fix
[that](#another-openship-instance-is-already-using-the-database) first — a locked-out API never comes up,
which is what leaves the dashboard unable to reach it.
3. **Fully quit and reopen.** Quit the app completely (not just closing the window), confirm no `openship`
process is left running, then start it again. It picks fresh ports automatically, so a busy port won't
block it.
The desktop app prints both servers' logs to its console, prefixed `[api]` and `[dashboard]`. If it keeps
failing, that output tells you which one died and why — include it if you file an issue.
## A stuck or failed update
The update download bar sits frozen, or you pressed **Update now**, the app quit, and it never came back — or
it reopened straight into **“Openship failed to start.”**
**What it means (plain words):** the desktop app checks for updates by pulling the latest **public GitHub
release** — it only ever *pulls*, nothing is pushed to you. It downloads the installer, then a small
background script waits for the app to fully exit, swaps in the new version, and relaunches it. Two things
commonly interrupt that: the download can't reach GitHub (offline, rate-limited, slow link), or the new copy
tries to open the database before the old one has finished letting go of it.
**How to fix:**
1. **If the download is frozen:** check your internet connection. A failed or offline check just resolves to
"no update," so a stuck bar usually means a slow or blocked connection to GitHub. Close the update prompt
and try again later.
2. **If it quit and didn't reopen, or reopened on an error:** wait a few seconds (the old version needs a
moment to release the database), then start Openship yourself. If it shows the lock error, follow
[the fix above](#another-openship-instance-is-already-using-the-database).
3. **Install it by hand:** download the installer for your platform from the project's GitHub **Releases**
page and run it over your existing install. Your data folder is untouched by reinstalling.
If the seamless self-replace can't complete, Openship doesn't leave you stranded — it opens the downloaded
installer and quits so you can finish the update yourself. Automatic updates are **off by default**; the
toggle lives under **Settings → Instance → Updates**. See the [Updating guide](/docs/guides/updating) for the
full flow.
## Where your local data lives
Everything Openship stores locally sits in one place per install. Quit Openship before touching any of it.
| Install | Data folder |
|---|---|
| **Desktop app — macOS** | `~/Library/Application Support/Openship/data` |
| **Desktop app — Windows** | `%APPDATA%\Openship\data` |
| **Desktop app — Linux** | `~/.config/Openship/data` |
| **Self-hosted / CLI (default)** | `~/.openship/data` |
| **Self-hosted with an override** | whatever you set in `PGLITE_DATA_DIR` |
A few companion files live beside the data:
- **`.lock`** — the single-instance lock (a sibling of the data folder, never inside it). Safe to
delete only when no Openship is running.
- On the **desktop app**, its parent folder also holds `config.json` (your app settings), `ports.json` (the
ports it reuses so you stay logged in across restarts), and `auth-secret` (keeps your session valid). Leave
these unless you're deliberately resetting.
Point the self-hosted API at any folder with the `PGLITE_DATA_DIR` environment variable — recommended if the
default `~/.openship/data` isn't where you want your data to live. A leading `~` is expanded for you.
### Recovering a corrupted database
Openship won't start and the logs show `RuntimeError: Aborted()`, often alongside
`DrizzleQueryError: Failed query: CREATE SCHEMA IF NOT EXISTS "drizzle"`.
**What it means:** the embedded database folder was damaged — most often by a hard kill mid-write, or by two
processes opening it at once (exactly what the lock exists to prevent). It's a data-folder problem, not a bug
in your project.
**How to fix (running from source / a self-hosted checkout):** two recovery scripts live in the repo and
**back up your data before changing anything**:
```bash
# First try: backs up the folder, clears a stale lock, trims the corrupt WAL tail
bun --cwd packages/db db:heal-pglite
# Deeper recovery if that isn't enough (needs a local Postgres 17 for pg_resetwal)
bun --cwd packages/db db:heal-pglite-resetwal
```
Both copy your data aside first (to `.backup-…` / `.preheal-…`), so you can always fall back to the
original if recovery isn't what you wanted.
If you're on the packaged desktop app (no repo checkout) and it won't recover, quit Openship, **copy** your
data folder somewhere safe, then move the original aside. Openship recreates a fresh, empty database on the
next launch. This gets you running again but starts you over locally — your backed-up copy is your only route
back to the old data, so keep it.
## Still stuck?
---
# Host control channel
URL: https://openship.io/docs/troubleshooting/host-channel.md
"This operation targets the HOST machine, but no host channel is configured" — what the host channel is, why the rest of the install looks healthy, and the repair for each install shape.
import { Step, Steps } from 'fumadocs-ui/components/steps';
When Openship runs in a container it builds and runs your apps through the Docker socket — but a
container can't operate the machine underneath it. For the handful of jobs that need the host itself,
Openship keeps a private SSH channel to it: an ed25519 key authorized for one user, dialed over the
internal `host.docker.internal` bridge and never over a public address.
This page is about the state where that channel was never built. The install reported success, the
dashboard looks fine, ordinary deploys work — and then one specific operation fails with this:
```
This operation targets the HOST machine, but no host channel is configured
(OPENSHIP_HOST_SSH_HOST is unset) and Openship is running in a container — so it
would have run inside the container instead, against the wrong filesystem.
Re-run `openship up` to provision the host channel. `openship doctor` reports
whether it worked.
```
You can also meet it before anything fails: as a `!!! HOST CONTROL NOT CONFIGURED` banner in the API's
boot log, as a **Host control** row reading *never provisioned* in `openship doctor`, or as a banner on
the server's screen in the dashboard.
Nothing here is a dashboard setting — the channel is **CLI-only on purpose**, because a toggle in the
dashboard would be reachable by the very thing it defends against. The install-time context is in
[Installation → Host control](/docs/getting-started/installation#host-control-hardening); the commands
are in the [CLI reference](/docs/cli/self-host).
## This is degraded, not broken
Read this before you touch anything, because the instinct to rebuild the box is the wrong one:
- **Ordinary deploys to this box still work — they go through the Docker socket.** Building, running,
restarting and routing your apps needs the socket, not this channel.
- **Blocked until the channel works:**
- the host terminal, host system info and host port scans
- taking over `:80`/`:443` from a proxy Openship didn't start
- installing or updating the mail engine
- deploying a catalog app that needs a generated config file on the host (Supabase's `kong.yml`, say)
One more symptom belongs next to those but isn't a lost feature: this box also reads **Offline** in the
dashboard's server list while the channel is down. That's the same break wearing a scarier label — the
box is up, the control plane just can't reach it the one way that check uses.
Because it *is* healthy. The channel's address is host-**local**, so it traverses the host's
`filter/INPUT` chain, where a default-deny firewall applies. Published container ports (`:4000`,
`:3001`, `:80`, `:443`) are DNAT'd and never reach that chain. Every check that goes through a published
port passes; only this one hangs.
## Repair — it depends how you installed
The two Compose install shapes look nearly identical on the box and have **different** repairs. Applied
to the wrong one, the first does nothing and the second can cost you every stored environment variable.
Check which you have:
```bash
ls ~/.openship/compose/docker-compose.yml # exists → the CLI installed this stack
```
### Installed with `openship up`
One command — the same one the error names:
```bash
openship up
```
It generates and authorizes the key, writes the environment variables, recreates the API container so it
reads them, and then **dials the host from inside that container** and prints what came back. If the
probe reports a dropped connection it offers to add the firewall rule for you (or takes
`--open-host-firewall` for a scripted run). Then [verify](#verify-it-worked).
The run is idempotent: your secrets, database volume and certificates are carried forward, and a channel
that already works is re-provisioned to the same key.
`openship update` regenerates the stack from the new template and re-provisions the channel the same
way, then re-probes it. That makes it the better command when you're also behind a version — an update
is exactly when a working channel silently stops working, because the recreated API container can land
in a different docker subnet than your firewall rule allows. But when you're already on the latest
release it exits at *"Already on the latest version"* without touching the stack, so on its own it is
not a repair. Use `openship up`.
### Installed from the raw `docker/docker-compose.yml`
Both install shapes pin the Compose project name `openship`, so `openship up` here doesn't create a
second stack — it **adopts** yours, volumes and all, while generating a fresh
`~/.openship/compose/.env`. Current releases stop before writing anything (*"Refusing to continue: this
would regenerate secrets your existing install already has"*), which is the outcome you want. Releases
without that guard minted a new `BETTER_AUTH_SECRET` — the key your stored environment variables are
encrypted with — making **every one of them permanently unreadable**. `openship update` is not the
answer either: with no `~/.openship/compose` stack to reconcile it updates the CLI and leaves your
containers alone.
Provision the channel by hand instead. It's five steps, and the environment variables are the *last*
one — setting them alone gets you `Cannot read host SSH key` or a hung handshake.
**Generate a key on the host** (not inside a container):
```bash
sudo mkdir -p /var/lib/openship/host-ssh
sudo ssh-keygen -t ed25519 -N '' -C openship-host-executor \
-f /var/lib/openship/host-ssh/id_ed25519
```
**Authorize it for `root`**, restricted to the private ranges the docker bridge dials from. It has to be
root: the paths host operations touch are root-owned, so a lesser user yields a channel that connects
and then can't do the job.
```bash
sudo mkdir -p /root/.ssh && sudo chmod 700 /root/.ssh
printf 'from="172.16.0.0/12,192.168.0.0/16,10.0.0.0/8,127.0.0.1",restrict,pty %s\n' \
"$(sudo cat /var/lib/openship/host-ssh/id_ed25519.pub)" \
| sudo tee -a /root/.ssh/authorized_keys
sudo chmod 600 /root/.ssh/authorized_keys
```
`restrict` denies port forwarding, agent forwarding and X11; `pty` is added back because the host
terminal needs one. Without `from=`, that key is a general-purpose root login from anywhere sshd
accepts — on a VPS, the whole internet.
**Satisfy the two prerequisites** — sshd reachable from containers, and the host firewall open for them.
They're [below](#the-two-prerequisites-that-break-this-silently); on a box running `ufw` the firewall is
the step that's actually missing.
**Set the variables** in the `.env` you pass with `--env-file`:
```bash
OPENSHIP_HOST_SSH_HOST=host.docker.internal
OPENSHIP_HOST_SSH_USER=root
OPENSHIP_HOST_SSH_PORT=22
OPENSHIP_HOST_SSH_KEY=/run/secrets/openship_host_key
OPENSHIP_HOST_KEY_PATH=/var/lib/openship/host-ssh/id_ed25519
```
The last two are a pair: `OPENSHIP_HOST_KEY_PATH` is the key's path **on the host**, which
`docker/docker-compose.yml` mounts at `OPENSHIP_HOST_SSH_KEY` inside the API container — so no compose
file needs editing. It must be an **absolute** path; a relative one resolves against `docker/`, not the
directory you run `docker compose` from. Left unset, `/dev/null` is mounted in its place, which is what
lets the stack start on a box with no key at all.
**Recreate the API container.** `env_file:` is read when a container is *created*, so a restart changes
nothing and the fix appears to have done nothing:
```bash
docker compose --env-file .env -f docker/docker-compose.yml \
up -d --force-recreate --no-deps api
```
## Verify it worked
The repair happens on the host and the fault shows up in a container, so "the command succeeded" and
"the channel works" are genuinely different questions. Ask the second one:
```bash
openship doctor
```
The **Host control** row dials the host from inside the API container: `reachable at
host.docker.internal:22` is the pass. Anything else names the cause — a dropped connection (firewall), a
refusal (sshd), or a name that didn't resolve.
The dial above needs the CLI's own stack at `~/.openship/compose`, which a hand-run
`docker/docker-compose.yml` install doesn't have. There, the **Host control** row falls back to what the
API says about its own environment over the loopback API: `never provisioned — run openship up` (read
the warning above before you do), `reachable from the api container`, or the fault by name. It cannot
name an address, because nothing dialed one.
For the address and the exact firewall rule, use the API's boot log — it diagnoses the channel on every
start:
```bash
docker compose --env-file .env -f docker/docker-compose.yml logs api | grep 'HOST CONTROL'
```
No output is the pass; the banner is only printed when something is wrong. Or exercise the channel
directly — open the server's **Terminal** tab in the dashboard, which is this channel and nothing else.
## The two prerequisites that break this silently
Either of these leaves a channel that is fully configured and completely dead, which is why the error
says "not configured" long before anyone suspects the host.
### sshd must be running, and listening where containers can reach it
The channel is real SSH to the host's own daemon. A minimal cloud image or a container-optimized OS may
not run one, in which case there's nothing to connect to:
```bash
sudo systemctl enable --now ssh
```
Also check that `ListenAddress` in `/etc/ssh/sshd_config` isn't pinned to `127.0.0.1`. That looks like
sensible hardening and is invisible to every other test, because everything else reaches this box
through a published port. A connection *refused* (rather than a hang) is this one.
### The host firewall must allow container→host on the SSH port
This is the common cause. Traffic from the API container to `host-gateway` is host-local, so it goes
through `filter/INPUT` — where `ufw`'s default deny sits. Published container ports are DNAT'd and skip
`ufw` entirely, so nothing else on the box notices. The connection doesn't fail, it *hangs*, which looks
exactly like a bad key.
Allow the docker bridge subnets the API container dials from:
```bash
# ufw
sudo ufw allow from 172.16.0.0/12 to any port 22 proto tcp
# firewalld
sudo firewall-cmd --permanent --add-rich-rule='rule family="ipv4" source address="172.16.0.0/12" port port="22" protocol="tcp" accept'
sudo firewall-cmd --reload
```
`172.16.0.0/12` is Docker's default address pool — wider than one bridge, and correct for any of them.
A raw `iptables` rule works too but doesn't survive a reboot on its own; persist it with
`iptables-persistent` or your distro's equivalent. On a CLI install you don't write any of this
yourself: `openship up` and `openship update` read the API container's actual networks, print the
narrower rule, and offer to apply it (or take `--open-host-firewall` for a scripted run).
Something ahead of `ufw`/`firewalld` is dropping it — check Docker's own `DOCKER-USER` chain, and any
cloud provider firewall or security group. If the failure *changed shape* when you added the rule (a
hang became a refusal), the rule did its job and you're now on the sshd problem above.
## Turning the channel off on purpose
A box that only manages *remote* servers doesn't need a host channel. Switching it off is a hardening
decision, not a repair — everything in the blocked list above stays blocked:
```bash
openship up --no-host-control
```
That deletes the private key and revokes its `authorized_keys` line, so the box's attack surface
shrinks rather than just this install's behaviour. On a raw `docker compose` install the equivalent is
`OPENSHIP_HOST_CONTROL=false` in `.env` (plus removing the key and its authorized line yourself). Host
operations then refuse with a message naming the choice instead of the fault, and this box stops being
offered as a deploy target.
## Related
---
# Common errors
URL: https://openship.io/docs/troubleshooting/common-errors.md
The API error codes and messages you'll actually hit — what each one means, and how to fix it.
When something goes wrong, the Openship API answers with a small JSON object, not a wall of stack trace.
It always has a human `error` message, and for the failures worth reacting to programmatically, a stable
machine `code`. Validation failures add a `details` map that names the exact fields that were wrong.
```json
{ "error": "This access token is read-only", "code": "TOKEN_READ_ONLY" }
```
So when you see an error, you have two things to work with: the **code** (look it up in the table below) and
the **HTTP status** (the number your client reports — `401`, `403`, `429`, and so on). The message tells you
what happened; the code tells you which fix applies.
## The error table
Scan for the code (or status) you got. Not every error carries a code — the generic `500` and the `429`
rate-limit response have none, so match those by status.
| Code / message | What it means | What to do |
|---|---|---|
| **`VALIDATION_ERROR`** (400) — "Validation error" | Your request body or query didn't match what the endpoint expects. The response's `details` map lists each offending field and why. | Read `details`, correct the named fields, and resend. This is a client-side mistake — retrying the same payload won't help. |
| **`INVALID_TOKEN`** (401) — "Invalid or expired access token" | The `Authorization: Bearer` token isn't recognized — it was mistyped, revoked, or the token no longer maps to a real user. | Create a fresh token with [`openship token create`](/docs/cli/access) and use that. Confirm you copied the whole `opsh_pat_…` value. |
| **`BEARER_NOT_ALLOWED_FROM_BROWSER`** (401) — "Access tokens are not allowed from browser origins" | You sent a bearer token from a browser-trusted origin. Bearer auth is for CLI and server-to-server calls only; this block stops a stolen session token being replayed past the cookie defence. | Use the token from a terminal or backend, not the browser. In the dashboard you don't need a token at all — it authenticates with your session cookie automatically. |
| **`UNAUTHORIZED`** (401) — "Unauthorized" *(no code on the plain form)* | No valid session and no valid token — you're simply not signed in. | In the dashboard, log in again. From the API/CLI, send `Authorization: Bearer `. See the [API overview](/docs/api) for the auth model. |
| **`TOKEN_ORG_SCOPE`** (403) — "This access token is scoped to a different organization" | Your token is bound to one organization, but you sent an `X-Organization-Id` header naming a different one. | Drop the `X-Organization-Id` header, or use a token that belongs to the org you're targeting. (The MCP wording is "This authorization is scoped to a different organization".) |
| **`TOKEN_READ_ONLY`** (403) — "This access token is read-only" | A read-only token was used for a mutating request (`POST`, `PUT`, `PATCH`, or `DELETE`). | Use a read-write token for writes, or switch the call to a read (`GET`). (The MCP wording is "This MCP authorization is read-only".) |
| **`FORBIDDEN`** (403) — "Forbidden" | You're authenticated, but your role or grants in this organization don't permit the action. | Ask an org owner/admin for the right role, or check [Permissions & roles](/docs/security/permissions) for what each action needs. |
| **`NOT_FOUND`** (404) — "`` not found" | The thing you asked for doesn't exist — or it exists but isn't in your organization (Openship returns 404 rather than leaking that it's someone else's). | Double-check the id. List the resource (e.g. `GET /api/projects`) to get valid ids for your org. |
| **`CONFLICT`** (409) — e.g. "Project '…' already exists", "Domain '…' is already in use" | Something with that name is already taken in your organization — a project name or slug, a domain/hostname, or an environment name. | Pick a different name, slug, or hostname, or reuse the resource that already exists instead of creating a duplicate. |
| **Rate limited** (429) — "Too many requests" *(no code)* | You exhausted a rate-limit bucket. Openship limits the whole `/api` surface per rolling minute. | Honor the `Retry-After` header (seconds) and back off — don't hammer-retry. See [rate limits](/docs/api/http#rate-limits) for the per-policy budgets. |
| **`AUTH_UNAVAILABLE`** (503) — "Authentication service unavailable" | Checking your session threw — the auth backend's database is unreachable, session decryption failed, or similar. Importantly, this is *not* treated as "no session" — Openship fails closed rather than letting you through. | Transient — retry after a moment. If it persists, check your instance's database and API logs. |
| **Internal server error** (500) — "Internal server error" *(no code)* | An unhandled error on the server. There's no machine code because it wasn't an anticipated failure. | Check your API server logs for the `[UNHANDLED ERROR]` entry — that has the real cause. If self-hosting, that log line is where to start. |
## The ones you'll hit first
Here are the everyday ones spelled out, with the fix step by step.
### "Access tokens are not allowed from browser origins"
Your API call returns `401` with `code: "BEARER_NOT_ALLOWED_FROM_BROWSER"`.
**What it means:** You sent an `Authorization: Bearer` token from a browser (or an origin Openship trusts as
a browser front-end). Bearer tokens are meant for the CLI and server-to-server calls — the dashboard is not
supposed to carry one, so Openship rejects it to stop an exfiltrated session token being replayed.
**How to fix:**
1. If you're building against the API, move the call to a terminal or a backend service — anywhere that
isn't a browser origin.
2. If you were poking the API from the browser to mimic the dashboard, you don't need a token: the dashboard
authenticates with its `httpOnly` session cookie automatically.
3. Generate tokens for machine use only, with [`openship token create`](/docs/cli/access).
### "This access token is read-only" / "scoped to a different organization"
A write returns `403` with `code: "TOKEN_READ_ONLY"`, or any call returns `403` with `code: "TOKEN_ORG_SCOPE"`.
**What it means:** Tokens can be narrowed at creation. A **read-only** token refuses `POST`/`PUT`/`PATCH`/`DELETE`;
an **org-scoped** token refuses to act on a different org than the one it's bound to (which happens when your
`X-Organization-Id` header names another org).
**Fixes:** For `TOKEN_READ_ONLY`, create a read-write token, or make sure the call really needs to be a write.
For `TOKEN_ORG_SCOPE`, remove the `X-Organization-Id` header (the token already knows its org) or use a token
issued for the org you're targeting.
### "Validation error"
A request returns `400` with `code: "VALIDATION_ERROR"` and a `details` object.
**What it means:** The request body or query parameters didn't match the endpoint's schema. This is always a
client-side problem — the `details` map pins down exactly which fields failed and why.
**How to fix:**
1. Read the `details` map — its keys are the field names, and each value lists the problems with that field.
2. Correct just those fields (a missing required field, a wrong type, a value out of range).
3. Resend. Retrying the identical payload will fail identically.
### "Too many requests"
A request returns `429` with body `{"error":"Too many requests"}`.
**What it means:** You've spent a rate-limit bucket for the rolling minute. Unauthenticated traffic is limited
per IP; authenticated traffic gets a larger per-user budget; a few route groups (login, webhooks, MCP) have
their own policies.
**How to fix:** Read the `Retry-After` response header (seconds until the window resets) and wait that long
before retrying. Every response also carries `X-RateLimit-Limit`, `X-RateLimit-Remaining`, and
`X-RateLimit-Reset` so you can pace yourself before you hit the wall. The per-policy limits are listed in the
[API overview](/docs/api/http#rate-limits).
If you get `400` with "Missing client IP — request must come through the proxy", your instance couldn't work
out the caller's IP for its per-IP limits. That means requests are reaching the API without going through the
reverse proxy that sets the forwarded-IP header. Route traffic through your proxy (openresty in the standard
topology) rather than hitting the API port directly.
## Build and deploy failures
The codes above are about the API request itself. If a **deployment** failed — the build screen went red, the
app won't start, a port is taken — that's a different set of symptoms.
---
# GitHub connection & repos
URL: https://openship.io/docs/troubleshooting/github.md
Fix an expired or unauthorized GitHub connection, a private repo that won't import, a public repo that should just work, and auto-deploy webhooks that never fire.
Most GitHub problems fall into one of four buckets: Openship can't read your repos, a **private** repo
won't import, a **public** repo that should need no login keeps asking you to connect, or pushes aren't
triggering deployments. This page walks each one from the exact message you'll see to the fix.
Openship can reach GitHub through the managed **Openship GitHub App**, workspace-owned GitHub Apps, a
personal token, SSH key, or the local `gh` identity. It also manages the webhooks that power auto-deploy. If you haven't connected yet, start
with [Deploy from GitHub](/docs/guides/deploy-from-github); the connection card itself lives in
[Settings → Git](/docs/dashboard/settings).
## Openship can't read your repositories
The repo list is empty, or an action fails with **"Not connected to GitHub"**, **"No GitHub access token
available. Please connect your GitHub account."**, or a `403` with code `GITHUB_TOKEN_REQUIRED`.
**What it means (plain words):** Openship has no usable credential for your account. Either you were never
connected, or a token that used to work has expired or been revoked (you signed out of `gh`, rotated a
personal access token, or removed the App). Openship isn't broken — it just has nothing to authenticate with.
**How to fix:**
1. Go to **Settings → Git**. For a workspace-owned App, verify its source card and make sure it lists the
intended GitHub account. For a local identity, use the **GitHub** card to reconnect it.
2. If it *does* show a login but repos still won't load, press **Disconnect**, then **Connect GitHub** again
to mint a fresh token.
3. On a self-hosted instance using the CLI fallback, run `gh auth login` in the terminal on the machine
running Openship, then reload the page.
The deploy pipeline gives a more specific hint depending on where the build runs. A local build asks you to
**"Run `gh auth login`, connect Openship Cloud, or set a per-project clone token in Settings."** A remote
(server / cloud) build asks you to **"Install the Openship GitHub App on this owner, or set a per-project
clone token in Settings."** — a `gh` CLI token is never shipped off the host, so a remote build needs the
App or a token. On a self-hosted **server** deploy you have more options: turn on **Settings → Clone
credentials → "Forward my git identity to build servers"**, log the server itself into GitHub, or save a
token/SSH key on the server. See [Git authentication for private repos](/docs/guides/git-authentication)
for the full chain and how to enable each.
If connecting returns a `503` with **"Openship Cloud is unreachable, so GitHub can't be connected right
now."**, your self-hosted instance is cloud-connected but can't reach Openship Cloud. GitHub connection
runs through the cloud in that mode, so check your network (or the cloud status) and try again — Openship
deliberately refuses to hand you a dead install link.
## A private repo won't import
Your private repo is missing from the picker, or importing it fails with **"GitHub App is not installed for
this account"**, a scope error like **"PAT is missing required scope (need one of: repo, public_repo)."**,
or a `409` **"No GitHub App installation token is available for this owner."**
**What it means:** GitHub only exposes a private repo to a credential that has explicit access to it.
Openship can see it only if the **GitHub App is installed on that owner and includes that repo**, or you've
given it a **personal access token** with the right scope. A public-repo-only token, or an App install that
skipped the repo, can't see it.
**How to fix:**
1. **Install / re-scope the App.** In **Settings → Git**, use **Install on account** on the intended
workspace-owned source (or **Install GitHub App** for the managed App). When GitHub asks *which
repositories* to grant, choose **All repositories** or make sure the private repo is selected.
2. **Or add a personal access token.** In the project's **Source** tab, paste a token into the
**Clone Token Override** card (or set a global one in **Settings → Git → GitHub clone credentials**).
The token must include the **`repo`** scope — `public_repo` alone only reaches public repos.
3. Reload the picker; the repo should now appear.
GitHub access is **default-deny** for everyone except the organization owner. If you're a member and a
private repo is invisible or won't build even though the App is installed, the owner hasn't granted you that
repo yet. Ask them to grant it (or connect your own personal access token). See
[Teams & members](/docs/guides/teams-members).
## A public repo keeps asking me to connect
You point Openship at a public GitHub repo expecting it to deploy with no login, but it still asks you to
connect a GitHub account.
**What it means:** A public github.com repo *can* be read and deployed with zero credentials — Openship
probes it anonymously first. That probe **fails closed**: if the repo doesn't come back as clearly public,
Openship falls back to asking for a credential. The usual reasons are that the repo isn't actually public,
the owner/repo is mistyped, or it isn't on github.com.
**How to fix:**
1. Open the repo in a private/incognito browser window (logged out). If you can't see it, it's **private** —
use the private-repo fix above.
2. Double-check the **owner/repo** spelling. Both `https://github.com/owner/repo` and
`git@github.com:owner/repo.git` forms are understood, but only **github.com** — GitLab and GitHub
Enterprise hosts always need a credential.
3. If you *just* made it public, wait a minute and retry. Openship caches the "public" verdict for about ten
minutes, and a transient network error during the probe makes it ask for a credential that one time.
## Auto-deploy isn't triggering (webhooks not firing)
You push to GitHub but nothing deploys. On GitHub, **Settings → Webhooks → Recent Deliveries** shows red
`401` responses, or no delivery at all.
**What it means:** Auto-deploy is a **webhook** — GitHub sends Openship a message the instant you push. If
the message never arrives, is rejected, or arrives for a branch/project that isn't set to auto-deploy,
nothing happens. Work through the checks below in order.
**How to fix:**
1. **Turn auto-deploy on.** Open the project's **Source** tab. If the **Auto Deploy** card says *Disabled*
("Deployments must be started manually"), toggle it on. This is also what registers the webhook on the
repo.
2. **Check the webhook is reachable.** If the Source tab shows the **"Enable auto-deploy"** banner —
*"Auto-deploy needs a direct webhook endpoint. Expose this Openship API on a public URL or configure a
verified webhook domain for direct delivery."* — then your instance is on `localhost` or a private
network and GitHub literally can't reach it. Put Openship behind a public URL, or pick a
[verified custom domain](/docs/guides/custom-domains) for direct delivery.
3. **Push the branch you actually deploy.** Openship only redeploys when the pushed branch matches the
project's deploy branch. A push to any other branch is ignored (the logs read *"No local auto-deploy
projects matched"*). Confirm the branch in the Source tab.
4. **Fix a rejected signature.** Red `401` deliveries with **"Invalid signature"**, **"Missing
x-hub-signature-256 header"**, or **"No webhook secret configured — signature cannot be verified"** mean
the hook's signing secret doesn't match. Toggle **Auto Deploy** off and on to re-register the webhook —
that mints a fresh per-project secret on both sides.
For monorepo / multi-service projects, Openship only rebuilds the services whose files changed. A push that
touches nothing under a service's root is skipped by design (logged as *"no affected services"*) — that's
smart routing, not a failure. See [Compose & multi-service](/docs/guides/compose-multi-service).
If a delivery is retried, Openship drops the repeat (*"Duplicate delivery ignored"*) so you don't get two
deployments from one push. Nothing to fix.
## Still stuck?
---
# Troubleshooting
URL: https://openship.io/docs/troubleshooting.md
Where Openship shows you what went wrong — the build screen, the Logs tab, and the CLI — and how to read an error before you try to fix it.
When something breaks, Openship has almost always already told you why — the trick is knowing where it
wrote it down. This page is the starting point: it shows you the handful of places the real answer lives,
and one habit that solves most problems on its own.
Whatever went wrong, scroll to the **bottom** of the output and read the **last red lines**. Openship (and
the tools it runs — npm, Docker, your framework) print the actual cause right before they give up.
Everything above the red is usually just normal progress.
## Where the useful information lives
There are only a few screens you ever need. Match your situation to the right one:
| When... | Look here | How to open it |
|---|---|---|
| A deploy is running or just failed | **The live build screen** | You land on it after pressing **Deploy**; it streams every build step as it happens. |
| Your app is deployed but misbehaving | **Project → Logs tab** | Open the project, choose **Logs**. Two sub-tabs: **Terminal** (your app's own output) and **Server**, whose panel is titled **HTTP Request Logs** (incoming requests). |
| Nobody's requests are reaching the app | **HTTP Request Logs** | The **Server** sub-tab of **Logs** — each row is a request with its method, path, status code, and response time. |
| You work from the terminal | **The CLI** | `openship logs --follow`, plus `openship doctor` and `openship status`. |
### The live build screen
This is the page you watch during a deploy — like watching the oven through the glass door. It streams the
build as it happens and, when it finishes, hands you the live URL. If a build fails, this is the first place
to look: the failing command and its error are in the last lines before the stream stops. See
[the deploy wizard](/docs/dashboard/deploy-wizard) for a tour of it.
### The project Logs tab
Once an app is live, open it and pick **Logs**. You get two sub-tabs you switch between:
- **Server** — its panel is headed **HTTP Request Logs**: one line per incoming request (method, path, status
code, response time, country, and size). Great for "is anything even hitting my app?" and for spotting a
flood of `4xx`/`5xx` responses. (For a static site with no runtime, this tab is relabeled **Requests**.)
- **Terminal** — your app's own stdout/stderr, streamed straight from the running container. This is where a
crash, a stack trace, or a "listening on port…" line shows up.
Use the **Copy** or **Download** buttons in the header row to grab the logs when you want to save them or ask
for help. The full walkthrough is in [Logs & monitoring](/docs/guides/logs-monitoring).
If the live terminal pops up **"Failed to connect to terminal logs, make sure your project is running"**, or
the **HTTP Request Logs** panel shows **"Connection to log stream lost"**, the app isn't currently running
(or was put to sleep). Redeploy it, or wake it, and the live tail reconnects on its own. In the terminal,
**"Waiting for logs…"** just means it's connected but the app hasn't printed anything yet — that's normal for
a quiet app.
### The CLI
Everything above has a terminal equivalent:
```bash
# Snapshot of a deployment's logs
openship logs
# Stream them live until the deployment finishes
openship logs --follow
# Just the last 50 lines
openship logs --tail 50
```
Two commands answer "is my setup even OK?" before you go hunting further:
```bash
# Check config, active login, whether the API is reachable, and your runtime
openship doctor
# Health + mode (self-hosted vs cloud) of the API you're pointed at
openship status
```
`openship doctor` prints a checklist with a green `✓`, yellow `!`, or red `✗` next to each of **config**,
**context**, **api**, **node**, and **bun** — so a red line tells you exactly which part is wrong. Full
command details live in the [CLI reference](/docs/cli).
## How to read an Openship error
Openship errors are short and structured on purpose — they're not meant to be scary.
**In the dashboard**, failures show up as a toast (a small popup) with a message, and — for anything that
was streaming — as a red line in the build screen or Logs terminal. Read the message; it's the same text the
server sent.
**From the API or CLI**, every error comes back as a small JSON object with two fields you care about:
```json
{ "error": "human-readable message", "code": "MACHINE_CODE" }
```
- **`error`** is the sentence to read.
- **`code`** is a stable label you can search for. Bad input is reported as `code: "VALIDATION_ERROR"` with a
`details` object naming the exact fields that failed.
- The **HTTP status** tells you the category at a glance: `400` bad request, `401` not logged in, `403` not
allowed, `404` not found, `409` conflict (something already exists / is in use), `500` a genuine server
error. A bare `{ "error": "Internal server error" }` with status `500` means the cause is in the server
logs, not in what you sent.
### Symptom: a deploy failed and you can't tell why
The build screen (or `openship logs --follow`) ends on red lines instead of a live URL.
**What it means** — a command in the build gave up. The line that matters is the **last** one before the
stream stopped, not the wall of output above it.
**How to fix**
1. Scroll to the bottom of the build screen and read the final red lines out loud — they name the failing
step (a missing command, a package that won't install, a port mismatch).
2. If it mentions a missing setting or secret, add it under the project's **Configuration** tab and redeploy.
3. Still stuck? Press **Copy**/**Download** to save the log, then match the message against
[Troubleshooting → Deployments](/docs/troubleshooting/deployments), which lists the common build and
runtime failures with fixes.
### Symptom: the CLI can't reach your instance
Commands hang or fail before doing anything, and `openship doctor` reports the **api** check as `unreachable`
or an unexpected `HTTP` status.
**What it means** — the CLI is pointed at an instance it can't talk to: the wrong address, an instance that
isn't running, or a login that has expired.
**How to fix**
1. Run `openship doctor`. It checks, in order: your **config** file, your active **context** and token, and
whether the **api** answers.
2. If **context** is yellow with *"has no token; run `openship login`"*, log in again.
3. If **api** is red, confirm the instance is actually up (`openship status` shows its health and mode) and
that the address is the one you expect.
### Symptom: openship up refuses to regenerate secrets
A re-run of `openship up` (Compose install) exits without starting anything and names one or more of
`POSTGRES_PASSWORD`, `BETTER_AUTH_SECRET`, `INTERNAL_TOKEN`.
**What it means** — those secrets are generated once and stored only in `~/.openship/compose/.env`. This run
couldn't read them there, but the install's database volume is still on the box. Regenerating them cannot work:
Postgres applies `POSTGRES_PASSWORD` only when it first creates its data directory (the API would fail with
`password authentication failed for user "openship"`), and `BETTER_AUTH_SECRET` is the key your stored
environment variables are encrypted with. So the run stops **before writing anything** rather than leaving you
with a stack that can't start.
**How to fix**
1. Check who you're running as. `sudo openship up` reads `/root/.openship/compose/.env`; without `sudo` it reads
the one in your own home. Re-run as the user that owns the install.
2. If the file is there but unreadable, fix its permissions — don't let the secrets be regenerated instead.
3. If it was overwritten, restore it. Every `openship up` keeps the `.env` it replaced at
`~/.openship/compose/.env.bak`; older values may also survive in a stopped container
(`docker inspect --format '{{json .Config.Env}}'`).
4. Only if the original values are genuinely gone: `openship up --reset-secrets`. The database password is
realigned for you, but **every stored environment variable becomes permanently unreadable** — you'll need to
re-enter them under each project's Configuration tab.
`openship up --dry-run` lists each secret as `` or `` and warns when a real run
would refuse — so you can check what a re-run will do before it touches the box.
### Symptom: the openship command crashes, or vanishes after a Node upgrade
`npm i -g openship` reported success, but the command either dies instantly with a `SyntaxError`
pointing at a file you've never heard of (`string-width`, `commander`) or isn't on your `PATH` at all.
**What it means** — a package-manager install runs on **your** Node, and Openship needs **Node 22+**.
On Node 18 the install genuinely succeeds and the binary is linked; it's the first dependency it loads
that can't be parsed by that Node.
Current CLI versions handle this for you: instead of the `SyntaxError` they offer to download an
official Node 22 into `~/.openship/runtime` and use it for Openship only. So a raw `SyntaxError` means
you're on an older release — reinstall the CLI and it will offer the fix.
The `command not found` variant usually follows *fixing* the first one: nvm, fnm and volta keep global
packages **per Node version**, so installing a newer Node leaves the CLI behind with the old one.
**How to fix**
1. Check what you're on: `node --version`. Below 22, either accept the CLI's offer to fetch its own
Node, upgrade yourself, or skip the question entirely with
`curl -fsSL https://get.openship.io | sh` — that installer never touches the Node you have.
2. Scripting it? `OPENSHIP_VENDOR_NODE=1` accepts the download without a prompt (`0` declines).
3. After upgrading Node with a version manager, reinstall the CLI on the new version: `npm i -g openship`.
4. Still not found? The official installer puts it in `~/.openship/bin` — open a new terminal, or
`export PATH="$HOME/.openship/bin:$PATH"`.
## Jump to the right page
---
# Domains, DNS & SSL
URL: https://openship.io/docs/troubleshooting/domains-ssl.md
Fix domain verification, DNS propagation, missing routes, SSL provisioning, and external ingress.
A working custom domain needs DNS to reach its ingress, a route to the intended application, and TLS at
the server or an external proxy. Verification depends on where the project runs. This page explains the
failure messages and which part to check.
If you haven't added a domain yet, start with the [custom domains guide](/docs/guides/custom-domains) — this
page is for when something is already stuck.
Openship Cloud checks a routing record and an ownership TXT record; with external ingress it checks only
the TXT record. Self-hosted verification obtains or reuses a valid certificate through ACME, without
comparing the public IP or checking an ownership TXT record. Self-hosted external ingress accepts the
operator's configuration and leaves TLS to the proxy.
## DNS and SSL are verified, but the app still returns 404 or 502
DNS verification and certificate issuance do not prove that a domain has a working upstream.
For a Compose project, open **Domains & Routes** and map the domain to the intended service's
container port. An unmapped project-level domain is skipped with a warning naming the available
ports; it must not inherit a stale project port from another service. Then retry routing or set
up the project's edge. Review any route warnings even when the edge itself is healthy.
On an Openship control-plane project, an instance administrator can use these repair actions to
route the adopted dashboard to its configured loopback port. The repair preserves the dashboard
service's existing port claim. Project membership alone does not grant access to reserved host
ports, and organization-bound or restricted API tokens cannot perform this instance action.
If setup recorded `OPENSHIP_PUBLIC_URL` as **external ingress**, boot assumes an existing proxy
terminates TLS. That record alone does not provision Openship's edge. Use the self-hosted setup
flow to configure Openship's edge when changing who owns ingress; retain external ingress when
your existing proxy should continue serving the domain.
A static route needs the absolute release directory of its active deployment. A container ID,
image tag or artifact hash cannot serve as a document root. A warning that no static root exists
means the deployment's artifact or workload metadata needs repair or a new successful deployment.
## Verification keeps failing
You click **Verify** and it doesn't turn green. The **"Verification failed"** toast contains the reason
Openship returned. On Openship Cloud, DNS failures name one or both records:
- `CNAME record not found for app.example.com`
- `TXT record _openship-challenge.app.example.com must equal "…"`
(If Openship can't produce a specific reason it falls back to the generic *"\{hostname} could not be verified yet."*)
From the API, `POST /api/domains/:id/verify` returns **422** with the failure message. For Cloud DNS checks,
`cnameVerified` and `txtVerified` identify the failing record. On self-hosted instances, read the message
for certificate or server connectivity failures; those flags do not represent separate DNS lookups.
**What it means.** Cloud DNS verification could not confirm the requested routing or ownership record.
Fix each record named in the message.
| Message you see | Which record | What's wrong |
|---|---|---|
| `CNAME record not found for …` | Routing (`CNAME`) — Openship Cloud | The `CNAME` is missing or doesn't point at the Cloud target. |
| `TXT record _openship-challenge.… must equal "…"` | Ownership (`TXT`) | The `_openship-challenge` TXT record is missing, or its value doesn't match the secret code. |
### If the Cloud routing record is failing
**How to fix**
1. Open your project's **Domains** tab and reopen the **DNS Records** panel for the domain (or run
`openship domain records `).
2. Compare the routing row against your registrar's record. Cloud expects a `CNAME` pointing at the
**Openship Cloud target** shown in the panel.
3. Fix any mismatch — copy the value from Openship, don't retype it. Delete any old, conflicting record for the
same name first (a stale `A`/`CNAME` left in place is a common cause).
4. Wait for the change to take effect, then click **Verify** again.
For HTTP-01, the hostname must reach the server's challenge endpoint on port 80, including through any
proxy or NAT. DNS-01 uses a connected DNS provider or the **Manual TXT** flow in **DNS-verified HTTPS**.
Neither mode compares the hostname's public IP with the server's IP. If another proxy owns TLS, use
**External ingress & TLS** and configure that proxy to forward application requests.
## Wildcard or manual TXT setup is waiting
Wildcard certificates require DNS-01. The routing `A` or `CNAME` record does not replace the certificate's
`_acme-challenge` TXT record. Open the domain's **DNS-verified HTTPS** panel to see the active attempt,
its deadline and **Certificate logs**.
| State or message | What to do |
|---|---|
| No DNS provider connected | Choose **Connect a DNS provider** in the DNS panel (also available in **Settings → Credentials**), or choose **Manual TXT** and generate a TXT record. |
| TXT record not visible | Compare both name and value. If the provider appends your zone name, enter only the relative part. Keep other TXT values, allow propagation, then **Check TXT & enable HTTPS**. |
| Connection interrupted | Reopen the panel or use **Refresh status**. An accepted operation continues on the server; the saved attempt can resume after a restart. |
| TXT challenge expired or CA order invalid | Cancel the old attempt if needed and start again. Publish the new value; remove only the previous attempt's value. |
| Certificate authority changed | Start a new challenge using the current HTTPS settings. An order belongs to the authority that created it. |
| Server connection or certificate installation failed | Restore access to the current deployment server, then retry the same saved challenge before its deadline. Existing TLS is retained. |
Manual TXT setup does not retry on a schedule: it waits for the operator to publish and check DNS.
Within 14 days of expiry, the domain details request renewal. Use **Renew SSL** to obtain and confirm a
fresh TXT value, or switch to **Automatic provider** for unattended renewal. See the
[wildcard setup guide](/docs/guides/custom-domains#wildcard-domains).
### If the Cloud TXT ownership record is failing
**How to fix**
1. At your registrar, add (or correct) a **TXT** record with host `_openship-challenge` — Openship looks it up
at `_openship-challenge.`.
2. Set its value to the exact string from the **DNS Records** panel. Use the **Copy** button; a single extra
space or a missing character will fail the match.
3. Save, wait for propagation, and click **Verify** again.
Cloudflare represents TXT content with surrounding double quotes, for example
`"ownership-token"`. Automatic DNS setup writes this form and repairs older
unquoted values when you apply the DNS plan again. The quotes delimit the DNS
string; they are not extra characters in the ownership token. Openship accepts
quoted resolver answers and joins chunks within a single TXT record.
## Cloud DNS is correct, but the certificate check fails
Openship Cloud gets its certificate status from the Cloud provider. Connecting
Cloudflare automates DNS records; it does not move Cloud certificate issuance to
the Openship API server. A Cloudflare certificate notification alone does not
confirm the origin's certificate or the application's route.
If the response contains `CLOUD_DOMAIN_NOT_CONNECTED`, the provider has no route
for this domain and project. Check the service mapping in **Domains & Routes**,
retry routing, then verify HTTPS. `CLOUD_DOMAIN_CHANGED` means the binding changed
during the operation; refresh the domain details before retrying. Openship does
not adopt another project's route to repair this condition.
Older Cloud adapters could throw `undefined is not an object` while reading
`info?.ssl.status`, even after the provider issued a certificate. Update the
Openship API to a version that accepts both flat and nested provider SSL status
responses, then use **Recheck SSL**. Rechecking reads the existing certificate
and does not request another one.
If you re-run Verify on a domain that's already done, Openship simply replies **"Already verified"** and
changes nothing — that's expected, not an error.
## DNS hasn't propagated yet
The records look correct at your registrar, but Verify still reports the routing or TXT record as not found —
sometimes minutes after you saved them.
**What it means.** DNS isn't instant. After you save a record, it has to spread across the internet's caches
before Openship's lookup can see it. As the DNS Records panel itself notes: *"DNS changes can take up to 48
hours to propagate globally."* Usually it's a few minutes; occasionally it's much longer.
**How to fix**
1. Double-check there are no typos in the **Host** field and no leftover conflicting record for the same name.
2. Wait. Save the records, give it several minutes, then click **Verify** again — re-clicking once DNS
resolves is the reliable path.
3. Openship's enabled-by-default **Domain DNS verification** job runs every 13 minutes. Once a pending
domain is at least 10 minutes old, the job retries verification and certificate issuance automatically.
This also runs in Openship Desktop against the project's connected deployment server. Clicking
**Verify** is the faster, explicit retry; it is not required for the normal background lifecycle.
Manual TXT domains are excluded from this job and wait for **Check TXT & enable HTTPS** instead.
A new custom domain starts **Pending**. Its deployment prepares the route and SSL toolchain. A DNS-01
certificate needs a connected provider, or manual TXT setup after deployment. A missing credential or
certificate failure remains actionable in the domain details; it does not erase the deployed application.
To check what the world currently sees, look the record up directly — e.g. `dig TXT _openship-challenge.app.example.com`
or `dig A app.example.com`. If your own lookup doesn't return the new value yet, Openship won't see it either;
that's a propagation delay, not an Openship problem.
## SSL stuck on "Provisioning" (or no certificate issued)
The domain is **Verified**, but the **SSL** pill stays on **Provisioning** instead of moving to **Active** —
so `https://` doesn't work yet.
**What it means.** On a self-hosted or Desktop-connected server, **Verify** obtains the certificate before
reporting success and rewrites the existing route with TLS. On Openship Cloud, verification can start
certificate issuance in the background. **Provisioning** means issuance is still in progress, its result has
not been observed yet, or the first attempt failed.
**How to fix**
1. Give it a moment, then open the domain's **⋯** menu and click **Recheck SSL**. This is a read-only check
(no certificate is re-issued, no rate limit is spent) that flips the status to **Active** as soon as the
certificate is actually in place.
2. If Recheck reports *"No valid certificate found for \{hostname} yet. If you just deployed, give Let's Encrypt
a moment, then recheck."* — the certificate genuinely isn't there yet. Wait a little longer and recheck
again.
3. The same scheduled domain job retries incomplete issuance with backoff. If you want an immediate retry,
click **Renew SSL**; any real failure reason (DNS, blocked ports, rate limit, ACME outage) surfaces on
that action.
Once a certificate is **Active** you normally never touch it again. Renewal targets certificates within about
two weeks of expiry: on Openship Cloud, and on self-hosted setups where your proxy or edge (Traefik, Caddy, a
load balancer) owns TLS, this is handled for you; a self-hosted operator can also point a scheduled job at the
renew endpoint. **Renew SSL** is the manual fallback if a certificate ever lapses. If you chose manual TXT,
this opens DNS setup for a fresh record; those certificates cannot renew unattended.
SSL actions require a **verified** domain — attempting them on a pending one returns
*"Domain must be verified before SSL can be managed"*. Finish verification first (above), then manage the
certificate.
The first deployment prepares certbot even while the domain is pending. After a successful **Verify**, the
certificate provider re-registers the existing route with TLS, so no redeploy is expected. If a current
deployment only starts serving HTTPS after redeploying, preserve both the deployment log and the Verify log;
that indicates a separate edge/route reconciliation failure.
## External ingress: your edge terminates TLS
Your app already sits behind a Cloudflare Tunnel, a load balancer, or another reverse proxy that handles
HTTPS — but Openship keeps asking for an `A`/`CNAME` and tries to issue its own certificate, which you don't
want.
**What it means.** Standard verification lets Openship manage the certificate. With an external proxy,
that proxy owns public TLS. External ingress keeps certificate issuance out of domain verification;
Cloud still checks ownership, while self-hosted installations accept the operator's configuration.
**How to fix**
1. When adding the domain, turn on **External ingress & TLS**. From the API, pass
`"externalIngress": true` on `POST /api/domains`.
2. On **Openship Cloud**, add the requested `_openship-challenge` TXT record. On **self-hosted instances**,
no DNS record is requested or checked. Configure DNS to reach your proxy, including internal DNS for
a homelab behind Nginx Proxy Manager; a rotating WAN IP does not block this verification mode.
3. Click **Verify**. Openship confirms *"Domain verified — TLS is handled by your external ingress;
no certificate is issued here."* Your proxy must forward requests to the Openship server and serve HTTPS.
An external-ingress domain reads **External TLS** for its SSL status. Verification does not request a
certificate from Openship; maintain the public certificate at your proxy. Any separately configured
origin certificate protects the proxy-to-server connection.
If your edge does **not** handle HTTPS, leave External ingress off — otherwise the domain will verify but
serve plain HTTP, with no certificate from anyone. When in doubt, leave it off and let Openship issue the
certificate.
## Still stuck?
If **Add domain** is rejected before you even reach verification, the hostname failed a basic check — e.g.
`Domain "app.example.com" is already in use` (it's attached elsewhere) or
`"…" is not a valid public hostname.` (a bare IP, `localhost`, a single-label name, or a dot-separated label
longer than 63 characters). Free `*.opsh.io`-style subdomains aren't added here either — those live in the
project's public endpoints, not as custom domains.
---
# Deployment & build failures
URL: https://openship.io/docs/troubleshooting/deployments.md
The build went red — here's how to read the failure and fix the usual causes, from a wrong build command to a compose deploy that needs a decision.
import { Step, Steps } from 'fumadocs-ui/components/steps';
A failed deploy is almost never a mystery. Openship checks your configuration *before* it spends any
resources, and once the build starts it streams every line to the build screen. So the reason is
usually right there in front of you — you just need to know where to look.
Open the build screen (from the project, or the link in your [deploy history](/docs/guides/rollback-redeploy))
and scroll to the bottom. The real error is in the last few red lines. Everything above it is usually
noise. If the deploy stopped *before any build output appeared*, it failed a pre-deploy check — see
[right below](#pre-deploy-checks-failed).
## "Pre-deploy checks failed"
**What you see** — the deploy is rejected almost instantly, with a message like:
`Pre-deploy checks failed: Build configuration: Missing required fields: install command, start command`
**What it means** — Openship runs a set of *preflight* checks the moment you press Deploy, before it
clones anything or starts a build. If any check fails, nothing is provisioned and you get a `403` with
the exact problems listed. This is a good failure: it's cheap, fast, and tells you precisely what to
fix. The most common ones are covered in the sections below.
---
## The framework was detected wrong, or the build command is off
The build runs a command that doesn't match your app — for example it tries `next build` on a plain
Vite app, or the deploy "succeeds" but serves the wrong files.
**What it means** — when you import a repo, Openship inspects it and guesses the framework, package
manager, and the install/build/start commands. It's right the vast majority of the time, but an unusual
project layout (or a repo it can't recognize, detected as **`unknown`**) can lead to a wrong guess.
**How to fix it**
Open your project and press **Deploy** to reopen the [deploy wizard](/docs/dashboard/deploy-wizard). The
current detected values are also shown, read-only, on the project's **Configuration** tab.
On the build/configuration step, correct the **Framework**, **Install command**, **Build command**, and
**Start command** to match what your app actually uses locally. If you build your app with
`npm run build` and start it with `npm start`, those are the values that belong here.
Deploy again. Openship remembers these values for future deploys and redeploys.
If your project is a static site, its application start command is ignored. A file-based release
is served by the edge; a managed Docker deployment serves the built files from its generated web container.
## A Dockerfile image reports `bun`, `npm`, or another command not found
When the selected project root contains a `Dockerfile`, detection selects the Dockerfile build.
Its build instructions and image `ENTRYPOINT`/`CMD` are the defaults, even if the repository also
contains framework configuration, package scripts, or lockfiles. The default port comes from
`EXPOSE`; a package script that the image does not run does not determine the port.
Leave **Start command** empty to use the image's default command. An explicit start command in
project settings or `openship.json` overrides `CMD` and must exist in the final runtime image.
This also applies to Dockerfile apps inside monorepos. An empty override does not make an image
static: the image still runs its own process.
Existing saved commands and previous deployment snapshots are preserved. If an older import saved
an inferred package-manager command, clear that override or set the intended command, then deploy
again. Updating Openship does not recreate existing containers.
## The static build succeeds, but the output directory is missing
**Output Directory** is relative to **Root Directory**, where the build command runs.
For a site in `apps/site` that builds into `apps/site/out`, set:
| Setting | Value |
|---|---|
| Root Directory | `apps/site` |
| Output Directory | `out` |
Do not repeat `apps/site` in Output Directory. Check that the build actually creates the folder
and its intended public files. The release saves this resolved path for routing and rollback;
the repository root is not published in place of a missing build output.
## A required command (or the port) is missing
`Pre-deploy checks failed: Build configuration: Missing required fields: ...` — where the list may
include `install command`, `start command`, `port`, or `build image`.
**What it means** — a server app needs to know how to install dependencies, how to start, and which port
to run on, and every app needs a build image. If any of those is blank, preflight stops the deploy rather
than letting it fail deep into the build. (A missing *build command* is only a warning, not a failure —
see the section above.) For a project made of [multiple services](/docs/guides/compose-multi-service),
the same check reports per sub-app, e.g. *`sub-app "web" missing install command`*.
**How to fix it**
Press **Deploy** to reopen the wizard and fill in whichever field the message named. Every field it
lists must have a value.
If your app **doesn't** need a build step, that's fine — but say so, so Openship doesn't expect a build
command. Likewise, a static site needs no start command or port.
Deploy again.
## The app isn't listening on the right port
The build finishes, then an enabled readiness check reports that the app never answered at its
published address within the configured timeout.
**What it means** — when `readiness.enabled` is `true`, Openship waits for your app to accept a TCP
connection, or return an HTTP status below 500 at the configured `path`. The default timeout is 45
seconds. If nothing answers, the app may have crashed, still be starting, or be listening on a
different port. For single-app deployments, checks run on **Local** and **Server** targets using the
deployment host's own connection. With the default `onFailure: "warn"`, the deployment stays live
with a warning. Only `onFailure: "fail"` rejects the deployment through the existing rollback handling.
If SSH fails or the probe cannot run, the log explicitly reports a **skipped** check and leaves the
deployment unverified. This is not evidence that the app is unhealthy: check the deployment host's
SSH connection and retry. This single-app probe is skipped on **Cloud** and **cluster** targets.
**How to fix it**
Read the runtime logs (the build screen, or the project's **Logs** tab — see
[Logs & monitoring](/docs/guides/logs-monitoring)). If your app logged an error and exited, fix that
first — the "port" message is often just the symptom of a crash.
Make your app bind to the port Openship gives it. Read the port from the environment
(`process.env.PORT` in Node, the equivalent in your language) rather than hard-coding one, and bind to
`0.0.0.0`, not only `127.0.0.1`.
Confirm the **port** on the project's **Configuration** tab matches the port your app actually listens
on. Correct it in the [deploy wizard](/docs/dashboard/deploy-wizard) if it doesn't, then redeploy.
On a Local or Server deploy, if another workload already holds the port, the deploy pauses with a
**Port In Use** dialog. For a single-app Docker deployment using a loopback host port, it also offers
**Use port 20002** (the number varies) when another port can be verified as available. This leaves the
existing workload running and continues with the built image. The app's internal port stays the same;
the selected host port is saved after a successful deployment for future redeploys.
Openship checks both live listeners and saved port reservations, then checks the exact suggestion again
when you choose it. If it is no longer available, the dialog asks again. It never substitutes another
port without your choice. If availability cannot be verified, the alternative is not offered.
The existing **Stop … & Continue**, **I Freed It — Re-check**, and **Cancel Deploy** actions remain
available where appropriate. Choose a stop action only if you recognize the occupant and intend to
stop it. Direct (Bare) apps still use their configured application ports; change those in configuration
if needed. Cancelling preserves the current port.
## The deployment is running, but the app only listens inside its container
An exposed Docker app listening only on `127.0.0.1` or `::1` cannot receive traffic through
its published port. Openship shows **Action required** in the deployment's existing port review
and in Monitoring. This applies to Docker deployments on your servers and Openship Cloud.
The deployment keeps running; this warning does not hold the release or trigger a rollback.
Use **Open settings** to review the app's start command or configuration. If it should receive
routed traffic, configure it to listen on `0.0.0.0` and redeploy. If it deliberately binds to
loopback behind a proxy, route to that proxy instead. Changing only the port number or retrying
routing does not change the app's bind address. **Skip** dismisses this deployment's warning;
it does not repair or expose the app.
The warning requires a confirmed loopback-only listener. An incomplete socket-table read or
unavailable probe does not establish that. Bare apps can legitimately use host loopback and do
not receive this Docker warning. Open **Domains** for a fresh port check after fixing the app.
## The app needs a bigger machine than this one
`Pre-deploy checks failed: Host capacity: PostHog needs 8 GB of RAM (this machine has 2 GB) and
4 vCPU (this machine has 2 vCPU). Install it on a bigger machine, or pick a different destination.`
**What it means** — a few catalog apps are genuinely heavy (a nine-container analytics stack, a
Postgres fork that wants 8 GB) and declare a host floor. Openship reads what your destination's
Docker daemon reports and compares. This is the *first* install of that app, so it stops rather than
letting you watch nine containers get OOM-killed one by one.
**How to fix it**
**Pick a bigger destination.** Reopen the app's install wizard — it states the floor next to the
destination picker and flags a server that's short *before* you install anything.
**Or resize the server** you already chose, then deploy again. The reading is cached briefly, so give
it a minute after a resize.
Once an app has deployed successfully, a shortfall is a warning, never a refusal — otherwise an app
running on a box that turned out to be undersized could never be redeployed. Likewise, a machine
Openship can't measure is never treated as too small, and Openship Cloud is sized from its tier, not
from host hardware. See [Host requirements](/docs/reference/app-catalog).
## The build ran out of memory
The build dies partway through — often with `JavaScript heap out of memory`, a bare `Killed`, or a plain
`exited with code 1`. Openship adds the hint: *"Build process was killed - typically because the target
ran out of memory during the build."*
**What it means** — building a modern app (bundling, type-checking, image optimization) can briefly use a
lot of RAM. When the machine runs out, the kernel kills the build process, and the underlying tool often
reports only a generic non-zero exit. Openship scans the output for the tell-tale signs and surfaces the
real cause.
**How to fix it** — the hint itself spells out the three options:
**Give the build more memory.** Raise the build memory limit for the project (build limits are separate
from runtime limits — see [Sleep mode & resources](/docs/guides/sleep-mode-resources) and the
[Projects API resources endpoint](/docs/api/projects)). On Openship Cloud, pick a larger resource tier.
**Add swap** on your own server so short memory spikes during the build don't get killed.
**Build locally and ship the result.** Switch the build to *"Build on this machine"* in the wizard, or
[deploy a pre-built folder](/docs/guides/deploy-local-folder) so the heavy build happens on your own
hardware.
## A build-time environment variable is missing
The build fails with an error *from your framework* — a reference to an undefined variable, a
`process.env.SOMETHING` that's `undefined`, or a client bundle that's missing a value it needed. A common
case is a `NEXT_PUBLIC_...` value that wasn't set.
**What it means** — your environment variables are passed to the build, not just to the running app. Some
frameworks **bake certain values in at build time** (anything a browser bundle reads, like Next.js
`NEXT_PUBLIC_*`). If that variable isn't set when the build runs, the value is baked in as empty — or the
build errors outright.
**How to fix it**
Add the variable to the project's environment — see
[Environment variables](/docs/guides/environment-variables). Set it for the environment you're deploying
(production vs. preview).
**Redeploy.** Build-time values are frozen into the artifact, so simply adding the variable isn't enough —
you have to rebuild for it to take effect.
## Some services deployed, some failed ("Action Required")
A [multi-service / compose](/docs/guides/compose-multi-service) project finishes with a banner reading
**Action Required**, and a note like *"Some services failed — see service deployments for details."* The
log shows *"Deployed 2/3 services. 1 service still need attention."*
**What it means** — when a project runs several services, Openship deploys each one independently. If at
least one succeeds but others fail, the deploy lands in a special **partial failure** state: the healthy
services are already live, but the deployment is *held for your decision* rather than reported as a clean
success. Nothing is rolled back automatically — Openship waits for you to choose.
**How to fix it**
Open the deployment and look at the per-service results to find which service failed and why. Each failed
service has its own logs — treat it exactly like a single-app failure and use the sections above.
Decide what to do with the deploy:
- **Keep** — accept the services that succeeded and clear the banner. The healthy services stay live.
- **Reject** — roll back the services this deploy changed, returning to the previous state.
If you've fixed the underlying problem, just **redeploy** — starting a new deployment automatically
resolves any pending keep/reject decision, so the banner clears on its own.
You can only keep or reject a deployment that's actually waiting on a decision — acting on any other
deployment returns *"Only a deployment awaiting a decision can be kept."* That's expected; it just means
there's nothing pending.
## A couple of other things you might hit
`A deployment is already in progress (dep_…). Cancel it first or wait for it to complete.` — Openship runs
one deploy per project at a time. Wait for the current one to finish, or cancel it from the build screen,
then try again.
`Docker build failed: docker build exited with code 1` (or a similar generic non-zero exit) means the
failure is inside your build itself, not Openship. Scroll up in the build log to the first red error —
that line is the real cause (a failing test, a TypeScript error, a missing dependency).
Not a build failure at all: this containerized install can't reach the machine it runs on, so the one
step that needs the host (a `:80`/`:443` takeover, the mail engine, a catalog app whose config file is
written on the host) refuses rather than run against the wrong filesystem. Ordinary deploys are
unaffected. The repair differs by install shape —
[Host control channel](/docs/troubleshooting/host-channel).
## Related
---
# Servers & SSH
URL: https://openship.io/docs/troubleshooting/servers-ssh.md
Fix a server that won't connect over SSH, a component that won't install or reports unhealthy, missing Docker, and port-forward tunnels that won't start.
import { Step, Steps } from 'fumadocs-ui/components/steps';
When you deploy to your own machine, Openship reaches it over SSH — the same way you'd type `ssh you@your-box`
in a terminal. Most "my server won't work" problems come down to one of four things: Openship can't log in,
can't reach the box, can't install a tool it needs, or a tool it installed isn't running. This page walks
through each one.
Servers are at **`/servers`**; each server's detail screen is **`/servers/`** with **Overview**,
**Components**, **Security**, **Ports** (desktop app only), and **Terminal** tabs. For the happy-path
walkthrough see [Deploy to your own server](/docs/guides/custom-servers) and the
[Servers dashboard reference](/docs/dashboard/servers). From the terminal, the matching commands live under
[`openship server`](/docs/cli/self-host).
A containerized install reaches **its own host** over a separate SSH channel that Openship provisions
for itself — no credentials you typed, and nothing on the Servers screens. If your symptom is
*"This operation targets the HOST machine, but no host channel is configured"*, a server that reads
**Offline** while its containers are plainly running, or a `:80`/`:443` takeover that won't start, go to
[Host control channel](/docs/troubleshooting/host-channel) instead.
## Two commands that tell you what's wrong
Before fixing anything, find out *which* stage is failing. Two actions answer that:
- **Test Connection** (the button on the server form, or `openship server test-connection --host ...`) tries
only the SSH login, using the details you typed, and **saves nothing**. Use it while you're still guessing at
credentials.
- **Re-check** (the Components tab, or `openship server check `) logs into a **saved** server and
reports which components are installed, healthy, and which required ones are missing.
If Test Connection succeeds but Re-check shows problems, your SSH is fine and the issue is a component. If Test
Connection itself fails, start with the SSH sections below.
## SSH connection fails
### Authentication failed
`Authentication failed - check your credentials`, or a longer line like
`SSH password authentication failed for root@123.45.67.89:22. Check the username/password, or verify that the
server allows password login.` / `SSH key authentication failed for … Check the username, private key,
passphrase, or whether the server accepts this key.`
**What it means.** Openship reached the server, but the server rejected the login. The network is fine — the
username, the secret (password / key / passphrase), or the chosen **auth method** is wrong, or the server
doesn't accept that kind of login.
**How to fix.**
Confirm the **Username** and **Port**. The form defaults to `root` and `22`; if your provider uses a
different user (like `ubuntu`) or a non-standard port, set them explicitly.
Match the **Authentication** method to how you actually log in:
- **Password** — the server must allow password login (`PasswordAuthentication yes` in its sshd config). Many
cloud images disable it.
- **SSH Key** — the **Key Path** must point at a **private** key the machine running Openship can read
(e.g. `~/.ssh/id_rsa`), and the matching public key must be in the server's `~/.ssh/authorized_keys`. Add
the **Passphrase** if the key has one.
- **Agent** — uses the host machine's running `ssh-agent`; see [Agent auth finds no keys](#agent-auth-finds-no-keys).
Verify the same details work from a plain terminal: `ssh -p @`. If that fails too, the fix
is on the server, not in Openship.
Re-run **Test Connection**. A green **Connection successful** means you're good; **Save & Continue to Setup**
persists the server.
When you **Edit** a saved server, leaving the password or key field blank keeps the stored secret. You only
re-enter it when you switch auth method or rotate the credential.
### Can't reach the host (refused, timed out, or unreachable)
A failure that isn't about credentials — the underlying message contains something like `ECONNREFUSED`,
`ETIMEDOUT`, `EHOSTUNREACH`, `ENETUNREACH`, or `SSH connection closed before ready`.
**What it means.** Openship never got as far as logging in. Either nothing is listening on that host and port,
a firewall is dropping the packets, or the address is wrong.
- `ECONNREFUSED` — the host answered but nothing is listening on that **port** (wrong port, or sshd is down).
- `ETIMEDOUT` / `EHOSTUNREACH` / `ENETUNREACH` — the packets never got a reply: wrong IP, or a firewall /
security group is blocking the SSH port.
**How to fix.**
Double-check the **Server IP Address** and **Port**. A typo here is the most common cause.
Confirm the SSH port is open to the machine running Openship — check your provider's firewall / security-group
rules, not just the server's local firewall.
Test raw reachability from the Openship host: `nc -vz ` (or `ssh -p @`). If
that can't connect, the problem is network/firewall, not Openship.
After a couple of consecutive failures Openship trips a short circuit breaker and fast-fails with
`Server is unreachable — cooling down after repeated failures, retry in ~30s.` instead of hammering a dead box
on every check. This is expected — fix the underlying reachability problem, wait out the countdown, then retry.
A single success clears it.
### Connecting through Cloudflare Access
Select **Cloudflare Access** in the server's **Connection** field. Use the Access application hostname,
not a URL or a raw `ProxyCommand`. Passwords, encrypted keys and agent authentication are supported.
If OpenShip reports that `cloudflared` is missing, install it on the machine running the API. Windows
desktop bundles it. An operator can override the executable using the process environment variable
`OPENSHIP_CLOUDFLARED_PATH`; quote Windows paths containing spaces when setting that variable.
Finish Cloudflare authentication as the same OS user running OpenShip, then retry **Test Connection**.
In headless or container installations, an authenticated `cloudflared` session must be available in
that environment. Check that the Access policy permits the account and that the tunnel points to SSH.
Cloudflare and a jump host are separate connection choices. Raw `ProxyCommand` and other options
that execute commands locally are rejected in the server form and API.
### A jump host or extra SSH args seem ignored
You set a **Jump Host** (bastion) or **Extra SSH Arguments** under **Advanced**, but the connection behaves as
if they weren't there.
**What it means.** The **Jump Host** (`-J`) and **Extra SSH Arguments** fields are only applied on the
**Agent** auth path, which drives your operating system's real `ssh` client. Password and SSH-Key auth connect
through an in-process SSH library that does not use those two fields.
**How to fix.**
Switch the server's **Authentication** to **Agent** so the jump host and extra args take effect.
Make sure the key that reaches the final host is loaded in your `ssh-agent` (see the next section), then
**Test Connection** again.
Prefer configuring the bastion once in your `~/.ssh/config` and pointing Openship at the target host — the
Agent path reads your SSH config the same way your terminal does.
### Agent auth finds no keys
**Agent** is selected, but the connection fails as if no key was offered — often surfacing as an
authentication failure.
**What it means.** Agent auth authenticates exactly the way `ssh ` does in your terminal: through the
host machine's `ssh-agent`. Openship looks for the agent socket in `SSH_AUTH_SOCK`, and — because a
GUI-launched desktop app often doesn't inherit that variable — falls back to `launchctl getenv SSH_AUTH_SOCK`
on macOS and `systemctl --user show-environment` on Linux. If no agent (or no loaded key) is found, the login
has nothing to offer and fails. The Agent path is also non-interactive (`BatchMode=yes`), so it never prompts
for a password or passphrase — it must succeed with agent/keys alone.
**How to fix.**
On the machine running Openship, confirm an agent is running and has your key:
`ssh-add -l`. If it lists "no identities", load one with `ssh-add ~/.ssh/id_rsa`.
Confirm plain `ssh @` works from that same machine. If it does but Openship doesn't, the agent
socket isn't being found — restart Openship from a shell that has `SSH_AUTH_SOCK` set, or switch to **SSH Key**
auth and point at the key file directly.
On Windows, the OpenSSH agent is a named pipe rather than a socket and isn't supported on this path — use
**SSH Key** or **Password** auth instead.
## A component won't install or reports unhealthy
Openship installs and health-checks a small set of components on each server: **Docker**, **Git**,
**OpenResty**, **Certbot**, and **rsync**. Docker and Git are the core requirements for deployments; the rest
are optional infrastructure. Manage them from the server's **Components** tab (the **System Health** card) or
with `openship server install`/`check`.
### Docker is missing or the daemon isn't running
`Docker is not installed`, or `Docker is installed but the daemon is not running`.
**What it means.** The health check runs `docker --version` to see if it's installed, then
`docker info` to see if the daemon is actually up. The first message means the binary is absent; the second
means it's present but the background service is stopped.
**How to fix.**
For a missing Docker, use **Install** on the Docker row (or `openship server install -c docker`).
Openship installs it via the official `curl -fsSL https://get.docker.com | sh` script and, on systemd hosts,
enables and starts the service.
If it's installed but not running, start it on the server: `systemctl start docker` (and `systemctl enable
docker` so it survives reboots).
Press **Re-check** (or `openship server check `) — the Docker row should read healthy with a version.
Automated Docker (and OpenResty) installation targets Linux servers. On a non-Linux host you'll see
`Docker installation is only supported on Linux servers` — install Docker yourself, then Re-check.
### A component is installed but "unhealthy"
A row shows a version but is flagged unhealthy, e.g. `OpenResty is installed but not running` or
`OpenResty is running but analytics scripts are not deployed - reinstall to fix`.
**What it means.** The binary exists, but the check for it doing its job failed — the service isn't running,
or (for OpenResty) its managed Lua scripts aren't in place.
**How to fix.**
For "not running", start the service on the server (`systemctl start openresty`) and **Re-check**.
For "analytics scripts are not deployed", use **Reinstall** on that component's row — this re-lays OpenResty's
managed config and scripts without a destructive removal.
Watch the streamed **Install Logs** panel for the real error if a reinstall fails; the last lines name the
package or permission problem.
**Remove** is destructive — removing **OpenResty** takes down the reverse proxy and its managed config until
you install it again. If you only need to refresh scripts or settings, use **Reinstall**.
### An install stops with an error
An install returns an error such as `install_in_progress`, `Invalid component names`, or
`Invalid or missing component name`.
**What it means.**
- `install_in_progress` — a setup session for this server is already running; only one runs at a time.
- `Invalid component names` / `Invalid or missing component name` — the component isn't one Openship installs.
The valid names are `docker`, `git`, `openresty`, `certbot`, and `rsync`.
**How to fix.**
For `install_in_progress`, wait for the running setup to finish (its progress streams live), then start the
new install. On the dashboard the in-progress session simply re-attaches.
For an invalid name, re-run with one of the five supported components — the CLI rejects anything else up front
with `Unknown component(s): … Valid: docker, git, openresty, certbot, rsync`.
If an install genuinely fails, the per-component result carries the underlying error and the failed step is
kept as **Failed** — use **Retry Failed** to re-run only those components.
If SSH and components are all healthy but a *deployment* fails, the problem is in the build or run step, not
the server. Head to [Troubleshooting → Deployments](/docs/troubleshooting/deployments).
## Port-forward tunnels won't start
Port forwarding maps a remote server port to `localhost:` on your own machine (like VS Code's port
forwarding). It's on the **Ports** tab of the server detail screen.
### The Ports tab is missing, or a tunnel returns "Not available"
There's no **Ports** tab, or a tunnel action fails with `Not available in this mode`.
**What it means.** Port forwarding is **desktop-only**. Forwarding a remote port to "localhost" only makes
sense when the Openship orchestrator *is* your own machine, so the feature is hidden on hosted and self-hosted
VPS instances.
**How to fix.** Use the desktop app to manage port forwards for that server. There's nothing to change on the
server itself.
### A tunnel won't open, or a port is rejected
Adding a forward is rejected with `Remote port must be between 1 and 65535` or
`Local port must be 0 (auto) or 1–65535`, or starting one fails — the error shows the underlying reason
(often the same SSH problem as above), or a generic `Failed to start tunnel` when there's no detail.
**What it means.** The first two are validation: the remote port must be a real port, and the local port must
be `0` (let the OS pick) or a valid port. A start failure means the SSH connection couldn't open the forward —
usually the same underlying SSH problem as the sections above, or the local port is already in use.
**How to fix.**
Enter a **Remote port** in `1–65535`, and either leave **Local** as `0` (auto) or pick a free port.
Confirm the server itself connects — open its **Terminal** tab or run **Re-check**. A tunnel rides the same
SSH connection, so if SSH is down the tunnel can't start.
If the start still fails, the OS may have picked a busy local port — set **Local** to `0` so Openship binds any
free port, then **Start** again. **Stop** and **Start** cleanly reopen a stuck forward.
## Still stuck?
---
# Projects, services, and domains
URL: https://openship.io/docs/cli/projects.md
Manage application configuration and related resources from the CLI.
Resource commands use the active [connection context](/docs/cli/access) or your selected
[native configuration](/docs/cli/native).
## Projects
```bash
openship project list
openship project create --name my-app --git-owner my-team --git-repo my-app
openship project get proj_123
openship project rename proj_123 "My application"
openship init --project proj_123
```
`project rename` updates the display name through the same operation as the dashboard.
The project ID, slug, volumes, and live routes keep their existing identities. Manage hostnames
with the domain commands below.
`init` writes a project link in `.openship/project.json`. This is different from `openship.json`, which
declares deployment configuration:
```bash
openship config init
openship config validate
```
See [project commands](/docs/cli/reference/project), [link options](/docs/cli/reference/init), and
[configuration commands](/docs/cli/reference/config).
Links record their context, API and any explicit organization scope. Commands reject a mismatched
connection before using the linked project. Pass `--project` to deliberately select a different target,
or run `init --force` to replace the link.
## Environment and source settings
```bash
openship project env get proj_123
openship project git branch proj_123 main
openship project sleep-mode proj_123 always_on
openship project environment create proj_123 Preview --type preview --branch feature
openship project environment list proj_123
openship project resources get proj_123
openship project resources set proj_123 resources.json
```
Use the project reference for environment writes, auto-deploy, release images, logs, and project
teardown. [Environment variables](/docs/guides/environment-variables) explains secret handling and
when changes reach a running application.
`project environment create` returns a **separate project ID** with its own runtime. Link or deploy that
ID to use it. `project resources set` accepts a JSON patch such as
`{"production":{"cpuCores":1,"memoryMb":1024}}`; the engine enforces the destination's capacity and policy.
Use `project update ` for other build/runtime configuration, `project storage` for object storage
bindings, and `project connections` to wire app outputs into another project's variables.
## Services
```bash
openship service list --project proj_123
openship service get svc_123 --project proj_123
openship service logs svc_123 --project proj_123 --follow
openship service env set svc_123 MODE=production --project proj_123
openship service env inspect svc_123 --project proj_123 --runtime
openship service env apply svc_123 --project proj_123
```
Services belong to a project. Supply the required `--project` flag. The [service reference](/docs/cli/reference/service)
covers creation, Compose synchronization, drift decisions, environment variables, runtime controls, and execution.
Ordinary `env set` changes only the named overrides. `--secret` marks supplied values as secret;
omitting it preserves existing secret classification. `--replace` explicitly replaces all overrides for
the selected variable set. `env delete` removes selected overrides, exposing any inherited values again.
Saving and deleting variables do not restart the service. `env apply` uses the engine's existing container
replacement and rollback workflow; `restart` alone does not apply pending environment changes.
`env inspect` shows effective values with secrets masked and checks the running container only with
`--runtime`. `env reveal ` explicitly reveals selected values and requires write access.
Use `service update --project ` for a JSON configuration patch, including image,
command, build settings, routing, ports and enabled state.
## Domains
```bash
openship domain add app.example.com --project proj_123
openship domain records dom_123
openship domain verify dom_123
openship domain verify-ssl dom_123
```
Follow the returned DNS instructions before verification. See [domain options](/docs/cli/reference/domain)
and the [custom-domain guide](/docs/guides/custom-domains) for DNS providers, TLS, and primary domains.
`dns providers`, `dns credentials` and `dns verify-zone` manage automated DNS access. Use
`domain dns plan` before `domain dns apply` to inspect provider record changes. For DNS certificate
challenges, use `domain dns challenge start`, inspect with `get`, and pass the returned attempt ID to
`check` or `cancel`. Manual challenges require the operator to add the TXT record, including at renewal.
## Catalog apps
```bash
openship app list
openship app get postgres
openship app host-fit postgres --server srv_123
```
`app install` creates an installation draft. Deploy the returned project ID with `openship deploy`.
Custom app definitions, curated settings, and connection details are covered in the
[app reference](/docs/cli/reference/app).
---
# Run and maintain Openship
URL: https://openship.io/docs/cli/run.md
Start a local installation, inspect it, and manage its lifecycle.
Use these commands on the machine that runs Openship. To manage an existing remote installation,
[configure a connection context](/docs/cli/access) instead.
## Start
```bash
openship
```
On a fresh machine, choose **Install Openship on this machine** for the interactive setup. The same
menu also connects to Cloud or an existing self-hosted installation. On an installed machine,
`openship` opens the local control panel or resumes an interrupted setup.
For direct startup:
```bash
openship up
openship status
openship open
```
`up` installs or starts a persistent service. `status` reports local service state and the active
context's API health. `open` opens the dashboard. Use `openship up --foreground` for an attached process.
See [all startup options](/docs/cli/reference/up), including Docker Compose configuration.
The installation owner can use `openship --local project list` without creating or pasting a token.
Local resource commands authenticate with the installation's protected credential; the public API
still requires authentication. See [local and remote access](/docs/cli/access).
## Stop and update
```bash
openship stop
openship update
```
`stop` disables the service so it stays stopped across reboot. `update` updates the CLI and bundled
server. Read [updating Openship](/docs/guides/updating) before updating a production installation.
## Diagnose a problem
```bash
openship doctor
```
The [doctor reference](/docs/cli/reference/doctor) describes health and repair options. Local admin
account recovery uses [reset-admin-password](/docs/cli/reference/reset-admin-password).
## Installation commands compared
| Command | Purpose |
| --- | --- |
| `npm install -g openship` | Install the CLI globally. |
| `npm install openship` | Add Ship SDK and the CLI to a Node project. SDK imports are available in 0.8.0 and later. |
| `openship install` | Download and install the desktop application. |
| `openship install cache` | Inspect or manage cached installation downloads. |
| `openship up` | Start the Openship API and dashboard as a local service. |
| `openship uninstall` | Remove local installation state and data; deployed apps are left running. |
See [installation](/docs/getting-started/installation) for platform requirements and
[command options](/docs/cli/reference#local-installation) before removing or repairing an installation.
---
# Connections and access
URL: https://openship.io/docs/cli/access.md
Authenticate, select an installation, manage tokens, and call HTTP endpoints.
The CLI stores named **contexts** in `~/.openship/config.json`. Each context contains an API URL,
dashboard URL, personal access token, and optional fixed organization. One context is the saved default;
`openship --context production ` selects another for one invocation.
Each command pins its connection settings for the entire invocation. Switching or updating a context
in another terminal affects the next command, including while this command paginates, uploads or watches logs.
## Choose where to connect
The same CLI works on your laptop and on an Openship server:
| Destination | Authentication | Start here |
| --- | --- | --- |
| Openship installed on this server | Automatic for the installation owner, using its protected local credential | `openship --local project list` |
| A remote self-hosted installation | Sign in once with a personal access token | `openship login --api-url https://ship.example.com --context production` |
| Openship Cloud | Sign in once with a Cloud personal access token | `openship login --cloud` |
On a fresh machine, `openship` offers Cloud, an existing self-hosted installation, or installing
Openship on this machine. Choosing a connection does not start a local server. `openship login`
also offers a guided Cloud/self-hosted choice when no endpoint is saved.
## On the installation server
Run the CLI as the OS account that installed Openship. Ordinary resource commands discover the
installed service when there is no remote connection configured. Use `--local` to choose it explicitly,
including after signing into Cloud or another server:
```bash
openship --local project list
openship --local server list
openship --local service list --project proj_123
```
The CLI reads the existing private installation credential, discovers the actual API port, and obtains
a temporary administrator session over loopback. It uses the normal API permissions and signs out
when the command finishes. It does not save that session in your contexts or enable anonymous API access.
An interrupted process's session expires within 24 hours; the next local authentication cleans expired sessions.
Both CLI-managed bare and Docker Compose installations are supported. If you installed under another OS account
or a custom `OPENSHIP_HOME`, run as that account or use the correct installation home with appropriate
permissions. Merely installing the CLI or being another user on the same server does not grant access.
Automatic local authentication requires a server release containing this feature. Older servers can
still use the existing PAT login until upgraded.
`--local` ignores saved and ambient remote credentials. An explicit remote endpoint/context or token
never falls back to local administrator privileges. Local setup, start, stop, and password recovery
continue to manage this machine independently of the active remote context.
## Log in to Cloud or a remote server
```bash
openship login \
--api-url https://ship.example.com \
--context production
```
The CLI opens the dashboard token page and prompts for a token without echoing it. For scripts, use
`--token-file /path/to/token` or `--token-file -` to read stdin. Login validates the token before storing
it and selects the context. Saved credentials are written atomically with owner-only permissions.
For most self-hosted installations, the public dashboard URL is also the API URL. Pass
`--dashboard-url` when they use different origins. Login reuses a saved connection's endpoints;
retargeting its API also updates the default dashboard address. The installed service's remembered
ports take precedence over the local defaults of API port 4000 and dashboard port 3001.
## Switch contexts
```bash
openship context list
openship context use production
openship status
openship --context cloud project list
openship --local project list
```
`context add` stores endpoints and a token without validating them. Use `login` when you want
validation. `context rm` removes an inactive context. `logout` clears a token while keeping its endpoints.
Changing a context's API clears its previous token, organization and capability cache. Authenticate
again for the new endpoint. If `OPENSHIP_TOKEN` is set, logout reports that environment authentication
is still active; unset the variable to stop using it.
```bash
openship logout --context production
```
See the [context](/docs/cli/reference/context), [login](/docs/cli/reference/login), and
[logout](/docs/cli/reference/logout) references for all options.
## Select an organization
```bash
openship access workspaces
openship login --cloud --organization org_123 --token-file /path/to/cloud-token
openship --organization org_123 --json project list
openship --organization org_123 init --project proj_123
```
`--organization` uses the SDK's fixed scope and requires a server that supports it. It never grants access
the credential does not already have. Use the same organization option when deploying a link created
with it. The native configuration selects its own organization.
`OPENSHIP_API_URL`, `OPENSHIP_TOKEN`, `OPENSHIP_ORGANIZATION_ID`, and `OPENSHIP_CONTEXT` can select an
ephemeral connection for CI. They are not saved. An explicit `--context` selects that context's complete
connection and ignores ambient connection variables. See [automation](/docs/cli/automation).
`access` also manages team workspaces, members, invitations and resource grants. See the
[access reference](/docs/cli/reference/access). Changes use the platform's existing permission checks.
## Store provider credentials
```bash
openship credential providers
openship credential create registry.json
openship credential list
openship credential verify credential_123
```
The JSON file contains `provider`, `name`, optional `selector`, and provider `values`. Provider discovery
describes the required fields. Reads return masked secrets; verification failures exit nonzero.
## Create a token
Choose explicit access for each token:
```bash
openship token create deploy-bot --grant project:proj_123:read,write
openship token create report-reader --read-only --expires 30 --full-access
openship token list
```
Pass either `--grant` or `--full-access`; omitting both is refused. A full-access token acts with your
own permissions. Scoped credentials cannot mint unrestricted credentials.
Copy a new token's secret when it is created; later reads show only metadata. Revoke by token ID:
```bash
openship token revoke pat_123
```
See [token options](/docs/cli/reference/token) and [permission scopes](/docs/security/permissions).
## Call an HTTP endpoint
```bash
openship api /projects
openship api /domains --query projectId=proj_123
```
Paths are relative to `/api`. Use `--method` to select a method and `--data` for a JSON body; supplying
data defaults the method to POST. Responses are printed, and non-success HTTP results exit nonzero.
See [raw API options](/docs/cli/reference/api) and the [HTTP reference](/docs/api).
## Native mode
Contexts describe remote HTTP connections. [Native mode](/docs/cli/native) uses an explicitly trusted
configuration file to select an owned installation and identity.
---
# Deploy and manage releases
URL: https://openship.io/docs/cli/deploy.md
Deploy a linked project or local folder, follow logs, and control releases.
First [connect to an installation](/docs/cli/access) or configure [native mode](/docs/cli/native).
## Deploy a Git project
From your repository, link an existing Openship project whose source is configured:
```bash
openship init --project proj_123
openship deploy --watch
```
Use `--project` to select a project without changing the local link. Select a branch, commit,
variable set, or registered server when needed:
```bash
openship deploy --project proj_123 --branch main --env production --watch
openship deploy --project proj_123 --server srv_123 --watch
```
For a preview, first create or select a **non-production project environment** with
`openship project environment create Preview --type preview`,
then deploy its project ID. That row owns its own routes, runtime and active release:
```bash
openship deploy --project proj_preview --env preview --watch
```
`--env` selects stored variables within that project. It does not create a preview runtime or switch
project IDs. Preview variables are refused on a production target before deployment starts.
The explicit `--env` option overrides the default saved by `init --environment`. When using a directory
link, its saved default is used next; otherwise the fallback is `production`. An explicit `--project`
does not inherit a different project's linked branch or variable set.
## Deploy a folder
Upload the current directory explicitly, including from a Git checkout:
```bash
openship deploy --folder --name my-site --watch
```
The CLI stages the directory through the shared SDK source workflow. Outside Git, `--name` also
opts into a folder upload for existing scripts. A project ID alone never opts into uploading the
current directory. Use `--project ` to redeploy from outside the checkout; the stored branch is
used unless `--branch` is supplied.
`--branch`, `--commit`, `--smart-route`, and `--refresh` select the Git path and cannot be combined
with `--folder`. `--service-ids` works for both paths. Archive staging must remain outside the source
tree: the system temporary directory and its ancestors are refused. Select your project directory,
or set `TMPDIR` outside the source tree.
Native directory deployment requires the directory to be inside `policy.sourceRoots`. See
[folder deployment](/docs/guides/deploy-local-folder) for packaging behavior.
## Select what changes
| Option | Behavior |
| --- | --- |
| `--force-all` | Rebuild all enabled services. |
| `--service-ids svc_a,svc_b` | Select services to deploy. |
| `--smart-route` | Use source changes to select affected services. |
| `--refresh` | Reapply environment configuration without pulling source or rebuilding. |
See the [deploy reference](/docs/cli/reference/deploy) for every option.
## Inspect progress
```bash
openship deployment list --project proj_123
openship deployment get dep_123
openship logs dep_123 --follow
openship deployment wait dep_123 --timeout 600000
```
Without `--watch`, deployment submission returns an ID that you can inspect later. A submitted build
is not yet a successful release. Follow the final status and any requested decisions.
Watching or waiting returns a failed exit status for failed releases and pending decisions. Inspect a
decision with `deployment pending`, then use `deployment respond --action ` and wait
again. The CLI never chooses a decision for you. `--watch`, `logs --follow` and `deployment wait` have a
ten-minute default deadline, adjustable with `--timeout` in milliseconds. A timeout stops observation;
it does not cancel the deployment.
`project server-logs --follow` follows request logs using the SDK's authorized self-hosted or
Cloud stream. Unavailable streaming exits nonzero; omit `--follow` to request a recent snapshot.
## Control a release
```bash
openship deployment cancel dep_123
openship deployment redeploy dep_123 --use-existing-commit
openship deployment rollback dep_previous
```
Rollback availability depends on retained artifacts or rebuild support. `pin` retains a deployment's
rollback artifacts; `keep` and `reject` settle releases waiting for a decision.
Use the [deployment command reference](/docs/cli/reference/deployment) for controls and
[rollback guide](/docs/guides/rollback-redeploy) for recovery behavior.
---
# Servers and operations
URL: https://openship.io/docs/cli/self-host.md
Manage servers, backup workflows, mail, and instance configuration.
Connect to a self-hosted installation to manage its SSH servers, mail and instance settings. Project,
backup and managed-server operations also support [Cloud](/docs/cli/cloud) where offered by that provider.
Host and resource permissions still apply in native mode.
## Servers
```bash
openship server list
openship server check srv_123
openship server add --host server.example.com --private-key-file /path/to/key
```
Use the [server reference](/docs/cli/reference/server) to register connections, install components,
set rate limits, and monitor a server. The [Servers API](/docs/api/servers) also exposes container,
Git credential, and tunnel operations. Start with the [server guide](/docs/guides/custom-servers)
for prerequisites.
`--private-key-file` reads a key on the machine running the CLI and submits it through the controller's
normal credential storage. `--key-path` instead refers to a file already on the controller host.
`--password-file` reads a password without placing it in process arguments.
## Backups and restores
The workflow has four parts:
| Step | Commands |
| --- | --- |
| Configure and verify storage | [backup destination](/docs/cli/reference/backup/destination) |
| Choose a source, schedule, and retention | [backup policy](/docs/cli/reference/backup/policy) |
| Inspect executions or prepare a restore | [backup run](/docs/cli/reference/backup/run) |
| Inspect, apply, or cancel a prepared restore | [backup restore](/docs/cli/reference/backup#openship-backup-restore) |
```bash
openship backup destination list
openship backup policy list --project proj_123
openship backup policy run policy_123
openship backup run list --project proj_123
```
Preparing a restore does not apply it. Inspect the returned restore session and confirmation
requirements before using the apply command. See [backups and restores](/docs/guides/backups-restore).
## Mail
Use [mail commands](/docs/cli/reference/mail) to provision or adopt a server, manage domains and
mailboxes, and inspect delivery health. The [email guide](/docs/guides/email-webmail) covers DNS,
relay configuration, and webmail. Mail commands require an HTTP context.
```bash
openship mail certificate get srv_mail
openship mail certificate check srv_mail
openship mail certificate renew srv_mail
openship mail certificate auto-renew srv_mail --state on
```
Renewal and monitoring reuse the platform's edge certificate workflow. Setup reports DNS/PTR checkpoints
as pending work; an interrupted stream is not a successful installation. Use `mail status` before resuming.
## Installation settings and data
Use [system commands](/docs/cli/reference/system) for instance settings, onboarding, filesystem
browsing, and data transfer. Settings have native SDK support; remaining setup and migration actions
require HTTP.
Archive exports contain plaintext credentials. `system data-transfer export --out backup.json` creates
a private file and refuses to overwrite an existing file. Use `--selection selection.json` to choose
projects, history, credentials and dependencies. `system data-transfer preview --schema` describes that
input. Import accepts reviewed mappings and an explicit `--mode merge` or confirmed `--mode wipe --yes`.
Whole-instance actions require an unbound administrator credential; workspace membership alone is insufficient.
## Move or copy workloads
```bash
openship migration scan srv_source
openship migration preview --schema
openship migration preview move.json
openship migration start move.json --yes
openship migration get mig_123
openship migration events mig_123
```
The preview and start use the existing migration inputs, including exact container IDs. Inspect the
returned state and target before `migration cutover mig_123 --token-file token.txt --originals retain --yes`.
Choose `retire` only to authorize source removal. The CLI never substitutes a cutover token or repeats
an uncertain start. Use `respond` for the exact pending prompt and `resume` for reviewed path overrides
or skipped items after a partial transfer.
For moving an installation, follow [control-plane migration](/docs/guides/migrate-control-plane).
For moving a workload, follow [server-to-server migration](/docs/guides/server-to-server-migration).
## Reverse proxy
The [edge workflow](/docs/cli/edge) covers setup, domains, and traffic rules. Its complete options are
in the [edge reference](/docs/cli/reference/edge).
---
# Openship CLI
URL: https://openship.io/docs/cli.md
Deploy applications and manage Openship from your terminal.
Use the CLI to deploy code, inspect releases, and manage Openship Cloud or a remote self-hosted installation
from any machine with Node.js and access to that API. A local Openship server or Docker installation is
not required for remote commands.
## Install
```bash
npm install -g openship
openship --help
```
Node.js 22 or later is required. A local `npm install openship` also provides the command through `npx`.
The reference follows this repository; use `--help` to check your installed version. SDK imports and
native mode are available in `openship` 0.8.0 and later. Newly added commands require a release containing them.
## Connect and deploy
Run `openship` for a guided choice of Cloud, a remote self-hosted installation, or
[installing on this machine](/docs/cli/run). To connect directly:
```bash
openship login \
--api-url https://ship.example.com \
--context production
openship project list
openship init --project proj_123
openship deploy --watch
```
`login` opens the token settings page and asks for a personal access token. `init` links the current
directory to a project. `deploy --watch` submits a deployment and follows its progress.
Use `openship login --cloud` for Openship Cloud. On the server that runs Openship, the installation
owner can use `openship --local project list` with automatic local authentication.
## Choose a workflow
Use `openship job` (alias `jobs`) to manage [scheduled jobs](/docs/guides/jobs), manual runs, and logs.
## Scripts and application code
Use `openship --json project list` for machine-readable command output. See [automation](/docs/cli/automation)
for CI setup and exit handling. To call the same operations directly from JavaScript or TypeScript,
use the [Node.js SDK](/docs/api/sdk).
---
# CLI automation
URL: https://openship.io/docs/cli/automation.md
Use contexts, JSON output, and explicit project IDs in scripts and CI.
## Authenticate a runner
Store a personal access token in your CI secret store. The CLI reads an ephemeral connection from
environment variables without writing the token to disk:
```bash
export OPENSHIP_API_URL=https://api.openship.io
export OPENSHIP_ORGANIZATION_ID=org_123
# OPENSHIP_TOKEN is injected by your CI secret store.
openship --json project list
openship deploy --project proj_123 --watch
```
Use a token with the resource grants needed for the job. `OPENSHIP_CONTEXT` selects a saved context
before applying the environment overrides. An explicit `--context production` uses only the saved
connection, so a token intended for a different API cannot leak into that invocation. An API override
without a replacement token never reuses a saved token from another endpoint.
For a persistent login, `openship login --cloud --token-file /run/secrets/openship` reads a private file;
`--token-file -` reads stdin. Both avoid putting the token in command arguments.
## Use explicit IDs and JSON
```bash
openship --json project list > projects.json
openship deploy --project proj_123 --branch main --watch
```
Put global `--json` before the command. Structured resource commands write JSON to stdout and
diagnostics to stderr. `OPENSHIP_JSON=1` also enables JSON output. Interactive installation commands
retain their command-specific behavior; inspect their help before using them unattended.
Long-running event commands emit one JSON object per line with `event` and `data`. Starting a job,
install, deployment or migration and observing its completion are separate steps. Reattach to an
existing operation after disconnection rather than starting it again.
Login, logout and context mutations also return structured JSON. Login and project selection do not
prompt in JSON or non-TTY mode. Pass credentials and project IDs explicitly. Commands that require
confirmation require `--yes` in automation; `--json` is an output format and does not confirm deletion.
`--project` avoids depending on a directory link. When using `init` in automation, `--yes` fails if
it would need to prompt.
## Handle failure
Check the exit status of each command. Operation and argument errors exit nonzero. A deployment
submission returns an ID before completion; use `--watch` or inspect that deployment before treating
the job as successful.
Use `deployment wait --timeout ` for a structured final outcome or pending decision.
Domain and certificate verification return their result in JSON and exit nonzero when verification
fails, matching human-readable mode. Scripts that previously relied on exit 0 from an unverified JSON
result must handle the nonzero status. Invalid instance import modes and malformed token-expiry values
are rejected before submitting changes.
If a mutation's response is lost, inspect the saved resource before submitting it again. The client
does not automatically replay mutations. Stopping observation does not undo a deployment.
## Native automation
Use [native CLI configuration](/docs/cli/native) to select an explicit installation and organization.
The command drains its owned worker on completion. For a long-running Node application, use
[the SDK directly](/docs/api/sdk/native) and keep the installation open across calls.
---
# Native CLI mode
URL: https://openship.io/docs/cli/native.md
Use supported CLI commands with native SDK storage and providers.
`--native-config` runs supported commands through the native SDK. The configuration selects the
installation, trusted identity, and organization. It is loaded only when you pass it explicitly.
## Create a configuration
Install the [SDK package](/docs/api/sdk/installation) and set a persistent
`OPENSHIP_ENCRYPTION_KEY` of at least 32 bytes. Save this file in your Node project:
```js title="ship-native.config.mjs"
import { resolve } from "node:path";
const encryptionKey = process.env.OPENSHIP_ENCRYPTION_KEY;
if (!encryptionKey) throw new Error("Set OPENSHIP_ENCRYPTION_KEY");
const stateDirectory = resolve("./ship-state");
/** @type {import("openship/native").VerifiedIdentity | null} */
let identity = null;
export default {
options: {
instanceId: "local-cli",
stateDirectory,
storage: { driver: "pglite", dataDir: resolve(stateDirectory, "database") },
encryptionKey,
runtime: "bare",
routing: "none",
administration: true,
policy: { allowHostExecution: true, sourceRoots: [process.cwd()] },
identity: {
resolve: async (/** @type {string} */ assertion) =>
assertion === "local-cli" ? identity : null,
},
},
/** @param {import("openship/native").OwnedShip} ship */
async scope(ship) {
const operator = ship.operator;
if (!operator) throw new Error("Native administration is required");
const person = await operator.ensureIdentity({
issuer: "local-cli",
subject: "me",
email: "me@example.test",
});
identity = { user: person.user, sessionId: "local-cli" };
return { identity: "local-cli", organizationId: person.personalOrganizationId };
},
};
```
This trusted host file selects one local user. A multi-user integration should verify identities through
its own authentication service. Retain the same key, instance ID, and storage when reopening.
## Run a command
```bash
npx openship --native-config ./ship-native.config.mjs --json project create --name my-app
npx openship --native-config ./ship-native.config.mjs --json project list
npx openship --native-config ./ship-native.config.mjs status
```
The CLI creates and starts the installation, selects the scope, runs the command, and drains the
worker before exit. Native project links record their instance and organization; a mismatched
configuration is rejected.
## Supported commands
| Group | Native behavior |
| --- | --- |
| `project`, `app`, `service`, `domain` | Named SDK resource operations. |
| `deploy`, `deployment`, `logs`, `init` | Deployment workflows and project linking. |
| `server`, `backup` | Available operations subject to host/provider policy. |
| `job`, `monitoring` | Shared job and health operations; continuous monitoring remains subject to native job policy and instance authority. |
| `access`, `token`, `credential`, `dns`, `notification`, `webhook`, `audit` | Shared resource operations with the native identity's permissions. |
| `billing`, `github`, `settings`, `analytics` | Shared operations; hosted billing and GitHub access still require their configured providers. |
| `system`, `status`, `doctor` | Supported SDK information/settings operations; remaining host/setup actions have command-specific limits. |
| `edge`, `mail`, `migration`, `api`, login/context, and installation commands | Not accepted by the native command gate; use their normal connection or local-installation mode. |
Interactive terminal subcommands and `system` archive/bootstrap/control-plane migration actions also require an HTTP context. They never fall back to a saved remote context from native mode.
The configuration must be `.mjs`, `.cjs`, or `.js` and export `{ options, scope }`, or a factory returning
that object. `scope` can be a scope object or an async function. Attached `PlatformKernel` instances
are not supported by this CLI mode.
See [native configuration](/docs/api/sdk/lifecycle) for options and
[compatibility](/docs/api/sdk/compatibility) for current platform limits.
---
# Monitoring and automation
URL: https://openship.io/docs/cli/operations.md
Inspect health, configure notifications, manage webhooks and read audit events.
These commands use the same SDK operations, validation and permissions as the control plane.
Pass global `--json` before the command for structured output.
## Health and issues
```bash
openship monitoring issues
openship monitoring summary
openship monitoring health
openship monitoring scan
```
Issue results include counts and the engine's recovery actions. Health results include workload state,
scan freshness and watcher capabilities. Scanning requests a current observation; it does not silently
enable recurring work. Authorized instance administrators can use `monitoring watch enable` or
`monitoring watch disable` to configure the existing health job. The CLI uses the watcher ID and
capabilities returned by the engine, including Cloud and native restrictions.
`project pending ` and `project incidents ` inspect a specific project. Instance-wide
`monitoring rescan` and `monitoring rescan status` require self-hosted administration;
`--health-only` avoids running infrastructure and update jobs.
## Notifications
```bash
openship notification categories
openship notification channel create channel.json
openship notification channel test channel_123
openship notification subscription set deploy.failed --channel channel_123
openship notification deliveries list --limit 50
```
A channel file contains its `kind`, `label` and provider `config`, as defined by the notification API.
The `channel test` command sends a real test notification and exits nonzero if delivery fails.
`notification defaults` manages organization defaults; `subscription` manages personal delivery choices.
## Incoming webhooks
```bash
openship webhook list --project proj_123
openship webhook create webhook.json --project proj_123
openship webhook deliveries --project proj_123 --limit 50
```
The JSON definition selects the name, action and authentication using the shared webhook contract.
Keep returned credential-bearing URLs and secrets private. Use `update` to change configuration,
`rotate --yes` to rotate credentials and `invoke` to execute an action with the caller's permissions.
Delivery pages return `nextCursor`; pass it as `--cursor` for the next page.
## Audit
```bash
openship audit list
openship audit list --query filters.json
openship audit facets
openship audit settings get
```
Audit queries accept the shared filters, dates and pagination fields, for example
`{"resourceType":"project","resourceId":"proj_123","limit":50}`. Administrators can update logging
and retention with `audit settings set `.
See the [command reference](/docs/cli/reference) for every argument and option.
---
# Manage the edge
URL: https://openship.io/docs/cli/edge.md
Set up the reverse proxy, attach domains, apply rules, and inspect traffic.
The edge is Openship's reverse proxy and TLS layer. Use these commands with an authorized HTTP
context on a self-hosted installation. See [the edge guide](/docs/guides/the-edge) for the routing model.
## Inspect and set up
```bash
openship edge status
openship edge up
```
Running `openship edge` opens the interactive panel. The `up` command configures the managed edge;
its [reference](/docs/cli/reference/edge#openship-edge-up) lists target and setup options.
If another reverse proxy owns the HTTP/HTTPS ports, inspect its sites before taking over. Use
`edge takeover` or `edge migrate` only after reviewing their detected configuration and options.
The [existing-proxy guide](/docs/guides/the-edge#taking-over-a-server-thats-already-serving) explains the workflow.
## Domains and rules
```bash
openship edge domains list
openship edge rules list
openship edge sites
```
| Task | Reference |
| --- | --- |
| Add or remove edge hostnames | [Domain commands](/docs/cli/reference/edge#openship-edge-domains) |
| Add or remove access, redirect, or traffic rules | [Rule commands](/docs/cli/reference/edge/rules#openship-edge-rules) |
| Inspect sites managed outside project records | [Sites](/docs/cli/reference/edge#openship-edge-sites) |
| Repair managed edge configuration | [Repair](/docs/cli/reference/edge#openship-edge-repair) |
Project-owned custom domains can also be managed with [domain commands](/docs/cli/reference/domain).
## Inspect traffic
```bash
openship edge logs
openship edge traffic
openship edge analytics
```
The [command reference](/docs/cli/reference/edge) lists filters, time windows, and target options.
For certificate failures, see [DNS and TLS troubleshooting](/docs/troubleshooting/domains-ssl).
---
# Manage Openship Cloud
URL: https://openship.io/docs/cli/cloud.md
Deploy and operate Cloud projects from your laptop, CI runner, or another server.
Use a Cloud token to connect directly to Openship Cloud. Remote commands need Node.js 22 or later and
network access to the API; Docker and a local Openship installation are not required.
## Connect and select a workspace
```bash
openship login --cloud
openship --context cloud access workspaces
openship --context cloud --organization org_123 --json project list
openship --context cloud --organization org_123 server managed list
```
Save the organization during login with `--organization org_123`, or provide it before each command.
The API enforces the token's membership and resource grants. Use a self-hosted API URL and its own
token in another context to manage that installation with the same project and service commands.
## Deploy code or redeploy a project
```bash
openship --context cloud --organization org_123 deploy \
--folder --name my-app --server srv_123 --watch
openship --context cloud --organization org_123 deploy \
--project proj_123 --watch
openship --context cloud --organization org_123 service list --project proj_123
openship --context cloud --organization org_123 project server-logs proj_123 --follow
```
Run the first command inside the source directory. The CLI uploads it through the SDK's source
staging workflow and builds on the selected server. The second command redeploys the project's saved
source and works outside its checkout. Use IDs returned by the resource commands. `--watch` checks
the final outcome and reports pending decisions or failures.
A desktop or self-hosted project can also run on a linked managed server. Connect with the local
context, use `server managed available`, then `server managed connect `, and deploy
to the returned local server ID. Project records remain on that controller. To manage records stored
in Cloud itself, use the direct Cloud context. An owner's Cloud link never expands a scoped token's
authority.
## Inspect or buy capacity
```bash
openship --context cloud billing plans
openship --context cloud billing state --server srv_123
openship --context cloud billing usage --server srv_123 --group-by day
openship --context cloud billing subscription get --server srv_123
```
`--server` resolves that exact server's billing workspace. It does not select another subscription.
Use `--workspace` for a known retained billing workspace.
To obtain another managed server, create its entry and request a checkout for a plan from `billing plans`:
```bash
openship --context cloud server managed create "Production"
openship --context cloud billing subscription create \
--server --idempotency-key
```
Complete payment at the returned URL. Inspect `billing checkout list` and `billing checkout get `
before retrying a purchase whose response was lost. Creating a checkout is not confirmation that
payment or provisioning finished.
For an existing subscription, review the exact quote before confirming a capacity change:
```bash
openship --context cloud billing change preview \
--server srv_123 --idempotency-key
openship --context cloud billing change apply \
--server srv_123 --confirm-restart --yes
```
The server validates the quoted change, current state, ownership and restart consent. Custom capacity
uses `billing quote` and the returned resources and `quoteReference`. See the
[billing reference](/docs/cli/reference/billing) and [managed server reference](/docs/cli/reference/server/managed).
## JSON configuration and useful operations
Complex commands accept a JSON file or `-` for stdin. `--schema` prints the current input schema
without contacting the API, for example `openship project options proj_123 --schema` or
`openship migration project --schema`.
Use `project environment` for isolated environments, `project resources` for runtime limits,
`project database` and `project volume` for managed data, `backup` for recovery, `monitoring` for
issues and updates, and `github` for repositories and server-side build access. Availability depends
on the selected controller and provider; unsupported operations return an error without switching
to another target.
---
# Your first deployment
URL: https://openship.io/docs/getting-started/first-deployment.md
A gentle, screen-by-screen walkthrough of putting one real GitHub app online with Openship — and what "live" actually looks like.
import { Step, Steps } from 'fumadocs-ui/components/steps';
You're about to take some code that lives on GitHub and turn it into a real website that anyone can open. Think
of it like handing a letter to the post office: you give Openship your code, it does the sorting, stamping, and
delivering, and out the other end comes a real web address you can click.
This page is the slow, friendly tour — we stop at every screen and explain what it means. If you'd rather do the
whole thing from the terminal in a couple of commands, the [Quickstart](/docs/getting-started/quickstart) has you
covered.
- Openship is up and running (you can see the dashboard). If not, start with [Installation](/docs/getting-started/installation).
- You have a **GitHub repository** with an app in it — a website, an API, anything.
- You do **not** need Docker, a server config, or any special files. Openship figures those out by reading your repo.
## The walkthrough
### Open a new project
In the dashboard, go to the **Library** page (the **New project** button lands you here too). It opens on the
**GitHub** tab, which shows a list of your repositories.
If this is your very first time, Openship won't have permission to see your repos yet — you'll see a **Connect
GitHub** button instead of a list. Click it, say yes in the GitHub window that pops up, and the list appears.
You only do this once.
### Pick the repository you want
Find your app in the list and click it. Openship reads the repo, works out what kind of app it is, and takes
you to the setup screen. There's nothing to fill in by hand yet — just choose the repo.
### Choose where it should run (you might not see this)
Depending on how you're running Openship, it may first ask **"Where do you want to deploy?"** The choices are
things like one of your **connected servers** or **Openship Cloud** (the managed option, where Openship runs the
app for you).
If Openship already knows where to send your app — there's only one place available, or you chose one the last
time — it skips this screen and takes you straight to setup. So don't worry if you never see it. When you do,
pick one and press **Continue**.
Not sure? The default is fine. This choice isn't permanent — you can move or redeploy the app later.
### Read the setup screen
This is the one screen worth a slow look. Openship has already filled it in for you by reading your code:
- **The framework and commands** — which kind of app it detected, plus the install and build commands it will run.
- **Environment variables** — an area to add any secrets or settings your app needs (like a database address).
Empty is fine if your app doesn't need any.
- **Project name** — a short, unique name for this deployment.
On the right is a summary panel with your repository, its branch, the web address the app will get, and a
**Deploy** button.
For most apps you change nothing here. If you see a field you don't recognize, leave it — the detected defaults
are correct for the large majority of apps.
When it looks right, press **Deploy**.
### Watch it go live
You land on the build screen. Two things are happening here:
- A **row of steps** across the top lights up one by one as each part finishes.
- A **live terminal** streams the build logs as they happen — like watching the oven through the glass door.
You don't have to do anything. When it's done, the title at the top changes to **Deployment Successful** and two
buttons appear: **Visit Site** and **View dashboard**.
## What "live" looks like
When the deployment is done, the build screen shows a **Ready** status in the deployment details, along
with the branch it built, the framework it used, and the **web address** your app now lives at.
Press **Visit Site** and Openship opens that address in a new tab — that's your app, on the internet, for real. 🎉
Openship gives every project a web address automatically — you'll see the exact one on the setup screen and again
in the build details. **Visit Site** just opens it. Prefer your own name, like `yourapp.com`? You can attach a
custom domain afterwards.
**View dashboard** takes you to the project's page, your home base for this app: its deploys, logs, environment
variables, and settings all live there.
## Troubleshooting
Your GitHub connection didn't finish, or Openship wasn't granted access to that repo. Connect again, and when
GitHub asks **which repositories** to allow, make sure yours is included.
Read the last few lines in the build terminal — that's the real reason, in plain text. First-time failures are
almost always one of three things: a missing build command, a missing environment variable, or the app listening
on the wrong port. Fix it in your repo (or in the setup screen), then redeploy.
## Related guides
---
# Installation
URL: https://openship.io/docs/getting-started/installation.md
Every way to get Openship running — the one-line install script, the npm CLI, the desktop app, or a Docker Compose stack.
Openship has a few different front doors, and they all lead to the same place. Think of it like getting a
new appliance: you can grab the quick-start cable (the install script), unpack it with tools you already
own (npm), buy the ready-to-use boxed version (the desktop app), or wire it into your workshop for good
(Docker Compose). Pick the one that fits you — you can always switch later.
- **Just want to try it on your own machine, the fast way?** Use the **install script**.
- **Already have Node.js and npm?** Use the **npm** CLI.
- **Want a clickable app with no terminal at all?** Get the **desktop app**.
- **Running a VPS or server and want it always on? (Recommended)** Install with **Docker** — either the **Docker Compose** stack below or the CLI (`openship up`), which **defaults to Docker/Compose on a Linux VPS**. A **bare** install (no Docker, embedded database) is also fully supported — see [Compose vs bare](#run-openship).
## Install
The fastest way. One command installs the `openship` command as a self-contained, checksum-verified
bundle that runs under **Node** — it uses your system Node when it's recent enough and otherwise fetches
an official Node build just for Openship, never touching your global tools. No Node or npm setup required.
```bash
curl -fsSL https://get.openship.io | sh
```
On **Windows**, run this in PowerShell instead:
```powershell
irm https://git.openship.io/windows | iex
```
Want a specific release instead of the latest? Set `OPENSHIP_VERSION` on the `sh` that runs the script —
not on `curl` — e.g. `curl -fsSL https://get.openship.io | OPENSHIP_VERSION=0.1.9 sh`. (A `VAR=… curl … | sh`
prefix sets the variable only for `curl`; the piped `sh` never sees it.)
The installer adds Openship's bin folder to your `PATH`. If your shell still can't find `openship`,
open a new terminal — or on macOS/Linux run `export PATH="$HOME/.openship/bin:$PATH"` — and try again.
When it finishes you'll have the `openship` command. Now jump to [Run Openship](#run-openship) below.
Already have **Node.js 22 or newer** and a package manager? Install the CLI globally with
whichever one you use:
```bash
npm i -g openship
```
```bash
pnpm add -g openship # pnpm
yarn global add openship # yarn
bun add -g openship # bun
```
That gives you the same `openship` command as the install script. Head to [Run Openship](#run-openship).
This is the one install path that runs on **your** Node — the install script above resolves its
own (system Node when it's 22+, otherwise it downloads one).
If you run `openship` on something older, it doesn't just refuse. It first looks for a Node 22 this
machine has already downloaded and quietly uses that; if there isn't one, it offers to fetch an
official Node 22 (~50 MB, checksum-verified) into `~/.openship/runtime` and use it **for Openship
only** — your system Node is left exactly as it is. Later runs pick it up automatically, so you're
asked once.
Non-interactive (CI, a provisioning script)? `OPENSHIP_VENDOR_NODE=1` accepts that offer without
prompting; `OPENSHIP_VENDOR_NODE=0` declines it. Below Node 20 the CLI cannot run at all, so
without one of those it stops and tells you why; on 20 or 21 it warns and continues.
Version managers (nvm, fnm, volta) keep global packages **per Node version**, so installing a
newer Node leaves the CLI behind with the old one and `openship` drops off your `PATH`. Reinstall
it on the new version:
```bash
npm i -g openship
```
Want to preview an unreleased build — a branch, a tag, or `main` ahead of the next release? This builds the
CLI **from source** (the same way `bun dev` does) and installs it as a **separate `openship-dev` command**:
```bash
curl -fsSL https://get.openship.io/dev | sh
```
Pick a branch/tag with `OPENSHIP_REF` (default `main`) — set it on the `sh` that runs the script, not on
`curl`, or the piped `sh` never sees it:
```bash
curl -fsSL https://get.openship.io/dev | OPENSHIP_REF=my-branch sh
```
The from-source build runs **fully isolated** from a production install — its own home (`~/.openship-dev`),
its own tokens/ports/data, and its own boot service — so your production `openship` is never touched. Use it
just like the normal CLI, under the `openship-dev` name:
```bash
openship-dev # interactive setup + control panel
openship-dev up # run locally
openship-dev update # pull the latest source + rebuild in place (no npm release needed)
```
The build is unverified (no signed release asset) and compiling the dashboard needs real RAM/CPU — small
boxes can OOM. It requires **Bun** and **git**. Not a production path; for production use the install script
or npm above. Remove it with `rm -f "$(command -v openship-dev)" && rm -rf ~/.openship-dev`.
The desktop app bundles the whole thing — the API, the dashboard, and the database — into a single
application you run on your own machine. No server, no Docker: great for local development and for deploying
straight from a folder on your disk.
If you already have the CLI, one command fetches and launches it:
```bash
openship install
```
Or download it directly for your system:
- **macOS** — [Apple Silicon](https://github.com/oblien/openship/releases/latest/download/Openship-arm64.dmg) · [Intel](https://github.com/oblien/openship/releases/latest/download/Openship-x64.dmg)
- **Windows** — [Openship-win32-x64.zip](https://github.com/oblien/openship/releases/latest/download/Openship-win32-x64.zip)
- **Linux** — [Openship.AppImage](https://github.com/oblien/openship/releases/latest/download/Openship.AppImage)
You can also grab them from the [download page](/download).
On **Linux**, make the AppImage runnable, then start it — no installer, no root:
```bash
chmod +x Openship.AppImage
./Openship.AppImage
```
Most Linux distros ship it already. If the AppImage won't start, either install FUSE
(`sudo apt-get install -y libfuse2` on Debian/Ubuntu) or run it self-extracting:
`./Openship.AppImage --appimage-extract-and-run`.
Prefer to run the containers on a server yourself? The self-hosted stack lives in
**`docker/docker-compose.yml`** and **pulls** published images from GitHub Container Registry — no build
tooling required. Run it from the repo root:
```bash
git clone https://github.com/oblien/openship.git
cd openship
cp .env.example .env # then edit the secrets inside
docker compose --env-file .env -f docker/docker-compose.yml up -d
```
It runs five services: **Postgres**, **Redis**, the **API** (`:4000`), the **dashboard** (`:3001`), and an
**OpenResty edge** on **:80/:443** — a container (host networking) that handles routing and Let's Encrypt TLS.
The API mounts the host Docker socket so it can build and run your deployed apps as host containers.
**Linux only** (the edge needs host networking); on macOS/Windows use the CLI (`openship up`) instead.
When it's up, open the dashboard at `http://localhost:3001`.
The stack pulls published images (`ghcr.io/oblien/*`), so it comes up without a build. Pin `OPENSHIP_VERSION`
in `.env` (e.g. `0.2.3`) for reproducible upgrades, then
`docker compose --env-file .env -f docker/docker-compose.yml pull` and `… up -d`. To build from source
instead, add `-f docker/docker-compose.build.yml … up -d --build`.
Copy `.env.example` to `.env` and fill in the secrets **before** you start the stack. To reach it from another
machine, also set `OPENSHIP_PUBLIC_URL` (and `TRUST_PROXY=true` behind a reverse proxy) — otherwise the
dashboard loads but login is rejected.
`openship up` provisions the container→host SSH channel for you; running this file yourself doesn't. The stack
comes up fine and deploys work, but the operations that touch the host machine — a `:80`/`:443` takeover, the
mail engine, a catalog app whose config file is written on the host — refuse until you provision it. The five
manual steps are in `.env.example` under **Host operations from the container**, with the failure mode and
verification in [Troubleshooting → Host control channel](/docs/troubleshooting/host-channel).
The compose file at the repo **root** is the SaaS / from-source **control plane** — it builds from source and
ships the marketing site, with no edge and no Docker socket. It does **not** self-host your apps. For
self-hosting, use `docker/docker-compose.yml` above (or just `openship up`).
## Run Openship
If you installed the CLI (the install script or npm), the quickest start is the **guided setup** — run:
```bash
openship
```
With no arguments, `openship` walks you through it: private or public, your domain (if public), and your
**admin name, email, and password**. It then deploys, creates your admin account, and prints the URL to sign
in. This is the recommended way to stand up a new instance.
Prefer to skip the prompts? `openship up` starts the same background service directly:
```bash
openship up
```
However you start it, on **Linux with Docker** Openship installs the container stack (Postgres, Redis, API,
dashboard, and the OpenResty edge on :80/:443 — the same stack as the Docker Compose tab above), which can
**host your deployed apps on this box** with domains and TLS. This is the **recommended mode for a VPS** and the
CLI default there. Everywhere else (macOS, Windows, or Linux without Docker) it installs a single lightweight
process with a built-in database — an always-on control plane that deploys apps out to a server or the cloud.
Both modes are fully supported; to force the choice, run `openship up --compose` or `openship up --bare`.
Either way, Openship runs as a **background service that starts on boot and restarts itself if it crashes** —
like a delivery truck that always comes back to the depot. It runs the API on `:4000` and the dashboard on
`:3001`, backed by a built-in database in bare mode (or Postgres + Redis in Compose mode). A CLI instance
always requires a login — the admin you create during `openship` setup, or the first account you register in
the dashboard when you run `openship up` directly.
```bash
openship stop # stop the service — it won't restart or come back on reboot
openship up --foreground # run it attached to this terminal instead (a one-off; stop with Ctrl-C)
openship up --no-ui # run the API only, without the dashboard
openship uninstall # remove Openship + its data (see below)
```
### Host control (hardening)
The control plane can operate the machine it runs on: free ports `80`/`443` from an existing proxy, read host
config, scan listening ports, open a host shell. On a Compose install that channel is an **SSH key to the host**
that `openship up` generates and authorizes for the invoking user (reached over the internal
`host.docker.internal` bridge, never the public IP).
Generating a key and writing the address isn't the same as a working channel, and the difference doesn't show
up at install time. Two things on the host decide it: an **sshd** that's listening where containers can reach
it, and a firewall that allows container→host traffic — this address is host-local, so it crosses
`filter/INPUT` where a default-deny `ufw` lives, while every published port is DNAT'd and skips it. So the
stack can read healthy while host operations are dead. `openship up` probes the channel for real and offers the
firewall rule; `openship doctor` re-checks it later. If you install by running `docker/docker-compose.yml`
yourself, none of that is provisioned for you — see the manual steps in `.env.example`. Either way, the repair
and the failure it produces are in
[Troubleshooting → Host control channel](/docs/troubleshooting/host-channel).
You can withhold it:
```bash
openship up --no-host-control
```
With it set: no host key is generated or mounted, host operations refuse with a clear error, and this box stops
being listed as a deploy target ("This Server" disappears). It is **CLI-only on purpose** — a toggle in the
dashboard would be reachable by the very thing it defends against.
**Which posture to use**
| Your box | Recommendation |
|---|---|
| Deploys apps to **itself** (the common single-server install) | **Leave host control on.** It's needed for `:80/:443` takeover, host port scans, and the host terminal. |
| Only manages **remote** servers | **`--no-host-control`.** It gains nothing here, and removes an easy path to host root. |
| Runs alongside workloads you can't risk | `--no-host-control`, and keep the dashboard off the public internet (`OPENSHIP_BIND_ADDR`, or behind your own proxy + auth). |
The API also mounts the host's **Docker socket**, because building and running your apps requires it. A mounted
socket is host-root-equivalent for anyone who can reach it — the same trade every self-hosted deploy platform
makes. `--no-host-control` removes the *easy, exposed* path (a host shell button and a key on disk); it does not
sandbox the control plane. Treat dashboard access as host access, and don't expose it publicly without a proxy
you trust.
### Removing Openship
`openship stop` halts Openship but keeps everything — the database, issued certificates and edge config all
survive, so `openship up` picks up where it left off. To remove it:
```bash
openship uninstall # asks first; removes the stack, its data, its images and ~/.openship
openship uninstall --keep-data # remove the running stack only, keep the database + certificates
openship uninstall --keep-images # don't delete the Openship container images
openship uninstall --yes # skip the confirmation (scripts)
```
Two things it deliberately leaves alone, because a self-hosted box is usually shared:
- **Your deployed apps keep running.** Removing the control plane doesn't stop the containers it created —
`docker ps` still shows them. Delete the projects first if you want those gone too.
- **Nothing is pruned.** Only Openship's own three images (by exact tag) and this stack's volumes are removed;
your other images, volumes and containers are untouched.
When Openship migrated an existing proxy during install, uninstalling frees those ports but can't always
restart what was there before — a completed takeover leaves no record of it. Re-enable your proxy yourself
(`sudo systemctl enable --now nginx`, or caddy / apache2). Its config was never modified.
`openship up` keeps running after you close the terminal. `openship up --foreground` does the opposite: it
stays in your terminal and stops when you press Ctrl-C. Use it for a quick throwaway run, or on a system
where the background service can't be installed.
Under the hood, `openship up` registers with your operating system's service manager so it can survive
reboots:
- **Linux** — a **systemd** unit (`--user` with linger enabled, or a system unit when you run it as root).
- **macOS** — a **launchd** agent that reloads at login.
- **Windows** — a **Scheduled Task** at logon (best-effort; here `openship up --foreground` or the desktop
app are the more reliable options).
On a Linux box without systemd, `openship up` can't install a persistent service. Run
`openship up --foreground` instead, or use the Docker Compose stack for always-on.
### Fully unattended install (headless)
`openship up` on its own installs only the *service* — the first admin is created in the dashboard (or via the
interactive `openship` wizard). Add `--non-interactive` (alias `--yes`) plus the install flags to provision a box
**with no prompts** — admin account and (where supported) domain included. Ideal for CI, cloud-init, or scripted
fleets.
The admin bootstrap and the `byo` / `free` / `none` domain steps run on **both** install methods (Compose and
bare). The one difference is a managed **custom** domain (Openship issues the Let's Encrypt cert itself), which is
wired only for the bare install — see below.
**Bare install** (`--bare`, embedded DB, no Docker) — Openship manages the host's OpenResty, so `--domain-kind
custom` provisions the cert end-to-end:
```bash
OPENSHIP_ADMIN_PASSWORD='a-strong-password' openship up --bare --non-interactive \
--admin-email you@example.com --admin-name "You" \
--domain-kind custom --hostname ops.example.com \
--acme-email you@example.com --edge takeover
```
**Compose install** (the default on Linux with Docker) — the edge runs as a container, and takes every domain kind
the bare install does, including `custom`. If an existing proxy holds `:80/:443`, `--edge` pre-answers what to do
with it (`migrate` imports its sites into Openship's edge first; `takeover` stops it and its sites stop serving):
```bash
OPENSHIP_ADMIN_PASSWORD='a-strong-password' openship up --non-interactive \
--admin-email you@example.com --admin-name "You" \
--domain-kind custom --hostname ops.example.com \
--acme-email you@example.com --edge migrate
```
- **Admin** — `--admin-email` (required) + optional `--admin-name`. The password comes from
`--admin-password` or, preferably, the **`OPENSHIP_ADMIN_PASSWORD`** env var (keeps it out of your shell
history). Idempotent: re-running resets the existing admin's password instead of failing. Works on both methods.
- **Domain** — `--domain-kind`:
- `byo` — front Openship with your own reverse proxy (`--hostname`, or derived from `--public-url`). Both methods.
- `custom` — Openship's edge issues a Let's Encrypt cert for `--hostname`; `--acme-email` and
`--edge migrate|takeover|cancel` pre-answer the `:80/:443` takeover. Both methods: the API picks the host
OpenResty or the container edge from `OPENSHIP_EDGE_MODE`, so the CLI makes the same calls either way.
- `free` — a `.opsh.io` subdomain (`--slug`). **Requires the box to already be connected to Openship
Cloud** (the free-domain connect is an interactive browser step) — connect first, then run the headless
install, or use `byo`.
- `none` (default when no domain flags) — a private box with no public domain.
Any missing or invalid flag exits non-zero with a precise message, so it's safe to script. Certificate issuance
streams its progress as it goes (ACME can take a minute on a fresh domain) and is best-effort: if it doesn't
finish, the install still succeeds and reports why, then retries in the background and on the next boot. Add
`--dry-run` to preview the installed service without provisioning.
## Open it and check it's working
With a local instance running, open the dashboard in your browser:
```bash
openship open
```
Or check the API's health straight from the terminal:
```bash
openship status
```
## Openship Cloud
Don't want to run a server at all? [Sign up for Openship Cloud](https://app.openship.io) — the same platform,
fully managed for you.
## Next steps
---
# Quickstart
URL: https://openship.io/docs/getting-started/quickstart.md
The fastest path from a fresh install to a live app — start Openship, open the dashboard, and deploy one thing.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Just installed Openship? This page gets you to a live app in four short steps. Think of Openship as a
little kitchen that runs on your own computer: you turn it on, open the door, hand it your code, and it
cooks and serves the meal. No servers to rent, no config files to write.
- A computer running macOS, Linux, or Windows.
- Some code you want to put online — a GitHub repo, or a folder on your disk.
- No rented server and no config files — Openship runs on the machine you're on. (On Linux it uses Docker automatically when it's installed; otherwise it runs as a single lightweight process.)
### Install the Openship CLI
The CLI is one small command-line tool. Copy the line for your system and paste it into a terminal:
Already have a package manager? `npm i -g openship` works too (or `pnpm`, `yarn`, `bun`) — that
route needs **Node 22+**, since it runs on your Node rather than bringing its own.
Full options — desktop app, cloud, Docker Compose — are on the [Installation](/docs/getting-started/installation) page.
### Set up Openship
```bash
openship
```
Run **`openship`** with no arguments — the interactive setup walks you through it: your **admin login**
(name, email, password), then whether the instance is private (this machine only) or public (your own domain
+ HTTPS). It deploys, installs itself as an always-on background service (back on reboot, auto-restarts), and
prints your sign-in URL. The **API** runs on `:4000` and the **dashboard** on `:3001`. On Linux with Docker
it brings up the full stack (Postgres, Redis, and an OpenResty edge for domains + TLS); otherwise a single
lightweight process with a built-in database. Nothing else to set up.
`openship up` runs the same install **without** the wizard (no admin is created — you register the first
account in the dashboard). `openship up --foreground` runs it attached to your terminal (Ctrl-C to stop);
`openship stop` stops the service.
The [desktop app](/docs/getting-started/installation) runs Openship on your machine only while it's open,
with no login.
### Open the dashboard
```bash
openship open
```
This opens the dashboard in your browser at `http://localhost:3001`. **Sign in with the admin you created
during setup.** A CLI-managed instance always requires a login — only the
[desktop app](/docs/getting-started/installation) runs with no login. (If you used `openship up` instead of
the wizard, register that first account here now.)
### Deploy one thing
In the dashboard, start a new project and point it at your code — a GitHub repository or a folder on your
disk. Openship looks at your code, figures out what kind of app it is, and shows you a summary. For most
apps you don't change anything: just press **Deploy**.
You land on the build screen, which streams the logs live — like watching the oven through the glass door.
When it finishes, you get a link. Click it, and your app is online. 🎉
## CLI
You can deploy without leaving the shell. First create a project in the dashboard, then from your code
folder:
```bash
cd your-project
openship init # pick which project this folder belongs to
openship deploy # build it and put it online
```
`openship init` writes a small `.openship/project.json` file so later commands know which project to act
on. Add `--watch` to `openship deploy` to follow the build logs until it's done.
## Troubleshooting
The platform isn't up yet. Run `openship up` first (give it a few seconds to become healthy), then try
`openship open` again. Check its state any time with `openship status`.
Open the build screen and read the last few red lines — that's the real reason. First-time failures are
usually a missing build command, a missing environment variable, or the app listening on the wrong port.
## Related guides
---
# Core concepts
URL: https://openship.io/docs/getting-started/core-concepts.md
The plain-language vocabulary the rest of the docs use — organizations, projects, deployments, services, servers, domains, environments, and runtimes.
Openship has a handful of words it uses over and over. Once you know them, the rest of the docs read easily.
Here's a way to hold them together: your code is a **recipe**, Openship is the **kitchen**, and the pages
below are the parts of the kitchen. This page is the short glossary — one idea each, in plain words.
## Organization (workspace)
*Like a shared filing cabinet for you and your team.*
Everything you make in Openship lives inside an **organization** (the dashboard also calls it a workspace).
Your projects, servers, and domains all belong to the organization — not to you personally. That's what lets
a team share them.
You can belong to more than one organization, and each person in one has a **role**: owner, admin, or member.
The role decides what they're allowed to do. See [Permissions](/docs/security/permissions).
## Project
*Like one dish on the menu — one app you want online.*
A **project** is a single app you deploy. It remembers where your code comes from (a GitHub repo or a folder
on disk), how to build it, and everything attached to it: its deployments, web addresses, environment
variables, logs, and settings.
You don't have to configure most of that by hand — Openship looks at your code and fills in sensible
defaults. Making one is covered in the [Quickstart](/docs/getting-started/quickstart).
## Environment
*Like having a real kitchen for customers and a test kitchen for trying recipes.*
An **environment** is a separate copy of your project. The two you'll meet most are:
- **Production** — the live version real people use.
- **Preview** — a throwaway copy for trying changes before they go live.
(There's also a **development** environment for local work.) Each environment keeps its own deployments, its
own environment variables, and its own web address, so testing something never touches what's live.
## Deployment
*Like one printing of a book — every deploy makes a new edition.*
A **deployment** is one attempt to build your code and put it online. Every time you deploy — or, with
auto-deploy on, every time you push to GitHub — Openship makes a new one. Each successful release gets a
version number (v1, v2, v3…) so you can tell them apart.
Only one deployment is **live** at a time. The others are kept as history, so if a new one breaks you can
**roll back** to an earlier one. Each deployment records which commit it built, whether it succeeded, and the
URL it went live at.
## Service
*Like a restaurant with a kitchen, a bar, and a dishwasher — separate stations working together.*
Most projects are one thing. But some apps are really several pieces running side by side — a website, a
database, a cache. Each piece is a **service**. Openship supports two shapes:
- **Compose** — services defined in a `docker-compose` file (for example `web`, `db`, and `redis`).
- **Monorepo** — several apps living in one repository, each built as its own service.
Services can depend on each other, each can have its own public address or stay private, and a single deploy
brings the whole set up together. See [Multi-service & Compose](/docs/guides/compose-multi-service).
## Domain
*Like the street address on your house.*
A **domain** is the web address people type to reach your app, such as `app.example.com`. Openship can give a
project a free address to start with, and you can also connect a custom domain you own.
When you add a custom domain, Openship checks a DNS record to confirm it's really yours, then turns on HTTPS
for you automatically. One domain per project is marked **primary** (the main address). Full details are in the
[Domains API](/docs/api/domains).
## Server
*Like renting a counter in someone else's kitchen — you bring the recipes, they provide the space.*
A **server** is your own remote computer that Openship connects to over SSH to run your apps. You add it once
with its connection details (host, user, and a key or password); after that Openship can deploy to it. One
organization can have several servers.
If you deploy locally or to Openship Cloud, you don't add a server at all. Servers are only for running your
apps on machines you own.
## Runtimes
*Like choosing whether to cook at home, at a friend's place, or order from a restaurant.*
When you deploy, you pick **where the app actually runs**. On the deploy screen this choice is called the
**deploy target**, and there are three:
- **Local** — on the same computer that's running Openship. Great for trying things out on the desktop app.
- **Your server** — on one of your own [servers](/docs/getting-started/core-concepts#server), reached over
SSH and, by default, run inside Docker.
- **Openship Cloud** — Openship runs it for you, no machine of your own required.
You choose it on the deploy screen, and you can move a project between them later. How each one works under
the hood is explained in the [Runtime model](/docs/architecture/runtime-model).
## Related guides
---
# App catalog JSON
URL: https://openship.io/docs/reference/app-catalog.md
The complete field reference for an Openship App definition — the JSON that turns a set of containers into a one-click install, with generated secrets, a curated settings form, and a connection card.
import { TypeTable } from 'fumadocs-ui/components/type-table';
An **App** is a JSON file that wraps a deployment into a one-click, focused experience. Instead of
creating a project, adding a service per container, hand-writing the images and the env that wire
them together, generating and matching a database password across two services, and then hunting
through raw env tabs to change a setting — you click the app, fill a short form, and deploy.
So an App is **not a new runtime**. It is metadata over the normal
[multi-service deploy](/docs/guides/compose-multi-service): a repo-less `services` project marked
`isApp`. Same engine underneath, much shorter path for the user. This page documents every field you
can author. To actually submit one, see [Add an app](/docs/guides/add-an-app).
Add the `$schema` line for editor autocomplete and inline validation:
```json
{
"$schema": "https://openship.io/app.schema.json",
"id": "it-tools",
"name": "IT-Tools",
"description": "A handy collection of developer and sysadmin utilities.",
"kind": "template",
"logo": "it-tools",
"category": "other"
}
```
It is **JSON, not JSONC** — no comments, no trailing commas.
The validator strips keys it does not recognize instead of failing. That is deliberate: it is what
lets a newer app definition stay installable on an older Openship, and it is why growth is always
additive. The trade-off is that a **misspelled field name fails silently** — it is dropped, not
reported, by both the published schema and the server. So keep the `$schema` line and let your editor
autocomplete field names rather than typing them from memory.
## Two kinds
| `kind` | What it does |
|---|---|
| **`template`** | Instantiates the `services` defined in the entry (a backend plus its database, a CMS plus its database, …) and deploys them through the compose/services path. This is the common case. |
| **`flow`** | Provisioning already has a bespoke wizard (for example the mail stack). The entry just points at that wizard via `flowHref`; it does **not** instantiate services. |
## Top level
## Public app pages
The public [Apps directory](/apps) uses the same catalog as the installer. `name`, `description`,
`logo`, `category`, and `tags` provide its cards and search. `unlisted` entries stay hidden;
`available: false` entries appear as coming soon without an install button. Deployment settings
and generated credentials are never included in the website's client data.
Add optional `marketplace` content for the app's detail page:
```json
{
"marketplace": {
"features": [
{ "title": "Private analytics", "description": "Understand your audience without tracking individual visitors." },
{ "title": "Your own database", "description": "Keep analytics data on the infrastructure you choose." }
],
"articleFile": "articles/umami.md"
}
}
```
`features` contains short titles with optional descriptions. For a longer overview, author
`packages/core/src/apps/catalog/articles/umami.md` and reference it with `articleFile`.
The filename must follow `articles/.md`; paths outside that directory are rejected.
Alternatively, use an inline `article` Markdown string. Choose one article source, not both.
Run `bun scripts/gen-catalog.ts` from `packages/core` after editing the JSON or Markdown.
The generator embeds the file as `marketplace.article` in the published `catalog.json` and
removes the authoring path. No separate article request is needed. The website renders
Markdown headings, lists, code, images, and safe links; raw HTML is displayed as text.
Apps without an article still have an overview, their feature summaries, and included services.
Development uses the bundled catalog to preview unpublished changes. Production reads the
published GitHub artifact with a ten-minute cache and falls back to the bundled catalog if
the fetch fails. Marketplace content is presentation only and never changes installation.
## Services
Each entry becomes one container in the created project.
Services reach each other by `name` on the project network. A service named `ghost-db` is reachable
at the host `ghost-db` — which is why a database host in `environment` is just the plain service
name, never an IP or a localhost address.
', description: 'Non-secret env defaults. Supports placeholders.' },
secretEnv: { type: 'string[]', description: 'Env keys on this service that are secrets — forced encrypted and never written as plaintext, whether the value comes from environment or a configField.' },
volumes: { type: 'string[]', description: 'Compose-style volumes. Named volumes are project-scoped.' },
dependsOn: { type: 'string[]', description: 'Other service names this one starts after.' },
healthcheck: { type: 'ComposeHealthcheck', description: '{ test, interval, timeout, retries, startPeriod, disable }. disable:true turns off an image baked-in check.' },
restart: { type: '"no" | "always" | "on-failure" | "unless-stopped"', description: 'Restart policy.' },
command: { type: 'string', description: 'Override the container command.' },
entrypointArgv: { type: 'string[]', description: 'Exact image entrypoint override, mapped to the existing Compose entrypoint. An empty array clears it. Requires minEngine >= 0.9.2.' },
commandArgv: { type: 'string[]', description: 'Exact container command arguments; useful for invoking a mounted startup script through its interpreter.' },
}}
/>
### Service sizing recommendations
Catalog `resources` profiles are advisory. They never become installed CPU or memory
limits on Cloud, Desktop or a connected server, and retrying an installation does not
copy them into saved settings. `minResources` describes recommended host capacity.
Installed services use the user's saved service limits, inheriting project limits only
for omitted dimensions. Without either setting, Docker receives no additional CPU or
memory cap. Existing saved settings and frozen deployment snapshots remain unchanged;
reset a service's limits explicitly to Full capacity if an older installer saved a
catalog profile there.
Cloud services share the selected managed server. Its purchased VM capacity and billing
remain independent of per-container limits. Automatic builds have no additional Docker
CPU or memory limits; Cloud admission keeps them from overlapping other builds on the
same server. A catalog update cannot resize the server or grant credits.
## Building an image
Prefer a published `image` with its supported environment settings. Use top-level `files` and
`commandArgv` when a setup script can run with tools already in that image. WordPress and Odoo
follow this path: their startup helpers are mounted read-only and run before the application
starts, so the customer does not need an image build. Initial account creation must finish
before exposing a public installer, and redeployment must preserve existing accounts and data.
Use `build` when the image actually needs additional software or compiled assets, as with
PocketBase's binary installation. It is an inline Docker build context that Openship
materializes at deploy time and builds on the deploy host through the normal compose build pipeline.
Use `entrypointArgv` with a read-only startup file when a published image has an executable
entrypoint that cannot invoke the helper. Keep its native initialization behavior and gate
the template to Openship 0.9.2 or newer. A build can also set its own `ENTRYPOINT`.
Set **exactly one** of `image` or `build` per service. Neither (nothing to run) and both (ambiguous)
are rejected — `service "" must set exactly one of image|build`.
### COPY paths are prefixed by the service name
This is the rule authors get wrong first. Every buildable service is materialized under a subdir
**named after the service**, inside one shared build context, and `docker build` runs with that shared
root as its context. So COPY/ADD sources are relative to the root, not to the service's own subdir:
```dockerfile
# service "compute", with files: [{ "path": "compute.sh", ... }]
COPY compute/compute.sh /shell/compute.sh # ✅ prefixed with the service name
COPY compute.sh /shell/compute.sh # ❌ COPY source not found → build fails
```
A `files[].path` is relative to the service's own subdir; you COPY it as `/`.
### Values and build args
`{{config:KEY}}` placeholders are resolved in `dockerfile` and in every `files[].content` at install
time, exactly as in `environment` values — so a generated secret or an install-step answer can flow
into the build.
There is **no `args` map**. A build `ARG` the Dockerfile declares is fed from the project's build env:
the runtime passes each env var as `--build-arg`. Declare the value as a normal `environment` entry (or
a `configField`) and reference it with `ARG` in the Dockerfile.
A large base image builds where it deploys. On a small host a heavy build — Neon's compute node pulls a
multi-hundred-MB base — can be slow or memory-bound. That cost is inherent to the app, not to Openship.
## Two field systems
The single most common authoring mistake is mixing these up. There are **two** places to declare env,
split by *role*:
| | `configFields` | `settings` with `installStep: true` |
|---|---|---|
| For | **Machine**-generated or derived env | **Human** inputs the wizard renders |
| Rendered as a form input? | **No** — resolved server-side | **Yes** — text, select, number, … |
| Typical use | `generate: "secret"` / `"jwt"`, `generateGroup` | a name, a toggle, a chosen option |
If you want the user to **fill it in**, it is an `installStep` setting — not a `configField`. Use
`configFields` only for values the operator never types.
## configFields
Generated or derived env only. Each entry maps to one env `key` on one `service`.
```json
"configFields": [
{ "key": "MYSQL_ROOT_PASSWORD", "service": "ghost-db", "label": "Database password",
"generate": "secret", "generateGroup": "ghostdb", "secret": true },
{ "key": "database__connection__password", "service": "ghost", "label": "Ghost DB password",
"generate": "secret", "generateGroup": "ghostdb", "secret": true }
]
```
Both fields share `generateGroup: "ghostdb"`, so one generated password is written to both sides and
the two always match.
## Settings
The curated settings form, grouped. A field with `installStep: true` is also collected in the
install wizard — **this is the human-input surface**. Everything else is day-2 configuration.
Validation is enforced live in the form **and** server-side on save.
Groups:
Fields:
### Form layout
The catalog controls grouping and field widths. The dashboard supplies the controls, spacing,
colors, and responsive behavior through the same form renderer used for installed app settings.
Fields remain defined once in `settings`; only fields with `installStep: true` appear at install.
For a compact install such as Convex, add this at the top level:
```json
{
"installLayout": {
"settings": "split"
}
}
```
`split` puts the editable project name and install fields in two adjacent cards, stacking them
when the available width is too small. Field labels identify each input without an extra card
heading. This suits small forms such as Convex's Name and Instance name.
`single` combines the name and install fields in one card. `grouped` keeps a separate name card
and renders each visible settings group with its label and description. Empty groups are omitted.
Without `installLayout`, the existing separate name card and single vertical settings card remain.
When reopening a draft, its project name stays hidden and the remaining settings use the full width.
`columns` defaults to `1`. Set it to `2` for fields that fit side by side; the form stacks them
when its available width is too small, including when dashboard navigation takes more room.
In grouped mode, a group's own `columns` overrides the install default. That group setting also
applies after installation. Set `fullWidth: true` on a field such as a long textarea to span both
columns. Field order follows the catalog; conditional and advanced visibility still apply.
These optional hints are returned in the catalog API for consumers to render. They do not change
environment values, required-field validation, or routing, and older clients can ignore them.
Use these supported hints rather than CSS classes or executable layout expressions in catalog JSON.
## Connection
The post-install **Connection card**: the URLs and keys a user needs, plus the handover into another
project.
Each output:
### Output sources
An output `source` (and each variant `source`) must match one of these three forms:
| Form | Resolves to |
|---|---|
| `env::` | That env value on that service |
| `publicUrl:` or `publicUrl::` | The public URL for that service, optionally for a specific route |
| `template:…` | A composed string, embedding `{{env:svc:KEY}}` placeholders |
Anything else fails validation, and the `` part must name a declared service.
## Prepare
Commands run **inside** a service container after it starts — never a host shell. Their stdout can
be captured and persisted as an env var (this is how an app like Convex gets its admin key).
A prepare step can run again on a later deploy. Write it idempotently, or gate it with `once`.
The schema accepts `"pre-deploy"`, but **the engine does not run it yet**. Do not rely on it. For
pre-run database initialization use [`files`](#files) to write into
`/docker-entrypoint-initdb.d`, combined with `dependsOn` and a `healthcheck`.
## Endpoints
What the install wizard asks you about — how to reach each port. Omit `endpoints` entirely and
Openship derives one public `http` endpoint per declared route of each exposed service.
Defaults follow the app's intended use on every deployment target:
- Public HTTP endpoints, such as dashboards and APIs, start with **Domain** routing.
- Raw TCP endpoints, such as databases, start **Internal only** unless their `scope` is `public`.
- An explicit `defaultMode` overrides these defaults within `allowedModes`. Use it for choices
such as a port-only API. Local or internal HTTP endpoints default to port-only access.
A Cloud connection only selects the domain provider: a managed free domain when connected,
or a custom domain when disconnected. It does not switch a public UI to port-only routing.
Custom domains still need a hostname and DNS setup. Users can choose another allowed mode;
saved draft choices take precedence over fresh-install defaults.
## Provides and requires
The connection graph between projects. `provides` advertises a connectable bundle; `requires`
declares a connection this app needs **from** another project — the install wizard then offers a
same-org source picker and wires it in one shot. Same-org only, and always user-confirmed.
## Host requirements
`minResources` describes the host capacity recommended for the app. Declare it when
upstream documents a meaningful requirement, such as 8 GB for a multi-service analytics stack.
It does not set container limits.
```json
{
"minResources": { "memoryMb": 8192, "cpuCores": 4 }
}
```
On self-hosted destinations, the installer and deployment preflight compare these
recommendations with the destination's Docker daemon (`NCPU`, `MemTotal`). A shortfall
shows a warning; it never prevents a first installation or redeployment. An unavailable
capacity reading means unknown, and no shortfall is inferred. A 10% tolerance accounts
for memory reserved by the operating system on machines sold with round RAM sizes.
On Cloud, the installer checks the runtime configuration, including service overrides,
against the organization's plan. It offers an upgrade when the allocation does not fit.
Advanced setup remains available to adjust the configuration. Source builds use the
remaining shared pool capacity reported by Oblien, with optional saved build caps;
image-only templates need no source builder. Deployment checks again before queuing work,
and Oblien enforces live capacity atomically when allocating or resizing a workspace.
[`GET /apps/catalog/{id}/host-fit`](/docs/api/apps) exposes this preview. Pass `projectId`
to include an existing draft's saved resource settings. The preview does not modify the
project, allocate resources, or grant a deployment allowance.
## Files
Generated config files bind-mounted into a container at deploy — for apps that need a config *file*,
not just env (an init `.sql`, for example). Supports [placeholders](#placeholders).
`files` are not applied on Openship Cloud.
## Management
Overrides how the installed app is managed.
| Value | Effect |
|---|---|
| `{ "kind": "schema" }` | Render the curated settings form from `settings`. |
| `{ "kind": "custom", "href": "/emails" }` | Send the user to a bespoke surface instead. |
Omit it and Openship derives the behavior: `schema` when `settings` exist, otherwise the raw project
tabs.
## Placeholders
Resolved at install. Usable in `environment` values, `files[].content`, and `connection` outputs:
| Placeholder | Resolves to |
|---|---|
| `{{publicUrl:}}` | That service public URL. Add `:` for a specific route. |
| `{{config:}}` | A generated config value by key — for example a `generate: "secret"`. |
## Localized strings
Several display-only fields accept either a plain string or an inline per-locale map:
```json
{ "title": { "en": "Creating the admin key", "ar": "إنشاء مفتاح المدير" } }
```
This applies to `prepare[].title`, `prepare[].description`, `requires[].label`,
`connection.firstLogin.username` / `password` / `note`, `connection.guide.intro` / `useHint`,
`connection.outputs[].sourceLabel`, and `variants[].label`.
## Validation
Beyond field types, these **referential** checks run at the gate — for both curated and custom
apps — so a dangling reference fails immediately instead of at deploy time:
- Every `service` reference resolves to a declared service — in `configFields`, `prepare`,
`endpoints`, `files`, `settings[].fields`, and `connection.outputs[].service`.
- Every `connection.outputs[].source` and `variants[].source` matches
`env::`, `publicUrl:[:]`, or `template:…`.
- Every `provides[].outputRefs` entry names a real `connection.outputs[].id`.
- Every `jwtSecretGroup` matches a declared `generateGroup`.
- `flowHref` starts with `/` — it can never be an external URL.
- `category` is one of the seven allowed values.
## Stability and versioning
The catalog JSON is a **stable, versioned public API**. Growth is additive and
backward-compatible: new optional fields and new enum members default to prior behavior, and a field
is never repurposed or removed within a schema version.
**One file per app — never author multiple versions.** The repo always holds the single latest file.
An older instance simply keeps the copy bundled in its own build. When an instance is older than an
app `minEngine`:
- the app **is bundled** there → it keeps serving the bundled copy, and may note that an update is
available;
- the app **is brand new** → the catalog shows a guided *Requires Openship ≥ X* card and install is
refused, client and server. Never a silent disappearance.
## See also
- [Add an app](/docs/guides/add-an-app) — how to submit one, and how to upload a custom app
- [Apps API](/docs/api/apps) — the REST surface
- [openship.json](/docs/reference/openship-json) — the per-repo deploy config
---
# openship.json
URL: https://openship.io/docs/reference/openship-json.md
The declarative deploy config for Openship — like vercel.json or railway.toml. Declare framework, build, runtime, env, domains, routes, resources, services and monorepo layout, and Openship deploys the same way every time.
import { TypeTable } from "fumadocs-ui/components/type-table";
`openship.json` is a repo-root file that tells Openship how to build, run, route, and scale a
project. It mirrors what you'd otherwise set in the [deploy wizard](/docs/guides/deploy-from-github),
so a repo becomes "ready to ship on Openship" and [auto-deploy on push](/docs/guides/auto-deploy)
and `openship deploy` become deterministic — no wizard needed.
When refreshing services for a project with a saved subfolder, Openship uses that subfolder's
`openship.json` when present. Otherwise, it uses the repository-root manifest, preserving existing
service definitions and environment defaults. The saved build directory still applies.
Openship **auto-detects** your stack first, then applies every field present in `openship.json` on
top. Fields you omit keep their detected value. So a good `openship.json` is **small** — declare
only what you want to override or pin, not the whole detected config.
Add the `$schema` line for editor autocomplete and inline validation:
```json
{
"$schema": "https://openship.io/openship.schema.json",
"framework": "nextjs",
"port": 3000
}
```
Validate it any time with the CLI:
```bash
openship config init # scaffold a starter openship.json
openship config validate # check it against the schema
```
It's **JSON, not JSONC** — no comments, no trailing commas.
## Build
## Runtime version selection
`runtimeVersion` is one setting shared by runtime policies; it is not a global PHP enum.
The selected or detected stack validates supported versions and chooses matching build/runtime images.
Explicit selection currently supports PHP 8.3 and 8.4 for generated Docker builds. Other runtimes
keep their existing repository detection and defaults; an explicit unsupported selection fails
before a project write or build instead of being ignored.
For the Laravel and Symfony stacks, select a version in the deploy wizard's
build settings or declare it in `openship.json`:
```json
{
"framework": "laravel",
"runtimeVersion": "8.3",
"installCommand": "composer install --no-dev --optimize-autoloader"
}
```
| Selection | Builder | Runtime |
| --- | --- | --- |
| Not declared (unchanged default) | `php:8.4-cli` | `dunglas/frankenphp:1-php8.4-bookworm` |
| `8.3` | `php:8.3-cli-bookworm` | `dunglas/frankenphp:1-php8.3-bookworm` |
| `8.4` | `php:8.4-cli-bookworm` | `dunglas/frankenphp:1-php8.4-bookworm` |
A new selection keeps Composer installation enabled even when there is no JavaScript asset build.
You can disable Build when your source already contains its prepared dependencies.
These are the currently tested selections. Other major/minor or patch selections are rejected.
Both selected stages verify their actual PHP major/minor version. The generated recipe checks
production Composer requirements in the builder and runtime, including PHP and extensions.
[Composer's platform check](https://getcomposer.org/doc/03-cli.md#check-platform-reqs) uses the real
platform, even if `config.platform` or the install command's `--ignore-platform-reqs` pretends otherwise.
An incompatible build fails before activation, leaving the current deployment available.
A declared `buildImage` overrides the managed builder, while the selected FrankenPHP runtime stays
fixed. The custom builder must provide the selected PHP version and support the generated
Composer/extension setup; known incompatible official PHP tags are rejected immediately and
custom images are checked during the build. Changing the version replaces a previously managed
builder default, but does not overwrite a custom builder. When you select a different version with
a custom builder, update both settings together.
This project-level setting applies to generated Docker builds on self-hosted and managed Cloud
Docker destinations. It cannot configure a user-owned Dockerfile, Compose/monorepo service image,
bare runtime, static site, or prebuilt image. Explicit selection on these paths is refused; configure
PHP in their own image instead. Existing projects and user Dockerfiles without `runtimeVersion` are unchanged.
The API and SDK accept `runtimeVersion` in project creation, ensure/update and build options. Send
`null` in project options to restore the default PHP version; custom builder overrides are preserved. Folder scans, the SDK source deployment flow,
and `openship deploy --folder` preserve repository declarations. The CLI validates this field with
`openship config validate`. Version and resolved image references are frozen in each deployment
snapshot; rollback reuses that release's retained application image rather than the latest project
setting. Openship Edge, TLS, routing and resource monitoring continue through the existing deployment path.
## Runtime
## Laravel cache warming
`php artisan optimize` warms Laravel's config, route, event, and view caches. A
warmed web role answers each request faster. The default is off, so an existing
project keeps its exact web command until it opts in.
Warming helps the web role only. It does not fix cold start, because cold start
is dominated by PHP opcode compilation, not cache state. Workers and schedulers
gain little, so leave them unwarmed.
`optimize` runs `config:cache`. `config:cache` freezes whatever environment is
present when it runs. After that, every `env()` call outside `config/*.php`
returns `null`.
Warm the cache at startup, after Openship injects the runtime environment. Do
not warm it in `buildCommand`, which freezes build-time values. Do not warm it
in `releaseCommands`, which runs in a throwaway container whose
`bootstrap/cache` is discarded. Read configuration through `config()` and keep
`env()` inside `config/*.php`.
### Opt-in flag
Set `optimize: true` to warm the web role. The flag prefixes the web command and
keeps the rest of the command unchanged.
```json
{
"framework": "laravel",
"optimize": true
}
```
Warming runs before the server through `&&`. A failing `php artisan optimize`
short-circuits the chain, so the web role never boots. Opt in only when the
command succeeds reliably in your runtime environment.
`optimize: true` always prepends `php artisan optimize && `. Do not also put
`php artisan optimize` in a custom `startCommand`, or it runs twice. The repeat
is harmless but wasteful.
### Override the web command directly
You can warm the web role without the flag. Override `startCommand` and keep the
`exec` form. `optimize` runs first. `exec` then hands PID 1 to FrankenPHP, so
`SIGTERM` still drains in-flight requests.
```json
{
"framework": "laravel",
"startCommand": "php artisan optimize && SERVER_NAME=\":$PORT\" exec frankenphp run --config /etc/frankenphp/Caddyfile --adapter caddyfile"
}
```
Neither the `optimize` prefix nor a manual `startCommand` override is applied to
a Laravel sub-app selected inside a JavaScript-workspace monorepo — a repo root
that declares a `pnpm`, `npm`, `yarn`, or Bun workspace. In that layout the
sub-app's web command is re-derived from the bare preset. This is pre-existing
behavior and not specific to `optimize`. Standalone Laravel repos, and Laravel
repos without a JavaScript workspace at the root, are unaffected.
### Warm a worker or scheduler
Warming a worker gives a small, one-time benefit, so prefer warming the web role
only. To warm a worker anyway, declare it in `roles`, and keep any other roles you
declared there. Prefix its command with `php artisan optimize && ` and keep the
`exec` form. The fields and rules are in
[Runtime roles](#runtime-roles).
```json
{
"roles": [
{ "name": "queue", "kind": "worker", "command": "php artisan optimize && exec php artisan queue:work", "stopGracePeriod": "90s" },
{ "name": "scheduler", "kind": "scheduler", "command": "php artisan optimize && exec php artisan schedule:work", "stopSignal": "SIGTERM", "stopGracePeriod": "10s", "singleton": true }
]
}
```
These are example shutdown budgets. Longer scheduled runs may need a larger grace period on
a Laravel version verified to drain.
## Custom runtime images
Docker source builds offer a **Runtime image** field under Advanced build settings.
It is a production **base** image, separate from the builder and the final application image.
Omit it in `openship.json`, or send `runtimeImage: null` through project options, to restore the managed default.
```json
{
"framework": "laravel",
"runtimeVersion": "8.3",
"runtimeImage": "registry.example.com/team/php-runtime:8.3"
}
```
The stack selects its Docker recipe, even when a custom image has a different name.
A PHP runtime base must provide the selected PHP version, FrankenPHP, `install-php-extensions`,
and the `www-data` user. The recipe checks these capabilities and Composer's actual platform.
Known incompatible official PHP image/version combinations are rejected before settings are saved.
Other custom interpreter images compare the actual builder/runtime fingerprint during the build
(runtime ABI or version, architecture, and libc where applicable). Compiled-native applications
continue through deployment readiness checks. A failed build does not replace the live application.
Overrides must support the generated recipe's shell, directories and package setup.
Use your own Dockerfile for a different server implementation or filesystem layout.
Project-level overrides are refused for bare runtimes, prebuilt images, static extraction and
service-owned Compose/monorepo builds. Those paths manage their images directly.
Omitted options preserve a saved override; `null` clears it. A version change preserves custom
image overrides and validates the new combination. Version, resolved images and the override
flag are frozen in each deployment snapshot, so retained-image rollback restores its original
application without changing the current project settings.
## Release commands
`releaseCommands` runs once per deploy, **after the build and before the new version goes
live**: the place migrations belong. Each command runs in order, its output streams into
the deploy log, and a non-zero exit **fails the deploy**: nothing cuts over, and the
version that was already serving keeps serving.
```json
{
"releaseCommands": ["php artisan migrate --force"]
}
```
Nothing is injected for you. A framework's release set is a choice, so an app with no
`releaseCommands` runs no release phase at all. The equivalents elsewhere:
| Stack | Typical release commands |
| ------- | ------------------------------------ |
| Laravel | `php artisan migrate --force` |
| Rails | `bundle exec rails db:prepare` |
| Django | `python manage.py migrate --noinput` |
Rails uses `db:prepare` rather than `db:migrate` because it also creates the database and
loads the schema when it is empty, which is exactly the state of a first deploy.
Set these commands in **Build settings → Before activation**, `openship.json`, or the
project API/SDK. A repository scan seeds a new project; existing projects keep their saved
commands, including an explicit empty list. The list is frozen on each deployment.
Each command gets the same environment variables as your start command and a 10-minute
budget. It runs once per forward deployment attempt, in list order. Failure, timeout, or
cancellation stops activation and leaves the previous application running.
On Docker, each command runs in a temporary container using the candidate image, the
project's persistent mounts, and its connected-service networks. It publishes no ports
and does not restart. Openship removes the container and its anonymous scratch volumes
afterwards. On Bare, commands run in the staged release directory **after persistent
paths are linked**, before the supervisor changes the running app. When a forward deploy
reuses a retained Bare release, the command gets a temporary copy so it cannot edit the
live application's files.
Only database and mounted-volume changes survive a Docker release container. Put
image-local cache generation, symlinks, and collected assets in the build or start
command. Store SQLite files under a declared persistent path, such as `storage/`, so the
release command and app use the same database on both Docker and Bare.
Release commands currently require a **single-app Docker or Bare deployment**, including
portless workers. A database deployed as its own app and connected to this project keeps it
single-app: the connection is injected as an environment variable, and the release command
reaches the database over the network. Adding any enabled service to the **same project**,
a database included, makes it a multi-service deployment instead, so a deploy with release
commands fails before it builds. To run migrations against a database, deploy the database
as its own app and connect it.
Full Compose/monorepo deployments, static sites, and runtimes without one-off command
support **fail before activation** when commands are configured. Per-service release
commands are not implemented. An action explicitly targeting only selected services skips
the main app's release commands.
Rollbacks skip release commands, including rollbacks that rebuild from Git. Other redeploys
run the commands saved on that deployment, even when they reuse an existing image.
Use idempotent commands and schema changes compatible with the previous application.
**Rolling code back does not undo database changes**, and a command may have made partial
changes before failing. Openship does not promise a transaction across multiple commands.
## Runtime roles
`roles` declares extra long-running processes that run **beside your web app, from the
same built image**: queue workers and schedulers. Each replica is its own container, so a
worker can scale without scaling the web app, and a scheduler runs exactly once.
```json
{
"roles": [
{
"name": "queue",
"kind": "worker",
"command": "exec php artisan queue:work --tries=3",
"replicas": 2,
"stopGracePeriod": "90s"
},
{
"name": "scheduler",
"kind": "scheduler",
"command": "exec php artisan schedule:work"
}
]
}
```
Roles are read from `openship.json` when a project is created from a repository scan.
Like release commands, an existing project
keeps the roles it has saved, so change those through the project API/SDK (`roles`; send
`[]` to remove them). The list is frozen on each deployment, and a project holds at most
20 roles.
### Fields
| Field | Rules |
| ----------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name` | Required. A DNS label: lowercase letters, digits and dashes, starting and ending with a letter or digit, at most 63 characters. Unique within the project. |
| `kind` | Required. `worker` or `scheduler`. `web` is rejected: the web process always comes from `startCommand`. |
| `command` | Required, non-empty. Runs under `sh -c` in the same image as the web app. |
| `replicas` | Optional, workers only. An integer from 1 to 100. Defaults to 1. Cannot be above 1 on a singleton. |
| `singleton` | Optional. Run exactly one instance. A `scheduler` is always a singleton, so `replicas` above 1 on a scheduler is an error. |
| `health` | Optional. `{ "kind": "process" }` or `{ "kind": "exec", "command": "..." }`. `exec` requires a non-empty `command`. `http` is rejected, because roles have no port. |
| `stopSignal` | Optional. A signal name such as `SIGQUIT`, or a positive integer. When omitted, the image's `STOPSIGNAL` applies, or `SIGTERM` if the image sets none. |
| `stopGracePeriod` | Optional. How long to wait after the stop signal before the process is killed: `90s`, `1m30s`, `10m`, or a bare number of seconds. When omitted, the Docker daemon's default stop timeout applies. |
### Where roles run
Source scans expose matching framework roles as `rolePresets`. These are suggestions,
separate from enabled `roles`; scanning a repository never starts a queue or scheduler.
An explicit `roles` array, including `[]`, suppresses suggestions. Presets use file and
dependency evidence, which can include development dependencies: review a suggested
command before enabling it. Explicit roles remain the saved project configuration.
Alternative queue backends share a preset slot; if both match, neither is suggested.
Independent workers do not exclude each other merely because both are workers.
Roles run on **single-app projects deployed to a Docker server**. A deploy that declares
roles is refused **before the build starts**, with no build, release command or container
run, on:
- Openship Cloud
- direct (bare) hosts
- Kubernetes
- multi-service projects (Compose or monorepo)
- static sites
Moving a project that has roles to another server is refused as well.
### What a role container gets
A role container starts from the same image as the web container and gets:
- the web container's environment variables, **without `PORT`**
- the project's persistent storage
- the same resource limits and restart policy
It publishes **no port, gets no route and no network alias**: only the web container
answers to the app's network name. It joins the project network and the networks of any
connected services **before its process starts**, so a worker can reach the database from
its first instruction.
### Deploy order
1. The build runs.
2. Release commands run.
3. Roles start.
4. The web container goes live.
**Workers** start beside the previous version's workers. The old ones keep running, and
are removed only once the new web container is live.
**Singletons** (schedulers, or `singleton: true`) hand over stop-first. A new role continues
a previous one only when it keeps the name, effective singleton status (`kind: "scheduler"` or
`singleton: true`) and the command. For a continued singleton, the old container is stopped
and retained before the new one starts.
Continuation compares saved role fields. It does not detect changes in behavior caused by a
new deployment image, environment, inherited image settings or application code behind an
unchanged command.
A previous singleton that no new role continues is outgoing. A rename, a command change, a
name swap or a change to a scalable worker each make a singleton outgoing. When the deploy
also adds or changes a role, Openship stops and retains each outgoing singleton after the
unchanged workers pass their startup check, and before any added or changed role starts.
Otherwise an outgoing singleton keeps running until the new web container is live.
When unwinding a failed deploy, Openship attempts to remove the new containers and restore
retained singletons. A continued singleton is restored only after its replacement is
confirmed removed. An outgoing singleton is restored only after every added or changed role
is confirmed removed.
This ordering uses the previous deployment's saved role definitions. Without them, only a
singleton that keeps its name hands over stop-first. Runtime failures or an interrupted
deploy can leave containers unresolved. Reconcile them, and restart the scheduler if needed,
before redeploying. A handover does not guarantee exactly-once scheduled execution, so keep
application-level guards such as Laravel's `onOneServer()`.
### Startup check
Every role container must stay up through the stabilization window, **15 seconds** by
default. This check always runs for roles, whatever the project's readiness settings,
because a role has no port to probe. If the role declares an `exec` health command, it
runs once, after the window. A failed startup check fails the deploy and triggers the
rollback attempt described above. The startup check runs only during a deploy.
Afterward, container monitoring watches each recorded role replica through the same
health checks, incident history and notifications as the web container. It checks
process state and restarts; it does not repeatedly execute a role's `health.command`.
Deployments, intentionally stopped projects and loss of the observer's network use
the same alert suppression rules as other workloads.
The command runs under `sh -c`. Without `exec`, the shell stays as the main process and
the stop signal never reaches your worker, so it is killed after the grace period instead
of finishing its job. Write `exec php artisan queue:work`, not `php artisan queue:work`,
and set `stopSignal` and `stopGracePeriod` to match how long a job can run.
`exec` lets the stop signal reach your process. Whether the process exits depends on the
command. For example, Laravel 12.70.0's `schedule:work`, running as PID 1, kept ticking after
SIGTERM until it was killed at the end of the grace period. A longer grace period only delayed
scheduler replacement there.
### Lifecycle
- Pausing, resuming and restarting the project act on its roles too.
- Deleting a deployment removes its role containers.
- Clearing a project's roles retires the running ones on the next deploy.
- Failed retirement produces a deployment warning naming the affected roles and
containers. Deployment reconciliation retries incomplete handover cleanup.
Retention does not reclaim its records or artifacts while recovery is pending.
### Interrupted deployments
New deployments record role identities before Docker creation and record a
singleton stop intent before sending its stop request. After a controller restart,
an unpublished handover removes its replacements before restoring the still-active
predecessor. Once the new web release passed readiness and routing and commit was
recorded, recovery finishes forward instead of restarting an older scheduler.
An unreachable server or uncertain cleanup keeps the handover pending. Another
rollout, project edit or runtime write is refused until recovery finishes, so a
timeout cannot authorize a second scheduler. Explicitly kept containers remain
untouched; deleting that cancelled deployment discards its replacements safely.
Older releases have no handover journal. If an earlier untracked role process is
still present, a new role rollout stops with the container IDs requiring review.
Openship does not delete them solely because their labels name another release.
### Status and logs
**Apps & Services** and **Topology** show the active deployment's roles, their replica
counts, live status, and observed restart counts. Open **View logs** on a replica to
read its output under **Monitoring & Logs**. The runtime log picker also lists role
replicas alongside the application and its companion services.
Status checks only inspect the runtime; they do not start processes or run health
commands. An unreachable server shows unknown status with Retry. A saved log link
is pinned to its deployment, so it cannot silently open a newer release's container.
Role configuration is still set in `openship.json` or through the project API. The SDK
exposes the same read-only inventory and log selection:
```ts
const projectId = "proj_example";
const runtime = await ship.projects.getRuntimeRoles(projectId);
if (runtime.deploymentId) {
const logs = await ship.projects.runtimeLogs(projectId, {
role: "queue",
replica: 1,
deploymentId: runtime.deploymentId,
tail: 100,
});
}
```
From the CLI:
```bash
openship project roles proj_example
openship project logs proj_example --role queue --replica 1 --follow
```
On the server, role containers are named
`openship----`; `docker logs `
remains available for direct inspection.
## Persistent storage
Everything a container writes is discarded when the next version replaces it. `volumes`
names the paths to keep.
A bare path is relative to the app; full compose syntax works too, so you can point a
mount at a specific volume name or a host directory:
```json
{
"volumes": ["storage", "uploads:/app/public/uploads", "/srv/data:/app/var"]
}
```
Omit the field to inherit the framework's own defaults (a Laravel app keeps `storage/`
with no configuration). Declare `[]` to turn persistence off entirely — that is
different from omitting it.
Named volumes are scoped per project, so two projects that both declare `storage` never
share one. On a bare (non-container) deploy the same paths are kept outside the release
directory and symlinked in. Openship Cloud has no volume primitive: a declared mount is
reported and skipped there, so use object storage for uploads instead.
Compose services declare their own mounts under [`services[].volumes`](#services-compose).
## Environment variables
`env` is an object. A value is a plain string, or `{ "value", "secret" }` to mark a secret
(encrypted at rest — never returned to the client afterward). These declarations are active
automatically; a value saved in the dashboard or CLI for the same key overrides the repository default.
```json
{
"env": {
"NEXT_PUBLIC_URL": "https://app.acme.com",
"DATABASE_URL": { "value": "postgres://…", "secret": true }
}
}
```
## Domains
`domains` is an array of hostnames or objects. A bare label (`"myapp"`) is a free
`*.opsh.io`-style subdomain; a dotted hostname (`"app.acme.com"`) is a [custom domain](/docs/guides/custom-domains).
```json
{ "domains": ["app.acme.com", { "domain": "api.acme.com", "port": 8080, "type": "custom" }] }
```
## Routes
`routes` reproduces `vercel.json`-style routing, compiled to the reverse proxy at deploy.
## Resources
CPU/memory limits for the project's containers — a named tier, **or** explicit values (which become
the `custom` tier). See [Sleep mode & resources](/docs/guides/sleep-mode-resources).
The default is **`unlimited`** on both connected and managed Cloud servers. A container
can use the host's available CPU and memory, shared with the other applications on that
server. Select a tier or explicit values only when you want an additional container cap.
The Cloud subscription sets the server's allocation separately. Changing a project's
resource tier never creates or resizes a server.
```json
{
"resources": { "cpuCores": 4, "memoryMb": 8192 }
}
```
## Services (compose)
Declaring `services` makes the project a multi-service (Docker) project — see
[Compose / multi-service](/docs/guides/compose-multi-service). Each entry requires a `name`.
Already have a compose file? Don't re-declare it here — point `composePath` at it and leave
`services` out. That works for a compose file anywhere in the repo (`deploy/docker-compose/`),
under any filename (`stack.yml`), and keeps the file the single source of truth: its services are
re-read on every deploy, and `build:` contexts resolve relative to it, exactly as compose does.
```json
{ "composePath": "deploy/docker-compose/docker-compose.yml" }
```
```json
{
"services": [
{
"name": "web",
"build": ".",
"buildArgs": { "NEXT_PUBLIC_API_URL": null },
"ports": ["3000"],
"exposed": true,
"domain": "app.acme.com"
},
{
"name": "db",
"image": "postgres:17",
"volumes": ["pgdata:/var/lib/postgresql/data"],
"env": { "POSTGRES_PASSWORD": { "value": "…", "secret": true } },
"restart": "unless-stopped"
}
]
}
```
",
description:
"Docker build arguments. null inherits the same-named top-level env value; a string overrides it for this service.",
},
ports: { type: "string[]", description: 'e.g. ["3000"], ["5432:5432"].' },
volumes: { type: "string[]", description: 'e.g. ["pgdata:/var/lib/postgresql/data"].' },
dependsOn: { type: "string[]", description: "Other service names this one depends on." },
env: { type: "env object", description: "Same shape as top-level env." },
command: { type: "string", description: "Override the container command." },
restart: {
type: '"no" | "always" | "on-failure" | "unless-stopped"',
description: "Restart policy.",
},
exposed: { type: "boolean", description: "Publicly routed." },
exposedPort: { type: "string", description: "Which container port is exposed." },
domain: { type: "string", description: "Public hostname for this service." },
healthcheck: {
type: "object",
description: "{ test, interval, timeout, retries, startPeriod, disable }.",
},
resources: {
type: "object",
description:
"Per-service cpu/memory caps, overriding the top-level resources field by field. Same shape; 0 = no limit. Parity with compose mem_limit / deploy.resources.limits.",
},
}}
/>
`dependsOn` takes service names such as `["db"]`, without a port. It controls container startup
order, not database availability during an image build. For `ENOTFOUND db` during `next build`,
see [Database access during a Next.js build](/docs/guides/compose-multi-service#database-access-during-a-nextjs-build).
Top-level `env` is available to Dockerfile builds as well as running containers. Use
`buildArgs` when a service needs an explicit override or when you want the config to document
which Dockerfile arguments it consumes. A service's own `env` is runtime-only and is never shared
with sibling builds. Keep runtime-only credentials in service `env` where possible: Docker build
arguments are not a secret-storage mechanism and can be retained in image metadata or build cache.
A compose file's own limits are honored too — Openship reads `mem_limit` / `cpus` and
`deploy.resources.limits.{memory,cpus}` off each service and applies them over the project-wide
setting.
## Monorepo
`monorepo` overrides Openship's detected sub-apps. Entries in `apps[]` are matched to detected
sub-apps by `rootDirectory` and override their build settings — they don't declare apps from
scratch (the detector finds the apps).
Each override must have a different normalized `rootDirectory`. Declaring a web
process and a worker at the same root is not a supported multi-app declaration.
`openship config validate` rejects duplicate roots; source scans report unmatched
apps and workspace overrides in the configuration diagnostics.
Create a monorepo through the repository import flow, which supplies the detected
app metadata. The API/SDK also accepts that metadata as `monorepoApps`. Setting
`projectType: "monorepo"` (or CLI `project create --type monorepo`) without it now
fails before creating a project. A local CLI import scans the workspace first.
For independent processes without containers, use separate projects pointed at
the required roots and start commands.
```json
{
"monorepo": {
"workspace": { "packageManager": "pnpm", "prepareCommand": "pnpm install && pnpm codegen" },
"apps": [
{ "name": "web", "rootDirectory": "apps/web", "framework": "nextjs", "port": 3000 },
{ "name": "api", "rootDirectory": "apps/api", "framework": "hono", "port": 8080 }
]
}
}
```
`sleepMode`, monorepo `sharedPaths`, and per-app `domain`/`env`/`exposed` are accepted by the
validator but **not applied** — leave them out. Set sleep mode and per-app domains in the
dashboard for now.
## How it maps
| `openship.json` | Deploy wizard / API |
| -------------------------------------------------------------------------------------------------------------- | ------------------------------------------------- |
| `framework`, `packageManager`, `*Command`, `outputDirectory`, `buildImage`, `runtimeVersion`, `runtimeImage`, `productionPaths`, `rootDirectory` | Build settings |
| `port`, `productionMode`, `runtime` | Runtime settings (`hasServer`, runtime isolation) |
| `releaseCommands` | Build settings → Before activation |
| `roles` | No dashboard field: set in `openship.json` or the project API |
| `volumes` | Configuration → Persistent storage |
| `env` | Environment variables (seeded as editable rows) |
| `domains` | Public endpoints / custom domains |
| `routes` | Reverse-proxy routing (`routingConfig`) |
| `resources` | Optional container resource limits |
| `services` | Compose services |
| `monorepo` | Monorepo sub-apps + workspace |
## See also
- [Guide: deploy with openship.json](/docs/guides/openship-json)
- [Deploy from GitHub](/docs/guides/deploy-from-github) · [Auto-deploy on push](/docs/guides/auto-deploy)
## Edit running role configuration
For a single-app Docker deployment, open **Apps & Services → Configure roles** to
add workers or schedulers and adjust worker replicas. Apply creates a configuration
deployment using the active container's immutable image and frozen environment.
It does not rebuild, run release commands, restart web, or rewrite domains. Unchanged
replicas keep their container identities; changed roles use the normal readiness,
singleton handover, cancellation, monitoring and recovery flow. A scheduler remains
one instance. Inspect the configuration deployment's logs if cleanup needs attention.
The editor starts from the **active release's** definitions. Saving also updates the
project's desired roles for later deployments. An explicit `roles` array in
`openship.json` overrides those project settings on the next source deployment;
update the repository when that file is your source of truth. Failed configuration
attempts leave the active release unchanged; its frozen roles remain authoritative.
A normal rollback restores the target release's frozen role definitions and replica
counts through the existing retained-image deployment path.
The SDK exposes `ship.projects.getRuntimeRoleConfiguration(id)` and
`ship.projects.configureRuntimeRoles(id, { expectedDeploymentId, expectedUpdatedAt, roles })`.
The expected release and project timestamp come from the configuration read and
prevent stale edits. CLI equivalents are `openship project role-config ` and
`openship project configure-roles `. The JSON file contains the same
three fields. These controls do not enable runtime roles on Cloud, bare, cluster,
static or multi-service deployments.
---
# Projects
URL: https://openship.io/docs/dashboard/projects.md
Find deployed apps and manage their domains, deployments, workflows, configuration, logs, and backups.
A **project** is one app Openship knows how to build and run. This is where you find every app
you've deployed and go into any one of them to change how it runs. There are two screens: the
**Projects list** (everything at a glance) and the **project detail** screen (one project and
its management tabs).
## The Projects list
Open **Projects** from the left nav. This screen is a single scannable list of every project in
your workspace — one row per project.
Each row shows, left to right: the app's icon (its favicon, or the framework logo), the **name**
and its live version badge, the primary **domain**, the detected **framework**, where it's hosted
(**Cloud**, a **Server** by name, or **Local**), its source (a GitHub repo or a local folder),
the build shape (**Services**, **Static**, or **Standalone**), how long ago it changed, and a
**status pill** (Live, Building, Failed, Draft, and so on). Click anywhere on a row to open that
project.
### Create Project
The **Create Project** button (top-right) takes you to the **Library**, where you pick a GitHub
repository, a local folder, or a template to deploy. See [Deploy from
GitHub](/docs/guides/deploy-from-github) and [Deploy a local folder](/docs/guides/deploy-local-folder).
### Search
Once you have more than three projects, a search box appears above the list. It filters by
**name**, **slug**, and **framework** as you type.
### Filter by target
When your projects span more than one deploy target, a **Filter by target** card appears in the
right column. It groups projects by where they run — **All projects**, **Openship Cloud**, each
connected **server** (by its name), and **Local** — with a count beside each. If you have no
server-hosted projects yet, that column instead shows a **Connect a server** prompt (see
[Custom servers](/docs/guides/custom-servers)).
## The project detail screen
Clicking a project opens its detail screen at the **Overview** tab. The layout is the same on
every tab: a breadcrumb (**Dashboard / _project name_ / _tab_**) and the tab title at the top, the
tab's content in the main column, and a sticky right column with the project card and tab
navigation.
The right-column **project card** shows the current **status**, the **Production** URL (or
**Local** address) with a link out to the live site, and the **Last Deploy** time. When a project
has more than one domain, a domain switcher lets you pick which one the card and Overview
analytics reflect.
### The environment switcher
The pill in the top-right shows the current **environment** (for example **Production**) and its
git branch. Click it to switch between environments, or use the **+** button next to it to spin a
new one up from a branch — pick a branch and Openship creates a matching environment (a `main`
or `master` branch becomes production, anything else a preview). **Manual environment** lets you
name one yourself. Full walkthrough: [Preview environments](/docs/guides/preview-environments).
The three-dot (**⋮**) menu beside the switcher is a **help menu** — Contact Support, Report Issue,
Send Feedback, Documentation, Join Community. The actions that change a project (pause/enable,
delete it) live on the **Advanced** tab, described below.
## Project tabs
Each tab has its own URL under `/projects/{id}/…`, so you can link straight to one. A
**services-only** project (multiple compose services, no single app) hides the **Configuration**
tab, since each service carries its own build config under **Services**.
### Overview
`…/overview` — the project's home. Shows live analytics for the selected domain plus two summary
cards: **Infrastructure** (where and how it runs) and **Source & CI/CD** (the connected repo and
deploy settings). A project that has never deployed successfully shows a focused "ready to
deploy" screen here instead. See [Logs & monitoring](/docs/guides/logs-monitoring).
### Services
`…/services` — for multi-service (docker-compose / monorepo) projects. Lists each service and
lets you start, stop, restart, and configure them individually. See [Compose &
multi-service](/docs/guides/compose-multi-service).
### Domains
`…/domains` — attach web addresses to the project, preview the DNS records they need, verify
them, and manage SSL. See [Custom domains](/docs/guides/custom-domains) and the [Domains
API](/docs/api/domains).
### Deployments
`…/deployments` — the full deploy history. Every build for this project, its status, and the
controls to **redeploy** the latest or **roll back** to an earlier one. See [Rollback &
redeploy](/docs/guides/rollback-redeploy).
### Actions
`…/actions` — workflows linked to this project, their runs, and its deployment rules.
Add a workflow using the same setup as **Actions → New workflow**: select a repository
file or standalone YAML, preview the job topology, then choose runners and triggers.
Choose **Manual**, **On push**, or **After Actions pass** for automatic deployment.
The last option waits for all selected required workflows to pass for the exact commit
and deployment branch. Failed checks remain visible here with retry and cancel controls;
a manual deployment remains available in **Deployments**. Repository push rules need
a reachable control plane, and required checks need its connected GitHub App.
See [Openship Actions](/docs/guides/actions) for inputs, schedules and authenticated webhooks.
### Source
`…/source` — the connected git repository: which repo and branch it deploys from, recent commits,
and automatic deployment settings. Open **Actions** to select workflows that must pass before
a push deploys. Upload/local projects show a "connect a repository" prompt here instead.
See [Auto-deploy on push](/docs/guides/auto-deploy).
### Configuration
`…/runtime` — labeled **Configuration** in the UI. A read-only summary of how a single-app project
builds and runs: framework, package manager, runtime isolation, port, and the install / build /
output / root-directory settings. An **Edit** button reopens the deploy wizard to change any of
them. The project's **environment variables** are edited here too. See [Environment
variables](/docs/guides/environment-variables) and [Sleep mode &
resources](/docs/guides/sleep-mode-resources).
The Configuration tab's route id is `runtime`. Older `…/settings` and `…/build` URLs redirect to
it, just as `…/general` maps to Overview and `…/git` maps to Source.
### Logs
`…/logs` — the project's live output. Switch between the **Terminal** view (streamed runtime
logs) and the **Server** / **Requests** view (HTTP request logs). On multi-service projects you
can pick which service's logs to watch. See [Logs & monitoring](/docs/guides/logs-monitoring).
### Backup
`…/backup` — schedule and manage backups: pick a **destination**, set per-service backup
**policies**, and browse **recent runs** to restore or protect a snapshot from pruning. See
[Backups & restore](/docs/guides/backups-restore).
### Advanced
`…/advanced` — project-level actions and the danger zone. It opens with the **route rules** editor,
then a **Project Info** summary and a **Project Status** card whose **Disable** / **Enable** button
pauses or resumes the project.
**Route rules** apply edge policies to a domain or path prefix, enforced at the OpenResty edge (self-hosted):
per-client **rate limiting** (requests/sec + burst), **bans** (IPs, CIDRs, countries, user-agents, empty
user-agent), **access** allow/deny lists and HTTP-method allow-lists, and **hotlink** protection (allowed
referers). Changes push to the edge live — no reload or redeploy.
The red **Danger Zone** at the bottom holds **Delete Project**. The full delete permanently removes the
project's deployments, domains, environment variables, and analytics. On **self-hosted** instances you also
get a **record-only** option that drops Openship's record of the project but **leaves the running
workload, its data, and its on-server manifest in place** — so you can re-import it later. (Cloud projects
are always fully deleted.)
## Related guides
---
# Backups
URL: https://openship.io/docs/dashboard/backups.md
The Backups page is where you register storage targets — S3 buckets, SFTP hosts, an existing server, or local disk — that your projects back up to.
The **Backups** page (in the sidebar, or at `/backups`) is where you set up the *storage targets* your
backups get written to. Openship calls these **destinations**. Think of a destination as an answer to one
question: "when a backup runs, where do the files go?"
This page manages destinations only. *When* and *what* to back up — the schedule and retention for a given
project — lives on that project's **Backup** tab. See
[Backups & restore](/docs/guides/backups-restore) for the full picture.
You add a destination once here, then any project's backup policy can point at it. A destination shared by
many projects is normal and expected.
## What the screen shows
At the top you get the page title and the subtitle "External storage targets for project and service
backups." When you already have at least one destination, an **Add Destination** button sits in the
top-right.
Each destination is a row in the list, showing:
- An icon and the **name** you gave it.
- A **Default** badge if it's the default destination.
- A **kind** pill — one of *S3-compatible*, *SFTP*, *Existing server*, *Local disk*, or *HTTP upload*.
- A **verification badge**: *Verified* (green), *Failed* (red), *Verifying…*, or *Not verified*.
- A one-line summary of where it points (bucket · region · endpoint, or `user@host:port`, etc.).
- A credentials line (e.g. "Access key stored", "Private key stored", "Reuses server credentials").
On the right of each row: a **Verify connection** button (the refresh icon) and a **⋯** menu with **Edit**,
**Set as default**, and **Delete**.
### First visit (empty state)
Before you've added anything, the page shows "No backup destinations yet" with an **Add Your First
Destination** button and a row of cards under **Supported destinations**:
| Card | Sub-label |
|---|---|
| S3-compatible | AWS · R2 · B2 · MinIO |
| SFTP | Any SSH host |
| Existing server | Reuse SSH creds |
| Local disk | Self-hosted only |
## Add a destination
Press **Add Destination** (or **Add Your First Destination**). A modal opens with two steps.
### Step 1 — pick a kind
Titled "Add backup destination" with the hint "Pick where your backups will be stored." Choose one of four
kinds:
| Kind | Best for | What it is |
|---|---|---|
| **S3-compatible** | Most setups, works anywhere | Any S3-API storage — AWS S3, Cloudflare R2, Backblaze B2, Wasabi, MinIO. |
| **SFTP** | A dedicated backup box or NAS | Push backups over SSH to any host, using new credentials. |
| **Existing server** | Reusing a server you already added | Reuses the SSH credentials of a server from `/servers`. |
| **Local disk** | Self-hosted only | Writes to a directory on the API host. Disabled in cloud mode. |
### Step 2 — configure it
Every kind starts with a **Name** (e.g. "Production R2"). The remaining fields depend on the kind. A lock
icon in the header reminds you that **credentials are encrypted at rest and never displayed back**.
| Field | Notes |
|---|---|
| **Endpoint** | Empty = AWS S3. For R2: `https://.r2.cloudflarestorage.com`. |
| **Region** | e.g. `us-east-1`, or `auto` for R2. |
| **Bucket** | The bucket name, e.g. `my-backups`. |
| **Path prefix** | Optional subpath inside the bucket. |
| **Access key ID** | S3 access key. |
| **Secret access key** | S3 secret (stored encrypted). |
| Field | Notes |
|---|---|
| **Host** | SSH host, e.g. `backups.example.com`. |
| **Port** | Defaults to `22`. |
| **User** | SSH user, e.g. `backup`. |
| **Path prefix** | Remote directory, e.g. `/backups/openship`. |
| **Password** | Leave empty if using a private key. |
| **Private key (PEM)** | Used when the password is empty. |
| Field | Notes |
|---|---|
| **Server** | Pick a server you've already added on the **Servers** page (`/servers`) — it reuses that server's SSH credentials. |
| **Remote path** | Absolute directory on the server, e.g. `/backups/openship`. |
If no servers are configured yet, the form links you to **Servers** to add one first.
| Field | Notes |
|---|---|
| **Absolute path** | A filesystem path on the API host, e.g. `/var/backups/openship`. Disabled in cloud mode. |
Press **Save destination** to finish. A toast confirms "Destination created."
## Verify a destination
Verifying does a real connectivity check against the destination — it confirms the credentials work and the
target is writable, so you find out *now* rather than when a backup silently fails later.
Click the **Verify connection** (refresh) button on a row. The badge flips to *Verifying…*, then settles on
**Verified** (with the last-verified time on hover) or **Failed** (hover shows the error). A toast reports
the result.
Re-verify whenever you edit a destination or rotate its credentials. A green **Verified** badge is the
quickest way to trust a target before you attach a backup policy to it.
## Set the default destination
Open a row's **⋯** menu and choose **Set as default**. That destination gets the **Default** badge — a
convenience marker that flags your go-to target so it's easy to spot in the list. ("Set as default" only
appears on rows that aren't already the default.)
## Edit a destination
From the **⋯** menu, choose **Edit**. The modal opens straight on the configure step (you can't change a
destination's kind after creation). Non-secret fields are pre-filled.
Secret fields (access keys, SFTP password/private key) show `•••••• stored — leave blank to keep`. Leave
them blank to keep the stored value, or type a new value to replace it.
The *S3-compatible*, *SFTP*, *Existing server*, and *Local disk* kinds are editable. An *HTTP upload*
destination can exist but is not editable from this screen.
## Delete a destination
From the **⋯** menu, choose **Delete** and confirm in the dialog.
Deletion can't be undone, and **a destination still used by a backup policy can't be deleted**. Remove or
repoint the policies on the affected projects' **Backup** tabs first.
## Next steps
---
# Billing
URL: https://openship.io/docs/dashboard/billing.md
Manage each Openship Cloud server's coverage, usage, upgrades and payments, including from a linked self-hosted installation.
Billing manages the selected Cloud server. Your own servers are free to manage;
linked self-hosted installations can also manage Cloud billing.
## Choose a server
Select a server in Billing to inspect its own plan, usage and payments. The right
card lists existing servers on usage and history tabs; Plans keeps a compact
selector in the header. **Get server** opens a separate server purchase. A server
without a plan keeps the selector so you can return to another server.
A first purchase shows **Monthly plans** and **Prepaid PAYG**. Monthly plans
and Custom use the same purchase controls. The PAYG pricing preview has resource
tier tabs inside the resource configurator. Each tier shows its shared CPU, RAM, storage
and server allowance, together with the credit-purchase amount needed to unlock it.
Resource inputs stay intact when switching tiers. Configurations above a pool's
limits show the excess and offer a larger tier when one fits.
Choose a credit package to see its qualifying tier and estimate one server's
hourly cost at full CPU usage using the provider's published rates. Spending credits
does not lower a tier. Purchases are not available yet; the displayed selections
do not grant access or change an existing plan.
Both purchase views end with an Enterprise contact card for larger or tailored needs.
## Coverage and usage
Monthly subscriptions include the purchased CPU, RAM and disk for the full paid
month, without another compute-credit allowance. Overview puts **Monthly coverage**
and the paid-through date after plan capacity and usage. Usage shows recorded CPU time and resource measurements.
The server page separates actual usage from provisioned capacity; unavailable
measurements stay unknown.
Monthly servers include managed internet transfer. Billing shows its available
allowance, or **Unlimited** when confirmed by the provider, and current-period
usage. Public app routes and backups are separate. Transfer exhaustion does not
end paid compute coverage. Existing metered subscriptions keep their saved terms
and credit displays; updating Openship does not convert them.
| Tab | What it does |
| --- | --- |
| **Overview** | Current plan, period, coverage and renewal controls. |
| **Usage** | Recorded resource usage over the selected period. |
| **Plans** | Review upgrades or other plans, including Custom resources. |
| **Top-ups** | Shown only for eligible saved metered subscriptions. |
| **Payments** | Unfinished payments, plus invoices and cards in the server's scoped Stripe portal. |
## Finish or cancel a checkout
Open **Pending payments** in the Billing header to find unfinished payments across
your Cloud servers, including servers without an active plan. Connected desktop and
self-hosted installations offer the same recovery flow without creating local
execution links. A server's **Payments** tab lists its own unfinished payments;
the header action lists all of your Cloud servers' payments.
**Resume payment** opens the original checkout with its saved plan and price.
**Cancel payment** closes a supported checkout after the provider confirms it
cannot be paid. If confirmation is still pending, retry cancellation or refresh;
do not start a competing purchase. Payments that have already been submitted link
to their verification status instead.
After confirmed cancellation or expiry, choose another plan or delete the unused
server using the existing delete confirmation. If cancellation is unavailable,
resume the payment, wait for expiry, or contact support.
## Change or cancel a plan
**Review change** shows the provider's amount due now, effective date and projects
that may restart. Upgrades apply after payment. Resource reductions and changes
of billing mode take effect at renewal. Review the actual quote before confirming.
If payment needs authentication, use **Complete payment**. Pending operations stay
visible and can be canceled when allowed; retries reuse the same operation.
After payment, the existing server resize worker applies the approved resources.
If projects changed after review, **Apply plan capacity** asks for an updated
restart confirmation. A resize can be retried without buying the plan again.
Disks can grow but cannot shrink in place; use Custom to retain storage while
reducing other resources, or migrate to another server.
Canceling renewal preserves the paid period. When coverage ends, compute stops
and retained disks follow the saved storage terms. Retention does not mean free
storage: billing continues until deletion, with no automatic deletion at the
minimum retention review date. Overview shows these terms and any storage amount
due. Invoices and cards stay scoped to this server, not other customers or the
provider account.
## Make room for another deployment
Apps and source builds share the managed server. A new project does not reserve
another VM or disk, and container sizes are limits within the existing host.
Image-only installs do not allocate a source builder. Inspect server usage,
stop an idle service if memory is tight, or review a larger plan. See
[Servers](/docs/dashboard/servers) for progress, logs and recovery.
## Credit warnings
Only saved metered subscriptions show low-credit notices. Monthly coverage does
not depend on an old credit balance. See
[credit warnings and recovery](/docs/guides/billing#credit-warnings-and-recovery)
for the metered flow, and the [billing API](/docs/api/billing) for the endpoints.
---
# The dashboard
URL: https://openship.io/docs/dashboard.md
A tour of the Openship dashboard — the sidebar that navigates everything, the home overview, and a map to each area.
The dashboard is your home base. It's a single screen split in two: a **sidebar** down the left that
navigates everywhere, and a large **main area** on the right that shows whatever you picked. There's no top
navbar to hunt through — if you want to go somewhere, it's in the sidebar.
This page orients you to the whole thing: what each sidebar link opens, what the home page is telling you,
and where to click next.
## The sidebar
The sidebar is the rounded panel pinned to the left edge. It stays put as you move around, and the item for
the page you're on is highlighted so you always know where you are.
At the very top you get the **Openship** logo and name, plus two small buttons:
- A **theme toggle** (sun / moon) that flips the whole dashboard between light and dark.
- A **collapse** button ("Collapse sidebar") that shrinks the panel to just icons to give the main area more
room. Press it again ("Expand sidebar") to bring the labels back.
### Navigation links
The links are grouped into labelled sections — **Main**, **Settings**, and **Infrastructure**.
| Section | Item | Route | What's there |
|---|---|---|---|
| Main | **Home** | `/` | The overview page (below) — your projects, quick links, and recent activity. |
| Main | **Projects** | `/projects` | Every project in the workspace. Click one to open its detail view. See [Projects](/docs/dashboard/projects). |
| Main | **Deployments** | `/deployments` | A feed of every build across your projects. See [Rollback & redeploy](/docs/guides/rollback-redeploy). |
| Main | **Backups** | `/backups` | Register the storage targets your backups write to. See [Backups](/docs/dashboard/backups). |
| Settings | **Settings** | `/settings` | Account, team, GitHub connection, tokens, and MCP. See [Settings](/docs/dashboard/settings). |
| Settings | **Billing** | `/billing` | Plan and usage — shown on Openship Cloud (or a cloud-connected instance). See [Billing](/docs/dashboard/billing). |
| Infrastructure | **Servers** | `/servers` | Managed Cloud servers or your own connected machines. See [Servers](/docs/dashboard/servers). |
| Infrastructure | **Emails** | `/emails` | The self-hosted mail stack and Zero webmail. See [Emails](/docs/dashboard/emails). |
The sidebar adapts to your instance. **Billing** shows only on Openship Cloud or a self-hosted instance
that's connected to Cloud. **Servers** is available in both, with controls suited to each server.
**Emails** appears only on a self-hosted instance.
### New Project
Just below the navigation is the bright **New Project** button. It takes you to the
[**Library**](/docs/dashboard/library) (`/library`), where you start a deployment — from a GitHub repo, a
local folder, a URL, or a template. It's the same place the "Import Git" shortcut on the home page leads to.
Start with [Deploy from GitHub](/docs/guides/deploy-from-github) — it walks the New Project → Library →
Deploy flow click by click.
### Workspace switcher
At the bottom sits the **Account** area. If you belong to more than one organization, this is a workspace
switcher: it shows the active organization's name (and either "N workspaces" or your email underneath).
Click it to open a popover titled **Switch organization**, pick another org, and the dashboard reloads
scoped to it. The current org is marked **Current** with your role beside it.
That same popover holds your signed-in identity and the **Log out** button. (On the desktop app the button
reads **Back to setup** instead, which returns you to the local setup screen.)
## The home page
Clicking **Home** (or the logo) lands you on the overview at `/`. It opens with a greeting — "Good morning /
afternoon / evening" with your first name — and the subtitle "Here's what's happening across your projects".
The body is a two-column layout.
### Your Projects
The main panel is **Your Projects** — the projects in this workspace with a count and a **View all** link to
`/projects`. It lists up to six; if you have more, a "View all N projects" link sits at the bottom. Click any
row to open that project.
If you have no projects yet, this panel becomes a welcome card ("Launch your first project") with two
buttons — **Create project** and **Import from GitHub** — both of which take you to the Library to get
started.
### Quick links
Under the projects panel is a row of four shortcut cards:
| Card | Goes to | For |
|---|---|---|
| **Import Git** | `/library` | Starting a project from a repository. |
| **MCP Deploy** | `/settings?tab=mcp` | Connecting an AI agent to deploy for you — see [MCP](/docs/mcp). |
| **Settings** | `/settings` | Your account and team. |
| **Docs** | Opens the docs | This documentation, in a new tab. |
### Activity and recent
The right-hand column is sticky (it follows you as the left side scrolls) and summarises the workspace at a
glance:
- **Activity** — a small scoreboard: total **Projects**, total **Deployments**, and your overall build
**Success rate** (green when healthy, amber or red when it needs attention).
- A contextual **tip** card ("Quick Tip") that changes with your state — connect GitHub, create your first
project, or open project settings; once GitHub is linked it shows your connected account instead.
- **Recent** — your latest projects, each with a coloured status dot, its status label, and how long ago it
changed. Click one to jump straight into it.
- An **All systems operational** note once you have active projects running.
## A map of the dashboard
Each area has its own page or guide with the details. Here's where to go next:
---
# Settings
URL: https://openship.io/docs/dashboard/settings.md
The Settings screen — GitHub connection, deploy defaults, tokens, MCP, team, notifications, audit log, cloud, and instance controls, one tab at a time.
Settings is where you configure everything that isn't tied to a single project: how you connect to
GitHub, where new deployments land by default, the tokens and AI clients that talk to your API, who's on
your team, and how this install itself is run and updated.
Open it from the dashboard's left navigation (the **Settings** item), or go straight to **`/settings`**. The
screen has a tab nav on the right (a horizontal strip on mobile) that switches between sections. Each tab
is also directly linkable with a `?tab=` query — e.g. `/settings?tab=team` — so you can bookmark or share the
exact place you mean.
The **Cloud** tab is hidden on the managed Openship Cloud — it shows on self-hosted and desktop installs
only. The **Audit log** tab is always listed, but the log itself loads only for **admins and owners**
(members get an empty feed). Within **Instance**, the **Updates** and **data export/import** sections appear
only where they make sense — a self-hosted or desktop install. If something described here isn't where you
expect, that's why.
## General
The home tab contains language, interface preferences, and self-hosted build preferences.
## Appearance
Open **Settings → General** to use the existing Light, Dim, Dark and System switches; preset changes apply immediately. Choose **Customize** to open the editor inline (`/settings?tab=general&view=appearance`) while General stays selected, and **Back to General** to return. Built-in presets remain unchanged; editing one in the editor creates a personal copy. System follows the device, using Dim for a dark Desktop environment and Dark on the web.
The editor groups all registered design tokens into surfaces, text, controls, status, effects and scales. Search by token name, edit its color or value, and reset individual overrides. Typography controls the interface and monospace fonts, size, weight and line height. Uploaded WOFF2 files are embedded in theme JSON, so custom fonts travel with an export.
Edits preview immediately across the dashboard, including open terminals, without restarting their sessions. **Save** persists the theme to the authenticated user on the connected instance. **Discard** restores the saved appearance. The bottom controls retain a readable base palette; **Reset** previews the default Light appearance and clears the personal library only when you save. Navigating away discards the unsaved preview; a full reload warns about unsaved changes.
Import a JSON file, paste JSON, or load a public HTTPS JSON URL that permits browser CORS requests. URL imports omit credentials and are fetched once, rather than continuously following remote changes. A single-theme import replaces a matching theme ID or adds it to the library; a library import replaces the draft library. Nothing is persisted until Save.
**Download theme** exports the active theme; **Download all** exports the personal library. The versioned format supports up to 32 themes, two WOFF2 fonts per theme (256 KiB each), and 1 MiB total. Unsupported tokens, invalid values, cyclic token references and incompatible versions are rejected. These preferences affect this account's dashboard, not deployed applications or other members.
The [appearance API and CLI](/docs/api/settings#personal-appearance) use the same format. Saving requires a version of the API that supports the appearance endpoints; a failed settings read stays visible and blocks saving until a retry succeeds.
## Git
The **Git** tab owns outbound source-control access. On self-hosted instances, workspace owners first see
**Self-hosted GitHub Apps**, where they can create Apps with GitHub's manifest flow, register an existing
GitHub or GitHub Enterprise App, manage installations, rotate credentials, verify health, and choose a
default source. See [Self-hosted GitHub Apps](/docs/guides/self-hosted-github-app).
The **GitHub** connection card underneath manages the separate local `gh`/device/token identity and the
managed Openship App fallback. When workspace-owned Apps exist, their install, manage, and delete controls
remain exclusively in the source cards, so **Disconnect** cannot misleadingly remove only an unrelated
OAuth account.
The **GitHub clone credentials** card stores a personal token fallback for private clones. On desktop it can
also forward the local Git identity to remote build servers.
See [Deploy from GitHub](/docs/guides/deploy-from-github) for the full walk-through.
### Deploy Defaults
*(Self-hosted and desktop only.)* Pick where new deployments should land by default — **This Machine**
(local Docker/runtime), **My Server** (a configured SSH server), or **Openship Cloud**. The chosen target
is preselected on the deploy picker; you can still override it per deployment, or **Clear default
(ask every time)**.
### Build Preferences
*(Self-hosted and desktop only.)* Choose the default build strategy for new deployments: **Auto** (smart per-framework),
**Server** (build on the remote), or **Local** (build on this machine). Per-project overrides live in the
project's own settings.
### Language
Choose the language used across the dashboard. The change applies immediately.
## Tokens
Credentials that let other things act on your behalf. GitHub clone credentials live in **Git**; this tab
contains API access tokens.
### Personal Access Tokens
Bearer tokens for the API, CLI, and MCP clients. Each token **acts as you** — it carries your role's
permissions unless you narrow it. When creating one you can:
- Name it (e.g. "MCP client").
- Set an expiry: **No expiry**, **30 days**, **90 days**, or **1 year**.
- Mark it **Read-only** to block all writes.
- **Limit to specific resources** to scope it below your own role — ideal for a narrow MCP token.
Press **Create token**, then copy it immediately — this is the only time the value is shown. Existing
tokens are listed with **read-only** / **scoped** badges and a **Revoke** button.
A new token's value is displayed once, at creation. If you lose it you can't recover it — revoke it and
make a new one.
## MCP
Connect AI agents (Claude, Cursor, VS Code, Windsurf, …) to your Openship API over the Model Context
Protocol. The tab shows this instance's **Endpoint** — a Streamable-HTTP JSON-RPC URL, typically
`https:///api/mcp` — plus per-client install snippets.
Two ways to authenticate:
- **OAuth** — the client opens a browser to authorize; you approve access and pick what it can reach.
Nothing to copy. Openship is a standards-compliant OAuth 2.1 MCP server.
- **Static token** — for clients without OAuth, drop a fixed, scoped token (created in the **Tokens** tab)
into the client config.
**Connected clients** lists every authorized client with its access level (read-only / full control) and
resource scope, each with a disconnect action.
## Team
Who can reach this organization's projects, deployments, and servers. See
[Teams & members](/docs/guides/teams-members) for the full workflow.
- **Active members** — everyone with access, their role, and a **Remove member** action.
- **Pending invitations** — invites you've sent that haven't been accepted yet.
- **Invite member** — send through the instance's configured email service or create a link to copy.
Pick a role: **Member** (read + write to everything), **Admin**
(Member plus manage members and billing), or **Restricted** (no default access — you choose exactly which
resources to unlock). Restricted invites open a resource picker.
Both delivery choices use the same email-bound invitation. The link is shown after creation
and stays available in Pending invitations, where it can also be revoked. From a connected
Desktop, copied links point to the remote instance. Recipients use their own accounts and
enter the invited organization after accepting.
Self-hosted recipients can choose **Open in Desktop** on the invitation page, confirm the
instance, and use the same sign-in and acceptance flow in the app. The page also provides
a copyable invitation URL for manual connection. Joining never grants more than the offered
role and resource access; opening the link alone does not join a workspace.
If you're on a personal workspace, this tab also offers **Create team** to spin up a separate, isolated
team organization.
## Notifications
Decide what you get told about and where it goes.
- **Delivery channels** — where notifications are sent. Add an **Email**, **Webhook**, **Slack**, **Discord**,
or **Microsoft Teams** channel; the **in-app** dashboard bell is always on. Outbound channels are skipped
until verified — send a test to verify one.
- **What to be notified about** — a grid of events × channels; each cell you switch on is one subscription.
Events span the whole platform: deploys (succeeded / failed / cancelled), backups (succeeded / failed /
restore completed), scheduled jobs, domain expiry + verification, team changes, and billing / quota alerts.
- **Organization defaults** — the subscriptions applied when a new member joins. Members can override their
own per-channel.
## Audit log
*(Admin or owner only.)* A running feed of every change in the organization — who did it, what changed, and
when. Search across events, actors, and resources, filter by event type, and expand any entry to see the
**before**/**after** of the change plus actor details (name, email, IP, user agent).
## Cloud
*(Self-hosted and desktop only.)* Link this instance to Openship Cloud to unlock cloud deployments, managed SSL, and the
global CDN. Press **Connect to Openship Cloud**, sign in, and review the account and organization
before authorizing. The consent screen has **Switch** actions for both. Once connected the card shows
your cloud account with a **Disconnect** option. This connection also enables migrating your instance
to Cloud — see [Connect to Cloud & migrate](/docs/guides/cloud-connect-migration).
## Instance
Everything about *this install*. Two cards at the top show the instance type (**Desktop**, **Openship
Cloud**, or **Self-Hosted**) with its deploy mode and version, and the auth mode (**Zero Auth**, **Cloud
Auth**, or **Local Auth**) with the signed-in user. On a zero-auth desktop install a **Change** link lets
you add an email + password login without losing any projects or history.
### Updates
*(Self-hosted and desktop.)* Shows your current version and whether a newer release is available, with
**Check now** / **Update now**, a toggle for **Automatic updates** (off by default), and a toggle for
**Update & security notifications**. Openship only ever *pulls* this data from the public GitHub releases —
nothing can push updates to your install. More in [Updating Openship](/docs/guides/updating).
### Instance location
Move between Desktop and a connected or managed server from one card. Choose API-only or
API + dashboard, or connect Desktop to an existing remote instance without copying its data.
The move preserves workspaces and credentials, verifies the receiver before cutover, and
keeps the source inactive afterward. **Move back to Desktop** transfers the latest remote
state. [Read the instance move guide](/docs/guides/migrate-control-plane).
The card shows the current location and its main action. The **More instance options** menu
contains existing-instance connections, move codes and returning to a previous server.
An active server offers **Connect a Desktop** directly; a retired server offers
**Move an instance here**.
### Backup & recovery
*(Self-hosted and desktop, instance administrators only.)* **Export instance or projects** downloads a
portable JSON file. Choose the entire instance, or select projects and individual environments in bulk.
The same project export is available in **Project → Advanced → Export project**, with all of that
project's environments selected by default.
Project exports include deployments, service configuration, environment variables, overview analytics, linked apps, routing,
backup policies and destinations, and Git credentials. Related self-hosted servers are recommended and
included by default. You can choose which configuration and history to include. Both instance and project
exports include environment values, private keys, deployment snapshots, inline Compose configuration,
and credentials as **unencrypted JSON**, with no export password. Credentials and all history are selected
by default. Keep using the listed servers, or connect the destination to the same Openship Cloud account.
**Import data** uploads the file once and previews its contents. An instance archive starts in **Replace
the entire destination instance** mode, with confirmation before applying. It restores the source
projects, users, servers, credentials, settings and included history over the destination's older records.
For project archives, select the environments to import into
the current workspace, review conflicts, and map source servers to destination servers. Matching
self-hosted servers are reused with their existing connection credentials. Existing projects are skipped
by default; **Overwrite matching project records** replaces the selected projects, removes destination-only
records in the selected categories, and respects credentials cleared at the source. The review shows
how many records will be removed. Excluded categories and other projects are retained. Individual projects
can override that choice. Shared integrations and backup
destinations are reused unless you explicitly choose to overwrite shared settings.
Cloud projects require the destination workspace to be connected to the **same Openship Cloud account**.
Cloud servers cannot be transferred between accounts. For project imports, a source control-plane host needs an
explicit target mapping. Projects mapped to a different host arrive disabled with live container
references cleared, ready for a migration or redeployment.
In project imports, loopback SSH addresses also require explicit mapping. Backup schedules that use a source-local folder
or a different backup host arrive disabled; reconnect the storage, verify it, and then enable the schedules.
Exports contain control-plane metadata. Volume contents, database payloads, source folders, and host TLS
files stay on their server. Keep using that server, or move the runtime data with migration/backup
restore. Reconnect local source folders and update Git/webhook callback URLs when the control-plane
address changes. The import result keeps these follow-up notes available.
Use **Instance location** for a live move of the whole control plane. Use an export file for
project selections so you can review conflicts and server mappings before applying them.
An instance archive offers merge or full replacement. Replacement erases
all destination data and signs you out. A project archive can never wipe an instance. Only an
**instance administrator** can export or import. Older password-protected archives still require their
original password. If an older file contains no credentials, export again from the updated source;
an import cannot recover values absent from the file. Update the destination before importing a newer
archive so all its fields can be restored.
---
# Servers
URL: https://openship.io/docs/dashboard/servers.md
Manage your deployment servers, with automatic setup on Openship Cloud and SSH connections for your own machines.
The **Servers** section shows where your projects run. On **Openship Cloud**, choose a plan and deploy:
Openship prepares a managed server automatically. You can open Servers later to inspect usage or change
supported settings. On **self-hosted Openship**, connect a machine you own over SSH and Openship installs
and checks the software your deployments need.
Connecting a Cloud account from self-hosted Openship also lists that account's managed servers here,
alongside your own machines. Existing execution links appear once. Cloud server settings, terminal
sessions and billing use their Cloud operations; browsing the list does not create another server.
The list is at **`/servers`**, adding a server is **`/servers/new`**, and each server's detail screen is
**`/servers/`**. Every project uses the same server destination, whether Openship manages the
host or you connect it yourself.
## Managed servers on Openship Cloud
Your first subscription prepares a **Production** server. Repository deployments, uploaded source, and
catalog apps automatically use that server when it is the only compatible destination. You do not need
SSH credentials or a separate setup step. **Add Server** creates an additional, separately billed target.
The list shows each server's state, placement, and project count. Open one for:
- **Overview** — measured CPU, memory, and disk use, purchased capacity, and the projects sharing it.
Project storage represents measured application data; shared images, cache, and system files are counted
once. Reserved disk capacity is shown separately from used storage.
- **Terminal** — a full-width interactive shell, next to Overview. The provider supports one server
shell at a time; an existing session is preserved if another connection is attempted.
- **SSH access** — enable SSH, replace an authorized public key or password, and issue a temporary
connection for a terminal or SFTP client. Disabling SSH requires confirmation.
- **Activity** — the latest server operation, its status and logs. Queued work shows its next retry;
failed work offers **Try again**. Completed logs stay here without covering the other tabs.
- **Settings → Components** — inspect Docker and Git health and run a fresh check. Software on managed servers
is maintained by the platform; the page does not offer host package installation or removal.
- **Networking → Listening ports** — scan listening ports through the server's existing execution connection. A listener
inside the server does not establish public reachability; provider networking and project routes
control external access.
- **Networking → Outbound & access** — choose an available managed outbound IP, configure a custom
HTTP/HTTPS proxy, or return to a managed connection. Internet access and the destination allowlist
have their own save action. A revision check rejects stale edits. Applying a change affects every project on this server. Domains and HTTPS stay in each
project's **Domains & routing** tab; Oblien manages the edge proxy and certificates.
- **Workloads** — inspect native host processes and their live state. Read recent logs, or create a
stopped manual background process and explicitly start it. Project and system processes link to their
owning controls; they cannot be deleted or stopped from this view. Docker containers remain in projects.
- **Settings → Runtime API** — reveal a server-only automation token or rotate it with confirmation. This API
remains enabled because Openship uses it for deployments and terminals. Rotation invalidates older
tokens and connections; let active work finish first.
- **Settings** — inspect the managed image, operating system, persistent lifecycle and allocated
resources, read recent boot logs, and open the existing capacity-change review. Application images
belong to project deployment settings; the shared server image is maintained by Openship.
Only supported tabs appear. These are the shared server overview, health, listener and terminal
components, with provider controls and the plan card for managed servers. Host package installation
and OpenResty maintenance belong to connected servers. Secret access, process logs and mutations
require server-admin permission. Credentials are cleared from the page after one minute, when the
browser tab is hidden, or when you leave the server tab; copying them does not revoke them.
### Outbound connections
The managed-IP picker reads the provider's current pool, with country codes. **Automatic** keeps
an existing managed address or assigns one when returning from a custom proxy. Changing an IP affects
external services that allowlist the server's outgoing address; it does not change application domains.
Custom proxies require a **public IPv4 address**, port and HTTP or HTTPS protocol. Hostnames and
private addresses are rejected. Enter both username and password if authentication is enabled;
credentials are never returned by Openship or included in its audit events. Re-enter them when
replacing an authenticated proxy. The provider performs its own connection preflight and enforces
proxy availability on the underlying Cloud account.
Openship applies one outbound change under the existing server activity lock, then reads the result
before confirming success. It does not combine that change with internet-policy or routing writes.
If a response is lost, **Refresh status** reads the current settings; it does not repeat the mutation.
A changed provider revision rejects an outdated proxy form, including a password-only replacement.
The same controls are available through `ship.servers.managedOutbound(id)`,
`ship.servers.managedOutboundOptions(id)` and `ship.servers.setManagedOutbound(id, input)`, or the CLI:
```bash
openship server managed outbound get srv_production
openship server managed outbound options srv_production
openship server managed outbound set srv_production reviewed-outbound.json
```
The JSON contains `mode`, the `expectedRevision` from the read, and `confirm: true`. For managed mode,
optionally include a listed `ip`; for custom mode, include `proxy` with `host`, `port`, `protocol`, and
both credentials or neither. Read secret-bearing JSON from a private file or stdin, rather than putting
credentials in shell arguments. Connected self-hosted installations use the owning Cloud server's
same operations.
### Plan changes and recovery
**Billing** opens this server's subscription, coverage, usage and payments. Top-ups appear only for
eligible metered subscriptions; monthly CPU, RAM and storage need no compute credits. Projects on a
shared Docker server use its existing capacity; creating a project does not reserve another VM or disk.
**Resume server** checks the current entitlement before starting a stopped host. **Apply plan capacity**
previews the purchased size and all projects that may restart. Disk shrinking is unavailable. Operations
show their progress and logs in **Activity**; action confirmations remain visible on the current tab.
Refreshing or reopening the page observes the same operation without starting another one.
Renaming a server preserves its placement and subscription. Deleting a project preserves the shared
server and its other projects. Deleting the server requires no remaining projects and an ended
subscription, followed by explicit confirmation.
See the [managed Cloud server guide](/docs/guides/cloud-workspaces) for lifecycle details and the
[Servers API and SDK](/docs/api/servers) for automation.
## Connected servers on self-hosted Openship
The remaining setup and infrastructure controls apply to machines you connect yourself. Give Openship
SSH access to a VPS, bare-metal server, or VM, then select it in the
[deploy flow](/docs/guides/deploy-from-github). See [Deploy to your own server](/docs/guides/custom-servers)
for a walkthrough.
## The Servers list
This screen (**`/servers`**) shows every server you've connected. The header reads **Servers** with the
subtitle "Manage your deployment servers and infrastructure", and an **Add Server** button sits top-right.
Each server appears as a card showing its name (or host if unnamed), a **Connected** / **Error** status pill,
and the `user@host:port` it dials. Click a card to open that server's detail screen.
On the right, a **Quick Info** panel tallies **Total Servers**, **Connected**, and **Errors**.
In the desktop app, a server card can also show a **\{n} forwarding** badge — the number of active
[port forwards](#ports-tab-port-forwarding) for that server. This badge does not appear on hosted instances.
If you have no servers yet, the empty state explains what an auto-setup configures, with an **Add Your First
Server** button and four cards under "What gets configured":
| Card | What it means |
|---|---|
| **Docker** | Container runtime |
| **OpenResty** | Reverse proxy & SSL |
| **Monitoring** | Health checks |
| **Git** | Source deployments |
## Adding a server
Press **Add Server** to reach **`/servers/new`**. The page title is **Add Server** with the subtitle "Enter
your server details and choose an auth method", and a **Getting Started** panel on the right lists what you
need: a server with SSH access (Ubuntu, Debian, or similar) and an SSH key or password.
### The SSH Connection form
| Field | Notes |
|---|---|
| **Server Name** | Optional label shown in the list and header. Leave blank to fall back to the host. |
| **Connection** | **Direct SSH** or **Cloudflare Access**. |
| **Server IP Address** | The host to connect to, e.g. `123.45.67.89`. Required. |
| **Port** | SSH port; defaults to `22`. |
| **Username** | SSH user; defaults to `root`. |
| **Authentication** | Choose **Password**, **SSH Key**, or **Agent** (see below). |
The **Authentication** control is a three-way toggle:
- **Password** — enter the server password.
- **SSH Key** — give a **Key Path** (e.g. `~/.ssh/id_rsa`) and an optional **Passphrase**.
- **Agent** — connects using the host machine's `ssh-agent` (like VS Code); no password or key is entered
here. The machine running Openship must already have access to the server.
Under **Advanced** you can add a **Jump Host** (e.g. `user@bastion.example.com`) and **Extra SSH Arguments**
(e.g. `-o ConnectTimeout=30`). Only connection tuning options are accepted.
For an existing Cloudflare Access SSH application, choose **Cloudflare Access** and enter its hostname,
such as `ssh.example.com`. Password, encrypted private key, and agent authentication are supported.
The SSH origin port is configured in Cloudflare Tunnel. Complete Cloudflare sign-in on the machine
running OpenShip before testing the connection. Windows desktop bundles the verified `cloudflared`
client; other installations need it on their PATH or configured through `OPENSHIP_CLOUDFLARED_PATH`.
The saved connection is reused for setup, deployments, health checks, Docker, source transfers, terminals,
and port forwarding. The server's **Open Cloudflare Access** link opens its Access application;
a browser terminal is available there only if you enabled it in Cloudflare.
Two buttons finish the form:
- **Test Connection** — dials the server with the details you entered and reports success or the failure
reason, without saving anything.
- **Save & Continue to Setup** — saves the server and moves straight into the component setup flow. (When
you're editing an existing server, this button reads **Save Changes** instead.)
### The setup flow
After you save a new server, Openship walks you through installing its prerequisites. You first choose how to
run it:
- **Automatic Setup** — "Check requirements and install everything automatically. One click — Openship handles
Docker, OpenResty, and Git."
- **Step-by-Step Setup** — review each component and its detailed status before installing.
The flow then moves through **Connect → Check → Install**: Openship opens the SSH connection, runs health
checks, and installs whatever's missing. Progress streams live, per component (Waiting → Installing → Installed,
or Failed), with an expandable **Install Logs** panel. When it finishes you can jump to the server's detail
screen; if anything failed, **Retry Failed** re-runs just those components.
You don't have to get setup perfect here. Every check, install, reinstall, and removal is also available later
from the server's **Components** tab.
## The server detail screen
Opening a server (**`/servers/`**) shows its name with a **Healthy** or **Issues** badge and the
`user@host:port` beneath it. Top-right are three controls:
- **Migrate Docker** — opens the migration wizard to bring a running Docker or Compose deployment on that
server into Openship.
- **Edit** — reopens the SSH Connection form (at `?edit=true`) so you can change connection details.
- The **⋯** menu — holds **Remove Server**, which clears the stored SSH credentials and connection settings.
If Openship can't reach the server, a banner appears above the tabs explaining whether the box is unreachable,
the credentials were rejected, or the config is incomplete — with a **Retry** and an **Edit** shortcut. A
**Connection** panel on the right always shows the current **Host**, **User**, and **Auth** method.
The screen is organized into tabs. **Overview**, **Components**, **Security**, and **Terminal** always show;
**Ports** appears only in the desktop app.
### Overview tab
A live dashboard for the server. Four stat cards show **CPU** (with load averages), **Memory**, **Disk**
(each with a usage bar that turns amber past 70% and red past 90%), and **Uptime**. Below them, a
**Components** card lists each installed component with a **Healthy** / **Unhealthy** marker and version. The
header summary reads "All systems operational" or "\{n} of \{m} unhealthy". See
[Logs & monitoring](/docs/guides/logs-monitoring) for more on reading these signals.
### Components tab
Manage the software Openship relies on. The **System Health** card lists every required component and, under a
**Detected Infrastructure** divider, any optional ones it found. Each row shows health, version, and a status
message, with per-component actions:
| Action | When it shows | What it does |
|---|---|---|
| **Install** | Component is missing and installable | Installs it. |
| **Reinstall** | Component is already installed | Reinstalls / refreshes it. |
| **Remove** | Component is removable and installed | Uninstalls it (destructive — confirmation required). |
Header buttons let you **Install Missing (\{count})** in one go, or **Re-check** to re-run the health checks.
Installs and removals stream a progress card with component rows and an expandable logs panel, matching the
setup flow.
Removing a component is destructive and can disable related deployment features until you install it again.
Removing **OpenResty** takes down the reverse proxy and its managed config; use **Reinstall** if you only need
to refresh its scripts or settings.
### Security tab (rate limiting)
This tab configures **OpenResty request rate limiting** for the server. The core control is **Requests /
second**; Openship derives a **burst** allowance automatically (about 40% of the rate). Open **Advanced** to
switch **Burst mode** to manual and set a custom **Burst allowance**.
**Whitelisted IPs** let you list addresses or CIDR ranges that bypass the limit (loopback `127.0.0.1` and
`::1` are always whitelisted). Type an IP or CIDR and press **Add**.
Save with **Apply rate limit** (first time) or **Save changes** (when one already exists); **Remove rate
limit** clears it, and **Refresh** re-reads the live config from OpenResty. A draft indicator at the bottom
summarizes pending changes before you save.
Rate limiting reads and writes the live OpenResty config on the server, so OpenResty must be installed and
reachable. If it can't be read, the tab shows a "Couldn't read OpenResty rate limit config" notice with a
**Retry**.
#### Exposed-port scan
The Security tab also has a **Scan ports** action that lists the ports actually **listening** on the server
and classifies each as **exposed** (bound to a public/all-interfaces address) or **loopback-only** (bound to
`127.0.0.1`, reachable only from the host). Use it to spot anything unintentionally reachable from the
internet — a database that should be loopback-only, a debug port left open — so you can lock it down. It's a
read-only probe (it changes nothing); re-run it after a deploy to confirm only what you expect is exposed.
### Ports tab (port forwarding)
Desktop-only. Port forwarding exposes a remote server port as `localhost:` on your own machine — like VS
Code's port forwarding. Each forward is bound to loopback and is active only while running.
Existing forwards are listed with a running/stopped dot, the remote `host:port`, the local address, and
per-forward controls: **Start** / **Stop**, **Remove**, and an **Open on startup** toggle. To add one, enter a
**Remote port** (1–65535) and an optional **Local (auto)** port (`0` for auto, or 1–65535), then press **Add**.
A service's **Open on localhost** action uses the same saved forwards. Private services use their live
container IP and configured TCP port, so they do not need a public domain or a published host port.
If no TCP port is configured, enter the port the service listens on when prompted.
The action is enabled when the service is running and its address is known. For a database,
connect your database client to the assigned localhost port using the database's normal credentials.
This tab is hidden on hosted instances — port forwarding only makes sense when the Openship orchestrator is
your own machine.
### Terminal tab
A live shell to the server, right in the browser. The header shows the configured session limit
(3 by default for connected servers; 1 for managed Cloud Docker servers). Text is copied on select.
Leaving the tab disconnects the browser and briefly parks the shell for reconnection; closing a shell
explicitly terminates it.
## Editing and removing a server
To change connection details, press **Edit** on the detail screen (or **Edit** from a single-server list) —
this reopens the same SSH Connection form with a **Save Changes** button. When editing, leaving the password
or key blank keeps the stored secret; you only re-enter it when switching auth method.
To disconnect a server, use **Remove Server** from the **⋯** menu. This clears the SSH credentials and
connection settings for that entry.
## Related guides
---
# New Project (Library)
URL: https://openship.io/docs/dashboard/library.md
The source picker that starts every deployment — upload a folder, import a GitHub repo, paste a Git URL, pick a template, or adopt an existing server.
This screen is where every new deployment begins. When you press **New Project** in the dashboard you land
on the Library page (route `/library`), titled **New Project** with the subtitle *"Import a repository, paste
a URL, or start from a template"*. Its job is simple: pick **where your code comes from**, and Openship hands
you off to the deploy wizard (`/deploy/...`) with everything pre-filled.
Think of this page as the front door with five doors behind it — each tab is a different way to bring code in.
Whichever you choose, they all end in the same place: the wizard where you confirm the framework, choose where
it runs, and press Deploy.
## The five tabs
The tab row sits just under the page title. The **GitHub** tab is selected by default. The last tab
(**Existing server**) only appears on self-hosted and desktop installs — Openship Cloud has no server inventory
to adopt from.
| Tab | Icon | What it's for |
|---|---|---|
| **Folder** | folder-up | Deploy from a folder — uploaded from your browser, or read straight off disk on the desktop app. |
| **GitHub** | github | Browse and deploy the repositories on your connected GitHub account. |
| **Git URL** | link-2 | Paste a public GitHub repo link — no account connection needed. |
| **Template** | sparkles | Start from a ready-made starter for a framework. |
| **Existing server** | boxes | *(self-hosted only)* Adopt a Docker/Compose app already running on your own machine. |
On the right of every tab is the **Overview** sidebar — repo counts and a "Quick Tip" — plus your GitHub /
Cloud connection status. It's informational; the action is always on the left.
## Folder
Deploy an app from a folder, no Git required. This tab behaves differently depending on how you're running
Openship:
- **Desktop app** — you get the **Local Projects** panel. Point Openship at a folder on your machine
(drop it or type the absolute path, then **Scan**), it auto-detects the framework, and builds and runs the
app locally. No upload happens — the local pipeline reads the folder in place.
- **Browser (Openship Cloud or a remote self-hosted instance)** — you get the **Folder upload** flow. A browser
can't see your filesystem, so Openship first asks **"What are you deploying?"** and shows a grid of stacks to
pick from (this fixes the build image). Then you drop or browse to your project folder — it's packed in your
browser (skipping `node_modules`, `.git`, and build output), uploaded, and you continue to the wizard.
See [Deploy a local folder](/docs/guides/deploy-local-folder) for the desktop picker, the browser upload, and
the one-command CLI equivalent.
## GitHub (Repositories)
The default tab. If your GitHub account isn't connected yet, you'll see a **connect** prompt here instead of a
list — connect once and the repos appear. (Follow [Deploy from GitHub](/docs/guides/deploy-from-github) for the
one-time connection.)
Once connected, this panel lists your repositories with tools to find the right one:
- An **account row** at the top to switch between the GitHub owners/orgs you've granted, plus a **+** to add
another account.
- A **search** box (`Search repositories...`).
- **Visibility** pills: **All**, **Public**, **Private**.
- A **sort** dropdown: **Recent**, **Name**, **Stars**.
Click any repository and Openship takes you straight into the deploy wizard for it.
A repo tagged **Local only** is visible through the `gh` CLI but the Openship GitHub App isn't installed on its
owner — so it can build locally, but remote deploys will be refused. Install the App on that owner (the
**Install GitHub App** action) to enable remote deploys.
## Git URL
For deploying a public repository you don't own or haven't connected. The panel is **Import from Git URL**:
paste a URL like `https://github.com/username/repository` and press **Import Repository**. No GitHub connection
is required. Openship parses the owner and repo from the link and sends you to the wizard.
This path clones over the public URL. For private repositories, use the **GitHub** tab so Openship can
authenticate. See [Deploy from a template or Git URL](/docs/guides/deploy-template-or-url).
## Template
A grid of framework starters. Pick a framework and Openship opens the wizard seeded from that template — a fast
way to get a working project online without bringing your own code first. (The plain "static" option is omitted
here.)
See [Deploy from a template or Git URL](/docs/guides/deploy-template-or-url) for what each starter includes.
## Existing server
*(Self-hosted and desktop only.)* This tab is for **adopting a deployment you're already running** — the card
is titled **Existing Docker server**, described as *"Migrate a running Docker or Compose deployment into
Openship."* Press **Migrate Docker** to open the migration wizard, which connects over SSH to your box,
inspects the running containers, and brings them under Openship's management.
Adoption reads containers off a server you control, so it isn't available on Openship Cloud. If you want to add
a fresh machine instead of adopting one, see [Connect your own server](/docs/guides/custom-servers).
## What happens next
Every tab leads to the same place — the **deploy wizard** at `/deploy/...`, where you confirm the detected
framework, choose where the app runs (Local, Server, or Cloud), and press **Deploy**.
---
# The deploy wizard
URL: https://openship.io/docs/dashboard/deploy-wizard.md
The screen where you choose where your app runs, review the detected build, and watch it go live.
The deploy wizard is the screen you land on after picking a source (a GitHub repo, a
local folder, an uploaded folder, or a template) from the [Library](/docs/dashboard/library).
Its job is to answer three questions and then do the work: **where should this run?**,
**does the detected build look right?**, and **is it live yet?**
The wizard lives at `/deploy/`. When you press **Deploy** it hands off to the
live build screen at `/build/`, which streams the logs until your app is online.
The very first screen — **Deploy target** — only appears in the **desktop app**, where
you can choose between your own servers, Openship Cloud, and your own machine. On a
self-hosted or cloud dashboard opened in a browser, the wizard skips straight to
**Config**.
## Screen 1 — Deploy target (desktop app only)
This is the "where do you want this to run?" screen. Its heading reads **"Where do you
want to deploy?"** and it shows one card per place you can deploy to.
### The target cards
| Card | What it means |
|---|---|
| **Your server** (shown by name) | Deploy to one of your connected servers over SSH. A single server shows by its name; multiple servers collapse into a **Your servers** card that expands to a picker. |
| **Openship Cloud** | Deploy to managed cloud infrastructure — no server setup. If you haven't connected Cloud yet, the card explains that and prompts you to connect when you continue. |
If you run Openship self-hosted, an **Add your own server** button sits below the cards.
It opens the **Add your server** form (name, IP address, port, username, and
authentication — password, SSH key, or agent) right inside the wizard; the new server is
selected automatically once saved, so you don't lose your place. See
[Custom servers](/docs/guides/custom-servers) for the full walkthrough.
There isn't a separate "local machine" target card in this picker — the two cards are your
server(s) and Openship Cloud. Running the **build** on your own computer is offered
separately as the **This Machine** build option (see *Advanced*, below), which is the
fast path when you have a capable laptop and a small VPS.
### Power — the cloud resource tier
When **Openship Cloud** is selected, a **Power** panel appears on the right. This is where
you size the machine your app runs on:
| Tier | Best for | Resources |
|---|---|---|
| **Micro** | Side projects, low traffic | 0.25 vCPU · 256 MB RAM · 4 GB disk |
| **Low** (default) | Small apps, light APIs | 0.5 vCPU · 512 MB RAM · 8 GB disk |
| **Medium** | Most production apps | 1 vCPU · 1 GB RAM · 16 GB disk |
| **High** | Heavy workloads, fast builds | 2 vCPU · 2 GB RAM · 32 GB disk |
| **Custom** | Dial it in yourself | Opens a dialog to set vCPU, RAM (MB), and disk (GB) |
If the project is just static files (no long-running server), there's no machine to size —
the summary shows a **Static** chip instead of a power tier.
### Advanced (server targets)
Pick a server and an **Advanced** section appears (collapsed by default — most people
never open it). Its summary line shows the current build location; expand it for:
- **Runtime** — how the app is isolated on the server.
- **Sandboxed** (recommended) — runs in an isolated container; a compromise can't reach
the host. Tiny overhead.
- **Direct** — runs straight on the host. Lowest overhead, but full host access if
compromised. Picking it shows a security caveat (and a memory-aware note on small
boxes).
- **Build location** — **This Machine** (build locally, then transfer the output — faster
on a powerful machine) or **Remote** (build on the deploy target — best when your machine
is limited).
- **Clone location** — for sandboxed/compose server deploys: **On your device** /
**On Openship** (clone then upload; works everywhere) or **On the server** (clone on the
server, no upload; best for big repos).
The old per-deploy "Forward my git credentials" toggle has moved to a single per-operator switch —
**Settings → Clone credentials → "Forward my git identity to build servers."** Turn it on once and every
server clone uses your local `gh` over SSH (nothing stored on the server). See
[Git authentication for private repos](/docs/guides/git-authentication) for the full clone-credential chain.
### Save as default & Continue
Tick **"Save as my default for every deployment"** to remember this target (and server)
for next time — you can change it later in Settings or per-deploy from this picker. Press
**Continue** to move to Config.
Once you've deployed before, the wizard remembers your last pick and drops you straight on
**Config** with a compact **Build & deploy** summary bar at the top. Click that bar (it has
a pencil) to reopen this picker for a one-off change.
## Screen 2 — Config
This screen is where you confirm what Openship detected and set anything it can't guess.
The main column holds the settings; a sticky sidebar on the right holds your repo info,
the domain, the **Deploy** button, and a build summary. For most apps the detected
defaults are correct and you can go straight to **Deploy**.
### The main column
What renders here depends on the project type Openship detected:
- **App** — a framework picker and build settings (install command, build command, output
directory).
- **Docker** — a single Dockerfile project; you mainly confirm the port.
- **Services** (Docker Compose) — the parsed services and their shared environment. See
[Multi-service with Compose](/docs/guides/compose-multi-service).
- **Monorepo** — a workspace header with one card per sub-app.
Below that, most flows also show **Environment Variables** (collapsible — see
[Environment variables](/docs/guides/environment-variables)), the **Project Name** field,
and, when routing rules were detected, an advanced **Routing** section.
GitHub sources also show **GitHub deployment checks**, enabled by default. Expand
**Customize checks** to choose the deployment result, all or selected services, and failure
details. These preferences stay with the project when changing branches or reopening the
wizard. The same controls are available in **Project → Source**. A connected GitHub App needs
Checks write access; see [GitHub deployment Checks](/docs/guides/deploy-from-github#github-deployment-checks).
### The sidebar
**Repository** — shows `owner/repo` and a branch dropdown. The overflow menu offers
**Copy clone token** (a ready-to-run `git clone` with a short-lived token, for
GitHub-App/Cloud repos). Local-folder sources appear with `local` as the owner and
have no overflow menu — there's no remote repo to clone.
**Domain** — one or more domain rows under a **Domain** card (**Add domain** with the `+`).
Each row is either a **free subdomain** on your instance's base domain or a **custom
domain**, plus the exposed **port** (server apps) or **static path** (static apps). To put
the app on your own address with HTTPS, see [Custom domains](/docs/guides/custom-domains).
Free `.` subdomains are routed through Openship Cloud. If you deploy to
your **own server** with a free domain (or expose a Compose service on one), the wizard
asks you to connect Openship Cloud or switch to a custom domain first. Custom domains work
without Cloud.
**Deploy Summary** — a read-only recap card at the bottom of the sidebar. For apps it lists
the **Domain**, **Build Location** (Local Machine / Openship Cloud / Server), **Framework**,
and the detected **Install** / **Build** / **Output** commands. For Docker/Compose it shows
the **Runtime**/**Stack** and **Port**.
### The Deploy button
The primary button in the sidebar. It reads **Deploy** (with a rocket) and switches to
**Deploying…** while it starts. Pressing it kicks off the build and navigates you to the
live build screen.
A few checks can interrupt before the build starts — none of them are errors, just the
wizard asking for the one thing it needs:
- Deploying **to Openship Cloud** without a Cloud connection → prompts you to connect.
- A **free domain on your own server** (or on Compose services) → prompts for Cloud or a
custom domain.
- **Compose services with ports but no public domain** → a "no public service is reachable"
warning with **Review Services** / **Deploy Anyway**.
- **No way to clone a private repo** (no `gh`, no GitHub App, no token) → a credential
dialog offering to install the App, paste a token, or build locally instead.
When you open this screen from a project's **Configuration** tab (via *Edit*), the button
becomes **Save changes** instead of **Deploy** — it writes the config back to the project
and returns you to that tab. Deploying is then the separate **Redeploy** action on the
project. See [Redeploy & rollback](/docs/guides/rollback-redeploy).
## The live build screen
Pressing **Deploy** takes you to `/build/` — the screen that watches your deployment
happen. It has three parts.
### Title and progress
The heading reflects the live status: **Deploying...**, then **Deployment Successful**,
**Deployment Ready With Warnings**, **Deployment Failed**, or **Deployment Cancelled**.
Under it, a horizontal **step tracker** lights up each phase as it completes (clone,
build, deploy, and so on), with a spinner on the current step and a red mark if one fails.
### Build Terminal
A live terminal streams the build output line by line — like watching the oven through the
glass. This is where you read what actually happened. After a successful deploy of a
server app, the same panel switches to **Production Logs** so you can watch the running
app; a failed deploy adds a "See logs for issue details" hint. For more, see
[Logs & monitoring](/docs/guides/logs-monitoring).
### Deployment Details & actions
The right sidebar summarizes the deployment: **Status**, **Instance** (Openship Cloud /
Server / Local machine), **Build** (local / cloud / server build), **Build time**,
**Framework**, **Branch**, and **Domain**. The action button underneath changes with the
state:
| State | Buttons |
|---|---|
| Building / deploying | **Stop Deployment** |
| Failed or cancelled | **Redeploy**, and **Go to project** if one exists |
| Ready | **Open Dashboard** — plus **View dashboard** and **Visit Site** in the header |
Read the last few lines in the Build Terminal — that's the real reason. Most first-time
failures are a missing build command, a missing environment variable, or the app listening
on the wrong port. Fix it, then press **Redeploy**. See
[Troubleshooting → Deployments](/docs/troubleshooting/deployments).
## Related guides
---
# Emails
URL: https://openship.io/docs/dashboard/emails.md
Run your own mail server from the dashboard — provision or adopt a server, walk the setup wizard, and manage domains and mailboxes from the ten-tab admin panel.
The **Email Server** screen (route `/emails`) is where you stand up a complete, self-hosted mail
server on one of your own servers and then run it day to day — domains, mailboxes, DNS, health, backups.
Openship installs the whole stack (Postfix, Dovecot, anti-spam, SSL, DKIM/SPF/DMARC) over SSH and then
gives you an admin panel so you never have to touch the box by hand.
You can run more than one. Each mail server lives on its own host (one mail setup per server), and the screen
lists them all so you pick which to manage — a single server opens straight into its admin panel, while
several land you on a **Mail servers** list with an **Add mail server** action to provision or adopt another.
This screen manages a mail server on **your own connected server** over SSH. It isn't part of Openship
Cloud — you provision it against a server you've added under **Servers**. For a friendly walkthrough of the
whole flow (including webmail), see [Email & webmail](/docs/guides/email-webmail).
## Why run your own — and how deliverability works
Two things usually stop people self-hosting email, and Openship's model is built around exactly those two
gaps: **deliverability** (a brand-new server IP lands in spam) and the fact that transactional senders like
**Amazon SES**, Postmark, or SendGrid **only send** — they give you no inbox, no IMAP, no webmail, and no
ownership of your messages.
- **You own the inbox.** Openship self-hosts the *receiving* side those providers don't offer — real Postfix +
Dovecot mailboxes, IMAP/POP3, and webmail — so your messages, domains, and mailbox data live on **your**
server. You own the infrastructure and the data, not a vendor.
- **You borrow the reputation for sending.** Outbound can go direct-to-MX, or **relay through a trusted
provider's SMTP** (Amazon SES, or any SMTP relay). When you relay, your mail inherits the provider's warmed,
high-reputation sending IPs — the deliverability of a managed sender — while everything else stays on your
box. Openship writes the Postfix relay (`relayhost` + SASL) for you and aligns SPF, DKIM, and MAIL FROM
(SES-aware) so messages authenticate.
Relaying through a trusted provider gives you **that provider's sending reputation** — which is what actually
lands mail in the inbox, with no self-hosted-IP warm-up fight. It isn't a literal "100% delivery" guarantee
(no mail system can promise that), but it closes the gap that makes self-hosted *sending* risky, while keeping
the **mailbox** — the part SES has no answer for — entirely yours.
The relay is optional and scoped: apply it to **all** domains, or only **selected** senders (the rest keep
delivering direct-to-MX). Prefer to run your own IP? Direct-to-MX with the reputation warm-up stays fully
supported.
## What the screen shows you
The screen adapts to how many mail servers you already have:
- **None yet** → the **setup wizard** (or the [adopt](#adopt-an-existing-mail-server) flow).
- **Exactly one** → it opens straight into that server's [admin panel](#the-admin-panel-ten-tabs).
- **More than one** → the **Mail servers** list, so you pick which one to open.
The server you're acting on is remembered in the URL (`?serverId=…`), so a refresh reopens the same one.
## The mail servers list
When you have several mail servers, you land on a list titled **Mail servers**. Each card shows the
server's domain (or name), its host, and a status pill:
| Pill | Meaning |
|---|---|
| **Installing** | An install is currently running on this server. |
| **Running** | Provisioned and managed by Openship. |
| **Incomplete** | Registered, but the install didn't finish. |
Click a card to open it. **Add mail server** starts a new provision/adopt. The trash icon (**Remove from
list**) detaches a stale or mis-marked entry — this is dashboard-only and re-adoptable; it never uninstalls
anything on the server.
## Set up a new mail server
The setup form is titled **Mail Server Setup**. You fill in two things:
- **Domain** — your root domain, e.g. `example.com`. Your mail server will live at `mail.`.
- **Admin Password** — the password for the `postmaster@` mailbox. Use **Generate** for a strong
random one (with a reveal toggle). You can change it later from the admin panel.
If you haven't already picked a server, a server selector appears above these fields. Press **Start Setup**
to begin.
The sidebar's **What gets installed** panel spells out the stack: the mail server (Postfix, Dovecot,
anti-spam), a Let's Encrypt **SSL Certificate**, **DNS Configuration** (DKIM, SPF, DMARC), and the
**Admin Panel**. The **Prerequisites** box lists what you need first:
- A domain with DNS access.
- Outbound port 25 allowed by your provider, plus inbound TCP 25, 465, 587, and 993 allowed in the
provider firewall/security group/security list/NSG.
- A clean Ubuntu/Debian server (recommended).
### Watching the install
Once you start, the screen streams the install live in a **Live logs** panel — each line tagged with its
step number. You can **Cancel** a running install, or **Reset** (two-click confirm) to wipe the on-server
state and start clean. If a step fails, an error banner offers **Retry from step N**. The right sidebar
tracks **All steps** and, if ports 80/443 are already taken, surfaces a **Port Conflict** resolver before
continuing.
Twice during the install, the wizard pauses and needs you to act — first for DNS, then for reverse DNS.
The final **Verify Public Mail Ports** step first confirms the daemons are listening on the server, then
connects from the Openship API to the public DNS address on TCP 25, 465, 587, and 993. The API may run on the
mail server itself. Missing or loopback-only listeners, failed client ports (465/587/993), and non-timeout
errors on TCP 25 stop setup. Check both the host firewall and the cloud provider's firewall when a listening
port cannot be reached.
A timeout on **TCP 25 only** lets setup finish with a warning when that port has a non-loopback listener and
465/587/993 all complete a TCP handshake. Public reachability remains **unverified** in Health. AWS
[blocks outbound port 25 to public addresses by default](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/ec2-resource-limits.html),
which can prevent the API's check even when inbound mail works. The same timeout can also mean inbound TCP 25
is blocked, so verify it from an independent host or send a test message from another mail provider before
relying on receiving mail. An SMTP relay configured in **Sending**, such as Amazon SES, handles outgoing mail
only; it does not make a blocked inbound port reachable.
### DNS hold — publish your records
After the DKIM step, the install stops on a prominent amber banner: **Publish DNS records before
continuing**. Mail delivery breaks without these. The banner lists every record (A/AAAA, MX, SPF, DKIM,
DMARC) as a card — a type chip plus a **Name** and a **Value** field, each with its own copy button. Add
them at your DNS provider, then click **I've set the records - continue** — the install resumes from the
SSL-certificate step.
**Auto-configure DNS** opens a provider picker (Cloudflare, Hostinger, AWS Route 53, DigitalOcean,
Namecheap, Google Cloud DNS). Direct API push is not shipped yet — each provider currently shows a
"coming soon" note, so publish the records manually for now.
### PTR hold — set reverse DNS
After you acknowledge DNS, a sky-blue banner appears: **Set reverse DNS (PTR) before continuing**. This is
the step people miss most, so it's called out separately.
PTR (reverse DNS) records are configured in your **VPS provider's panel** (Hostinger, DigitalOcean, AWS,
etc.) — **not** at your DNS provider. Without matching rDNS, Gmail and Outlook reject your outbound mail.
The banner shows an **IPv4 PTR** (required) and, if present, an **IPv6 PTR** (recommended), each with the
IP and the hostname to point it at (`mail.`). It also gives you a verify command —
`dig +short -x ` should return `mail..`. When it's set, click **I've set the PTRs - continue**
and the install finishes with SSL.
## Adopt an existing mail server
Already installed a mail server with Openship but lost the dashboard record (e.g. you re-imaged the
orchestrator)? On the setup form, click **Already have a mail server? Adopt it**. In the **Adopt existing
mail server** dialog, pick the server and press **Scan server** — Openship reads the box (detects the mail
stack and its on-server state file) without changing anything. If a mail stack is found, **Adopt** brings it
back under management with no reinstall and no data loss.
## The admin panel (ten tabs)
Once a server is fully provisioned, `/emails` becomes its admin panel. A horizontal tab bar (icon beside
label, the active tab marked with a primary-colored underline) switches between ten tabs; the active tab is
stored in the URL so refresh and back/forward keep your place. For the primary domain, a **Reputation warm-up** banner sits above the tabs
during the first days of sending.
| Tab | What it's for |
|---|---|
| **Overview** | Hostname, webmail, mail stats, and quick actions. |
| **Domains** | Add and manage the domains this server hosts. |
| **Mailboxes** | Create and manage accounts, scoped to one domain. |
| **Aliases** | Forwarding addresses, and a catch-all for a domain. |
| **Notifications** | Get told in a notification channel when mail arrives at an address here. |
| **Sending** | Deliver direct or relay through a provider — and send a test email. |
| **DNS** | Per-domain record reference plus a "are they published?" check. |
| **Health** | Live daemon status and a DNS scan. |
| **Backup** | Snapshot and restore/migrate the mail server. |
| **Advanced** | Protocol settings, recovery tools, and the danger zone. |
### Overview
Your day-one screen. The top card shows the mail server **Hostname** (`mail.`, click to copy) and a
webmail action: **Open webmail** if webmail is deployed, or **Deploy webmail** if it isn't — the latter
takes you into the webmail deploy flow for this server. A **Protocol details →** link jumps to the Advanced
tab. A webmail deployed by Openship 0.6.1 or earlier also gets a **Replace webmail** link here — those installs
predate the webmail app and are replaced rather than redeployed (see
[Email & webmail](/docs/guides/email-webmail#step-3--deploy-the-webmail-app)).
Below that, **Setup guides** deep-links to client walkthroughs (iOS & macOS Mail, Android Gmail app,
Desktop clients, Send via code). The right column shows **Mail stats** (Domains, Mailboxes, Aliases,
Storage, Messages) and **Quick actions** (Add a mailbox, Add a domain, Review DNS records).
### Domains
A table of every domain this server hosts, with columns **Domain**, **Mailboxes**, **Aliases**, **Default
quota**, and **Status** (Active / Disabled, with a **Primary** tag on the install domain). **Add domain**
creates a new one — DKIM is generated automatically, and a per-domain DNS banner then prompts you to publish
its MX/SPF/DKIM/DMARC records before mail flows. Row actions let you **Edit** (description, default quota,
active) or **Delete** (with a cascade checkbox when a domain still has mailboxes or aliases). Newly-added
domains show a reputation warm-up banner.
### Mailboxes
Always scoped to one domain via the picker at the top (defaults to the primary domain; the choice mirrors to
`?domain=` in the URL). The table lists **Mailbox**, **Quota**, and **Status**, with a **Postmaster** tag on
the bootstrap account. **Add mailbox** collects the local part, full name, a password (with **Generate**),
and a quota. Deleting offers **soft delete** (deactivates and queues cleanup) or **hard delete** (removes DB
rows and the Maildir immediately); the postmaster account is protected from hard delete.
### Aliases
Also scoped to one domain. An alias forwards mail from one address to another — internal or external — and a
**catch-all** takes every address at the domain that no mailbox or alias matched. Changes are live the moment
you save; nothing restarts.
### Notifications
Rules of the shape "mail arrives here → tell me in this channel", for the addresses on this server. Each rule
watches **one mailbox**, **a whole domain**, or **every domain on the server**, can narrow further on *From
contains* / *Subject contains*, and fans out to one or more notification channels.
Channels themselves live in **Settings → Notifications** (they're shared with jobs, deploys and health alerts),
and only channels that are enabled *and* verified can be picked — an unverified one is dropped by the
dispatcher, so it would be a rule that never delivers. **Add a notification channel** links straight there when
you have none. **Test now** replays already-captured mail against your rules and reports how many matched,
without sending or deleting anything.
Mailbox-scoped rules match the To and Cc headers, so mail that reached the mailbox by Bcc or through an alias
won't match. Watch the whole domain if you need every message.
### Sending
Receiving always stays on this server; this tab only decides how outbound mail **leaves** it:
- **Direct delivery** (default) — this server delivers to each recipient's MX itself. Simplest, but fresh-VPS
IPs are often blocklisted and many hosts block outbound port 25.
- **Relay through a provider** — hand outbound mail to a smarthost (SES, SendGrid, Mailgun, Postmark, Resend,
or any SMTP server). You choose whether **all senders** relay or only **selected** domains and addresses, and
the DNS tab then gains that provider's SPF include and DKIM records.
Nothing is applied until you press **Save**; the right-hand column shows a live summary of what it will apply.
**Test sending** sits at the bottom of that column: press **Send test email**, choose a recipient (and the
sending domain), and check the destination inbox — and its spam folder. It tests the path that is live right
now, so save first if you just changed one.
### DNS
A per-domain reference plus a live check. Pick a domain, and **Records for publishing** shows exactly what to
add at your DNS provider. **Published records check** runs a live public-DNS lookup on demand — press
**Verify** (or **Rescan**) and each record comes back **Pass**, **Warning**, or **Fail**, with expected vs.
actual values when something's off.
### Health
If Openship cannot read the server, **Mail status unavailable** offers **Retry status**. Saved details
remain visible when available, and current health is unknown until a check succeeds. A failed
connection does not offer setup or engine repair, or start and stop mail services.
The single "is everything working?" screen. A banner at the top aggregates a verdict across four sections:
- **Daemons** — live systemd status of each mail process (Postfix, Dovecot, anti-spam, etc.), refreshed on a
10-second poll. Each row has a **Logs** button and a menu to **Start**, **Stop**, or **Restart** that unit.
- **Public mail ports** — combines the server's local listener table with connections from the Openship
control plane to the public DNS address on TCP 25, 465, 587, and 993. The UI poll reuses one result for 60
seconds, so this is a bounded health check rather than a continuous port watcher.
- **Outbound delivery** — shows the direct/relay send path, queue depth, and actionable deferral reasons.
- **DNS scan** — a live public-DNS check of every expected record, with a **Rescan** button.
Opening UFW or firewalld on the server does not change OCI security lists, AWS security groups, GCP firewall
rules, Azure NSGs, or another provider firewall. A row that says **Blocked** while the daemon is listening
usually means this outer layer is dropping the connection.
### Backup
Backups run through Openship's general backup system, so the mail server is just another backup source.
Choose **what to back up**: accounts, domains & aliases (always included), **Mailbox message data** (the
maildirs — can be large), and **DKIM keys & secrets**.
Including keys means the archive holds password hashes, DKIM private keys, and plaintext secrets. Keep the
destination private.
Pick a **Destination** (managed on the [Backups](/docs/dashboard/backups) page) and an **Automatic backups**
schedule (Manual only / Daily / Weekly), then **Save settings** or **Back up now**. **Recent backups** lists
each run; successful runs offer **Restore** (in place) and **Migrate** (onto another server).
### Advanced
**Mail certificate** shows expiry and the certificate served by SMTP (465/587) and IMAP (993).
**Check certificate** refreshes those observations. **Renew certificate** uses the existing Openship
edge to obtain a certificate when due, reloads Postfix and Dovecot, and checks the served certificates.
A certificate that is still valid is reused, so repeated clicks do not create extra ACME orders.
**Automatic renewal** is enabled by default for each mail server. It uses the shared **SSL certificate
renewal** job; disabling the mail toggle leaves certificate monitoring active. Expiry, failed renewal,
and services still serving an old certificate appear in **Health** and global **Monitoring**.
The checks share a five-minute cache; Monitoring's re-scan refreshes them immediately.
The Openship control plane must remain running for scheduled renewal. In Desktop, keep Openship open;
for unattended operation, run a self-hosted control plane. When adopting a legacy mail host, Openship
retires a host Certbot timer only if it manages this mail certificate alone. A timer that also manages
other certificates is left unchanged and reported for migration.
The power-user surface, top to bottom:
- **Protocol settings** — the host/port/encryption pairs for **Incoming · IMAP** (SSL/TLS) and **Outgoing ·
SMTP** (STARTTLS), for wiring a client by hand.
- **Mail-stack tools** — **Restart stack** cycles every mail daemon at once (a quick fix after a deploy
hiccup); it doesn't touch mailboxes, queues, or state.
- **Danger zone** — **Re-run setup wizard** (**Open wizard**), **Reset on-server state** (**Reset state** —
clears Openship's tracking but leaves the running stack intact), and **Remove mail server** (**Remove** —
drops it from the list only, re-adoptable later).
- **Install metadata** — Server ID, Primary domain, and the Started / Finished timestamps.
## Related
---
# Error reporting
URL: https://openship.io/docs/api/diagnostics.md
Correlate API failures and understand Cloud-only diagnostic collection.
Openship API responses include an `X-Request-ID`. Include this reference when reporting a failure. The
Cloud diagnostic event associates it with the error category, operation, stack and authorized
resource identifiers where available. An incoming request ID is only a parent reference; each API
request receives a new server-generated ID.
Automatic error collection is enabled only in Openship Cloud. The SaaS API stores redacted events
in an automatically created diagnostics table in its existing database and keeps its local JSON logs.
Self-hosted and Desktop installations do not collect or upload diagnostic events, including recovered
catches. Connecting a local installation to Cloud does not enable uploads. Intentional local warnings
and fatal error output remain available. Application logs, deployment logs and the security audit log
keep their existing purposes.
## Browser reports
The Cloud dashboard automatically submits errors to its serving API. The endpoint is available only
in Cloud and returns 404 on local installations. It is public so sign-in
and initialization failures can be reported. It cannot read logs or act on resources. Payloads cannot
assert a user, organization, severity or trusted API result, and every accepted event is marked
`untrusted` and redacted again by the server.
The body is an object with an `events` array of one to eight entries:
| Field | Limit | Meaning |
| --- | --- | --- |
| `name` | 80 characters | Error name; required. |
| `message` | 2,049 characters | Redacted message; required. |
| `component` | 1–160 characters | Optional source module label, such as `dashboard/hooks/useBuildConnection`; untrusted. |
| `stack` | 4,097 characters | Optional redacted stack. |
| `code` | 100 characters | Optional letters, digits, underscores, periods and hyphens. |
| `page` | 512 characters | Optional page path. Queries and invitation tokens are removed. |
| `requestId` | UUID | Optional parent API reference; not an identity. |
| `eventId` | 100 characters | Optional client reference; the server generates its own event and error IDs. |
Requests are limited to 64 KiB and 20 batches per minute per IP, including loopback requests. Extra
fields and invalid JSON are rejected with `400`, oversized bodies with `413`, and excess requests
with `429` and `Retry-After`. Accepted batches return `204` with `Cache-Control: no-store`.
During a Desktop connection to a remote instance, UI collection stays disabled. A remote Cloud API
can still record failures of requests it handles using its authorized context.
Delivery is best effort with a bounded memory buffer. Reporting does not delay the operation while
waiting for an exporter. Buffer overflow and failed delivery produce explicit local diagnostic events;
process termination or loss of the local output can still lose events. This is not a durable audit log.
## HTTP endpoint
{/* api-operations:start */}
| Operation | REST API |
| --- | --- |
| Submit bounded, untrusted dashboard error reports. Public, rate-limited intake with no read access. | `POST /api/diagnostics/client-errors` `Handler authentication` |
{/* api-operations:end */}
---
# Actions
URL: https://openship.io/docs/api/actions.md
Configure GitHub-compatible workflows, select runners, and inspect durable execution.
`ship.actions` uses the same operations as the dashboard and REST API. All user
operations require the selected organization and `job` permissions. Workflow
access also checks the originating user's repository, runner and storage access.
Configuring a runner requires administration access to its server.
See [Openship Actions](/docs/guides/actions) for supported syntax, destination
requirements, fork restrictions and compatibility limits.
## Configure and dispatch
Select runner IDs from `actions.runners()`. Saving an existing repository file
does not execute it; dispatch resolves a commit and saves an immutable snapshot.
```ts
const workflow = await ship.actions.create({
controller: "openship",
name: "CI",
owner: "your-organization",
repo: "your-app",
ref: "main",
path: ".openship/workflows/ci.yml",
runnerIds: ["runner_123"],
});
const run = await ship.actions.dispatch(workflow.id, {
idempotencyKey: crypto.randomUUID(),
});
```
Reuse the original idempotency key after a timeout or lost response. A new key
requests a new run. `rerun(runId, { idempotencyKey })` uses the saved revision,
definition and configuration as a new attempt.
`create` and `update` accept the same complete workflow configuration. Optional
`source` contains inline YAML; otherwise Openship reads the repository file.
`variables` are plain environment values. `secrets` adds or replaces only the
provided encrypted entries; `removeSecrets` explicitly removes named entries.
`storageDestinationId` selects an authorized backup destination for artifacts and
cache. Reads return secret names, never their values.
Optional `accessPolicy` configures `audience` (`owner`, `selected` or
`collaborators`), `users` (1–30 GitHub usernames for selected-user access),
`approval` (`required` or `automatic`) and `forks` (`deny` or `review`). New
workflows default to the owner, required approval and denied forks. The server
resolves GitHub identities and never accepts account IDs supplied by the caller.
Fork review requires a disposable Cloud runner and always needs approval.
Run details exposes `admission`, `runnerIds` and `canApprove`. When admission is
`approval_required`, review the commit, attempt, requester and destinations, then
send `{ key: run.admission.key }` to `approve`. A changed review returns a conflict;
refresh the run before approving again. Approval requires `job:admin` and
administration of the current destinations. `canApprove` is a presentation hint;
the mutation checks permissions again. The legacy no-body approval remains only
for independent fork runs without a saved access policy.
`importWorkflows({ workflows })` accepts up to 50 complete configurations from one
repository and branch. It validates all new files, then saves workflows and project
links in one transaction. Repeating the import reuses each file's existing record,
preserves its settings and adds new authorized project links. Use `update` to change
an already imported workflow. Importing does not commit repository changes or start runs.
For a standalone workflow, omit `owner` and `repo` and provide `source`. It can run
manually, on a schedule, from an authenticated webhook, or through a Job without
GitHub credentials. `actions/checkout` needs an explicit `with.repository` in this mode.
Optional `projectIds` associates a workflow with projects the caller can edit.
`actions.projectPolicy(projectId)` reads linked workflows and pending deployment requests;
`actions.updateProjectPolicy(projectId, input)` selects manual, push, or required-check
deployment. Required workflows must cover every push to the project's branch without
path filters. Linking workflows alone does not enable automatic deployment.
`dispatch` accepts either declared manual `inputs` or an `eventType` and optional
`clientPayload` for `repository_dispatch`. Both use normal API authentication and the
caller's selected organization. See the [webhook example](/docs/guides/actions#triggers-and-jobs).
## GitHub-controlled workflows
Use `controller: "github"`, `source: null` and a committed `.github/workflows/*.yml`
file. Configure `accessPolicy` to control which matching jobs may execute on its
destinations. The old `repositoryRunnerConsent` field is accepted for compatibility
but grants no permission. GitHub manages secrets, variables, artifacts and
Checks; omit Openship secrets, variables and storage settings in this mode.
`preview`, `repositorySource` and `updateRepositorySource` infer the controller from
the file path: `.github/workflows/` uses GitHub, while `.openship/workflows/` and
standalone YAML use the independent controller. API callers may also provide an
explicit `controller`.
GitHub mode dispatches `workflow_dispatch` through GitHub and mirrors the exact
returned run ID and attempt. It delegates reruns and cancellation to GitHub. Reuse
request keys: an uncertain GitHub POST is never automatically replayed. An accepted
command whose run is not visible yet will appear through reconciliation. Send
`repository_dispatch` and other GitHub events to GitHub's own API.
Run and job views include `externalUrl`. GitHub live logs open at that URL;
`jobEvents` provides the completed log preview with the same cursor contract.
`settledAt` also waits for Openship's runner cleanup. Native GitHub Check IDs and
conclusions are preserved without creating duplicate Checks.
## Observe and cancel
```ts
const current = await ship.actions.getRun("run_123");
for (const job of current.jobs) {
const output = await ship.actions.jobEvents(job.id, { after: 0 });
console.log(output.events);
// Save output.next and use it as after when polling or reconnecting.
}
await ship.actions.cancel(current.id);
```
Cancellation is a durable request. Job `cleanedAt` confirms destination cleanup;
run `settledAt` confirms all jobs and GitHub Checks have settled. A disconnected
controller resumes inspection of the original worker rather than replaying it.
Artifact download links expire after 60 seconds. The runtime protocol endpoints
below authenticate scoped job capabilities and recheck their saved authority.
They do not accept a user session as an upload grant. `/twirp` is also exposed at
the API origin because the official cache client resolves that absolute path.
Preserve both paths when configuring an external reverse proxy.
## Operations
{/* api-operations:start */}
### Workflows
| Operation | SDK | REST API |
| --- | --- | --- |
| List authorized workflows. | `actions.list(input?)` | `GET /api/actions/workflows` `job:read` |
| Configure a workflow and its allowed runners. Encrypts secrets without returning their values. | `actions.create(input)` | `POST /api/actions/workflows` `job:write` |
| Read a workflow definition, runner selection and secret names. | `actions.get(id)` | `GET /api/actions/workflows/:id` `job:read` |
| Replace workflow configuration while preserving secret values omitted from the update. | `actions.update(id, input)` | `PATCH /api/actions/workflows/:id` `job:write` |
| Disable a workflow without deleting its run history. | `actions.remove(id)` | `DELETE /api/actions/workflows/:id` `job:write` |
| Validate YAML and inspect logical job dependencies without executing the workflow. | `actions.preview(input)` | `POST /api/actions/preview` `job:read` |
| List workflow files at an authorized repository revision. | `actions.discover(input)` | `GET /api/actions/discover` `job:read` |
| Import up to 50 files from one repository and branch in one transaction. Reuses existing workflows without replacing their settings and adds authorized project links. | `actions.importWorkflows(input)` | `POST /api/actions/workflows/import` `job:write` |
### Runners
| Operation | SDK | REST API |
| --- | --- | --- |
| List authorized runners and their verified capabilities. | `actions.runners()` | `GET /api/actions/runners` `job:read` |
| Enable a runner on a connected server. Requires server administration access. | `actions.addRunner(input)` | `POST /api/actions/runners` `job:admin` |
| Inspect OS, architecture, Git, Node and Docker on an authorized server. | `actions.inspectDestination(input)` | `POST /api/actions/runners/inspect` `job:admin` |
| Enable and verify Docker CPU emulation. Requires administration of the selected server. | `actions.enableEmulation(input)` | `POST /api/actions/runners/emulation` `job:admin` |
| Update an idle runner; active execution settings cannot be changed. | `actions.updateRunner(id, input)` | `PATCH /api/actions/runners/:id` `job:admin` |
| Disable a runner for new jobs while retaining active work and history. | `actions.removeRunner(id)` | `DELETE /api/actions/runners/:id` `job:admin` |
| Refresh a runner’s verified capabilities. | `actions.probeRunner(id)` | `POST /api/actions/runners/:id/probe` `job:admin` |
### Runs
| Operation | SDK | REST API |
| --- | --- | --- |
| Dispatch a manual or authenticated webhook event with an idempotency key and immutable source. | `actions.dispatch(id, input)` | `POST /api/actions/workflows/:id/dispatch` `job:write` |
| List recent runs, optionally filtered by workflow or linked project. | `actions.listRuns(input?)` | `GET /api/actions/runs` `job:read` |
| Read durable run, job, matrix and step state. | `actions.getRun(id)` | `GET /api/actions/runs/:id` `job:read` |
| Request cancellation; runner capacity remains held until cleanup is confirmed. | `actions.cancel(id)` | `POST /api/actions/runs/:id/cancel` `job:write` |
| Approve the reviewed commit and attempt using its current admission key. Requires administration of the selected destinations. | `actions.approve(id, input?)` | `POST /api/actions/runs/:id/approve` `job:admin` |
| Create a new attempt of the saved workflow and commit using an idempotency key. | `actions.rerun(id, input)` | `POST /api/actions/runs/:id/rerun` `job:write` |
### Output
| Operation | SDK | REST API |
| --- | --- | --- |
| Read masked job events after a durable sequence cursor. | `actions.jobEvents(id, input?)` | `GET /api/actions/jobs/:id/events` `job:read` |
| List retained artifacts belonging to an authorized run. | `actions.artifacts(id)` | `GET /api/actions/runs/:id/artifacts` `job:read` |
| Create a short-lived link for one authorized run artifact. | `actions.artifactDownload(id, input)` | `POST /api/actions/runs/:id/artifacts/download` `job:read` |
### Project integration
| Operation | SDK | REST API |
| --- | --- | --- |
| Read an authorized workflow file and its GitHub content SHA for review. | `actions.repositorySource(input)` | `GET /api/actions/repository-source` `job:read` |
| Commit a reviewed workflow change to a branch, guarded by the original content SHA and repository write access. | `actions.updateRepositorySource(input)` | `PUT /api/actions/repository-source` `job:write` |
| List projects available for workflow associations. | `actions.projects()` | `GET /api/actions/projects` `job:read` |
| Read linked workflows, required checks and pending deployment requests for a project. | `actions.projectPolicy(input)` | `GET /api/actions/project` `job:read` |
| Choose manual, push or required-check deployments and link existing workflows. | `actions.updateProjectPolicy(input)` | `PUT /api/actions/project` `job:write` |
| Retry or cancel an unaccepted required-check deployment request without duplicating deployment. | `actions.updateDeploymentRequest(input)` | `POST /api/actions/project/requests` `job:write` |
| Read the connected GitHub account and verify repository Checks access without starting a workflow or publishing a Check. | `actions.repositoryChecks(input)` | `GET /api/actions/repository-checks` `job:read` |
### Job runtime protocols
| Operation | SDK | REST API |
| --- | --- | --- |
| Resolve a legacy cache entry. Requires a purpose-bound job capability. | HTTP only | `GET /api/actions/runtime/_apis/artifactcache/cache` `Handler authentication` |
| Reserve a legacy cache upload. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/_apis/artifactcache/caches` `Handler authentication` |
| Upload a legacy cache byte range. Requires a purpose-bound job capability. | HTTP only | `PATCH /api/actions/runtime/_apis/artifactcache/caches/:id` `Handler authentication` |
| Finalize a legacy cache upload. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/_apis/artifactcache/caches/:id` `Handler authentication` |
| Read an object or byte range. Requires a purpose-bound job capability. | HTTP only | `GET /api/actions/runtime/objects/:id` `Handler authentication` |
| Upload an authorized object or block. Requires a purpose-bound job capability. | HTTP only | `PUT /api/actions/runtime/objects/:id` `Handler authentication` |
| Reserve an artifact upload. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/CreateArtifact` `Handler authentication` |
| Remove an artifact owned by this job. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/DeleteArtifact` `Handler authentication` |
| Finalize a completed artifact upload. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/FinalizeArtifact` `Handler authentication` |
| Obtain a short-lived artifact URL. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/GetSignedArtifactURL` `Handler authentication` |
| List artifacts available to this job. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/ListArtifacts` `Handler authentication` |
| Reserve a cache upload. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.CacheService/CreateCacheEntry` `Handler authentication` |
| Finalize a cache upload. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.CacheService/FinalizeCacheEntryUpload` `Handler authentication` |
| Resolve a compatible cache entry. Requires a purpose-bound job capability. | HTTP only | `POST /api/actions/runtime/twirp/github.actions.results.api.v1.CacheService/GetCacheEntryDownloadURL` `Handler authentication` |
| Reserve an artifact upload. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.ArtifactService/CreateArtifact` `Handler authentication` |
| Remove an artifact owned by this job. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.ArtifactService/DeleteArtifact` `Handler authentication` |
| Finalize a completed artifact upload. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.ArtifactService/FinalizeArtifact` `Handler authentication` |
| Obtain a short-lived artifact URL. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.ArtifactService/GetSignedArtifactURL` `Handler authentication` |
| List artifacts available to this job. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.ArtifactService/ListArtifacts` `Handler authentication` |
| Reserve a cache upload. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.CacheService/CreateCacheEntry` `Handler authentication` |
| Finalize a cache upload. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.CacheService/FinalizeCacheEntryUpload` `Handler authentication` |
| Resolve a compatible cache entry. Requires a purpose-bound job capability. | HTTP only | `POST /twirp/github.actions.results.api.v1.CacheService/GetCacheEntryDownloadURL` `Handler authentication` |
| Discover the configured Openship identity issuer. Public HTTPS metadata contains no credentials. | HTTP only | `GET /api/actions/oidc/.well-known/openid-configuration` `Handler authentication` |
| Read the issuer's RSA verification keys. Only public parameters are returned. | HTTP only | `GET /api/actions/oidc/jwks` `Handler authentication` |
| Request a five-minute identity for an approved running job with id-token: write. Requires a job-bound OIDC capability and rechecks authority, destination and cancellation. | HTTP only | `GET /api/actions/oidc/token` `Handler authentication` |
{/* api-operations:end */}
---
# Mail
URL: https://openship.io/docs/api/mail.md
Set up and operate a self-hosted mail server.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Mail API drives Openship's self-hosted email feature: it installs an [iRedMail](https://www.iredmail.org)
stack on one of your servers over SSH, tracks the wizard's progress, then exposes an admin panel for the
running server — domains, mailboxes, stats, backups, DNS health, and per-component control — plus a one-click
webmail deploy. In the dashboard this is the **Emails** page.
Every route here is gated by `localOnly` and is **never mounted in Openship Cloud** — the module is
dynamically imported only on self-hosted instances. On a cloud instance these paths return `404`.
Most paths carry a `:serverId` (or take one in the body / `?serverId=`). Openship checks that the server
belongs to your organization on every call — a `mail_server` grants SSH-level reach into the box, so a
`serverId` outside your org returns `404`, indistinguishable from one that doesn't exist.
## Start (or resume) setup
Kicks off the iRedMail install wizard against a server and streams progress as
[Server-Sent Events](https://developer.mozilla.org/en-US/docs/Web/API/Server-sent_events). The wizard is
idempotent: re-POST with `startStep` to resume from where a previous run stopped (or was gated). Only one
install may run per instance at a time.
```
POST /api/mail/setup
```
.', required: true },
startStep: { type: 'number', description: 'Step to start/resume from (clamped to 1..total).', default: '1' },
config: { type: 'IRedMailConfig', description: 'Optional install config (see below).' },
}}
/>
`config` is an optional `IRedMailConfig`:
', description: 'Previously-generated secrets to reuse on a retry, keyed as iRedMail expects (e.g. VMAIL_DB_BIND_PASSWD).' },
}}
/>
```bash
curl -N -X POST "$OPENSHIP_URL/api/mail/setup" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123","domain":"example.com"}'
```
The stream emits `step_start`, `log`, and `step_done` events per step, plus these control events:
- `dns_records` / `dns_pending` — the DKIM step publishes the records you must add, then **holds**. Add the
records at your DNS provider and call `POST /api/mail/setup/dns-ack`, then re-POST `/setup` with the
`resumeStep` from the event.
- `ptr_pending` — after DNS is acknowledged, the wizard holds again for reverse-DNS (PTR). Set the PTR record
at your VPS provider, call `POST /api/mail/setup/ptr-ack`, and resume.
- `complete` — carries `domain`, `webmailUrl`, and `adminUrl`.
- `error` — carries `message` and (when resumable) `resumeStep`.
The terminal `verify_reachability` step reads the target's TCP listener table and then connects from the API
host to the public-DNS address on 25, 465, 587, and 993. Listener failures and off-box failures remain distinct
in the result. A measured failure blocks completion and points at both the host firewall and the provider-level
firewall/security group/security list/NSG; an unavailable probe is returned as a non-blocking warning rather
than being invented as an outage.
`GET /api/mail/health/:serverId` reuses one public-port sweep for 60 seconds. Pass
`?refreshReachability=1` after changing firewall rules to force an immediate recheck; concurrent requests are
still coalesced into one bounded four-port probe.
## Acknowledge DNS / PTR
Both flip a single flag in the on-server state file so the wizard can move past its gate on the next `/setup`
POST. Both take the same body.
```
POST /api/mail/setup/dns-ack
POST /api/mail/setup/ptr-ack
```
The same `{ serverId }` body applies to `POST /api/mail/scan`, `POST /api/mail/adopt`,
`POST /api/mail/setup/cancel`, and `POST /api/mail/setup/reset`.
## Adopt an existing install
If Openship lost its record of a mail server (rebuilt desktop, wiped DB), scan the server, then adopt it —
no reinstall, nothing changes on the box.
```
POST /api/mail/scan
POST /api/mail/adopt
```
```bash
# 1. Probe for iRedMail + its on-server state
curl -X POST "$OPENSHIP_URL/api/mail/scan" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123"}'
# 2. Re-adopt it (idempotent)
curl -X POST "$OPENSHIP_URL/api/mail/adopt" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123"}'
```
## Rotate the postmaster password
```
POST /api/mail/credentials/postmaster
```
## Add a mail domain
```
POST /api/mail/admin/:serverId/domains
```
`PATCH /api/mail/admin/:serverId/domains/:domain` accepts the same fields (all optional) plus
`active` (boolean).
```bash
curl -X POST "$OPENSHIP_URL/api/mail/admin/srv_123/domains" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"domain":"example.com","defaultQuotaMB":2048}'
```
## Create a mailbox
```
POST /api/mail/admin/:serverId/mailboxes
```
`PATCH /api/mail/admin/:serverId/mailboxes/:email` accepts `name`, `password`, `quotaMB`, and `active`
(all optional). `DELETE` soft-deletes by default; add `?hard=true` to purge the maildir.
```bash
curl -X POST "$OPENSHIP_URL/api/mail/admin/srv_123/mailboxes" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"localPart":"alice","domain":"example.com","password":"a-strong-password"}'
```
## Configure backups
Plugs the mail server into the general [backup system](/docs/api/backups) — pick a destination and what to
capture. Requires an existing backup destination in your organization.
```
POST /api/mail/admin/:serverId/backup-policy
```
## Send a test email
```
POST /api/mail/admin/:serverId/test-email
```
## Deploy webmail
Installs the **webmail** app from the app catalog, pointed at this mail server's IMAP/SMTP, then queues a
deployment and starts it. Returns `{ deploymentId, projectId }` so the dashboard can redirect to
`/build/[deploymentId]`. Re-deploying an existing webmail reuses its project (and its stored sessions).
The IMAP/SMTP backend is derived from the mail server — `mail.` on 993/465 — so there is nothing
to configure here. To point a webmail at a mailbox host you run elsewhere, install the `webmail` app from
`/apps` (or use `POST /api/mail/webmail/deploy-external`) instead.
```
POST /api/mail/webmail/deploy-project
```
`target` is one of:
- `{ "kind": "self", "serverId": "srv_123" }` — self-hosted on one of your Openship servers.
- `{ "kind": "cloud", "serverId": "srv_managed" }` — on a selected managed Openship Cloud server.
Both targets need a real server ID. Use `GET /api/system/servers/destinations` to list accessible servers.
For a Cloud server that is not connected to this installation yet, use
`POST /api/system/servers/managed/connect` and pass its returned **local** `serverId` here. The dashboard
uses the same connection flow. A missing Cloud destination is refused before creating a webmail project.
Redeploying an existing managed webmail preserves its server binding; moving it to another server requires
the normal project migration flow.
```bash
curl -X POST "$OPENSHIP_URL/api/mail/webmail/deploy-project" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"mailServerId":"srv_123","hostname":"mail.example.com","target":{"kind":"self","serverId":"srv_123"}}'
```
### Reconnecting an existing webmail
Forgetting and re-adopting a mail server can leave its catalog webmail running
with a missing control-plane link. `mail.getStatus({ serverId })` returns
`webmailRecoveryCandidates` for accessible, unlinked catalog apps on that mail
server which already route its `mail.` hostname. Reading status grants
no routing rights.
Choose the existing app in **Emails → Deploy webmail**, then press **Reconnect
and deploy**. With the SDK, pass its `projectId` as `reconnectProjectId` to
`mail.deployWebmail(input)`; the CLI accepts the same input through
`mail webmail deploy reconnect.json`. Keep the app's existing server and mail hostname
for this recovery. It reuses the project, service, generated credentials and
persistent volumes, and restores the link before queuing deployment. The mail
certificate record stays owned by the mail service.
An omitted selection returns `WEBMAIL_RECONNECT_REQUIRED` when a recoverable
app exists. `WEBMAIL_LINK_CHANGED` means another operation changed the link;
refresh status and review the current app before retrying. A project from
another organization, another mail server's linked app, or a different
destination cannot be adopted through this path.
### Replacing a pre-catalog webmail
Openship 0.6.1 and earlier shipped webmail as a prebuilt bundle rather than an image. Those installs can't be
redeployed — they have to be **replaced** by the catalog app. `GET /api/mail/status` reports one as
`webmail.legacy: true`, and a deploy over it is refused with `409` and `"code": "LEGACY_WEBMAIL"` until you
retry the same request with `replaceLegacy: true`.
The replace tears the old project down — container, routes, host state directory, project row — and then
installs the webmail app at the same hostname. Mailboxes, mail data and every message live on the mail server
and are untouched; the old webmail's sign-in sessions and per-user settings are not, so everyone signs in
again. If the old install can't be removed, nothing is installed and the existing webmail keeps running.
## Errors
`GET /api/mail/status` could not read the server's saved setup state. Preserve any last-known
details and retry the read; this response does not mean mail is stopped or uninstalled.
If the saved state was read but the live engine check failed, the response instead keeps that
state, omits `engine`, and includes `observationError`. Treat engine health as unknown.
You're calling a cloud instance. The Mail API is self-hosted only; run it on an instance where `CLOUD_MODE`
is off.
The `:serverId` doesn't belong to your organization (or doesn't exist). List your mail servers with
`GET /api/mail/servers` to get valid IDs.
Only one install runs per instance at a time, and per-server writes (reset, postmaster rotation) are refused
while its setup is active. Wait for it to finish, or cancel it with `POST /api/mail/setup/cancel`.
The webmail linked to this mail server predates the catalog app, so it can only be replaced. Retry the same
`deploy-project` call with `replaceLegacy: true` once you've confirmed the operator accepts losing the old
webmail's sessions and per-user settings.
Openship couldn't reach the server over SSH, or the probe threw. Check the server is online and its SSH
credentials are valid, then retry.
## Operations
## SDK and CLI
The remote SDK exposes `client.mail`; its methods below cover setup, health and administration through
the same server permissions as the dashboard. Certificate renewal uses the existing edge pipeline.
```ts
const certificate = await client.mail.getCertificate("srv_mail");
await client.mail.updateCertificate("srv_mail", { autoRenew: true });
const domains = await client.mail.listDomains("srv_mail");
const mailboxes = await client.mail.listMailboxes("srv_mail", { domain: "example.com" });
```
`client.mail.setup(input)` returns the existing event stream. Observe its completion or DNS/PTR
checkpoint before continuing. The CLI supplies `mail setup`, `mail domain`, `mail mailbox`, `mail alias`,
`mail relay`, `mail certificate`, `mail backup`, `mail inbound`, `mail component` and `mail webmail`.
Use `--schema` for JSON configuration commands. Mail is a remote, self-hosted feature.
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List all setup steps and the total count. | `mail.getSteps()` Remote client | `GET /api/mail/steps` `mail_server:read` · Self-hosted |
| Current setup progress for a server (rendered from its on-server state file). | `mail.getStatus(input?)` Remote client | `GET /api/mail/status` `mail_server:read` · Self-hosted |
| List every server Openship has provisioned (or is provisioning) mail on. | `mail.listServers()` Remote client | `GET /api/mail/servers` `mail_server:list` · Self-hosted |
| Probe a server for an existing iRedMail install + its on-server state (read-only). | `mail.scan(input)` Remote client | `POST /api/mail/scan` `mail_server:write` · Self-hosted |
| Re-adopt a scanned server whose orchestrator state was lost. | `mail.adopt(input)` Remote client | `POST /api/mail/adopt` `mail_server:write` · Self-hosted |
| Cancel the running setup. | `mail.cancelSetup()` Remote client | `POST /api/mail/setup/cancel` `mail_server:write` · Self-hosted |
| Mark DNS (DKIM) records as configured, releasing the DNS gate. | `mail.acknowledgeDns(input)` Remote client | `POST /api/mail/setup/dns-ack` `mail_server:write` · Self-hosted |
| Mark reverse-DNS (PTR) as configured, releasing the PTR gate. | `mail.acknowledgePtr(input)` Remote client | `POST /api/mail/setup/ptr-ack` `mail_server:write` · Self-hosted |
| Wipe the on-server state file (does not touch iRedMail). | `mail.resetSetup(input)` Remote client | `POST /api/mail/setup/reset` `mail_server:admin` · Self-hosted |
| Rotate the postmaster account password. | `mail.setPostmasterPassword(input)` Remote client | `POST /api/mail/credentials/postmaster` `mail_server:write` · Self-hosted |
| List deploy-target options (self-hosted servers / cloud). | `mail.getWebmailTargets(input)` Remote client | `GET /api/mail/webmail/targets` `mail_server:read` · Self-hosted |
| Install or redeploy webmail; reconnectProjectId explicitly recovers an existing app after its mail-server link was lost. | `mail.deployWebmail(input)` Remote client | `POST /api/mail/webmail/deploy-project` `mail_server:write` · Self-hosted |
| Deploy webmail for an external mail server. | `mail.deployExternalWebmail(input)` Remote client | `POST /api/mail/webmail/deploy-external` `mail_server:write` · Self-hosted |
| Stop managing a server (drops the DB row only; leaves the stack + state file intact). | `mail.forget(id)` Remote client | `DELETE /api/mail/servers/:serverId` `mail_server:admin` · Self-hosted |
| Mail daemons, outbound delivery, and cached public-port reachability (TCP 25/465/587/993). | `mail.getHealth(id, input?)` Remote client | `GET /api/mail/health/:serverId` `mail_server:read` · Self-hosted |
| Read the mail certificate, SMTP/IMAP TLS checks and automatic renewal settings. | `mail.getCertificate(id)` Remote client | `GET /api/mail/admin/:serverId/certificate` `mail_server:read` · Self-hosted |
| Recheck the certificate on disk and served by SMTP/IMAP without issuing a certificate or sending email. | `mail.checkCertificate(id)` Remote client | `POST /api/mail/admin/:serverId/certificate/check` `mail_server:write` · Self-hosted |
| Renew a due mail certificate through Openship Edge and reload Postfix/Dovecot, reusing a still-valid certificate and repairing its service configuration. | `mail.renewCertificate(id)` Remote client | `POST /api/mail/admin/:serverId/certificate/renew` `mail_server:admin` · Self-hosted |
| Set `autoRenew` to enable or disable automatic mail certificate renewal. Monitoring continues when renewal is disabled. | `mail.updateCertificate(id, input)` Remote client | `PATCH /api/mail/admin/:serverId/certificate` `mail_server:admin` · Self-hosted |
| List mail domains on the server. | `mail.listDomains(id)` Remote client | `GET /api/mail/admin/:serverId/domains` `mail_server:list` · Self-hosted |
| Add a mail domain. | `mail.createDomain(id, input)` Remote client | `POST /api/mail/admin/:serverId/domains` `mail_server:write` · Self-hosted |
| List additional domains whose DNS is still pending. | `mail.pendingDomainDns(id)` Remote client | `GET /api/mail/admin/:serverId/domains-dns/pending` `mail_server:read` · Self-hosted |
| List mailboxes in a domain. | `mail.listMailboxes(id, input)` Remote client | `GET /api/mail/admin/:serverId/mailboxes` `mail_server:list` · Self-hosted |
| Create a mailbox. | `mail.createMailbox(id, input)` Remote client | `POST /api/mail/admin/:serverId/mailboxes` `mail_server:write` · Self-hosted |
| Rotate the platform mailbox credential. | `mail.rotatePlatformMailbox(id)` Remote client | `POST /api/mail/admin/:serverId/platform-mailbox/rotate` `mail_server:admin` · Self-hosted |
| List mail aliases on a server. | `mail.listAliases(id, input)` Remote client | `GET /api/mail/admin/:serverId/aliases` `mail_server:list` · Self-hosted |
| Create a mail alias. | `mail.createAlias(id, input)` Remote client | `POST /api/mail/admin/:serverId/aliases` `mail_server:write` · Self-hosted |
| Aggregate counts (domains, mailboxes, storage). | `mail.getStats(id)` Remote client | `GET /api/mail/admin/:serverId/stats` `mail_server:read` · Self-hosted |
| The mail server's backup policy (or `null`). | `mail.getBackupPolicy(id)` Remote client | `GET /api/mail/admin/:serverId/backup-policy` `mail_server:read` · Self-hosted |
| Create or update the backup policy. | `mail.saveBackupPolicy(id, input)` Remote client | `POST /api/mail/admin/:serverId/backup-policy` `mail_server:admin` · Self-hosted |
| Recent backup runs for the mail server. | `mail.listBackupRuns(id)` Remote client | `GET /api/mail/admin/:serverId/backup-runs` `mail_server:read` · Self-hosted |
| Live DNS health scan (MX/SPF/DKIM/DMARC/PTR). | `mail.scanDns(id, input?)` Remote client | `GET /api/mail/admin/:serverId/dns-scan` `mail_server:read` · Self-hosted |
| Read outbound relay configuration. | `mail.getRelay(id)` Remote client | `GET /api/mail/admin/:serverId/relay` `mail_server:read` · Self-hosted |
| Configure an outbound relay. | `mail.configureRelay(id, input)` Remote client | `POST /api/mail/admin/:serverId/relay` `mail_server:admin` · Self-hosted |
| Remove outbound relay configuration. | `mail.removeRelay(id)` Remote client | `DELETE /api/mail/admin/:serverId/relay` `mail_server:admin` · Self-hosted |
| Send a test email from the server. | `mail.sendTestEmail(id, input)` Remote client | `POST /api/mail/admin/:serverId/test-email` `mail_server:write` · Self-hosted |
| Restart every mail component. | `mail.restartComponents(id)` Remote client | `POST /api/mail/admin/:serverId/components/restart-all` `mail_server:admin` · Self-hosted |
| List inbound mail rules. | `mail.listInboundRules(id)` Remote client | `GET /api/mail/admin/:serverId/inbound-rules` `mail_server:read` · Self-hosted |
| Create an inbound mail rule. | `mail.createInboundRule(id, input)` Remote client | `POST /api/mail/admin/:serverId/inbound-rules` `mail_server:write` · Self-hosted |
| Evaluate a message against inbound mail rules. | `mail.testInboundRules(id)` Remote client | `POST /api/mail/admin/:serverId/inbound-rules/test` `mail_server:write` · Self-hosted |
| Get one domain's config. | `mail.getDomain(parentId, id)` Remote client | `GET /api/mail/admin/:serverId/domains/:domain` `mail_server:read` · Self-hosted |
| Update a domain (quotas, limits, active flag). | `mail.updateDomain(parentId, id, input)` Remote client | `PATCH /api/mail/admin/:serverId/domains/:domain` `mail_server:write` · Self-hosted |
| Delete a domain (add `?cascade=true` to remove its mailboxes too). | `mail.removeDomain(parentId, id, input?)` Remote client | `DELETE /api/mail/admin/:serverId/domains/:domain` `mail_server:admin` · Self-hosted |
| Count mailboxes/aliases that depend on a domain. | `mail.domainDependents(parentId, id)` Remote client | `GET /api/mail/admin/:serverId/domains/:domain/dependents` `mail_server:read` · Self-hosted |
| DNS records + publish state for an additional domain. | `mail.getDomainDns(parentId, id)` Remote client | `GET /api/mail/admin/:serverId/domains/:domain/dns` `mail_server:read` · Self-hosted |
| Confirm a domain's DNS records are published. | `mail.acknowledgeDomainDns(parentId, id)` Remote client | `POST /api/mail/admin/:serverId/domains/:domain/dns/acknowledge` `mail_server:write` · Self-hosted |
| Preview the mail domain's DNS records. | `mail.planDomainDns(parentId, id)` Remote client | `GET /api/mail/admin/:serverId/domains/:domain/dns/plan` `mail_server:read` · Self-hosted |
| Apply the mail domain's DNS plan through a configured provider. | `mail.applyDomainDns(parentId, id)` Remote client | `POST /api/mail/admin/:serverId/domains/:domain/dns/apply` `mail_server:write` · Self-hosted |
| Get one mailbox. | `mail.getMailbox(parentId, id)` Remote client | `GET /api/mail/admin/:serverId/mailboxes/:email` `mail_server:read` · Self-hosted |
| Update a mailbox (name, password, quota, active). | `mail.updateMailbox(parentId, id, input)` Remote client | `PATCH /api/mail/admin/:serverId/mailboxes/:email` `mail_server:write` · Self-hosted |
| Delete a mailbox (add `?hard=true` to purge its maildir; default is a soft delete). | `mail.removeMailbox(parentId, id, input?)` Remote client | `DELETE /api/mail/admin/:serverId/mailboxes/:email` `mail_server:admin` · Self-hosted |
| Update a mail alias. | `mail.updateAlias(parentId, id, input)` Remote client | `PATCH /api/mail/admin/:serverId/aliases/:id` `mail_server:write` · Self-hosted |
| Remove a mail alias. | `mail.removeAlias(parentId, id)` Remote client | `DELETE /api/mail/admin/:serverId/aliases/:id` `mail_server:admin` · Self-hosted |
| Update an inbound mail rule. | `mail.updateInboundRule(parentId, id, input)` Remote client | `PATCH /api/mail/admin/:serverId/inbound-rules/:ruleId` `mail_server:write` · Self-hosted |
| Remove an inbound mail rule. | `mail.removeInboundRule(parentId, id)` Remote client | `DELETE /api/mail/admin/:serverId/inbound-rules/:ruleId` `mail_server:write` · Self-hosted |
| Tail a component's logs. | `mail.componentLogs(parentId, id, input?)` Remote client | `GET /api/mail/admin/:serverId/components/:key/logs` `mail_server:read` · Self-hosted |
| Run an action (`start`/`stop`/`restart`/…) on one component. | `mail.componentAction(parentId, id, input)` Remote client | `POST /api/mail/admin/:serverId/components/:key/:action` `mail_server:admin` · Self-hosted |
| Start or resume the install wizard — returns an SSE stream. | `mail.setup(value, options?)` Remote client | `POST /api/mail/setup` `mail_server:write` · Self-hosted |
{/* api-operations:end */}
---
# Members and permissions
URL: https://openship.io/docs/api/permissions.md
Manage organizations, members, invitations, and grants.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Permissions API runs Openship's team and access-control model: it reports whether the active org is a
team, lists the resources you can grant, creates a team organization, and manages the
per-member **grants** and invitations that scope a `restricted` member to specific projects, servers, or
other resources. In the dashboard this is the organization's **Team** tab. See
[Auth & access](/docs/security/auth) for how roles and grants combine.
User grants give a `restricted` member access to specific resources. Roles also provide their standard
permissions. Token grants and read-only restrictions are an additional limit for every role. A user
grant is `(user, resourceType, resourceId, permissions[])`; `resourceId: "*"` applies across the organization.
## List workspaces
`GET /api/permissions/workspaces` (SDK: `ship.permissions.listWorkspaces()`) returns workspace names,
`organizationId` values, slugs, team status, and effective roles, including workspaces with no projects.
The response also identifies `currentOrganizationId`, `boundOrganizationId`, `canSwitchOrganization`,
and `readOnly`. It is a membership discovery operation available to every authenticated member,
including restricted and read-only credentials.
Organization-bound credentials only see their own workspace. Unbound requests list the user's
memberships; an explicitly fixed SDK or HTTP scope returns only its selected workspace.
`canSwitchOrganization` describes whether the credential permits selecting other memberships.
The response contains workspace identity metadata, without billing credentials or runtime namespace details.
Through MCP, call `get_permissions_workspaces` with `{}`, then pass the chosen `organizationId` as a
top-level argument when creating an app or Compose project. See [MCP workspace selection](/docs/api/mcp#discover-and-select-a-workspace).
## Create a team organization
Creates a brand-new organization, marks it as a team, and sets the caller as its owner. Personal workspaces
stay personal — this is the way to get a shared, multi-member org.
```ts
const result = await ship.permissions.createTeamOrg({
name: "Acme Platform",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/permissions/create-team-org" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"Acme Platform"}'
```
Returns `201` with `{ data: { id, name, isTeam: true } }`.
## List grantable resources
Side-effect-free picker payload for the grant modal and invite flow. Pass the resource `type`; get back
`{ id, label, meta? }[]`. The `*` wildcard is not listed — the picker adds it itself.
```ts
const result = await ship.permissions.listResources({
type: "server",
});
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/permissions/resources?type=server" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
For `type=billing` or `type=audit` the only entry is the org-wide `*`. For `type=github_repository` you can
narrow to one account with `&owner=`.
## Grant a resource
Idempotent upsert of a single grant tuple. Re-sending the same `(userId, resourceType, resourceId)` replaces
its `permissions` in place. An **empty `permissions` array revokes** the grant (Openship keeps no
zero-permission placeholder rows).
```ts
const result = await ship.permissions.upsertGrant({
userId: "user_123",
resourceType: "project",
resourceId: "proj_abc",
permissions: ["read", "write"],
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/permissions/grants" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"userId":"user_123","resourceType":"project","resourceId":"proj_abc","permissions":["read","write"]}'
```
Returns `201` with `{ data: }`, or `{ data: null, revoked: true }` when `permissions` was empty.
## Replace a member's grant set
Sends the member's **entire** desired grant set; the server diffs against what exists — upserting
added/changed tuples and deleting any that are absent. This is the single save path for the member-grants
editor. Zero-permission entries are dropped.
```ts
const result = await ship.permissions.replaceGrants({
userId: "user_123",
grants: [
{
resourceType: "project",
resourceId: "proj_abc",
permissions: ["read", "write"],
},
{
resourceType: "server",
resourceId: "srv_1",
permissions: ["read"],
},
],
});
console.log(result);
```
```bash
curl -X PUT "$OPENSHIP_URL/api/permissions/grants" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"userId":"user_123",
"grants":[
{"resourceType":"project","resourceId":"proj_abc","permissions":["read","write"]},
{"resourceType":"server","resourceId":"srv_1","permissions":["read"]}
]
}'
```
Each entry of `grants` is a `Grant` object:
Non-wildcard, row-backed resources are checked to belong to the active org; a foreign id is rejected with
`400 RESOURCE_NOT_IN_ORG`.
## Invite a member with grants
Wraps Better Auth's invite and, in the same call, stores **pending** grants against the invitation. When the
invitee accepts, the accept-invite page calls `POST /invitations/:id/materialize` to turn those pending
grants into real ones.
```ts
const result = await ship.permissions.inviteWithGrants({
email: "dev@acme.com",
role: "restricted",
grants: [
{
resourceType: "project",
resourceId: "proj_abc",
permissions: ["read", "write"],
},
],
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/permissions/invite-with-grants" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"email":"dev@acme.com",
"role":"restricted",
"grants":[{"resourceType":"project","resourceId":"proj_abc","permissions":["read","write"]}]
}'
```
Returns `201` with `{ data: { id, email, role, pendingGrantCount } }`.
## Materialize an invitation's grants
Called from the accept-invite page after Better Auth records the acceptance. It finds the invitation's
pending grants, upserts them as real grants for the now-joined user, and clears the pending rows. Authorized
by the invitation itself — the caller's email must match the invite and its status must be `accepted`.
```ts
const result = await ship.permissions.materializeInvitation("inv_123");
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/permissions/invitations/inv_123/materialize" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Returns `{ data: { materialized: } }`.
## Errors
`userId`, `resourceType`, and `resourceId` are required on `POST /grants`; `name` is required on
`create-team-org`; `email` on `invite-with-grants`. An unknown `resourceType` returns
`code: "INVALID_RESOURCE_TYPE"`. On the invitation flow, `400` also means the invite hasn't been accepted yet
or has expired.
The grant/invitation routes require the caller to be `admin` or `owner` in the active org. On
`/invitations/:id/materialize`, `403` means your account's email doesn't match the invitation.
`POST /grants` returns `404` when the target `userId` isn't a member of the active org;
`DELETE /grants/:id` returns `404` when the id doesn't belong to your organization (grants are org-scoped, so
you can't touch another tenant's rows even by guessing the id).
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List available workspace IDs, names, roles, and credential scope. | `permissions.listWorkspaces()` | `GET /api/permissions/workspaces` `permissions:read` |
| Read the selected organization’s permission metadata. | `permissions.orgMeta()` | `GET /api/permissions/org-meta` `permissions:read` |
| List resources available for permission grants. | `permissions.listResources(input)` | `GET /api/permissions/resources` `permissions:read` |
| Create a team organization with the caller as its owner. | `permissions.createTeamOrg(input)` | `POST /api/permissions/create-team-org` `permissions:write` |
| Read grants for the requested subject. | `permissions.listGrants(input)` | `GET /api/permissions/grants` `permissions:read` |
| Create or update one resource grant. | `permissions.upsertGrant(input)` | `POST /api/permissions/grants` `permissions:write` |
| Replace the requested subject’s grant set. | `permissions.replaceGrants(input)` | `PUT /api/permissions/grants` `permissions:write` |
| List organization invitations. | `permissions.listInvitations()` | `GET /api/permissions/invitations` `permissions:read` |
| Invite a member with explicit role and optional grants. | `permissions.inviteWithGrants(input)` | `POST /api/permissions/invite-with-grants` `permissions:write` |
| List organization members. | `permissions.listMembers()` | `GET /api/permissions/members` `permissions:read` |
| Apply accepted invitation grants to the resulting membership. | `permissions.materializeInvitation(id)` | `POST /api/permissions/invitations/:id/materialize` `permissions:write` |
| Remove one grant. | `permissions.deleteGrant(id)` | `DELETE /api/permissions/grants/:id` `permissions:admin` |
| Accept an authorized invitation. | `permissions.acceptInvitation(id)` | `POST /api/permissions/invitations/:id/accept` `permissions:write` |
| Reject an invitation. | `permissions.rejectInvitation(id)` | `POST /api/permissions/invitations/:id/reject` `permissions:write` |
| Cancel a pending invitation. | `permissions.cancelInvitation(id)` | `POST /api/permissions/invitations/:id/cancel` `permissions:write` |
| Resend an eligible invitation. | `permissions.resendInvitation(id, input?)` | `POST /api/permissions/invitations/:id/resend` `permissions:write` |
| Change a member’s organization role. | `permissions.setMemberRole(id, input)` | `PATCH /api/permissions/members/:id` `permissions:write` |
| Remove a member while preserving the final owner. | `permissions.removeMember(id)` | `DELETE /api/permissions/members/:id` `permissions:admin` |
{/* api-operations:end */}
---
# MCP tool catalog
URL: https://openship.io/docs/api/mcp-tools.md
Generated tool descriptions, API mappings, availability, and intentional HTTP-only routes.
This catalog is generated from the route metadata used by MCP discovery. Run `tools/list` against your instance for its current input schemas and the tools available to your credential. See [MCP setup](/docs/mcp), [protocol and arguments](/docs/api/mcp), and the [cluster/scaling workflow](/docs/guides/mcp-clusters-and-scaling).
The current API has **512 unique tools**. Permission tags below describe the route's initial authority; shared operations also enforce workspace, resource, source-access and instance-admin requirements. Self-hosted tools are unavailable on the hosted Cloud controller.
## Tools
### actions
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_actions_runners_by_id` `DELETE /api/actions/runners/:id` | Disable a runner for new jobs, retaining active jobs and history. | `job:admin` |
| `delete_actions_workflows_by_id` `DELETE /api/actions/workflows/:id` | Disable a workflow while retaining its execution history. | `job:write` |
| `get_actions_discover` `GET /api/actions/discover` | Discover workflow files in a repository. | `job:read` |
| `get_actions_jobs_by_id_events` `GET /api/actions/jobs/:id/events` | Read masked job logs after a durable cursor. Resume with next after reconnecting. | `job:read` |
| `get_actions_project` `GET /api/actions/project` | Read project workflows and deployment automation. | `job:read` |
| `get_actions_projects` `GET /api/actions/projects` | List projects available for linking to workflows. | `job:read` |
| `get_actions_repository_checks` `GET /api/actions/repository-checks` | Read the connected account and verify Checks access for the selected repository without starting a workflow or publishing a Check. | `job:read` |
| `get_actions_repository_source` `GET /api/actions/repository-source` | Read a repository workflow and preview its topology. | `job:read` |
| `get_actions_runners` `GET /api/actions/runners` | List Actions runners and their verified OS, architecture and Docker capabilities. | `job:read` |
| `get_actions_runs` `GET /api/actions/runs` | List durable workflow runs and their job states. | `job:read` |
| `get_actions_runs_by_id` `GET /api/actions/runs/:id` | Read workflow topology, jobs, outputs and completion. | `job:read` |
| `get_actions_runs_by_id_artifacts` `GET /api/actions/runs/:id/artifacts` | List the artifacts retained for an authorized workflow run. | `job:read` |
| `get_actions_workflows` `GET /api/actions/workflows` | List authorized GitHub-compatible Openship Actions workflows. | `job:read` |
| `get_actions_workflows_by_id` `GET /api/actions/workflows/:id` | Read a configured workflow without secret values. | `job:read` |
| `patch_actions_runners_by_id` `PATCH /api/actions/runners/:id` | Update an idle runner's configuration. | `job:admin` |
| `patch_actions_workflows_by_id` `PATCH /api/actions/workflows/:id` | Update an Actions workflow's configuration. | `job:write` |
| `post_actions_preview` `POST /api/actions/preview` | Validate workflow YAML and preview its dependency graph without executing it. | `job:read` |
| `post_actions_project_requests` `POST /api/actions/project/requests` | Retry or cancel a project's pending Actions deployment approval. | `job:write` |
| `post_actions_runners` `POST /api/actions/runners` | Enable Actions on an authorized server. Native runners execute trusted workflow code as the server's connected user. | `job:admin` |
| `post_actions_runners_by_id_probe` `POST /api/actions/runners/:id/probe` | Recheck an authorized runner's capabilities. | `job:admin` |
| `post_actions_runners_emulation` `POST /api/actions/runners/emulation` | Enable and verify Docker CPU emulation on an authorized Actions server. Installs only missing binfmt emulators; does not restart Docker or applications. | `job:admin` |
| `post_actions_runners_inspect` `POST /api/actions/runners/inspect` | Check OS, architecture, Git and Docker on an authorized Actions destination without changing the server. | `job:admin` |
| `post_actions_runs_by_id_approve` `POST /api/actions/runs/:id/approve` | Approve the reviewed commit and attempt for its allowed Actions destinations. The approval key must match the current run policy. | `job:admin` |
| `post_actions_runs_by_id_artifacts_download` `POST /api/actions/runs/:id/artifacts/download` | Get a short-lived download link for one authorized artifact. | `job:read` |
| `post_actions_runs_by_id_cancel` `POST /api/actions/runs/:id/cancel` | Request cancellation. Runner capacity is released only after execution has stopped. | `job:write` |
| `post_actions_runs_by_id_rerun` `POST /api/actions/runs/:id/rerun` | Retry the same immutable workflow and commit as a new attempt. | `job:write` |
| `post_actions_workflows` `POST /api/actions/workflows` | Configure an Actions workflow and its authorized runner destinations. Secrets are encrypted and never returned. | `job:write` |
| `post_actions_workflows_by_id_dispatch` `POST /api/actions/workflows/:id/dispatch` | Dispatch a workflow using an idempotency key and an immutable resolved commit. | `job:write` |
| `post_actions_workflows_import` `POST /api/actions/workflows/import` | Import repository workflows together, reusing existing workflows and linking authorized projects. | `job:write` |
| `put_actions_project` `PUT /api/actions/project` | Configure required workflow checks before automatic project deployment. | `job:write` |
| `put_actions_repository_source` `PUT /api/actions/repository-source` | Commit reviewed workflow YAML to its branch using the expected file SHA. | `job:write` |
### analytics
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_analytics` `GET /api/analytics` | Read request and traffic totals for query.projectId, optionally filtered by domain. Requires a project ID; use dashboard for the workspace rollup. | `analytics:read` |
| `get_analytics_container` `GET /api/analytics/container` | Container-level metrics for a project's runtime. | `analytics:read` |
| `get_analytics_dashboard` `GET /api/analytics/dashboard` | Dashboard analytics rollup (headline metrics). | `analytics:read` |
| `get_analytics_deployments` `GET /api/analytics/deployments` | Deployment statistics (frequency, success rate, durations). | `analytics:read` |
| `get_analytics_geo` `GET /api/analytics/geo` | Visitor geography for a project: requests per country, distinct visitors, top paths. | `analytics:read` |
| `get_analytics_overview` `GET /api/analytics/overview` | Analytics overview (traffic, status codes, top paths). | `analytics:read` |
| `get_analytics_periods` `GET /api/analytics/periods` | Available analytics time periods. | `analytics:read` |
| `get_analytics_resources` `GET /api/analytics/resources` | Project resource usage: overall totals plus a per-service breakdown with live status. | `analytics:read` |
| `get_analytics_server_by_serverId` `GET /api/analytics/server/:serverId` | Read saved edge request/traffic buckets for query.domain on this server, optionally within an ISO date range. These are HTTP traffic measurements, not k3s workload CPU metrics. | `server:read` |
| `get_analytics_server_by_serverId_geo` `GET /api/analytics/server/:serverId/geo` | Read this server’s saved visitor geography for query.domain and optional query.day (YYYYMMDD). Missing observations are not zero traffic. | `server:read` |
| `get_analytics_server_by_serverId_live` `GET /api/analytics/server/:serverId/live` | Read current OpenResty counters for query.domain on this server. This is a point-in-time JSON observation, not a continuous stream. | `server:read` |
| `get_analytics_usage` `GET /api/analytics/usage` | Read current runtime resource usage for query.projectId. Unsupported runtimes return no observation; this does not imply zero usage. | `analytics:read` |
| `get_analytics_usage_history` `GET /api/analytics/usage/history` | Resource usage over time for a project (CPU/memory/network), optionally scoped to one service. | `analytics:read` |
| `post_analytics_paths_collection_by_projectId` `POST /api/analytics/paths-collection/:projectId` | Turn per-path request aggregation (Top Paths) on or off for a project. | `project:write` |
### apps
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_apps_custom_by_appId` `DELETE /api/apps/custom/:appId` | Remove a custom app from this org's catalog. | `project:write` |
| `get_apps_catalog` `GET /api/apps/catalog` | List the one-click app catalog (Convex, WordPress, mail, …). | `project:list` |
| `get_apps_catalog_by_id` `GET /api/apps/catalog/:id` | Get one app's full template (services, config, endpoints) by id. | `project:list` |
| `get_apps_catalog_by_id_host_fit` `GET /api/apps/catalog/:id/host-fit` | Preview app capacity before installing. Self-hosted minimums are advisory; Cloud checks the shared workspace allocation against the plan. Pass projectId to include an existing draft's saved resource settings. Query: deployTarget, serverId, projectId. | `project:list` |
| `get_apps_custom` `GET /api/apps/custom` | List this org's custom (user-uploaded, unverified) apps. | `project:list` |
| `get_projects_by_id_app_connection` `GET /api/projects/:id/app-connection` | Get an installed app's resolved connection details (URLs + generated keys). | `project:write` |
| `get_projects_by_id_app_settings` `GET /api/projects/:id/app-settings` | Get an installed app's curated settings schema + current values. | `project:read` |
| `patch_projects_by_id_app_settings` `PATCH /api/projects/:id/app-settings` | Update an installed app's curated settings (safe env merge). | `project:write` |
| `post_apps` `POST /api/apps` | Install an app from the catalog as a project (or return a flow route for wizard apps). Public hostnames come ONLY from `routes` — omit it and the app installs port-only (no domain is invented). | `project:write` |
| `post_apps_custom` `POST /api/apps/custom` | Add a custom app from an uploaded JSON definition (stored per-org, unverified). | `project:write` |
### audit
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_audit` `GET /api/audit` | List workspace audit events with actor, resource and source filters. Use page/perPage or cursor/limit for pagination; inspect sourceClientId to identify MCP activity. | `audit:read` |
| `get_audit_facets` `GET /api/audit/facets` | Read available audit filters, event counts, actors and client names for this workspace. | `audit:read` |
| `get_audit_settings` `GET /api/audit/settings` | Read whether audit logging is enabled, its retention period and whether the caller can manage it. | `audit:read` |
| `patch_audit_settings` `PATCH /api/audit/settings` | Change workspace audit logging and retention. Reducing retention can remove older audit history. | `audit:write` |
### backup-destinations
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_backup_destinations_by_id` `DELETE /api/backup-destinations/:id` | Remove an unused backup destination from Openship. Check usage first; dependencies can block removal. This does not erase backup objects from external storage. | `backup_destination:admin` |
| `get_backup_destinations` `GET /api/backup-destinations` | List accessible backup destinations with stored-byte/run statistics and availability. Destination secrets are masked. | `backup_destination:list` |
| `get_backup_destinations_by_id` `GET /api/backup-destinations/:id` | Read one backup destination’s configuration and statistics with credentials masked. | `backup_destination:read` |
| `get_backup_destinations_by_id_runs` `GET /api/backup-destinations/:id/runs` | List backups stored at this destination, newest first. Use query.limit and query.before to continue history. | `backup_destination:read` |
| `get_backup_destinations_by_id_usage` `GET /api/backup-destinations/:id/usage` | List projects, services and policies using this backup destination so changes or deletion can be reviewed. | `backup_destination:read` |
| `get_backup_destinations_history` `GET /api/backup-destinations/history` | Read backup history across accessible destinations, newest first. Use query.limit and the returned next cursor as query.before for further pages. | `backup_destination:list` |
| `patch_backup_destinations_by_id` `PATCH /api/backup-destinations/:id` | Update a backup destination’s settings. Omitted credentials are preserved. Destination address changes are refused while dependent backups or cluster databases require the original location. | `backup_destination:write` |
| `post_backup_destinations` `POST /api/backup-destinations` | Create an S3, SFTP or local backup destination using the existing destination contract. Preflight it before attaching a policy; creating a destination does not create a backup. | `backup_destination:write` |
| `post_backup_destinations_by_id_preflight` `POST /api/backup-destinations/:id/preflight` | Test this saved backup destination’s connectivity and required access, returning the actual checks and errors. | `backup_destination:write` |
| `post_backup_destinations_preflight` `POST /api/backup-destinations/preflight` | Test draft backup-destination connectivity and permissions without saving the destination. Returns checks and errors to resolve before policy setup. | `backup_destination:write` |
### backups
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_backup_policies_by_policyId` `DELETE /api/backup-policies/:policyId` | Disable and remove this backup policy. Existing backup history remains available according to its retention and destination state. | `backup_destination:backup_policy:write` |
| `get_backup_restores_by_restoreId` `GET /api/backup-restores/:restoreId` | Get one backup restore's status. | `backup_destination:backup_restore:read` |
| `get_backup_runs_by_runId` `GET /api/backup-runs/:runId` | Get one backup run's details/status. | `backup_destination:backup_run:read` |
| `get_projects_by_projectId_backup_policies` `GET /api/projects/:projectId/backup-policies` | List a project's backup policies (schedules/retention). | `project:write` |
| `get_projects_by_projectId_backup_runs` `GET /api/projects/:projectId/backup-runs` | List a project's backup runs (history, status). | `project:write` |
| `patch_backup_policies_by_policyId` `PATCH /api/backup-policies/:policyId` | Update a backup policy’s schedule, retention, payload or destination. Omitted fields are preserved. Changing retention can prune old unprotected backups. | `backup_destination:backup_policy:write` |
| `post_backup_policies_by_policyId_run` `POST /api/backup-policies/:policyId/run` | Start an on-demand backup under this policy. Returns runId and possibly runIds for a multi-service batch; poll each run until succeeded or failed. Accepted work is not a completed backup. | `backup_destination:backup_policy:write` |
| `post_backup_restores_by_restoreId_apply` `POST /api/backup-restores/:restoreId/apply` | Apply a prepared restore using its returned confirmationToken. In-place restoration overwrites target data and can stop the service. Poll restore status until it finishes before reporting success. | `backup_destination:backup_restore:admin` |
| `post_backup_restores_by_restoreId_cancel` `POST /api/backup-restores/:restoreId/cancel` | Request cancellation of this backup restore. Poll the restore’s returned status; accepted cancellation does not undo data already written during apply. | `backup_destination:backup_restore:admin` |
| `post_backup_runs_by_runId_protect` `POST /api/backup-runs/:runId/protect` | Protect or unprotect this backup from retention cleanup, optionally until a specified time. Read the returned retention lock and backup status. | `backup_destination:backup_run:write` |
| `post_backup_runs_by_runId_restore_prepare` `POST /api/backup-runs/:runId/restore/prepare` | Prepare restoration from this backup without applying it. Returns restoreId and confirmationToken. Poll the restore until prepared, review its target and mode, then explicitly apply the returned token. | `backup_destination:backup_run:admin` |
| `post_projects_by_projectId_backup_policies` `POST /api/projects/:projectId/backup-policies` | Create a project or service backup policy with destination, schedule and retention. For one-click volume/data backup, use the existing policy payload defaults; source code remains in its repository. Run the policy separately to test it. | `project:write` |
### billing
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_billing_actions` `GET /api/billing/actions` | Read the organization's separate prepaid Cloud Actions balance, live VM usage rates, estimated minutes and recent deposits. Amounts use the returned unitsPerDollar. Does not create a checkout or expose payment URLs. Purchases may be unavailable. | `billing:read` |
| `get_billing_checkouts` `GET /api/billing/checkouts` | List unfinished payments for the organization's managed servers, optionally scoped to one server. Saved offers and verified payment state only; no checkout is created or resumed and no payment URL is exposed. Recover payments in Billing. | `billing:read` |
| `get_billing_subscription_change` `GET /api/billing/subscription/change` | Read a provider-confirmed subscription change for the selected managed server. Queued, payment_pending and scheduled do not activate new capacity; applied confirms the new terms. Server resizing uses its existing operation status. | `billing:read` |
| `post_billing_subscription_change_preview` `POST /api/billing/subscription/change/preview` | Preview an existing managed server's plan change using the provider's prorated price and next renewal date. Saves an expiring quote without charging. Uses trusted preset or Custom resources, preserves the billing interval, and lists projects that would restart. Complete confirmation in Billing. | `billing:write` |
### billing-local
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_billing_allowances` `GET /api/billing/allowances` | List resources consuming workspace allowances, including the projects holding managed domains. | `billing:read` |
| `get_billing_credit_alerts` `GET /api/billing/credit-alerts` | Read monthly compute coverage and metered credit alerts across this organization's managed servers. Each result identifies its server; unavailable billing state remains unknown. | `billing:read` |
| `get_billing_resources` `GET /api/billing/resources` | List Cloud resources contributing to this workspace’s bill and usage. | `billing:read` |
| `get_billing_state` `GET /api/billing/state` | Read the selected Cloud server's saved plan, paid compute coverage, usage and resource limits. Older metered plans also include their credit balance. Self-hosted instances need a connected Cloud account. | `billing:read` |
| `get_billing_subscription` `GET /api/billing/subscription` | Read the selected Cloud server's saved subscription, billing mode, paid period and pending plan change. | `billing:read` |
| `get_billing_subscription_quote` `GET /api/billing/subscription/quote` | Quote a Custom Cloud server's monthly retail price for its CPU, memory in MiB, and disk in GiB. Monthly compute and storage are covered for the paid period, without a compute-credit allowance. This read does not create a server or start a purchase. Complete checkout in Billing. | `billing:read` |
| `get_billing_topup_packs` `GET /api/billing/topup-packs` | List metered Cloud credit packs and prices. Monthly servers need no compute-credit top-ups. Reading this does not buy credits. | `billing:read` |
| `get_billing_usage` `GET /api/billing/usage` | Read metered Cloud usage over the requested date range, grouped by hour or day. This is billing data, not live workload metrics. | `billing:read` |
### cloud-local
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_cloud_status` `GET /api/cloud/status` | Openship Cloud connection status for this instance. | `cloud:read` Self-hosted |
### credentials
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_credentials_by_id` `DELETE /api/credentials/:id` | Delete a stored credential. | `settings:admin` |
| `get_credentials` `GET /api/credentials` | List the organization's stored credentials. Secrets are masked. | `settings:read` |
| `get_credentials_by_id` `GET /api/credentials/:id` | Get one stored credential. The secret is masked. | `settings:read` |
| `get_credentials_providers` `GET /api/credentials/providers` | List the credential providers this instance supports, with the fields each needs. | `settings:read` |
| `patch_credentials_by_id` `PATCH /api/credentials/:id` | Rename, re-scope or rotate a stored credential. | `settings:admin` |
| `post_credentials` `POST /api/credentials` | Store a credential for a third-party provider (registry login, DNS token). | `settings:admin` |
| `post_credentials_by_id_verify` `POST /api/credentials/:id/verify` | Re-check a stored credential with its provider and record the result. | `settings:admin` |
### deployments
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_deployments_by_id` `DELETE /api/deployments/:id` | Delete an inactive deployment record and its releasable resources. The active deployment is protected; inspect status before deletion. | `deployment:admin` |
| `get_deployments` `GET /api/deployments` | List deployments in the org (optionally filter with query.projectId). | `deployment:list` |
| `get_deployments_by_id` `GET /api/deployments/:id` | Get a deployment by id — status, urls, timing, error summary. | `deployment:read` |
| `get_deployments_by_id_build` `GET /api/deployments/:id/build` | Live build/deploy status: progress, current step, per-service state, and — when the deploy is HELD waiting on a decision — `pendingPrompt` (its `actions[].id` is what the build-respond tool takes, and `expiresAt` is when the deploy gives up). Also carries `deploymentStatus` (the real persisted status, e.g. action_required), `errorCode`/`errorDetails` for a classified failure, `decisionPending` for a partial-failure release, and advisory `portCheck` results. Prefer the pending-actions tool when you want the resolution spelled out as a call. | `deployment:read` |
| `get_deployments_by_id_info` `GET /api/deployments/:id/info` | Get container info for this deployment. | `deployment:read` |
| `get_deployments_by_id_logs` `GET /api/deployments/:id/logs` | Fetch a deployment's build/runtime logs. | `deployment:read` |
| `get_deployments_by_id_pending` `GET /api/deployments/:id/pending` | What this deploy is waiting on, each item carrying the concrete call that resolves it in `resolveWith` ({method, path, body}). Poll this when a deploy appears stuck: a blocking prompt (e.g. a port already in use) shows up here with its action ids and `expiresAt`, so you never have to guess how to answer it. | `deployment:read` |
| `get_deployments_by_id_restore_plan` `GET /api/deployments/:id/restore-plan` | How a rollback to this deployment would run: instant from its retained image, or a rebuild from its commit. | `deployment:read` |
| `get_deployments_by_id_usage` `GET /api/deployments/:id/usage` | Get container CPU/memory usage for this deployment. | `deployment:read` |
| `post_deployments` `POST /api/deployments` | Git-based deploy — redeploy an already-linked project from its git source. To deploy a LOCAL FOLDER instead, use the folder-upload flow: projects folder/session → (upload) → folder/scan → projects/ensure → deployments/build/access. | `deployment:write` |
| `post_deployments_build_access` `POST /api/deployments/build/access` | Start the build and deployment for projectId. For uploaded source also pass uploadSessionId. The project's selected serverId determines where it runs; deployTarget alone does not select a managed server or transfer project records. Managed servers require buildStrategy:'server'. A desktop project imported from localPath can build on its connected Cloud server without a folder upload or transfer_to_cloud. Returns { success, deployment_id, project_id }. | `deployment:write` |
| `post_deployments_by_id_build_respond` `POST /api/deployments/:id/build/respond` | Answer a decision the deploy is HELD on, unblocking the pipeline. `action` must be one of the ids the prompt itself offers (e.g. free_port / abort for a port conflict) — read them from the pending-actions or build-status tool rather than guessing; do not invent an id. The deploy aborts on its own if nobody answers before the prompt's `expiresAt`. | `deployment:write` |
| `post_deployments_by_id_cancel` `POST /api/deployments/:id/cancel` | Cancel an in-progress deployment. | `deployment:write` |
| `post_deployments_by_id_keep` `POST /api/deployments/:id/keep` | Keep a partial-failure deployment awaiting a decision (accept the succeeded services). | `deployment:write` |
| `post_deployments_by_id_pin` `POST /api/deployments/:id/pin` | Pin or unpin a retained deployment image for rollback using body.pinned. Read restore-plan to confirm whether that image is still available. | `deployment:write` |
| `post_deployments_by_id_redeploy` `POST /api/deployments/:id/redeploy` | Re-run the latest deployment for this project. | `deployment:write` |
| `post_deployments_by_id_reject` `POST /api/deployments/:id/reject` | Reject a partial-failure deployment awaiting a decision (roll back the changed services). | `deployment:write` |
| `post_deployments_by_id_restart` `POST /api/deployments/:id/restart` | Restart the running container(s) for this deployment. | `deployment:write` |
| `post_deployments_by_id_rollback` `POST /api/deployments/:id/rollback` | Roll back to this deployment's artifact/commit. | `deployment:write` |
| `post_deployments_by_id_skip_port_check` `POST /api/deployments/:id/skip-port-check` | Dismiss the advisory 'nothing is listening on this port' warning for a target (service id, or the port as a string). Advisory-only — it never changes the deployment's status. Use when the app legitimately listens elsewhere. | `deployment:write` |
| `post_deployments_prepare` `POST /api/deployments/prepare` | Detect stack/build config for a git repo or local path before deploying. | `deployment:write` |
### dns
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_dns_credentials_by_id` `DELETE /api/dns/credentials/:id` | Disconnect a DNS provider credential. | `settings:admin` |
| `delete_dns_ingress_by_id` `DELETE /api/dns/ingress/:id` | Disconnect a public ingress binding, removing only its owned hostnames and connector. | `settings:admin` |
| `get_dns_credentials` `GET /api/dns/credentials` | List connected DNS provider credentials for the org. | `settings:read` |
| `get_dns_credentials_by_id` `GET /api/dns/credentials/:id` | Get one connected DNS provider credential. | `settings:read` |
| `get_dns_ingress` `GET /api/dns/ingress` | List public ingress connections on connected self-hosted servers. | `settings:read` |
| `get_dns_ingress_domains_by_id` `GET /api/dns/ingress/domains/:id` | Get a domain's persisted tunnel, DNS and Access setup status. | `settings:read` |
| `get_dns_providers` `GET /api/dns/providers` | List supported DNS providers and the token scopes they need. | `settings:read` |
| `post_dns_credentials` `POST /api/dns/credentials` | Connect a DNS provider credential (Cloudflare API token). | `settings:admin` |
| `post_dns_ingress` `POST /api/dns/ingress` | Connect or create a named Cloudflare Tunnel for a deployment server. Optionally install its connector and enroll new custom domains. | `settings:admin` |
| `post_dns_ingress_by_id_retry` `POST /api/dns/ingress/:id/retry` | Retry persisted public ingress setup or cleanup. | `settings:admin` |
| `post_dns_ingress_discover` `POST /api/dns/ingress/discover` | List Cloudflare accounts, named tunnels and reusable Access policies using a saved credential. | `settings:admin` |
| `post_dns_verify_zone` `POST /api/dns/verify-zone` | Check whether a connected DNS provider manages a hostname's zone. | `settings:read` |
| `put_dns_ingress_by_id` `PUT /api/dns/ingress/:id` | Change tunnel defaults for future custom domains without changing existing hostname policies. | `settings:admin` |
| `put_dns_ingress_domains_by_id` `PUT /api/dns/ingress/domains/:id` | Connect a custom domain to its server's tunnel, change its Access policy, or disconnect it. | `settings:admin` |
### domains
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_domains_by_id` `DELETE /api/domains/:id` | Delete a domain by id. | `domain:admin` |
| `get_domains` `GET /api/domains` | List domains for the project named by the projectId query parameter. | `domain:list` |
| `get_domains_by_id` `GET /api/domains/:id` | Read one domain's verify + SSL state. | `domain:read` |
| `get_domains_by_id_dns_challenge` `GET /api/domains/:id/dns/challenge` | Read the current DNS-01 HTTPS setup, including the actual ACME TXT record, deadline, logs, and result. Safe to poll or reopen after reconnecting; contains no certificate keys. | `domain:read` |
| `get_domains_by_id_dns_plan` `GET /api/domains/:id/dns/plan` | Preview what auto-configuring this domain's DNS through a connected provider would change. | `domain:read` |
| `get_domains_by_id_records` `GET /api/domains/:id/records` | Get the DNS records for a domain. | `domain:read` |
| `post_domains` `POST /api/domains` | Add a domain (free subdomain or custom). | `domain:write` |
| `post_domains_by_id_certificate` `POST /api/domains/:id/certificate` | Install an operator-supplied TLS certificate (bring-your-own / Cloudflare Origin CA). | `domain:write` Self-hosted |
| `post_domains_by_id_dns_apply` `POST /api/domains/:id/dns/apply` | Auto-configure this domain's DNS through a connected provider. | `domain:write` |
| `post_domains_by_id_dns_challenge` `POST /api/domains/:id/dns/challenge` | Start wildcard or DNS-01 HTTPS on a self-hosted deployment. Automatic uses a connected DNS provider; manual prepares a real ACME TXT record to publish. Returns the current attempt immediately; repeated starts reuse an active attempt. Read DNS challenge status, then check the manual attempt after adding its TXT value. Manual renewals need this flow again. | `domain:write` |
| `post_domains_by_id_dns_challenge_cancel` `POST /api/domains/:id/dns/challenge/cancel` | Cancel the named manual DNS certificate attempt. Preserves existing certificates and routes. An installation already in progress must finish. Remove only this attempt's TXT value from DNS afterward. | `domain:write` |
| `post_domains_by_id_dns_challenge_check` `POST /api/domains/:id/dns/challenge/check` | Check the exact TXT record for a manual DNS certificate attempt, then validate with the CA and install HTTPS on the current deployment server. Pass the attemptId returned by DNS challenge status. Read status for the result; a missing TXT keeps the same order available for retry. | `domain:write` |
| `post_domains_by_id_primary` `POST /api/domains/:id/primary` | Set this domain as the project's primary domain. | `domain:write` |
| `post_domains_by_id_renew` `POST /api/domains/:id/renew` | Renew the domain's SSL certificate. | `domain:write` |
| `post_domains_by_id_verify` `POST /api/domains/:id/verify` | Verify a domain's ownership / DNS. | `domain:write` |
| `post_domains_by_id_verify_ssl` `POST /api/domains/:id/verify-ssl` | Check/verify the domain's SSL certificate. | `domain:write` |
| `post_domains_preview` `POST /api/domains/preview` | Preview the DNS records a domain will need, before adding it. | `domain:read` |
| `post_domains_renew_all` `POST /api/domains/renew-all` | Attempt certificate renewal for eligible domains in this workspace. Inspect individual domain SSL state afterward; one domain’s failure does not prove all renewals failed. | `domain:write` |
| `post_domains_verify_pending` `POST /api/domains/verify-pending` | Recheck pending domains in this workspace and record current DNS/verification results. Read individual domain status for remaining blockers. | `domain:write` |
### github
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_github_repos_by_owner_by_repo_webhooks` `DELETE /api/github/repos/:owner/:repo/webhooks` | Delete a repository webhook identified by body.hookId. Read the repository webhook list first; removing it can stop automatic deployments. | `github:admin` |
| `get_github_connect_poll` `GET /api/github/connect/poll` | Read a GitHub connection attempt using its returned state, or self-hosted device authorization without a state. Completion means the requested connection committed; polling never grants access. | `github:read` |
| `get_github_home` `GET /api/github/home` | GitHub home: connection state, accounts, and repos in one call. | `github:read` |
| `get_github_local_status` `GET /api/github/local-status` | Read this self-hosted controller’s GitHub identity status and any connection problem. Local here means the Openship controller, not the MCP client. | `github:read` Self-hosted |
| `get_github_orgs_by_org_repos` `GET /api/github/orgs/:org/repos` | List repositories in a GitHub org/account. | `github:list` |
| `get_github_repos` `GET /api/github/repos` | List the connected account's GitHub repositories. | `github:list` |
| `get_github_repos_by_owner_by_repo` `GET /api/github/repos/:owner/:repo` | Get a GitHub repository's metadata. | `github:read` |
| `get_github_repos_by_owner_by_repo_branches` `GET /api/github/repos/:owner/:repo/branches` | List a repository's branches. | `github:list` |
| `get_github_repos_by_owner_by_repo_detect` `GET /api/github/repos/:owner/:repo/detect` | Detect a repo's build config without reading its files — framework, package manager, install/build/start commands, output directory, port, and compose services. Use this to configure a deploy; it needs no content access. | `github:read` |
| `get_github_repos_by_owner_by_repo_file` `GET /api/github/repos/:owner/:repo/file` | Read a single file's contents from a repo. Requires repo content access; prefer /detect for build config. | `github:read` |
| `get_github_repos_by_owner_by_repo_files` `GET /api/github/repos/:owner/:repo/files` | List files and directories at query.path and optional query.branch. Requires repository content access; results remain confined to the granted paths. | `github:list` |
| `get_github_repos_by_owner_by_repo_webhooks` `GET /api/github/repos/:owner/:repo/webhooks` | List a repo's webhooks (to check push auto-deploy wiring). | `github:list` |
| `get_github_sources` `GET /api/github/sources` | List configured self-hosted GitHub App sources and their connection status without private keys. Requires workspace-owner access. | `github:admin` Self-hosted |
| `get_github_status` `GET /api/github/status` | GitHub connection status for the org. | `github:read` |
| `post_github_connect` `POST /api/github/connect` | Start GitHub connection and return a redirect, installation selection, device code, or token instructions. Let the user complete approval in Openship or GitHub. For redirects with completion=attempt, poll using the returned state; existing connection status does not confirm a new installation. | `github:write` |
| `post_github_repos_by_owner_by_repo_webhooks` `POST /api/github/repos/:owner/:repo/webhooks` | Register Openship’s deployment webhook for this repository. Prefer the project auto-deploy tool when configuring an existing project; it chooses the correct delivery strategy. | `github:write` |
| `post_github_sources_by_id_verify` `POST /api/github/sources/:id/verify` | Verify a configured self-hosted GitHub App source and refresh its health status. Does not create an installation or return its credentials. | `github:admin` Self-hosted |
### issues
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_issues_history` `DELETE /api/issues/history` | Clear resolved monitoring incident history in the caller's organization. Requires an organization owner/admin with unrestricted access. Preserves open incidents, other organizations and incidents resolving after the server-side cutoff. Does not clear audit logs, notifications or workloads. | `project:admin` Self-hosted |
| `get_issues` `GET /api/issues` | THE place to answer "what is broken right now?" across the whole installation — start here before per-project tools. One org-wide feed that merges every check Openship already runs: container health incidents (unhealthy / crash_loop / down, plus a server-level `server_unreachable` row when a whole box is offline), managed edge/mail container state, deploy blockers and held prompts, partial-release decisions, unsynced routing, port advisories, unverified domains, certificate errors, and available updates. Each item carries `severity` (`outage` = not being served right now, `action_required`, `advisory`), a `target` with a dashboard href, and `resolveWith` — concrete {method, path} calls that fix it, callable as-is. Items whose fix is a managed container carry `infraFix` instead (a UI flow, not an API call). `?status=resolved` returns incident HISTORY (the only source with a lifecycle; up to 30 days), so a resolved-tab absence never means "nothing else ever broke". Infrastructure rows require server read access and are absent in cloud mode. | `project:list` |
| `get_issues_health` `GET /api/issues/health` | Latest health-watch snapshot for every expected workload in the organization. Cached only: this read performs no Docker polling. Includes healthy, unhealthy, crash-looping, down and unknown states plus watcher enabled status. | `project:list` |
| `get_issues_rescan_status` `GET /api/issues/rescan/status` | Read the current or most recent issue-rescan session, including stage status, errors and completion. Start once with the rescan tool, then poll this tool instead of launching repeated scans. | `job:read` Self-hosted |
| `get_issues_summary` `GET /api/issues/summary` | Counts only from the same feed as GET /issues: {outage, actionRequired, advisory, total}. Use for a quick health verdict; read GET /issues for the rows and their fixes. | `project:list` |
| `post_issues_health_scan` `POST /api/issues/health/scan` | Check the current container state of every deployed workload in the caller's organization, including managed Cloud servers. Reuses the health watch scanner and refreshes only its in-memory snapshots: it does not enable a job, update incident history, send alerts, or start Docker event subscriptions. | `project:list` |
| `post_issues_rescan` `POST /api/issues/rescan` | Run the checkers behind GET /issues immediately instead of waiting for their schedules, then re-read GET /issues. Send {healthOnly:true} to recheck container/server health without running component updates or domain reconciliation. Returns a scan session with stages; GET /issues/rescan/status follows its completion. These are the existing scheduled jobs, recorded in job history as manual runs. Self-hosted only and requires an instance administrator. | `job:write` Self-hosted |
### jobs
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_jobs_by_key` `DELETE /api/jobs/:key` | Delete a custom job (system jobs can't be deleted). | `job:write` |
| `get_jobs` `GET /api/jobs` | List your authorized command jobs with schedule, next run, and recent history. Self-hosted installations also show their built-in maintenance jobs; Cloud keeps platform maintenance private. | `job:read` |
| `get_jobs_backup_schedules` `GET /api/jobs/backup-schedules` | List scheduled backup policies (read-only), surfaced alongside jobs. | `job:read` |
| `get_jobs_by_key` `GET /api/jobs/:key` | Get one job's config, schedule, and recent runs. | `job:read` |
| `get_jobs_by_key_runs` `GET /api/jobs/:key/runs` | List a job's run history. | `job:read` |
| `get_jobs_runs_by_runId` `GET /api/jobs/runs/:runId` | Get one job run incl. captured output. | `job:read` |
| `get_jobs_trigger_events` `GET /api/jobs/trigger-events` | List the events a job can be triggered on. | `job:read` |
| `patch_jobs_by_key` `PATCH /api/jobs/:key` | Update a job's schedule/enabled (any job) or full config (custom jobs). | `job:write` |
| `post_jobs` `POST /api/jobs` | Create a command job on one or more servers you administer, using cron, one-time or manual scheduling, retries, env, secrets, dependencies, triggers and notifications. Cloud jobs reuse a subscribed managed server selected by serverId; they share its resources and metered allowance. | `job:write` |
| `post_jobs_by_key_run` `POST /api/jobs/:key/run` | Run a job immediately (custom jobs stream live; returns a runId). | `job:write` |
### mail
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_mail_admin_by_serverId_aliases_by_id` `DELETE /api/mail/admin/:serverId/aliases/:id` | Delete a mail alias or forward. Messages addressed through it will no longer use that mapping. | `mail_server:admin` Self-hosted |
| `delete_mail_admin_by_serverId_domains_by_domain` `DELETE /api/mail/admin/:serverId/domains/:domain` | Delete a mail domain. Inspect dependents first; query.cascade=true also removes dependent mailboxes and aliases. | `mail_server:admin` Self-hosted |
| `delete_mail_admin_by_serverId_inbound_rules_by_ruleId` `DELETE /api/mail/admin/:serverId/inbound-rules/:ruleId` | Delete an inbound-mail notification rule and release capture that no remaining rule needs. | `mail_server:write` Self-hosted |
| `delete_mail_admin_by_serverId_mailboxes_by_email` `DELETE /api/mail/admin/:serverId/mailboxes/:email` | Remove a mailbox account. query.hard=true also deletes its stored mail; read its details before requesting permanent removal. | `mail_server:admin` Self-hosted |
| `delete_mail_servers_by_serverId` `DELETE /api/mail/servers/:serverId` | Forget Openship’s mail-server registration without uninstalling daemons or deleting mail data. Scan and adopt can restore the registration. | `mail_server:admin` Self-hosted |
| `get_mail_admin_by_serverId_aliases` `GET /api/mail/admin/:serverId/aliases` | List mail aliases and forwards, optionally filtered by query.domain. | `mail_server:list` Self-hosted |
| `get_mail_admin_by_serverId_backup_policy` `GET /api/mail/admin/:serverId/backup-policy` | Read this mail server’s saved backup policy, or null when no policy exists. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_backup_runs` `GET /api/mail/admin/:serverId/backup-runs` | Read this mail server’s recent backup runs. Follow run IDs with the general backup status and restore tools. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_certificate` `GET /api/mail/admin/:serverId/certificate` | Read the mail certificate, SMTP/IMAP TLS checks and automatic renewal settings. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_components_by_key_logs` `GET /api/mail/admin/:serverId/components/:key/logs` | Read recent logs for one managed mail component, with optional query.lines. Logs can contain recipient addresses; redact before sharing. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_dns_scan` `GET /api/mail/admin/:serverId/dns-scan` | Check current mail DNS records, optionally for query.domain. Does not apply changes. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_domains` `GET /api/mail/admin/:serverId/domains` | List mail domains configured on this mail server. | `mail_server:list` Self-hosted |
| `get_mail_admin_by_serverId_domains_by_domain` `GET /api/mail/admin/:serverId/domains/:domain` | Read a mail domain’s configuration and status. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_domains_by_domain_dependents` `GET /api/mail/admin/:serverId/domains/:domain/dependents` | Inspect mailboxes and aliases affected by deleting this mail domain. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_domains_by_domain_dns` `GET /api/mail/admin/:serverId/domains/:domain/dns` | Read required DNS records and the current DNS acknowledgment state for this mail domain. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_domains_by_domain_dns_plan` `GET /api/mail/admin/:serverId/domains/:domain/dns/plan` | Preview DNS changes for this mail domain through a connected DNS provider. Does not apply records. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_domains_dns_pending` `GET /api/mail/admin/:serverId/domains-dns/pending` | List mail domains still requiring DNS configuration or acknowledgment. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_inbound_rules` `GET /api/mail/admin/:serverId/inbound-rules` | List inbound-mail notification rules and their enabled or paused state. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_mailboxes` `GET /api/mail/admin/:serverId/mailboxes` | List mailboxes, optionally filtered by query.domain. Passwords are not returned. | `mail_server:list` Self-hosted |
| `get_mail_admin_by_serverId_mailboxes_by_email` `GET /api/mail/admin/:serverId/mailboxes/:email` | Read a mailbox’s profile, quota and enabled state without its password. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_relay` `GET /api/mail/admin/:serverId/relay` | Read outbound relay configuration with its password hidden. Relay credentials are managed in the mail server’s settings. | `mail_server:read` Self-hosted |
| `get_mail_admin_by_serverId_stats` `GET /api/mail/admin/:serverId/stats` | Read mail-server domain, mailbox, alias and storage totals. | `mail_server:read` Self-hosted |
| `get_mail_health_by_serverId` `GET /api/mail/health/:serverId` | Check live mail components, delivery and network reachability. Set query.refreshReachability to bypass the reachability cache. | `mail_server:read` Self-hosted |
| `get_mail_servers` `GET /api/mail/servers` | List mail servers managed by this workspace, their installation state and linked webmail projects. | `mail_server:list` Self-hosted |
| `get_mail_status` `GET /api/mail/status` | Read saved setup progress for query.serverId. A missing state after an SSH failure is not proof that mail is uninstalled; check the mail health tool for live reachability. | `mail_server:read` Self-hosted |
| `get_mail_steps` `GET /api/mail/steps` | Read the ordered mail installation steps. Installing a new mail stack uses the dashboard’s streaming setup wizard. | `mail_server:read` Self-hosted |
| `get_mail_webmail_targets` `GET /api/mail/webmail/targets` | List permitted deployment targets for the mail server named by query.serverId. | `mail_server:read` Self-hosted |
| `patch_mail_admin_by_serverId_aliases_by_id` `PATCH /api/mail/admin/:serverId/aliases/:id` | Enable or disable this mail alias using body.active. | `mail_server:write` Self-hosted |
| `patch_mail_admin_by_serverId_certificate` `PATCH /api/mail/admin/:serverId/certificate` | Enable or disable automatic mail certificate renewal. Monitoring continues when renewal is disabled. | `mail_server:admin` Self-hosted |
| `patch_mail_admin_by_serverId_domains_by_domain` `PATCH /api/mail/admin/:serverId/domains/:domain` | Update a mail domain’s description, capacity limits, default quota or enabled state. | `mail_server:write` Self-hosted |
| `patch_mail_admin_by_serverId_inbound_rules_by_ruleId` `PATCH /api/mail/admin/:serverId/inbound-rules/:ruleId` | Update an inbound-mail notification rule and reconcile capture on affected domains. pausedReason=null clears the saved pause reason. | `mail_server:write` Self-hosted |
| `patch_mail_admin_by_serverId_mailboxes_by_email` `PATCH /api/mail/admin/:serverId/mailboxes/:email` | Update a mailbox’s name, quota, password or enabled state. Omit password to preserve it. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_aliases` `POST /api/mail/admin/:serverId/aliases` | Create a mail alias, forward or catch-all and its destination. A catch-all applies to unmatched recipients in the domain. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_backup_policy` `POST /api/mail/admin/:serverId/backup-policy` | Create or update the mail-server backup policy. Set messageData=true to include stored messages; keys default to included. Omitted retention preserves an existing policy or uses creation defaults; null removes that retention limit. Use the general backup policy run tool for an immediate backup. | `mail_server:admin` Self-hosted |
| `post_mail_admin_by_serverId_certificate_check` `POST /api/mail/admin/:serverId/certificate/check` | Recheck the mail certificate on disk and served by SMTP/IMAP. Does not issue a certificate or send email. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_certificate_renew` `POST /api/mail/admin/:serverId/certificate/renew` | Renew a due mail certificate through the Openship edge and reload Postfix/Dovecot. A still-valid certificate is reused and its service configuration repaired. | `mail_server:admin` Self-hosted |
| `post_mail_admin_by_serverId_components_by_key_by_action` `POST /api/mail/admin/:serverId/components/:key/:action` | Run a supported action on a managed mail component. Read health for component keys and supported actions; inspect health again to confirm recovery. | `mail_server:admin` Self-hosted |
| `post_mail_admin_by_serverId_components_restart_all` `POST /api/mail/admin/:serverId/components/restart-all` | Restart managed mail components on this server. Mail delivery can be briefly interrupted; inspect health afterward. | `mail_server:admin` Self-hosted |
| `post_mail_admin_by_serverId_domains` `POST /api/mail/admin/:serverId/domains` | Create a mail domain with mailbox, alias and quota limits. Then inspect its DNS plan and apply or configure the required records. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_domains_by_domain_dns_acknowledge` `POST /api/mail/admin/:serverId/domains/:domain/dns/acknowledge` | Recheck and acknowledge a mail domain’s DNS configuration. Only use after the required records have been configured. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_domains_by_domain_dns_apply` `POST /api/mail/admin/:serverId/domains/:domain/dns/apply` | Apply this mail domain’s required DNS records through a connected provider. Inspect the DNS plan first. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_inbound_rules` `POST /api/mail/admin/:serverId/inbound-rules` | Create an inbound-mail notification rule for a mailbox, domain or all domains, targeting existing notification channels. Inspect its resulting enabled/paused state if engine capture cannot be armed. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_inbound_rules_test` `POST /api/mail/admin/:serverId/inbound-rules/test` | Preview matches for this server’s inbound notification rules without sending notifications or deleting captured messages. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_mailboxes` `POST /api/mail/admin/:serverId/mailboxes` | Create a mailbox with a supplied password and optional quota. This changes the mail server’s account database. | `mail_server:write` Self-hosted |
| `post_mail_admin_by_serverId_test_email` `POST /api/mail/admin/:serverId/test-email` | Send a mail-delivery test to body.to, optionally from body.fromDomain. This sends a real email; use the recipient requested by the user. | `mail_server:write` Self-hosted |
| `post_mail_adopt` `POST /api/mail/adopt` | Register an existing Openship mail installation found by scan. Restores control-plane ownership without reinstalling the stack. | `mail_server:write` Self-hosted |
| `post_mail_scan` `POST /api/mail/scan` | Inspect an existing mail installation on body.serverId without reinstalling it. Returns adoptable state; use adopt to register an existing stack. | `mail_server:write` Self-hosted |
| `post_mail_webmail_deploy_project` `POST /api/mail/webmail/deploy-project` | Deploy webmail for an existing mail server to a permitted target. Both self and cloud targets need target.serverId; use the local ID of a connected managed server for Cloud. Returns projectId and deploymentId for normal deployment monitoring. reconnectProjectId explicitly reuses an unlinked webmail on its existing mail server and hostname. replaceLegacy=true explicitly replaces an older unmanaged webmail installation. | `mail_server:write` Self-hosted |
### migration
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_migration_migrations_by_id` `DELETE /api/migration/migrations/:id` | Delete a terminal migration’s history record. Does not delete the migrated project or its data; active runs must first finish or be cancelled. | `server:write` |
| `delete_migration_sources_by_serverId` `DELETE /api/migration/sources/:serverId` | Remove a migration-only connection and its stored credentials after its runs finish. Does not delete the external server, source containers, data or imported projects. | `server:write` |
| `get_migration_active` `GET /api/migration/active` | Find an existing active migration involving query.serverId before starting or reattaching to work. Returns its ID and cutover state; source environment values remain masked. | `server:read` |
| `get_migration_migrations_by_id` `GET /api/migration/migrations/:id` | Read migration state, saved progress, logs and pendingPrompt. When awaiting_cutover, review target health/routing before confirmation. A partial run can be resumed; polling never starts another migration. | `server:read` |
| `get_migration_runs` `GET /api/migration/runs` | List up to 50 recent migration summaries for query.serverId or query.projectId. Read a specific run for logs, prompts and cutover details. | `server:read` |
| `get_migration_sources` `GET /api/migration/sources` | List reusable migration-only SSH sources in the active organization. These connections cannot host Openship deployments or run general server commands. | `server:read` |
| `post_migration_adopt` `POST /api/migration/adopt` | Register selected discovered Docker services as an Openship project while preserving running containers and volumes. Rediscovers values on the server; do not send masked secrets as replacements. Deployment and cutover are separate. | `server:write` Self-hosted |
| `post_migration_migrate` `POST /api/migration/migrate` | Start adoption, data transfer, deployment and routing verification for the reviewed Docker services. Returns migrationId and confirmationToken; poll the run and answer its offered pending prompts. Leave killOriginals false to review explicit cutover. True authorizes automatic retirement of original containers after verification. | `server:write` |
| `post_migration_migrations_by_id_cancel` `POST /api/migration/migrations/:id/cancel` | Cancel an in-flight migration and request rollback of target changes. Poll until rollback finishes. Not available after awaiting_cutover or terminal completion; use explicit cutover at that point. | `server:write` |
| `post_migration_migrations_by_id_cleanup_target` `POST /api/migration/migrations/:id/cleanup-target` | Remove target volumes copied by a failed migration, so a later retry can start cleanly. Source data is retained; succeeded migrations are refused. Review the failed run before cleanup. | `server:write` |
| `post_migration_migrations_by_id_cutover` `POST /api/migration/migrations/:id/cutover` | Confirm migration cutover using the returned confirmationToken. kill:true destroys original containers. False retains them: external cross-server imports restart previously running sources; existing project moves and same-server imports leave them stopped. Source volumes remain. Failed destructive cutover can only resume that same choice. | `server:write` |
| `post_migration_migrations_by_id_respond` `POST /api/migration/migrations/:id/respond` | Answer the migration’s current pendingPrompt with its promptId and an offered action ID. Use the run’s actual options and expiry; do not invent takeover decisions. | `server:write` |
| `post_migration_migrations_by_id_resume` `POST /api/migration/migrations/:id/resume` | Resume a partial migration’s remaining paths, optionally with reviewed source-path overrides or skips. Skipping excludes data from the move. Poll the run through verification and cutover. | `server:write` |
| `post_migration_preview` `POST /api/migration/preview` | Preview a Docker migration’s images, volumes, destination conflicts and downtime warnings without moving workloads. Use the same server and service selection for the subsequent migrate call. | `server:write` |
| `post_migration_project` `POST /api/migration/project` | Move or copy an existing Docker project to a registered server through the migration pipeline. Requires access to the project and both servers. Returns migrationId; poll and explicitly confirm cutover. Does not move k3s projects or convert database replication. | `server:write` |
| `post_migration_reimport` `POST /api/migration/reimport` | Re-register an orphaned Openship project found on this server, preserving its scanned project ID and configuration. Use scan to identify the project; this is recovery of existing workloads. | `server:write` Self-hosted |
| `post_migration_repo_compose` `POST /api/migration/repo-compose` | Read derived Compose service configuration from an accessible GitHub repository for migration mapping. Environment values are masked; absence of Compose returns an empty services list. | `server:read` |
| `post_migration_scan` `POST /api/migration/scan` | Inspect Docker workloads on body.serverId, returning groups, container IDs, volumes and detected routes with secrets masked. Does not adopt or stop workloads. Use container IDs when selecting services shared across Compose projects. | `server:write` |
| `post_migration_sources` `POST /api/migration/sources` | Connect a public SSH server for migration only. Verifies the connection, pins its host key and encrypts credentials. Scan it, preview a move to a managed server, then start the existing migration flow. | `server:write` |
| `post_migration_sources_test` `POST /api/migration/sources/test` | Verify a public SSH migration source using a password or uploaded private key. Returns its host fingerprint; does not save credentials or modify workloads. | `server:write` |
### notifications
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_notifications_channels_by_id` `DELETE /api/notifications/channels/:id` | Delete a notification channel. | `notifications:write` |
| `delete_notifications_subscriptions_by_id` `DELETE /api/notifications/subscriptions/:id` | Delete a notification subscription. | `notifications:write` |
| `get_notifications_categories` `GET /api/notifications/categories` | List notification categories (the registry of event types). | `notifications:read` |
| `get_notifications_channels` `GET /api/notifications/channels` | List the caller's notification channels (email, webhook, etc.). | `notifications:read` |
| `get_notifications_defaults` `GET /api/notifications/defaults` | List org default notification settings. | `notifications:read` |
| `get_notifications_deliveries` `GET /api/notifications/deliveries` | List notification deliveries (the in-app alert feed). | `notifications:read` |
| `get_notifications_deliveries_unseen_count` `GET /api/notifications/deliveries/unseen-count` | Count unseen notifications. | `notifications:read` |
| `get_notifications_subscriptions` `GET /api/notifications/subscriptions` | List the caller's notification subscriptions. | `notifications:read` |
| `patch_notifications_channels_by_id` `PATCH /api/notifications/channels/:id` | Update a notification channel. | `notifications:write` |
| `post_notifications_channels` `POST /api/notifications/channels` | Create a notification channel. | `notifications:write` |
| `post_notifications_channels_by_id_test` `POST /api/notifications/channels/:id/test` | Send a test delivery to a channel; marks it verified on success. | `notifications:write` |
| `post_notifications_deliveries_by_id_seen` `POST /api/notifications/deliveries/:id/seen` | Mark a notification delivery as seen. | `notifications:write` |
| `put_notifications_defaults` `PUT /api/notifications/defaults` | Set a workspace default notification destination and enabled state for an event category. Existing subscriptions and delivery policy still apply. | `notifications:admin` |
| `put_notifications_subscriptions` `PUT /api/notifications/subscriptions` | Create or update a notification subscription. | `notifications:write` |
### permissions
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_permissions_grants` `GET /api/permissions/grants` | Read workspace resource grants for query.userId. Requires permission to inspect that member; does not widen this credential’s access. | `permissions:read` |
| `get_permissions_invitations` `GET /api/permissions/invitations` | List pending workspace invitations and their proposed grants. Accepting or sending invitations remains an account-owner workflow. | `permissions:read` |
| `get_permissions_members` `GET /api/permissions/members` | List workspace members and their current roles. | `permissions:read` |
| `get_permissions_org_meta` `GET /api/permissions/org-meta` | Read this workspace’s identity, team status and member count. | `permissions:read` |
| `get_permissions_resources` `GET /api/permissions/resources` | List grantable resources of query.type visible to this credential. This reads resources; it does not grant access. | `permissions:read` |
| `get_permissions_workspaces` `GET /api/permissions/workspaces` | List the Openship workspaces (organizations/workgroups) available to this credential, including empty workspaces. Returns each name, organizationId, slug and role, plus currentOrganizationId, boundOrganizationId, canSwitchOrganization and readOnly. Call before creating an app or Compose project; pass the chosen organizationId as a top-level tool argument on every call. Bound credentials can only list and target their own workspace. | `permissions:read` |
### projects
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_projects_by_id` `DELETE /api/projects/:id` | Delete this project and its owned deployment resources. Inspect deletion-preview first. Volumes are preserved unless query.wipeVolumes is explicitly true; force-orphan and record-only options can leave remote resources behind. | `project:admin` |
| `delete_projects_by_id_cluster_databases` `DELETE /api/projects/:id/cluster/databases` | Stop a managed database and retain its volumes when deleteData:false, or permanently delete owned database data when true. Requires its exact name and latest expectedSequence. Retained data continues to block project/runtime cleanup; poll inspection until the operation finishes. | `project:write` Self-hosted |
| `delete_projects_by_id_cluster_volumes` `DELETE /api/projects/:id/cluster/volumes` | Permanently delete an unmounted project volume with its resourceVersion, matching confirmName and deleteData:true. Disconnect and redeploy first. External backups are preserved. | `project:write` Self-hosted |
| `delete_projects_by_id_cluster_volumes_backups` `DELETE /api/projects/:id/cluster/volumes/backups` | Permanently delete a project file backup archive. Confirm the exact backupName using confirmName; the source volume is preserved. | `project:write` Self-hosted |
| `delete_projects_by_id_connections_by_linkId` `DELETE /api/projects/:id/connections/:linkId` | Remove a database/app connection and its injected env var. | `project:admin` |
| `delete_projects_by_id_incoming_webhooks_by_hookId` `DELETE /api/projects/:id/incoming-webhooks/:hookId` | Delete an incoming webhook. | `project:write` |
| `delete_projects_by_id_route_rules_by_ruleId` `DELETE /api/projects/:id/route-rules/:ruleId` | Delete this project’s edge traffic rule and synchronize routing. Removing a restriction changes which traffic is allowed. | `project:write` Self-hosted |
| `delete_projects_by_id_storage` `DELETE /api/projects/:id/storage` | Remove the object-storage binding and the env vars it injected. | `project:admin` |
| `get_projects` `GET /api/projects` | List projects in the org. | `project:list` |
| `get_projects_by_id` `GET /api/projects/:id` | Get a project by id — config, source, routes, status. | `project:read` |
| `get_projects_by_id_branches` `GET /api/projects/:id/branches` | List the linked repository's branches. | `project:read` |
| `get_projects_by_id_cluster` `GET /api/projects/:id/cluster` | Read the project’s selected cluster, desired replicas, activeDeploymentId, updatedAt and observed pod readiness. Use those exact IDs/timestamps as scaling preconditions. error means runtime observation failed; saved desired replicas are not proof of running replicas. | `project:read` Self-hosted |
| `get_projects_by_id_cluster_databases` `GET /api/projects/:id/cluster/databases` | List this project’s managed cluster databases with saved lifecycle progress and connections. Database replication has a separate lifecycle from stateless application replicas. | `project:read` Self-hosted |
| `get_projects_by_id_cluster_databases_imports` `GET /api/projects/:id/cluster/databases/imports` | List completed PostgreSQL and Redis backups eligible for import into a new database on a server cluster. Requires source-project administrator access; returns reviewed backup identities, never archive paths or credentials. | `project:read` Self-hosted |
| `get_projects_by_id_cluster_volumes` `GET /api/projects/:id/cluster/volumes` | List the project's shared volumes, current attachment health and backups. Observe this status after a mutation. | `project:read` Self-hosted |
| `get_projects_by_id_cluster_volumes_backups` `GET /api/projects/:id/cluster/volumes/backups` | List project file backups, including archives whose source volume was deleted. Restore a completed archive into a new volume. | `project:read` Self-hosted |
| `get_projects_by_id_commit_status` `GET /api/projects/:id/commit-status` | Compare the deployed commit against the remote HEAD. | `project:read` |
| `get_projects_by_id_connections` `GET /api/projects/:id/connections` | List the database/app connections wired into this project. | `project:read` |
| `get_projects_by_id_connections_candidates` `GET /api/projects/:id/connections/candidates` | List projects and apps available for a service connection, filtered by access. | `project:write` |
| `get_projects_by_id_connections_consumers` `GET /api/projects/:id/connections/consumers` | List the projects that consume THIS app's connection (a shared database has many). | `project:read` |
| `get_projects_by_id_deletion_preview` `GET /api/projects/:id/deletion-preview` | Preview what deleting this project would remove (read-only). | `project:read` |
| `get_projects_by_id_deployments` `GET /api/projects/:id/deployments` | List a project's deployments (history, statuses). | `project:deployment:list` |
| `get_projects_by_id_edge_config` `GET /api/projects/:id/edge-config` | Compare saved project routes with the configuration currently served by the self-hosted edge. Use this to investigate routing drift before retrying. | `project:read` Self-hosted |
| `get_projects_by_id_env` `GET /api/projects/:id/env` | List a project's environment variables (secret values masked). | `project:read` |
| `get_projects_by_id_environments` `GET /api/projects/:id/environments` | List a project's environments (production / previews). | `project:read` |
| `get_projects_by_id_git` `GET /api/projects/:id/git` | Get the project's linked git repository info. | `project:read` |
| `get_projects_by_id_incidents` `GET /api/projects/:id/incidents` | Container runtime health for this project: OPEN incidents (a workload the health watch found `unhealthy`, `crash_loop`, or `down`, each with its reason, exit code, restart count, OOM flag and a log excerpt) plus recently-resolved ones. Two fields decide whether an empty list means anything, so always read them: `watching` is false when health monitoring is turned OFF — with it off, the absence of incidents is NOT evidence of health; `serverUnreachable` is non-null when the box itself is unreachable, in which case this project's rows are frozen and stale (nothing is being observed). Read this whenever a project looks unhealthy, or a deploy that reported success still isn't serving — it reports the RUNTIME state and complements the pending-actions tool (which covers deploy/domain/routing items that each carry a concrete fix). Incidents auto-resolve when the workload recovers; the usual move for an open one is to redeploy or inspect its `logExcerpt`. Self-hosted only. | `project:read` Self-hosted |
| `get_projects_by_id_incoming_webhooks` `GET /api/projects/:id/incoming-webhooks` | List a project's incoming webhooks (dynamic trigger URLs). | `project:read` |
| `get_projects_by_id_incoming_webhooks_by_hookId_deliveries` `GET /api/projects/:id/incoming-webhooks/:hookId/deliveries` | List one incoming webhook's recent deliveries (paginated). | `project:read` |
| `get_projects_by_id_info` `GET /api/projects/:id/info` | Get a project's detailed info (runtime, build, source). | `project:read` |
| `get_projects_by_id_logs` `GET /api/projects/:id/logs` | Fetch the project's runtime logs (non-streaming). | `project:read` |
| `get_projects_by_id_pending_actions` `GET /api/projects/:id/pending-actions` | What is waiting on a human for this project, and how to resolve each item. Covers a deploy blocked on a named cause (e.g. a port already in use), a deploy HELD right now on a decision (answer it with the build-respond tool — the exact action id and body are in the item's resolveWith, and `expiresAt` is when the deploy gives up), a partial-failure release awaiting keep/reject, unsynced routing, unverified domains, and failed/expired certificates. Each item carries `resolveWith`, an array of concrete {method, path, body} calls — use those rather than guessing. Call this after starting a deploy that seems stuck, and whenever a project reads as Action Required. This covers deploy/domain/routing items only — for container-runtime health (crash loops, unhealthy or down containers) read the project's incidents instead. Scoped to ONE project: to ask what is broken across the whole installation (these items for every project, plus runtime incidents, unreachable servers and edge/mail state, ranked by severity), read the issues feed instead. | `project:read` |
| `get_projects_by_id_previews` `GET /api/projects/:id/previews` | List managed pull request previews, URLs, lifecycle state, and configuration. | `project:read` |
| `get_projects_by_id_resources` `GET /api/projects/:id/resources` | Get the project's CPU/RAM/disk resource config. | `project:read` |
| `get_projects_by_id_roles` `GET /api/projects/:id/roles` | Read the active deployment's runtime roles, replicas, live status, and restart counts. | `project:read` |
| `get_projects_by_id_roles_configuration` `GET /api/projects/:id/roles/configuration` | Read editable runtime role settings from the active Docker release. | `project:read` |
| `get_projects_by_id_rollback_capacity` `GET /api/projects/:id/rollback-capacity` | Get the rollback retention window in force (explicit or disk-sized), the measured per-release size, and the deploy host's free disk. | `project:read` |
| `get_projects_by_id_route_rules` `GET /api/projects/:id/route-rules` | List project edge rules for rate limits, access restrictions and traffic filtering. | `project:read` Self-hosted |
| `get_projects_by_id_routing_edge_status` `GET /api/projects/:id/routing/edge-status` | Check whether the project's server edge (OpenResty on 80/443) is already set up. | `project:read` |
| `get_projects_by_id_server_logs_recent` `GET /api/projects/:id/server-logs/recent` | Fetch recent HTTP request logs for the project. | `project:read` |
| `get_projects_by_id_storage` `GET /api/projects/:id/storage` | Read this project's object-storage binding (S3 bucket wired into its filesystem config) and what could be bound. | `project:read` |
| `get_projects_by_id_webhook_deliveries` `GET /api/projects/:id/webhook-deliveries` | List a project's webhook delivery feed — GitHub pushes + custom hooks (paginated). | `project:read` |
| `get_projects_home` `GET /api/projects/home` | Read the combined local and connected-Cloud project overview, including project groups and hosting location. Individual operations still enforce each project’s scope. | `project:list` |
| `get_projects_local` `GET /api/projects/local` | List projects registered from directories on this Openship controller. These paths are not on the MCP client machine. | `project:list` Self-hosted |
| `patch_projects_by_id` `PATCH /api/projects/:id` | Update a project's configuration (build config, source, options). | `project:write` |
| `patch_projects_by_id_cluster` `PATCH /api/projects/:id/cluster` | Select a ready k3s compute cluster for one stateless application or worker, or clear its selection with clusterId:null. Requires expectedUpdatedAt from the latest cluster read and stateless:true. Source builds need a reachable imageRepository. Saves the target only; deploy separately. Compose projects, persistent app mounts and live worker changes are unsupported. | `project:write` Self-hosted |
| `patch_projects_by_id_cluster_databases` `PATCH /api/projects/:id/cluster/databases` | Update database resources and replica count using its latest expectedSequence. Redis partition changes require a previously configured backup destination and confirmRedisRebalance:true; a backup is verified before moving data. Major PostgreSQL upgrades use a separate copy, not an in-place edit. Inspect progress for completion. | `project:write` Self-hosted |
| `patch_projects_by_id_cluster_volumes` `PATCH /api/projects/:id/cluster/volumes` | Grow a project shared volume using its current resourceVersion. Volumes cannot shrink; inspect status until expansion finishes. | `project:write` Self-hosted |
| `patch_projects_by_id_cluster_volumes_backups` `PATCH /api/projects/:id/cluster/volumes/backups` | Schedule hourly or daily file backups with a retained archive count, or select manual to stop the schedule. The native storage controller runs accepted schedules independently. | `project:write` Self-hosted |
| `patch_projects_by_id_env` `PATCH /api/projects/:id/env` | Merge env var changes (upserts + deletes); untouched vars are preserved. | `project:write` |
| `patch_projects_by_id_incoming_webhooks_by_hookId` `PATCH /api/projects/:id/incoming-webhooks/:hookId` | Update an incoming webhook (name/enabled/action/auth). | `project:write` |
| `patch_projects_by_id_resources` `PATCH /api/projects/:id/resources` | Update the project's CPU/RAM/disk, sleep mode, or port. | `project:write` |
| `patch_projects_by_id_route_rules_by_ruleId` `PATCH /api/projects/:id/route-rules/:ruleId` | Update this project’s edge traffic rule. Supply the complete replacement rule spec when changing it; omitted top-level fields are preserved. | `project:write` Self-hosted |
| `post_projects` `POST /api/projects` | Create a project from a git or local source (build config baked into the project). For a folder-upload deploy use projects/ensure instead (it accepts the folder/scan config and gitProvider:'upload'). | `project:write` |
| `post_projects_by_id_auto_deploy` `POST /api/projects/:id/auto-deploy` | Enable/disable auto-deploy on push. | `project:write` |
| `post_projects_by_id_branch` `POST /api/projects/:id/branch` | Set the project's deploy branch. | `project:write` |
| `post_projects_by_id_build_cache_migration` `POST /api/projects/:id/build-cache/migration` | Inspect manual build cache mounts and migrate selected mounts after a successful managed-cache deployment. Cached volume data is retained. | `project:write` |
| `post_projects_by_id_clear_build` `POST /api/projects/:id/clear-build` | Clear all unused Docker build cache on the project's self-hosted Docker server. Build cache is host-wide, so other projects on that server may rebuild dependencies on their next deployment. Returns reclaimed bytes. | `project:admin` Self-hosted |
| `post_projects_by_id_cluster_databases` `POST /api/projects/:id/cluster/databases` | Create PostgreSQL or Redis on a ready cluster using a stable requestId. Optional clusterId prepares data before moving a Docker application. Choose only one source: restoreFrom a managed backup, importFrom a listed project backup, or copyFrom a ready PostgreSQL database for a reviewed copy or major upgrade. The original is preserved; switching application connections and deployment are separate actions. Redis cluster mode requires clusterAwareClient:true. Inspect saved progress until ready. | `project:write` Self-hosted |
| `post_projects_by_id_cluster_databases_backup` `POST /api/projects/:id/cluster/databases/backup` | Save a PostgreSQL or Redis backup using the latest expectedSequence and configured destination. Inspect until the backup completes. Redis snapshots are consistent per partition, with no cross-partition transaction guarantee. | `project:write` Self-hosted |
| `post_projects_by_id_cluster_databases_connect` `POST /api/projects/:id/cluster/databases/connect` | Save this database’s application connection under envKey, or remove its managed connection with envKey:null. Requires latest expectedSequence and refuses overwriting an unrelated variable. Redeploy the application separately to apply environment changes. | `project:write` Self-hosted |
| `post_projects_by_id_cluster_databases_inspect` `POST /api/projects/:id/cluster/databases/inspect` | Read a managed database by databaseId. Set observe:true for fresh native-operator, instance, volume and backup observations; inspect timestamps and errors before claiming readiness. | `project:read` Self-hosted |
| `post_projects_by_id_cluster_databases_retry` `POST /api/projects/:id/cluster/databases/retry` | Resume a failed or interrupted database operation using its latest expectedSequence. Retains the saved intent, including deletion; inspect its error and progress before retrying. | `project:write` Self-hosted |
| `post_projects_by_id_cluster_scale` `POST /api/projects/:id/cluster/scale` | Scale an already deployed k3s application to 1–100 replicas using expectedDeploymentId and expectedUpdatedAt from a fresh cluster read. Starts a configuration deployment with the active immutable image, without rebuilding. Poll the returned deploymentId, then verify observed ready/available replicas. This is manual replica scaling, not a metrics-driven autoscaling policy. | `project:write` Self-hosted |
| `post_projects_by_id_cluster_volumes` `POST /api/projects/:id/cluster/volumes` | Create a replicated shared volume, optionally restored into a new volume from a completed project backup. Reuse a stable requestId after a lost response. Attach it using the project's cluster config mounts and deploy. | `project:write` Self-hosted |
| `post_projects_by_id_cluster_volumes_backup` `POST /api/projects/:id/cluster/volumes/backup` | Create a file-volume backup at the cluster's configured external destination. Use a stable requestId and inspect progress; application-consistent snapshots may require pausing writes. | `project:write` Self-hosted |
| `post_projects_by_id_connect` `POST /api/projects/:id/connect` | Attach a custom domain to this project, with optional www alias or external ingress. Inspect the returned routing status and pending actions; attaching a hostname does not prove DNS or HTTPS readiness. | `project:write` |
| `post_projects_by_id_connections` `POST /api/projects/:id/connections` | Connect a database app into this project (inject its connection URL as a secret env). | `project:write` |
| `post_projects_by_id_connections_bundle` `POST /api/projects/:id/connections/bundle` | Wire several outputs from one source app into this project atomically (all-or-nothing). | `project:write` |
| `post_projects_by_id_disable` `POST /api/projects/:id/disable` | Disable a project (pause deploys / take offline). | `project:write` |
| `post_projects_by_id_enable` `POST /api/projects/:id/enable` | Enable a project (allow deploys / bring online). | `project:write` |
| `post_projects_by_id_env_migrate_commands` `POST /api/projects/:id/env/migrate-commands` | Atomically move literal command variables into encrypted project or service Environment. Refuses changed commands, shell expressions, and conflicting values. | `project:write` |
| `post_projects_by_id_environments` `POST /api/projects/:id/environments` | Create a project environment (e.g. a preview). | `project:write` |
| `post_projects_by_id_git_link` `POST /api/projects/:id/git/link` | Link a git repository to the project. | `project:write` |
| `post_projects_by_id_incoming_webhooks` `POST /api/projects/:id/incoming-webhooks` | Create an incoming webhook that fires a deploy or job when its URL is called. | `project:write` |
| `post_projects_by_id_incoming_webhooks_by_hookId_invoke` `POST /api/projects/:id/incoming-webhooks/:hookId/invoke` | Invoke an enabled incoming webhook with the current and saved actor's permissions. | `project:write` |
| `post_projects_by_id_incoming_webhooks_by_hookId_rotate` `POST /api/projects/:id/incoming-webhooks/:hookId/rotate` | Rotate an incoming webhook's token / HMAC secret. | `project:write` |
| `post_projects_by_id_options` `POST /api/projects/:id/options` | Set build/deploy options for a project. | `project:write` |
| `post_projects_by_id_output_check` `POST /api/projects/:id/output-check` | Live static-output check for the project's active deployment (advisory; static apps). | `project:read` |
| `post_projects_by_id_port_check` `POST /api/projects/:id/port-check` | Live port-reachability check for the project's active deployment (advisory). | `project:read` |
| `post_projects_by_id_previews` `POST /api/projects/:id/previews` | Enable or disable isolated same-repository pull request previews. Preview Environment values are used; disabling cleans up managed previews. | `project:write` |
| `post_projects_by_id_roles_configuration` `POST /api/projects/:id/roles/configuration` | Apply runtime role settings using the active image without rebuilding or restarting web. Expected release and project revision prevent stale edits. | `project:write` |
| `post_projects_by_id_route_rules` `POST /api/projects/:id/route-rules` | Create an edge traffic rule for this project, optionally scoped to a domain or path. A rule can block live traffic; read the existing rules before changing access. | `project:write` Self-hosted |
| `post_projects_by_id_routing_retry` `POST /api/projects/:id/routing/retry` | Repair project routes and verify pending domains and HTTPS without rebuilding; clears the routing warning only when all checks succeed. | `project:write` |
| `post_projects_by_id_sleep_mode` `POST /api/projects/:id/sleep-mode` | Set the project's sleep mode (auto_sleep / always_on). | `project:write` |
| `post_projects_by_id_storage` `POST /api/projects/:id/storage` | Bind an S3 bucket to this project — either an installed MinIO app or an external provider. Verifies the bucket, then injects the framework's storage env vars. | `project:write` |
| `post_projects_by_id_transfer_to_cloud` `POST /api/projects/:id/transfer/to-cloud` | Transfer this project’s control-plane records to the connected Openship Cloud. Inspect the returned deployment guidance: record transfer is not workload or volume migration. k3s projects cannot use this Docker/Cloud transfer path. | `project:admin` Self-hosted |
| `post_projects_by_id_transfer_to_self_hosted` `POST /api/projects/:id/transfer/to-self-hosted` | Transfer this Cloud project’s control-plane records to this self-hosted instance. Inspect returned guidance and deploy separately; this does not move database volumes. k3s workloads use their cluster lifecycle. | `project:admin` Self-hosted |
| `post_projects_by_id_webhook_domain` `POST /api/projects/:id/webhook-domain` | Choose or clear a verified public webhook domain for the project’s GitHub auto-deploy endpoint. This configures webhook delivery; it does not add a site route. | `project:write` |
| `post_projects_ensure` `POST /api/projects/ensure` | Folder-upload deploy — STEP 3/4. Create or update the project that carries the build config — deployments/build/access reads config from the PROJECT ROW, not the upload session, so this must run first. Map the folder/scan fields in (framework = the scan's stack id) and set gitProvider:'upload'. For a docker-compose folder, pass the scan's `services` array through too — that persists the project's service set — AND pass `uploadSessionId` with it, since the scan masks env values (`••••••••`) and that is what restores them. Pass projectId to update an existing project. Returns the project id for STEP 4. | `project:write` |
| `post_projects_folder_scan_by_sessionId` `POST /api/projects/folder/scan/:sessionId` | Folder-upload deploy — STEP 2/4. Run AFTER the tarball is uploaded. Detects the uploaded source's framework/build config (stack, packageManager, install/build/start commands, outputDirectory, productionPaths, port) and, for a docker-compose folder, the `services` array. Body may be empty ({}). Feed the result into projects/ensure (STEP 3) — including `services` verbatim when present. | `project:write` |
| `post_projects_folder_session` `POST /api/projects/folder/session` | Open a folder-upload session for projectId. Credentials limited to their own projects must create a project first and pass its id; omitting projectId requires wildcard project write access. Returns upload = { url, absoluteUrl, method, headers, requiresAuth }. An authenticated HTTP uploader must POST the gzipped tarball with the returned headers and the same API credential. Binary upload is not an MCP tool and MCP does not expose its OAuth bearer. For a folder on the desktop controller's machine, use projects/import with localPath instead. After upload: folder/scan → projects/ensure (explicit projectId) → deployments/build/access. | `project:write` |
| `post_projects_import` `POST /api/projects/import` | Register a project from a source directory accessible to the Openship controller. On desktop, use localPath and an accessible managed serverId to deploy that folder to Cloud without an out-of-band upload. This creates project configuration; deploy the returned projectId separately with buildStrategy:'server' for a managed server. Source location does not choose build location. | `project:write` Self-hosted |
| `post_projects_scan` `POST /api/projects/scan` | Inspect a source directory accessible to the Openship controller and detect build or Compose configuration. For a folder on the MCP client machine, use the folder-upload workflow. | `project:write` Self-hosted |
| `put_projects_by_id_release_image_source` `PUT /api/projects/:id/release-image-source` | Atomically configure this single-app project to track and deploy a prebuilt container image from GitHub releases or a version URL. | `project:write` |
### services
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_projects_by_id_services_by_serviceId` `DELETE /api/projects/:id/services/:serviceId` | Delete this service from its project and clean up its owned runtime. Review persistent volumes and dependent services before removing it. | `project:service:admin` |
| `get_projects_by_id_services` `GET /api/projects/:id/services` | List a project's services (compose services / monorepo sub-apps). | `project:service:list` |
| `get_projects_by_id_services_by_serviceId` `GET /api/projects/:id/services/:serviceId` | Get one service by id. | `project:service:read` |
| `get_projects_by_id_services_by_serviceId_env` `GET /api/projects/:id/services/:serviceId/env` | List a service's environment variables. | `project:service:read` |
| `get_projects_by_id_services_by_serviceId_environment` `GET /api/projects/:id/services/:serviceId/environment` | Read the effective saved environment for a service, including Compose and shared project values. Optionally compare it with its deployed container. Secrets are masked. | `project:service:read` |
| `get_projects_by_id_services_by_serviceId_logs` `GET /api/projects/:id/services/:serviceId/logs` | Fetch a service's runtime logs (non-streaming). | `project:service:read` |
| `get_projects_by_id_services_by_serviceId_volume_sizes` `GET /api/projects/:id/services/:serviceId/volume-sizes` | Measure the on-disk size (du) of each of a service's volumes. | `project:service:read` |
| `get_projects_by_id_services_containers` `GET /api/projects/:id/services/containers` | List the running containers for a project's services. | `project:read` |
| `patch_projects_by_id_services_by_serviceId` `PATCH /api/projects/:id/services/:serviceId` | Update a service's configuration. Partial: an omitted field is left alone. `environment` and `advanced` are MERGED onto the stored values rather than replacing them — omit a key to keep it, set a key to null to remove it, send null for the whole field to clear it. Env values read back masked as `••••••••`; echo the sentinel to keep one unchanged. Every other field (`ports`, `volumes`, `dependsOn`, `publicEndpoints`, …) REPLACES its stored value wholesale, so send the complete list. | `project:service:write` |
| `patch_projects_by_id_services_by_serviceId_env` `PATCH /api/projects/:id/services/:serviceId/env` | Save only the named service environment overrides. Preserve other variables; source IDs reject stale edits. | `project:service:write` |
| `post_projects_by_id_services` `POST /api/projects/:id/services` | Add a service to a project. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_apply_env` `POST /api/projects/:id/services/:serviceId/apply-env` | Apply saved runtime environment to this service using its current image and runtime configuration. Gracefully replaces its container without a build or deployment session. Returns after the replacement starts; preserves the previous configuration on failure. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_drift_accept` `POST /api/projects/:id/services/:serviceId/drift/accept` | Accept upstream docker-compose changes for this service. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_drift_keep` `POST /api/projects/:id/services/:serviceId/drift/keep` | Keep local edits over upstream docker-compose changes for this service. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_exec` `POST /api/projects/:id/services/:serviceId/exec` | Run a shell command inside this service's running container and return its exit code and combined output. Interpreted by `sh -c`; stderr is merged in. Times out (default 30s, max 120s) and truncates large output. Requires a Docker runtime — a bare or cloud-hosted service has no container to enter. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_restart` `POST /api/projects/:id/services/:serviceId/restart` | Restart (bounce) this service's container. Answers 409 SERVICE_CONFIG_STALE when saved env is pending. Use POST /api/projects/:id/services/:serviceId/apply-env to apply it, or ?force=true to bounce with the old env. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_start` `POST /api/projects/:id/services/:serviceId/start` | Start this service's container. | `project:service:write` |
| `post_projects_by_id_services_by_serviceId_stop` `POST /api/projects/:id/services/:serviceId/stop` | Stop this service's container. | `project:service:write` |
| `post_projects_by_id_services_sync` `POST /api/projects/:id/services/sync` | Sync services from the project's docker-compose file into the service table. | `project:service:write` |
| `put_projects_by_id_services_by_serviceId_env` `PUT /api/projects/:id/services/:serviceId/env` | Replace a service's environment variables. | `project:service:write` |
### settings
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_settings` `GET /api/settings` | Get the org's workspace settings (build mode, deploy defaults, preferences). | `settings:read` |
| `get_settings_appearance` `GET /api/settings/appearance` | Get the authenticated user's personal theme library and active appearance. Does not read other users' themes. | `settings:read` |
| `get_settings_webhook_deliveries` `GET /api/settings/webhook-deliveries` | List the org's webhook delivery feed, including pushes forwarded to Cloud or from unmanaged repos (paginated). | `settings:read` |
| `patch_settings_build_mode` `PATCH /api/settings/build-mode` | Set the default build mode (server / local). | `settings:write` |
| `patch_settings_clone_strategy_preference` `PATCH /api/settings/clone-strategy-preference` | Set the default clone strategy preference (prompt / local / remote-with-token). | `settings:write` |
| `patch_settings_deploy_defaults` `PATCH /api/settings/deploy-defaults` | Set/clear the default deploy target (local/server/cloud) and server. | `settings:write` |
| `patch_settings_forward_git` `PATCH /api/settings/forward-git` | Enable/disable forwarding your local git identity (gh CLI) to remote build servers during a server clone. | `settings:write` |
| `patch_settings_route_strategy` `PATCH /api/settings/route-strategy` | Set the default edge→app route strategy (auto / loopback-port / container-ip). | `settings:write` |
| `patch_settings_transfer` `PATCH /api/settings/transfer` | Set the default volume-transfer mode (auto/stream/direct/rsync) and compression (auto/zstd/gzip/none) for migrations. | `settings:write` |
| `put_settings_appearance` `PUT /api/settings/appearance` | Save the authenticated user's versioned appearance JSON, including validated theme tokens and embedded WOFF2 fonts. Null resets saved appearance. | `settings:write` |
### system
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `delete_system_compute_clusters_by_id` `DELETE /api/system/compute-clusters/:id` | Delete an empty compute-cluster record using its current revision. Remove dependent projects, databases and the owned runtime first. Private networks and registered servers are retained. | `server:admin` Self-hosted |
| `delete_system_compute_clusters_by_id_runtime` `DELETE /api/system/compute-clusters/:id/runtime` | Start removal of the owned k3s installation using the latest runtime sequence. Refuses attached projects, database data or foreign resources. Poll runtime until removed; failures are resumable. Retains Docker workloads and private networking. | `server:admin` Self-hosted |
| `delete_system_compute_clusters_by_id_storage` `DELETE /api/system/compute-clusters/:id/storage` | Remove an empty shared-storage installation using its latest sequence. Refuses persistent or retained volumes and preserves external backup archives. | `server:admin` Self-hosted |
| `delete_system_networks_by_id` `DELETE /api/system/networks/:id` | Remove a native private-network record using its current revision. Dependencies block removal. For an Openship-managed WireGuard network, prepare and apply a removal plan first; this call does not force-delete host networking. | `server:admin` Self-hosted |
| `delete_system_networks_operations_by_operationId` `DELETE /api/system/networks/operations/:operationId` | Discard an unapplied managed-network plan using its current planHash. Refuses active or partially applied plans; inspect the operation and use its rollback action when host cleanup is required. | `server:admin` Self-hosted |
| `delete_system_networks_operations_by_operationId_members_by_serv` `DELETE /api/system/networks/operations/:operationId/members/:serverId` | Remove a server from an unfinished managed-network operation using its planHash and sequence. Reconciles owned partial changes and returns a replacement preparation/plan; inspect it before applying. | `server:admin` Self-hosted |
| `delete_system_networks_preparations_by_preparationId` `DELETE /api/system/networks/preparations/:preparationId` | Cancel or discard an unfinished managed-network preparation using its latest sequence. Follow any returned cleanupOperationId until owned host changes have been cleaned up; a cancellation request alone does not prove cleanup finished. | `server:admin` Self-hosted |
| `delete_system_networks_preparations_by_preparationId_members_by_` `DELETE /api/system/networks/preparations/:preparationId/members/:serverId` | Remove a server from an unfinished managed-network preparation using the latest sequence and a new requestId. Returns replacement setup state and any required cleanup; this is not live k3s worker removal. | `server:admin` Self-hosted |
| `delete_system_servers_by_id` `DELETE /api/system/servers/:id` | Remove this registered server and its managed records. Read deletion-preview first. query.destroyOnSource explicitly selects remote workload destruction; without it, workloads are left on the source. | `server:admin` Self-hosted |
| `delete_system_servers_by_id_managed` `DELETE /api/system/servers/:id/managed` | Delete an empty managed server after its subscription has ended. Requires billing admin, explicit confirmation and an idempotency key. Refuses servers with projects; confirms provider removal before removing ownership. Project deletion never deletes this server. | `server:admin` |
| `delete_system_servers_by_id_tunnels_by_tunnelId` `DELETE /api/system/servers/:id/tunnels/:tunnelId` | Stop and delete this saved SSH tunnel. Connections using its local port will close. | `server:write` Self-hosted |
| `get_system_browse` `GET /api/system/browse` | Browse source directories on this Openship controller, not the MCP client. Requires instance administrator authority; use folder upload for a client-side directory. | `settings:read` Self-hosted |
| `get_system_compute_clusters` `GET /api/system/compute-clusters` | List compute clusters, their server membership, selected private network and saved k3s readiness. A compute cluster does not become ready for deployments until runtime setup succeeds. | `server:read` Self-hosted |
| `get_system_compute_clusters_by_id` `GET /api/system/compute-clusters/:id` | Read a compute cluster and its current revision, server IDs, private network and saved runtime readiness. Use this revision when setting up k3s or changing the cluster. | `server:read` Self-hosted |
| `get_system_compute_clusters_by_id_runtime` `GET /api/system/compute-clusters/:id/runtime` | Read saved k3s setup or removal progress, including status, sequence, per-host steps, logs and errors; returns null before setup. Poll this endpoint after starting work. Reading never starts or retries an operation. | `server:read` Self-hosted |
| `get_system_compute_clusters_by_id_storage` `GET /api/system/compute-clusters/:id/storage` | Read shared-storage setup, capacity and saved progress. Use observe=true for current disk and volume health. | `server:read` Self-hosted |
| `get_system_containers` `GET /api/system/containers` | List the cached managed-container inventory across registered servers. Scan the fleet or one server for fresh observations. | `server:read` Self-hosted |
| `get_system_containers_applying` `GET /api/system/containers/applying` | Read queued, running and recently completed managed-container update or repair operations. Poll after starting a fleet apply. | `server:read` Self-hosted |
| `get_system_containers_behind` `GET /api/system/containers/behind` | Read the fleet-wide count of managed containers with available updates. This reads cached inventory; scan to refresh it. | `server:read` Self-hosted |
| `get_system_containers_issues` `GET /api/system/containers/issues` | List managed-container problems across the server fleet, including stale or unreachable observations. | `server:read` Self-hosted |
| `get_system_diagnostics` `GET /api/system/diagnostics` | Read instance health, database/migration status and resource counts. Requires instance administrator authority. This does not inspect every remote workload. | `settings:read` Self-hosted |
| `get_system_edge_untracked` `GET /api/system/edge/untracked` | Inspect edge hostnames that are not owned by any project in this instance. Requires instance administrator authority; compare ownership before removing anything. | `settings:read` Self-hosted |
| `get_system_install_session` `GET /api/system/install/session` | Read the current or named server installation session, including progress and pending decisions. query.serverId selects the server; query.sessionId reattaches to a specific session. | `server:read` Self-hosted |
| `get_system_networks` `GET /api/system/networks` | List private networks with members, saved verification and any managed setup operation. Private networks provide connectivity; compute clusters and their k3s runtime are separate resources. | `server:read` Self-hosted |
| `get_system_networks_by_id` `GET /api/system/networks/:id` | Read a private network, its current revision, member addresses, verification report and managed operation. Poll after verification; a saved report is dated evidence, not continuous monitoring. | `server:read` Self-hosted |
| `get_system_networks_capabilities` `GET /api/system/networks/capabilities` | Check whether private networking is available, whether this credential may manage the server fleet, supported providers and network modes, and member limits. Start network or cluster setup here. | `server:read` Self-hosted |
| `get_system_networks_operations_by_operationId` `GET /api/system/networks/operations/:operationId` | Read a managed-network operation, its planHash, sequence, per-host steps/logs, verification report and errors. Poll while applying, verifying, committing or rolling_back. A saved plan is not an applied network. | `server:read` Self-hosted |
| `get_system_networks_preparations` `GET /api/system/networks/preparations` | List saved managed-network preparations so interrupted setup can be found without starting another operation. | `server:read` Self-hosted |
| `get_system_networks_preparations_by_preparationId` `GET /api/system/networks/preparations/:preparationId` | Read a managed-network preparation’s status, sequence, per-host steps/logs and errors. When ready, follow operationId to inspect the generated plan. replacementPreparationId and cleanupOperationId identify any follow-up work. | `server:read` Self-hosted |
| `get_system_servers` `GET /api/system/servers` | List registered deployment servers accessible to this credential, with server IDs and connection summaries. Use these IDs for infrastructure operations; private-network and compute-cluster IDs are different. | `server:list` |
| `get_system_servers_by_id` `GET /api/system/servers/:id` | Read this registered server’s configuration, supported capabilities, managed plan and lifecycle progress. Stored SSH secrets are not returned. Use reachability for a fresh connection check. | `server:read` |
| `get_system_servers_by_id_containers` `GET /api/system/servers/:id/containers` | Read managed containers and their cached health/version information on this server. | `server:read` Self-hosted |
| `get_system_servers_by_id_containers_by_component_apply_session` `GET /api/system/servers/:id/containers/:component/apply/session` | Read the active managed-container update or repair session for this server component. This only observes an existing operation. | `server:read` Self-hosted |
| `get_system_servers_by_id_deletion_preview` `GET /api/system/servers/:id/deletion-preview` | Preview which projects, apps and server-scoped records would be affected by deleting this server. Review this before removal; no resources are changed. | `server:read` Self-hosted |
| `get_system_servers_by_id_github` `GET /api/system/servers/:id/github` | Read GitHub authentication status on this deployment server. This is the server’s clone identity, distinct from the controller’s GitHub connection. | `server:read` Self-hosted |
| `get_system_servers_by_id_github_connect_poll` `GET /api/system/servers/:id/github/connect/poll` | Poll GitHub device authorization already started on this server. The user must complete the returned browser approval. | `server:read` Self-hosted |
| `get_system_servers_by_id_infrastructure` `GET /api/system/servers/:id/infrastructure` | Read this server’s attached private networks and compute cluster, subject to fleet visibility. Use these resource IDs to inspect network or k3s readiness. | `server:read` Self-hosted |
| `get_system_servers_by_id_managed_info` `GET /api/system/servers/:id/managed/info` | Read the selected managed server image, operating system, lifecycle and actual allocation. Does not start the VM or return its raw configuration. | `server:read` |
| `get_system_servers_by_id_managed_outbound` `GET /api/system/servers/:id/managed/outbound` | Read this managed server's outbound connection and revision. Returns only public IP/proxy metadata, never credentials. Does not start the server. | `server:read` |
| `get_system_servers_by_id_managed_outbound_options` `GET /api/system/servers/:id/managed/outbound/options` | List available managed outbound IPs and countries for this owned Cloud server. No proxy credentials or internal pool identifiers are exposed. | `server:read` |
| `get_system_servers_by_id_managed_runtime_api` `GET /api/system/servers/:id/managed/runtime-api` | Read the managed server Runtime API status without enabling it or returning a token. | `server:read` |
| `get_system_servers_by_id_managed_ssh` `GET /api/system/servers/:id/managed/ssh` | Read SSH enablement and public connection instructions for this managed server. Never returns passwords. | `server:read` |
| `get_system_servers_by_id_managed_workloads` `GET /api/system/servers/:id/managed/workloads` | List native managed processes with live status, capped at 100 entries. Distinguishes manual, project and system workloads; does not return environments or commands. | `server:read` |
| `get_system_servers_by_id_modules` `GET /api/system/servers/:id/modules` | List installed native modules, available updates and migrations requiring consent on this server. | `server:read` Self-hosted |
| `get_system_servers_by_id_network_settings` `GET /api/system/servers/:id/network-settings` | Read a managed Docker server's provider network settings. Add details=true for outbound rules, IP diagnostics and the revision required to edit rules. Null internetAccess means unavailable. Ports are managed by project routing; this read never starts the server. | `server:read` |
| `get_system_servers_by_id_rate_limit` `GET /api/system/servers/:id/rate-limit` | Read this server’s OpenResty request-rate limit, burst allowance and whitelist. | `server:read` Self-hosted |
| `get_system_servers_by_id_reachability` `GET /api/system/servers/:id/reachability` | Probe whether the Openship controller can reach this server now. A controller connection failure is not evidence that deployed applications are down. | `server:read` |
| `get_system_servers_by_id_resize` `GET /api/system/servers/:id/resize` | Preview applying a managed server's purchased capacity. Returns a revision and the projects that may restart; no billing or runtime changes. Review before resize. Disk shrinking requires migration. | `server:read` |
| `get_system_servers_by_id_tunnels` `GET /api/system/servers/:id/tunnels` | List saved SSH port-forwarding tunnels for this server and their current state. Tunnels run from this Openship controller, not from the MCP client. | `server:read` Self-hosted |
| `get_system_servers_by_id_usage` `GET /api/system/servers/:id/usage` | Read measured CPU, memory and disk usage plus accessible projects on this server. Purchased disk is capacity, not bytes used. Unavailable measurements are null. This never provisions or resumes a server. | `server:read` |
| `get_system_servers_destinations` `GET /api/system/servers/destinations` | Read accessible deployment servers and their capabilities. Use serverId to place a project on a connected or managed Cloud server. | `server:list` |
| `get_system_servers_managed_available` `GET /api/system/servers/managed/available` | List managed servers available through this installation's connected Cloud account. Does not create a server or copy projects. Use connectManaged to add a selected server to this organization. | `server:admin` |
| `get_system_settings` `GET /api/system/settings` | Read public instance settings and setup state, with secrets masked. | `settings:read` Self-hosted |
| `get_system_settings_email` `GET /api/system/settings/email` | Read instance email-delivery configuration with credentials masked. | `settings:read` Self-hosted |
| `patch_system_compute_clusters_by_id` `PATCH /api/system/compute-clusters/:id` | Update compute-cluster membership and network using the current revision. A runtime must be removed before changing its members; this is not live worker joining or draining. | `server:admin` Self-hosted |
| `patch_system_compute_clusters_by_id_storage_backup` `PATCH /api/system/compute-clusters/:id/storage/backup` | Configure an existing external backup destination for shared files. Uses the current storage sequence and preserves an already configured destination so archives stay recoverable. | `server:admin` Self-hosted |
| `patch_system_networks_by_id` `PATCH /api/system/networks/:id` | Replace a native private network configuration using its current revision. Existing runtime dependencies block membership changes. Verify again after changing the configuration. | `server:admin` Self-hosted |
| `patch_system_networks_preparations_by_preparationId_connections` `PATCH /api/system/networks/preparations/:preparationId/connections` | Revise permitted server-to-server connections for an unfinished managed-network preparation using its latest sequence and a new requestId. Returns replacement preparation; inspect and apply its new plan. k3s requires bidirectional access among all selected members. | `server:admin` Self-hosted |
| `patch_system_servers_by_id` `PATCH /api/system/servers/:id` | Update this registered server’s name or SSH connection settings. Omitted fields are preserved. Check reachability after changing connection settings. | `server:write` |
| `patch_system_servers_by_id_managed_outbound` `PATCH /api/system/servers/:id/managed/outbound` | Change this managed server's outbound connection after explicit review. Send expectedRevision from managed/outbound and confirm:true. Choose a listed managed IP, or a custom public IPv4 HTTP/HTTPS proxy with both credentials or neither. Affects outgoing connections for every project; preserves internet policy, ingress and routes. Credentials are never returned or audited. | `server:admin` |
| `patch_system_servers_by_id_managed_ssh` `PATCH /api/system/servers/:id/managed/ssh` | Enable or disable SSH with explicit confirmation and expected enablement. Changes all SSH users on this server. | `server:admin` |
| `patch_system_servers_by_id_network_settings` `PATCH /api/system/servers/:id/network-settings` | Change outbound internet access and optional egress host allowlist on a managed Docker server after reviewing current settings. Egress changes also require expectedRevision from the network read. Disabling it affects downloads, external APIs and builds for every project. Send expectedInternetAccess and confirm:true. Ingress, private links and edge routing remain managed by Openship and Oblien. | `server:admin` |
| `patch_system_servers_by_id_rate_limit` `PATCH /api/system/servers/:id/rate-limit` | Update the server-wide OpenResty rate limit and whitelist. This affects traffic to all routes on the server. | `server:admin` Self-hosted |
| `post_system_check` `POST /api/system/check` | Inspect required software and component readiness on body.serverId. Returns missing components and health messages; does not install them. | `server:admin` |
| `post_system_compute_clusters` `POST /api/system/compute-clusters` | Create a compute cluster from registered servers on one private network. Reuse requestId for the same intent after a lost response. This saves membership; start its runtime setup next. | `server:admin` Self-hosted |
| `post_system_compute_clusters_by_id_runtime` `POST /api/system/compute-clusters/:id/runtime` | Start durable k3s setup on this compute cluster with its current revision and a stable requestId. Checks private connectivity and host prerequisites before installation. Returns accepted progress, not completion; poll runtime until ready, failed or interrupted. Requires fleet administration. | `server:admin` Self-hosted |
| `post_system_compute_clusters_by_id_runtime_retry` `POST /api/system/compute-clusters/:id/runtime/retry` | Resume a failed or interrupted k3s setup or removal using the latest runtime sequence. Reuses the saved version, ownership and operation intent. Inspect errors first and poll runtime for completion; do not retry merely because a response was lost. | `server:admin` Self-hosted |
| `post_system_compute_clusters_by_id_storage` `POST /api/system/compute-clusters/:id/storage` | Enable persistent and shared storage on reviewed cluster servers and dedicated empty directories. Installs prerequisites without formatting disks. Reuse requestId after a lost response and follow saved progress. | `server:admin` Self-hosted |
| `post_system_compute_clusters_by_id_storage_retry` `POST /api/system/compute-clusters/:id/storage/retry` | Resume failed or interrupted storage setup/removal using its latest sequence. Inspect the error before retrying. | `server:admin` Self-hosted |
| `post_system_containers_apply_all` `POST /api/system/containers/apply-all` | Start the selected update or repair intents for managed containers across the fleet. Targets come from current inventory. Poll containers/applying for progress and failures. | `server:write` Self-hosted |
| `post_system_containers_scan` `POST /api/system/containers/scan` | Refresh managed-container versions and health across the server fleet without applying updates. | `server:write` Self-hosted |
| `post_system_edge_untracked_remove` `POST /api/system/edge/untracked/remove` | Remove one untracked hostname from the edge after rechecking that no project owns it. Requires instance administrator authority. Never use this to repair a domain still owned by a project. | `settings:admin` Self-hosted |
| `post_system_install` `POST /api/system/install` | Install one named component on body.serverId using the shared server installer. Read check first. For k3s cluster setup use the compute-cluster runtime tool, which verifies the whole cluster. | `server:admin` Self-hosted |
| `post_system_install_respond` `POST /api/system/install/respond` | Answer a server installation’s current pending prompt using its sessionId and an offered action ID. Read install/session first; never invent a takeover decision. | `server:admin` Self-hosted |
| `post_system_networks` `POST /api/system/networks` | Register an existing native private network using discovered private interfaces and distinct IPv4 addresses. This does not provision a provider network. Reuse requestId after a lost response, then verify the saved network. | `server:admin` Self-hosted |
| `post_system_networks_by_id_verify` `POST /api/system/networks/:id/verify` | Start bidirectional private-network verification for the current revision. Poll the network detail until verification finishes and inspect its peer report. Provider firewall rules must already permit the probe traffic. | `server:admin` Self-hosted |
| `post_system_networks_operations_by_operationId_apply` `POST /api/system/networks/operations/:operationId/apply` | Apply, resume or roll back the exact managed-network plan identified by planHash. Review host changes and provider firewall requirements first. Returns accepted progress; poll the operation until it settles and inspect failures before retrying. | `server:admin` Self-hosted |
| `post_system_networks_plans` `POST /api/system/networks/plans` | Plan an Openship-managed WireGuard network change without applying it. Returns an expiring planHash, host changes and firewall requirements. Reuse requestId for the same intent; inspect the plan before calling operations/apply. | `server:admin` Self-hosted |
| `post_system_networks_preparations` `POST /api/system/networks/preparations` | Start durable preparation for managed WireGuard networking: check hosts and install missing prerequisites, then produce a reviewed plan. Reuse requestId after a lost response. Poll the preparation; when ready, inspect its operationId and plan before applying networking. | `server:admin` Self-hosted |
| `post_system_remove` `POST /api/system/remove` | Remove one managed component from body.serverId. This may interrupt workloads using it; read component readiness and removal restrictions first. | `server:admin` Self-hosted |
| `post_system_servers` `POST /api/system/servers` | Register a deployment server with SSH connection settings. Credentials are encrypted by the existing server operation. This does not create a cloud machine; test its connection and inspect prerequisites next. | `server:write` Self-hosted |
| `post_system_servers_by_id_containers_scan` `POST /api/system/servers/:id/containers/scan` | Refresh managed-container versions and health on this server without applying changes. | `server:write` Self-hosted |
| `post_system_servers_by_id_ensure` `POST /api/system/servers/:id/ensure` | Queue idempotent provisioning or resume of a subscribed managed Cloud server. Checks provider entitlement and preserves existing data. Docker and bare projects reuse this server. Poll server get for operation progress. | `server:write` |
| `post_system_servers_by_id_exec` `POST /api/system/servers/:id/exec` | Run a shell command on this server's host and return its exit code and combined output. Interpreted by `sh -c`, so pipes and redirects work; stderr is merged in. Times out (default 30s, max 120s) and truncates large output. Use this to inspect or repair a server; prefer the read-only endpoints when they answer the question. | `server:admin` |
| `post_system_servers_by_id_github_connect` `POST /api/system/servers/:id/github/connect` | Start GitHub device authorization on this deployment server. Present the returned user code and URL to the user, then poll the server GitHub connection. | `server:write` Self-hosted |
| `post_system_servers_by_id_managed_boot_logs` `POST /api/system/servers/:id/managed/boot-logs` | Read a bounded tail of managed server boot logs. Requires server admin; logs may contain application output. | `server:admin` |
| `post_system_servers_by_id_managed_runtime_api_credential` `POST /api/system/servers/:id/managed/runtime-api/credential` | Reveal the current workspace-only Runtime API credential. Requires server admin and confirmation. Does not enable the service or issue an account/namespace token. | `server:admin` |
| `post_system_servers_by_id_managed_runtime_api_enable` `POST /api/system/servers/:id/managed/runtime-api/enable` | Enable the Runtime API used by Openship for deployments and server management. Requires server admin and active server entitlement. | `server:admin` |
| `post_system_servers_by_id_managed_runtime_api_rotate` `POST /api/system/servers/:id/managed/runtime-api/rotate` | Rotate the Runtime API credential after reviewing the current revision. Invalidates prior tokens and sessions. A stale revision cannot repeat a successful rotation. | `server:admin` |
| `post_system_servers_by_id_managed_ssh_connection` `POST /api/system/servers/:id/managed/ssh/connection` | Issue a short-lived SSH connection for this managed server. Requires server admin and confirmation. Treat its password as a secret. | `server:admin` |
| `post_system_servers_by_id_managed_workloads` `POST /api/system/servers/:id/managed/workloads` | Create a stopped manual native process on this server. Reuse the same idempotency key after an uncertain response. Commands and environment are admin-only and not audited. Start it explicitly after creation. | `server:admin` |
| `post_system_servers_by_id_managed_workloads_control` `POST /api/system/servers/:id/managed/workloads/control` | Start, stop or delete a manual process created by the server controls. Requires confirmation. Project and platform processes must use their own lifecycle controls. | `server:admin` |
| `post_system_servers_by_id_managed_workloads_logs` `POST /api/system/servers/:id/managed/workloads/logs` | Read bounded logs for a process on this managed server. Requires server admin. Process ID is scoped to the server. | `server:admin` |
| `post_system_servers_by_id_modules_by_module_apply` `POST /api/system/servers/:id/modules/:module/apply` | Apply available updates to this native server module through its owned migration workflow. Read modules first and inspect pendingConsent in the result; a returned consent request is not a completed update. | `server:write` Self-hosted |
| `post_system_servers_by_id_modules_scan` `POST /api/system/servers/:id/modules/scan` | Refresh native-module versions and available migration information on this server. Does not apply updates. | `server:write` Self-hosted |
| `post_system_servers_by_id_network_inspect` `POST /api/system/servers/:id/network/inspect` | Inspect this server’s actual network interfaces, private IPv4 addresses, MTUs and machine identity over SSH. Does not change networking. Use the observation to register a native private network. | `server:admin` Self-hosted |
| `post_system_servers_by_id_ports_scan` `POST /api/system/servers/:id/ports/scan` | Inspect listening ports through this server's execution connection. Returns protocol, bound address and process without changing listeners. Managed Cloud listeners are inside the server; public access is controlled by provider networking and project routes. | `server:read` |
| `post_system_servers_by_id_resize` `POST /api/system/servers/:id/resize` | Apply a reviewed managed server resize with its preview revision, idempotency key and restart confirmation. Preserves container recovery checkpoints and waits for deployments. Poll server get for completion. | `server:admin` |
| `post_system_servers_by_id_retry` `POST /api/system/servers/:id/retry` | Retry this managed server's failed lifecycle operation. Reuses its provider identity and saved recovery checkpoint. Inspect the error first, then poll server get for progress. | `server:admin` |
| `post_system_servers_by_id_tunnels` `POST /api/system/servers/:id/tunnels` | Save an SSH port-forwarding tunnel configuration. Start it separately; its local bind address belongs to the Openship controller. | `server:write` Self-hosted |
| `post_system_servers_by_id_tunnels_by_tunnelId_start` `POST /api/system/servers/:id/tunnels/:tunnelId/start` | Start this saved tunnel on the Openship controller and return its local address. Read the tunnel list to inspect state. | `server:write` Self-hosted |
| `post_system_servers_by_id_tunnels_by_tunnelId_stop` `POST /api/system/servers/:id/tunnels/:tunnelId/stop` | Stop this controller-side SSH tunnel while retaining its saved configuration. | `server:write` Self-hosted |
| `post_system_servers_managed` `POST /api/system/servers/managed` | Create a managed Cloud server identity. Projects share its purchased capacity and use the Docker or bare runtime. This does not charge or provision. Subscribe to this server in Billing, then ensure it. Use the returned serverId for management and deployment. | `server:admin` |
| `post_system_servers_managed_connect` `POST /api/system/servers/managed/connect` | Connect an existing managed Cloud server to this self-hosted organization. Verifies Cloud server administration and pins its account identity. Returns the local serverId to use for deployments; no projects or subscriptions are copied. | `server:admin` |
| `post_system_test_connection` `POST /api/system/test-connection` | Test draft SSH connection settings before registering a server. Does not save a server or install components. | `server:write` Self-hosted |
| `put_system_servers_by_id_managed_ssh_key` `PUT /api/system/servers/:id/managed/ssh/key` | Replace the root authorized public key on this server. Accepts one OpenSSH public key; never a private key. Requires confirmation. | `server:admin` |
| `put_system_servers_by_id_managed_ssh_password` `PUT /api/system/servers/:id/managed/ssh/password` | Set the root SSH password on this managed server. Requires confirmation. The password is never returned or audited. | `server:admin` |
### updates
| Tool and HTTP route | Description | Access |
| --- | --- | --- |
| `get_updates` `GET /api/updates` | List update statuses for the org (apps, projects, self-app, webmail). ?behind=1 filters to those with an update available. | `updates:read` |
| `post_updates_by_projectId_apply` `POST /api/updates/:projectId/apply` | Apply the available update to a project/app (force-pulls image tags, redeploys, pre-deploy backup). | `project:write` |
| `post_updates_scan` `POST /api/updates/scan` | Trigger a fresh update scan across the org's projects/apps. | `updates:write` |
## HTTP-only routes
Every remaining route has an explicit boundary: browser authorization, streaming/binary transport, internal relay, compatibility alias, or an operator workflow. These exclusions do not remove HTTP functionality. The documentation check fails if a new authenticated route has neither MCP metadata nor an exclusion reason.
| HTTP route | Why it is not an MCP tool |
| --- | --- |
| `GET /` | Browser landing pages for API-only instances. |
| `GET /.well-known/oauth-authorization-server` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /.well-known/oauth-authorization-server/api/mcp` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /.well-known/oauth-authorization-server/api/proxy/api/mcp` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /.well-known/oauth-protected-resource` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /.well-known/oauth-protected-resource/api/mcp` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /.well-known/oauth-protected-resource/api/proxy/api/mcp` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /accept-invite/:id` | Browser landing pages for API-only instances. |
| `GET /api/actions/oidc/.well-known/openid-configuration` | Public OIDC discovery and RSA verification keys contain no credentials or tenant data. |
| `GET /api/actions/oidc/jwks` | Public OIDC discovery and RSA verification keys contain no credentials or tenant data. |
| `GET /api/actions/oidc/token` | Requires a purpose-bound job capability and rechecks running job, actor, approval, destination and id-token permission before issuing a five-minute identity. |
| `GET /api/actions/runtime/_apis/artifactcache/cache` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/_apis/artifactcache/caches` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `PATCH /api/actions/runtime/_apis/artifactcache/caches/:id` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/_apis/artifactcache/caches/:id` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `GET /api/actions/runtime/objects/:id` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `PUT /api/actions/runtime/objects/:id` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/CreateArtifact` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/DeleteArtifact` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/FinalizeArtifact` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/GetSignedArtifactURL` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.ArtifactService/ListArtifacts` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.CacheService/CreateCacheEntry` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.CacheService/FinalizeCacheEntryUpload` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /api/actions/runtime/twirp/github.actions.results.api.v1.CacheService/GetCacheEntryDownloadURL` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `GET /api/analytics/usage/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/auth/*` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/*` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/callback/github` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/cloud-callback` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/desktop-auth-poll` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/desktop-auth-start` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/desktop-claim` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/desktop-login` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/get-session` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/invitation-preview/:id` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/mcp/jwks` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/auth/mcp/userinfo` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/accept-invitation` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/cancel-invitation` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/invite-member` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/leave` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/reject-invitation` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/remove-member` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/organization/update-member-role` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/auth/sign-up/*` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/backup-restores/:restoreId/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/backup-runs/:runId/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/billing/actions/checkout` | Starts a prepaid browser payment. Complete payment in Actions → Budget when purchases are available. |
| `POST /api/billing/actions/checkout/resume` | Resumes the original prepaid browser checkout. Complete payment in Actions → Budget. |
| `GET /api/billing/actions/purchase` | Reconciles a browser payment with its verified provider receipt. Use Actions → Budget for payment recovery. |
| `POST /api/billing/cancel` | Paid subscription renewal is managed by the account owner in Settings → Billing; MCP exposes the resulting subscription state. |
| `GET /api/billing/checkout` | Browser checkout configuration; use the billing reads to inspect a plan and complete purchases in Settings → Billing. |
| `POST /api/billing/checkout/cancel` | Cancels an unfinished hosted payment and releases its capacity reservation. Financial actions are completed in Billing. |
| `POST /api/billing/checkout/resume` | Resumes a paid browser checkout using its original offer and identity. Complete payment in Billing. |
| `POST /api/billing/oblien-webhook` | Oblien webhook — verified via X-Webhook-Signature, not user session |
| `GET /api/billing/plans` | Public pricing endpoint — read by marketing site + signup flow before auth |
| `POST /api/billing/portal` | Creates an account billing-portal session. Open Settings → Billing to manage payment details. |
| `POST /api/billing/resume` | Paid subscription renewal is managed by the account owner in Settings → Billing; MCP exposes the resulting subscription state. |
| `POST /api/billing/subscription` | Starts a paid browser checkout. Purchases and payment authorization are completed in Settings → Billing. |
| `POST /api/billing/subscription/change` | Confirms a paid subscription change and server restart. Payment authorization and restart consent are completed in Billing. |
| `POST /api/billing/subscription/change/cancel` | Cancel a pending financial change in Billing; MCP exposes its resulting status. |
| `POST /api/billing/topup` | Starts a paid browser checkout. Buy credits in Settings → Billing; MCP can list pack prices and current balance. |
| `POST /api/billing/webhook/stripe` | Retired Stripe endpoint — always 410, no billing mutations |
| `GET /api/cloud/account` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/analytics` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/connect-authorize` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/connect-finalize` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/connect-handoff` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/connect-poll` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/desktop-handoff` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/disconnect` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/edge-proxy` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/edge-proxy/delete` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/edge-proxy/verify` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/edge-proxy/verify-check` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/exchange-code` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/export-subgraph` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/github/install-callback` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/github/install-url` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/github/installation-token` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/github/installations` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/github/oauth-bridge` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/github/oauth-handoff` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/github/oauth-success` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/github/user-status` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/ingest-subgraph` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/pages` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/pages/delete` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/pages/disable` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/pages/enable` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/preflight` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/promote-project` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/resource-proxy` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/route-registry` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/send-invitation` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `GET /api/cloud/server-deletions/:id` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/servers/:id/activity` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/servers/:id/activity/release` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/servers/:id/authorize` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/servers/:id/connection` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/support` | Public Cloud support intake, including customers who cannot sign in. Only returns a receipt; no ticket data can be read anonymously. |
| `GET /api/cloud/support/mine` | Private Cloud account support. Requires a real user session; local installations use the caller's own verified Cloud link. Cloud enforces ticket ownership and message quotas. Organization grants, another member's link and API tokens do not grant access. |
| `POST /api/cloud/support/mine` | Private Cloud account support. Requires a real user session; local installations use the caller's own verified Cloud link. Cloud enforces ticket ownership and message quotas. Organization grants, another member's link and API tokens do not grant access. |
| `GET /api/cloud/support/mine/:id` | Private Cloud account support. Requires a real user session; local installations use the caller's own verified Cloud link. Cloud enforces ticket ownership and message quotas. Organization grants, another member's link and API tokens do not grant access. |
| `PATCH /api/cloud/support/mine/:id` | Private Cloud account support. Requires a real user session; local installations use the caller's own verified Cloud link. Cloud enforces ticket ownership and message quotas. Organization grants, another member's link and API tokens do not grant access. |
| `POST /api/cloud/support/mine/:id/replies` | Private Cloud account support. Requires a real user session; local installations use the caller's own verified Cloud link. Cloud enforces ticket ownership and message quotas. Organization grants, another member's link and API tokens do not grant access. |
| `GET /api/cloud/support/session` | Private Cloud account support. Requires a real user session; local installations use the caller's own verified Cloud link. Cloud enforces ticket ownership and message quotas. Organization grants, another member's link and API tokens do not grant access. |
| `GET /api/cloud/support/tickets` | Cloud support operator API. Requires the instance's internal token; never available to customer organization owners. |
| `GET /api/cloud/support/tickets/:id` | Cloud support operator API. Requires the instance's internal token; never available to customer organization owners. |
| `PATCH /api/cloud/support/tickets/:id` | Cloud support operator API. Requires the instance's internal token; never available to customer organization owners. |
| `POST /api/cloud/support/tickets/:id/replies` | Cloud support operator API. Requires the instance's internal token; never available to customer organization owners. |
| `POST /api/cloud/support/tickets/:id/retry` | Cloud support operator API. Requires the instance's internal token; never available to customer organization owners. |
| `POST /api/cloud/teardown-project` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/cloud/telemetry` | Optional hosted dashboard product telemetry; validates the exact Origin and associates only verified cookie sessions. Not an SDK/MCP operation. |
| `POST /api/cloud/token` | Internal Cloud relay or browser credential handoff. Use the authenticated project, domain, GitHub, analytics and Cloud status tools instead. |
| `POST /api/deployments/:id/build` | Legacy start-by-deployment-ID adapter. Start or redeploy through /api/deployments or /api/deployments/build/access. |
| `GET /api/deployments/:id/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/deployments/ssl/renew` | Legacy hostname renewal; use POST /api/domains/:id/renew for managed domain identity and ownership. |
| `POST /api/deployments/ssl/status` | Legacy hostname probe; use the managed domain detail/status tools for scoped routing and certificate evidence. |
| `POST /api/diagnostics/client-errors` | Browser error intake; no user operation or data access. |
| `POST /api/domains/:id/verify/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/github/connect/redirect` | GitHub OAuth callback - no session yet during redirect |
| `POST /api/github/disconnect` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `POST /api/github/installations/claim` | The browser completes GitHub authorization and selects an installation. Use connect/status to start and inspect the connection. |
| `POST /api/github/instance-token` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `POST /api/github/repos` | GitHub repository creation is outside deployment management. Create repositories through GitHub, then deploy with Openship. |
| `DELETE /api/github/repos/:owner/:repo` | Deleting the upstream GitHub repository is outside deployment management. Openship project removal does not delete source repositories. |
| `GET /api/github/repos/:owner/:repo/clone-token` | Returns a bearer credential. MCP deploys and browses through permission-scoped GitHub tools without exporting installation tokens. |
| `GET /api/github/repos/:owner/:repo/tree` | Recursive dashboard access picker; MCP uses the path-scoped files tool for bounded repository browsing. |
| `DELETE /api/github/sources/:id` | GitHub App credentials and source ownership are managed by the workspace owner in Settings → GitHub. |
| `PATCH /api/github/sources/:id` | GitHub App credentials and source ownership are managed by the workspace owner in Settings → GitHub. |
| `POST /api/github/sources/:id/default` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `POST /api/github/sources/:id/install` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `POST /api/github/sources/manifest` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `POST /api/github/sources/manifest/convert` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `POST /api/github/sources/manual` | GitHub credential ownership and App installation are configured by the workspace owner in Settings → GitHub. Use connect/status for an existing supported connection flow. |
| `GET /api/health` | Public discovery or callback with its own HTTP authentication/transport. |
| `GET /api/health/env` | Public discovery or callback with its own HTTP authentication/transport. |
| `GET /api/images` | Image upload/download uses binary HTTP transport. |
| `GET /api/jobs/runs/:runId/stream` | Live SSE output can remain open. Poll GET /api/jobs/runs/:runId for captured output and completion over MCP. |
| `POST /api/mail/admin/:serverId/platform-mailbox/rotate` | Rotates the platform’s private mail-delivery credential. Use the mail-server settings; this is not a user mailbox. |
| `DELETE /api/mail/admin/:serverId/relay` | Changes server-wide delivery from relay to direct SMTP. Manage relay identity and removal together in the mail-server settings. |
| `POST /api/mail/admin/:serverId/relay` | Configures outbound delivery credentials and provider identity in the mail-server settings; MCP can inspect the resulting relay state. |
| `POST /api/mail/credentials/postmaster` | Privileged mail administrator credentials are changed in the authenticated mail settings. |
| `POST /api/mail/setup` | Mail installation is an interactive SSE wizard with DNS/PTR checkpoints. Open Emails → Set up mail; MCP can inspect status and administer or adopt existing installations. |
| `POST /api/mail/setup/cancel` | Controls the active browser mail-installation SSE session. Finish or cancel that setup in the Emails wizard. |
| `POST /api/mail/setup/dns-ack` | Acknowledges a checkpoint in the active mail-installation wizard. Use the Emails wizard; existing domain DNS has dedicated MCP tools. |
| `POST /api/mail/setup/ptr-ack` | Acknowledges provider PTR setup in the active mail-installation wizard. Use the Emails wizard to review the required reverse DNS. |
| `POST /api/mail/setup/reset` | Resets the mail-installation wizard’s on-host state. Use the Emails recovery flow; forgetting registration is available separately. |
| `POST /api/mail/webmail/deploy-external` | External mail-provider setup is a catalog/browser configuration flow. Use the catalog webmail app with its template inputs; managed mail-server webmail has a dedicated deploy tool. |
| `GET /api/mcp` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/mcp` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/migration/migrations/:id/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/migration/reveal-env` | Explicit dashboard secret reveal. Migration rediscovers real source environment server-side; MCP passes selected container IDs. |
| `GET /api/migration/scan/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/notices` | Platform status notices — non-sensitive operator announcements shown in the app banner |
| `POST /api/notices` | Operator status-notice push — internalAuth shared token |
| `DELETE /api/notices/:id` | Operator status-notice deactivate — internalAuth shared token |
| `GET /api/notices/all` | Operator notice listing (incl. inactive) — internalAuth shared token |
| `POST /api/permissions/create-team-org` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/grants` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `PUT /api/permissions/grants` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `DELETE /api/permissions/grants/:id` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/invitations/:id/accept` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/invitations/:id/cancel` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/invitations/:id/materialize` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/invitations/:id/reject` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/invitations/:id/resend` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `POST /api/permissions/invite-with-grants` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `DELETE /api/permissions/members/:id` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `PATCH /api/permissions/members/:id` | Membership, invitations and grants change account authority. Manage these in Settings → Team; MCP may inspect access but cannot mint or widen its own permissions. |
| `GET /api/projects/:id/clone-token` | Git credential management is kept in the authenticated dashboard; MCP deploys through the configured credentials. |
| `PATCH /api/projects/:id/clone-token` | Git credential management is kept in the authenticated dashboard; MCP deploys through the configured credentials. |
| `GET /api/projects/:id/cluster/databases/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/projects/:id/cluster/volumes/stream` | SSE transport for live volume status. Use the JSON list tool over MCP. |
| `POST /api/projects/:id/deployment-session` | Browser deployment-session handoff. MCP starts deployments through /api/deployments/build/access. |
| `GET /api/projects/:id/logs/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/projects/:id/resources` | Compatibility alias; use PATCH /api/projects/:id/resources. |
| `POST /api/projects/:id/routing/ensure-edge/respond` | Response to the browser’s ensure-edge SSE session. Use routing/retry and the project pending-actions tool for routing repair; interactive edge setup and proxy takeover remain in the dashboard. |
| `POST /api/projects/:id/routing/ensure-edge/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/projects/:id/routing/retry/stream` | Read-only SSE replay of an existing routing repair session. |
| `POST /api/projects/:id/routing/retry/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/projects/:id/server-logs/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/projects/:id/server-logs/stream-token` | Browser streaming credential. MCP reads the bounded server-logs endpoint with its own bearer. |
| `POST /api/projects/:id/services/:serviceId/env-reveal` | Explicit dashboard secret reveal. MCP reads masked effective environment and saves named overrides without retrieving plaintext. |
| `GET /api/projects/:id/services/:serviceId/logs/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/projects/folder/scan/:sessionId/env-reveal` | Explicit dashboard secret reveal. MCP passes uploadSessionId to project ensure so real values stay server-side. |
| `POST /api/projects/folder/upload/:sessionId` | Binary tarball upload; use the authenticated upload URL from folder/session outside JSON-RPC. |
| `POST /api/services/terminal/ticket` | Single-use browser WebSocket terminal ticket. Use the service exec tool for bounded commands over MCP. |
| `GET /api/services/terminal/ws/:serviceId` | WebSocket upgrade — auth happens inside upgradeWebSocket via ticket subprotocol or session-cookie fallback (HTTP middleware blocks the handshake) |
| `PUT /api/settings` | Compatibility settings update; use the dedicated build-mode tool for this preference. |
| `PATCH /api/settings/clone-credentials` | User-global Git clone credentials are configured in the authenticated dashboard; MCP deploys using those saved credentials. |
| `POST /api/system/bootstrap-admin` | CLI first-admin creation — internal-token gated, one-shot before any admin exists (openship setup) |
| `POST /api/system/cli-session` | CLI on the installation host — requires the private internal token, refuses Cloud and browser callers, and creates a temporary session for the existing instance administrator |
| `POST /api/system/cloud-connect` | CLI setup — finalize Openship Cloud PKCE handshake for a free domain; internal-token gated |
| `GET /api/system/cloud-status` | CLI setup — read Openship Cloud connection state; internal-token gated |
| `GET /api/system/clusters` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `POST /api/system/clusters` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `DELETE /api/system/clusters/:id` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `GET /api/system/clusters/:id` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `PATCH /api/system/clusters/:id` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `POST /api/system/clusters/:id/verify` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `GET /api/system/clusters/capabilities` | Compatibility private-network API. Use /api/system/networks; compute clusters live at /api/system/compute-clusters. |
| `DELETE /api/system/clusters/network-operations/:operationId` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `GET /api/system/clusters/network-operations/:operationId` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `POST /api/system/clusters/network-operations/:operationId/apply` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `DELETE /api/system/clusters/network-operations/:operationId/members/:serverId` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `GET /api/system/clusters/network-operations/:operationId/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/system/clusters/network-plans` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `GET /api/system/clusters/network-preparations` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `POST /api/system/clusters/network-preparations` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `DELETE /api/system/clusters/network-preparations/:preparationId` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `GET /api/system/clusters/network-preparations/:preparationId` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `PATCH /api/system/clusters/network-preparations/:preparationId/connections` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `DELETE /api/system/clusters/network-preparations/:preparationId/members/:serverId` | Compatibility alias for /api/system/networks; use the canonical network tools. |
| `GET /api/system/clusters/network-preparations/:preparationId/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/clusters/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/compute-clusters/:id/runtime/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/compute-clusters/:id/storage/stream` | SSE progress transport; read the JSON storage status through MCP. |
| `PUT /api/system/data-transfer/direct/chunk/:sessionId/:index` | Accepts one bounded, encrypted, signed direct-transfer chunk. |
| `POST /api/system/data-transfer/direct/chunk/:sessionId/finalize/stream` | Keeps an authenticated direct-transfer restore alive through proxy timeouts. |
| `POST /api/system/data-transfer/direct/chunk/:sessionId/heartbeat` | Extends an authenticated in-progress direct-transfer lease. |
| `POST /api/system/data-transfer/direct/chunk/init` | Initializes an encrypted upload using the one-time receive capability. |
| `POST /api/system/data-transfer/direct/receive` | One-time instance receive capability — payload is ECDH-encrypted and authorized by the expiring token inside it. |
| `POST /api/system/data-transfer/direct/send` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/data-transfer/direct/send/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/system/data-transfer/direct/session` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/data-transfer/export` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/data-transfer/import` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/data-transfer/import/session` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `PUT /api/system/data-transfer/import/session/:sessionId/chunk/:index` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/data-transfer/import/session/:sessionId/finalize/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/system/data-transfer/import/session/:sessionId/preview` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `GET /api/system/data-transfer/preview` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/data-transfer/preview` | Instance archive import/export transfers binary data and credentials as an operator recovery workflow. Use Settings → Data transfer; application migration and volume backups have dedicated MCP tools. |
| `POST /api/system/edge/import-sites` | CLI `openship up` (compose) — register sites migrated from a foreign proxy into the container edge (host stops the proxy pre-up; api re-serves via DockerEdgeExecutor); internal-token gated |
| `GET /api/system/health` | CLI `openship doctor` — internal-token gated deep health rollup (DB liveness/migrations + project/service counts); the public /api/health is only a liveness stub |
| `GET /api/system/install/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/system/install/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/instance` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/bootstrap` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/cancel` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/connect` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/connect-address` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/disconnect` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `GET /api/system/instance/identity` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/move` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/move-previous` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/offer` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/pair` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/pair/claim` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/peer/:id/:action` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `GET /api/system/instance/peer/:id/chunks/:index` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `PUT /api/system/instance/peer/:id/chunks/:index` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/preflight` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/provision` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/resume` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/instance/return` | Instance relocation requires an administrator's reviewed handoff in Settings → Instance. |
| `POST /api/system/invite-signup` | Self-host invited signup — authorized by the unguessable invitation id (token) in the emailed link, NOT a session; creates the account for the invitation's own email. |
| `POST /api/system/migration/preflight` | Instance control-plane/team-mode migration uses a browser session and changes the instance identity. Use Settings → Instance → Instance location; application migration has dedicated /api/migration MCP tools. |
| `POST /api/system/migration/start` | Instance control-plane/team-mode migration uses a browser session and changes the instance identity. Use Settings → Instance → Instance location; application migration has dedicated /api/migration MCP tools. |
| `POST /api/system/migration/start-cloud` | Instance control-plane/team-mode migration uses a browser session and changes the instance identity. Use Settings → Instance → Instance location; application migration has dedicated /api/migration MCP tools. |
| `POST /api/system/migration/start-tunnel` | Instance control-plane/team-mode migration uses a browser session and changes the instance identity. Use Settings → Instance → Instance location; application migration has dedicated /api/migration MCP tools. |
| `POST /api/system/migration/switch-back` | Instance control-plane/team-mode migration uses a browser session and changes the instance identity. Use Settings → Instance → Instance location; application migration has dedicated /api/migration MCP tools. |
| `GET /api/system/monitor/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/networks/operations/:operationId/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/networks/preparations/:preparationId/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/networks/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `GET /api/system/onboarding` | First-run onboarding status check - no user exists yet |
| `POST /api/system/onboarding` | First-run onboarding setup - creates initial admin user |
| `POST /api/system/onboarding/test-connection` | First-run SSH reachability test - no user exists yet; gated to no-servers instance |
| `POST /api/system/reset-admin-password` | CLI password recovery — internal-token gated; resets the local admin login for a locked-out operator (openship reset-admin-password) |
| `POST /api/system/self-edge/preflight` | CLI setup — detect what owns ports 80/443 before installing OpenResty; internal-token gated |
| `POST /api/system/self-register` | CLI setup — register the control plane as an app + attach its domain; internal-token gated |
| `GET /api/system/self-register/stream` | CLI setup — SSE progress for custom-domain edge provisioning; internal-token gated |
| `GET /api/system/servers/:id/containers/:component/apply/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `POST /api/system/servers/:id/containers/:component/apply/stream` | SSE transport for live progress. Use the resource’s JSON status/log tools over MCP, or an authenticated HTTP client for streaming. |
| `DELETE /api/system/servers/:id/github` | Disconnects the server-wide clone identity. Manage credential ownership in the server’s GitHub settings. |
| `PUT /api/system/servers/:id/github/deploy-key-mode` | Changes a deployment server’s GitHub credential mode. Configure tokens and deploy keys in the server’s GitHub settings. |
| `POST /api/system/servers/:id/github/ssh-key` | Changes a deployment server’s GitHub credential mode. Configure tokens and deploy keys in the server’s GitHub settings. |
| `PUT /api/system/servers/:id/github/token` | Changes a deployment server’s GitHub credential mode. Configure tokens and deploy keys in the server’s GitHub settings. |
| `DELETE /api/system/settings` | Instance reset/recovery is an operator workflow in Settings, not a tenant automation operation. |
| `PATCH /api/system/settings` | Instance identity and authentication settings are operator-controlled through Settings; workspace deployment preferences have dedicated MCP tools. |
| `PUT /api/system/settings/email` | Instance-wide email identity and credentials are configured by the instance administrator in Settings. |
| `POST /api/system/settings/email/test` | Instance email setup test sends to an arbitrary recipient; use the instance administrator’s Settings workflow. |
| `GET /api/system/setup` | Electron desktop client setup read - protected by internalAuth shared token |
| `POST /api/system/setup` | Electron desktop client setup - protected by internalAuth shared token |
| `POST /api/system/upgrade-to-auth` | Zero-auth upgrade flow — no session cookie exists for the synthetic local user. Handler enforces authMode === 'none' before mutating. |
| `POST /api/terminal/ticket` | Single-use browser WebSocket terminal ticket. Use the exec tool for bounded commands over MCP. |
| `GET /api/terminal/ws/:serverId` | WebSocket upgrade - auth happens inside upgradeWebSocket factory via single-use ticket (issued by POST /ticket under terminal:write) or session-cookie fallback; HTTP middleware would block the upgrade handshake |
| `GET /api/tokens` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/tokens` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `DELETE /api/tokens/:id` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/tokens/mcp-authorize` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/tokens/mcp-clients` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `DELETE /api/tokens/mcp-clients/:clientId` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /api/tokens/mcp-clients/:clientId` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `POST /api/webhooks/:provider` | Provider webhook (GitHub) - HMAC/signature verified in handler |
| `POST /api/webhooks/backup` | Backup webhook - bearer token in Authorization header is the credential |
| `POST /api/webhooks/incoming/:id` | Incoming webhook - per-hook token/HMAC/none credential verified in handler |
| `GET /auth/callback/close` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /auth/callback/install` | Authentication, credential issuance or MCP transport. These modules cannot become tools. |
| `GET /login` | Browser landing pages for API-only instances. |
| `POST /twirp/github.actions.results.api.v1.ArtifactService/CreateArtifact` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.ArtifactService/DeleteArtifact` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.ArtifactService/FinalizeArtifact` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.ArtifactService/GetSignedArtifactURL` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.ArtifactService/ListArtifacts` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.CacheService/CreateCacheEntry` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.CacheService/FinalizeCacheEntryUpload` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
| `POST /twirp/github.actions.results.api.v1.CacheService/GetCacheEntryDownloadURL` | Authenticates an expiring, purpose-bound Actions job capability and rechecks the saved actor and organization; user sessions and provider keys are not accepted. |
---
# Migration
URL: https://openship.io/docs/api/migration.md
Discover, adopt, and move services between servers.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Migration API brings workloads you deployed to a server by hand — Compose stacks and stray containers —
under Openship management. It inspects a server's Docker over SSH, returns the stacks it can adopt, and then
creates an Openship `services` project from the ones you pick. In the dashboard this is the **migration
wizard**; there is no CLI equivalent.
This module is mounted only when your instance runs in self-hosted mode — adopting a deployment requires SSH
into a server you manage, which Openship Cloud has no notion of. On a cloud instance these routes are not
mounted and return `404`.
## Scan a server
Read-only. Enumerates the server's Docker — Compose stacks plus hand-run containers — reconciles them with
any Compose files found on disk, and returns the discovered `stack` for the wizard to preview. Nothing on the
server changes.
```
POST /api/migration/scan
```
```bash
curl -X POST "$OPENSHIP_URL/api/migration/scan" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123"}'
```
On success the response is `{ "success": true, "stack": … }`, where `stack` describes the discovered Compose
stacks and containers that can be adopted.
## Adopt discovered services
Creates an Openship `services` project from the services you selected. The server is re-discovered
server-side (the server is the source of truth, not client-sent config), and existing named volumes are
reused in place — this records the project only; deploy and cutover are separate steps.
```
POST /api/migration/adopt
```
```bash
curl -X POST "$OPENSHIP_URL/api/migration/adopt" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123","projectName":"legacy-stack","serviceNames":["web","worker"]}'
```
On success the response is `{ "success": true, … }` with the created project's details.
## Run a reviewed migration
`POST /api/migration/migrate` starts the complete migration. Per-service options use the discovered
container IDs as keys; legacy service-name keys remain accepted. `routesByServiceName` accepts an array of
routes per service, preserving aliases, listen ports, path prefixes and exact matches. Environment values
are saved in the service's production environment scope.
A hostname can contain only explicit paths, such as `/api/` and an exact `/health`, without a
service at `/`. Migration preserves that selection as a project-owned route: matching requests
reach their selected services, and unmatched paths return `404`. An exact `/` match does not
become a catch-all. If an existing source catch-all is omitted, the run asks you to confirm
the selected paths or cancel and review them before creating project records or changing
source containers. Routing retries retain the previous complete table when any selected
service has no live upstream.
When routes are selected, migration prepares the target edge before changing source containers. If another
proxy must be replaced, the run waits for consent. Read `pendingPrompt` from
`GET /api/migration/migrations/:id` (also included in the stream snapshot), then answer it with:
```http
POST /api/migration/migrations/:id/respond
Content-Type: application/json
{"promptId":"","action":"migrate"}
```
Use an action ID from the current prompt. An expired, already answered or invalid prompt returns `409`.
Answering requires write access to both migration servers. Cancelling keeps the original proxy and source
containers intact. After attachment or deployment, Openship applies the owned routes and retries pending
domain verification; unresolved routing failures remain visible on the run.
## Errors
`serverId` is required on both routes; `adopt` additionally requires a non-empty `projectName` and at least
one entry in `serviceNames`. The response body names the missing field.
The `serverId` doesn't belong to your organization (or doesn't exist). List your servers with
[`openship server list`](/docs/cli/projects) to get valid IDs. On a cloud instance the module isn't mounted
at all, so every path here returns `404`.
Openship couldn't reach or inspect the server's Docker (SSH unreachable, Docker not running, permission
denied), or the adoption failed. The message includes the underlying reason. Confirm the server is online and
its Docker is accessible, then retry.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List the active organization's migration-only SSH connections. | `migrations.listSources()` Remote client | `GET /api/migration/sources` `server:read` |
| Verify and save a public SSH source with encrypted credentials and a pinned host key. Does not enable external Cloud deployment destinations. | `migrations.createSource(input)` Remote client | `POST /api/migration/sources` `server:write` |
| Test a public SSH source without saving it and return its host fingerprint. | `migrations.testSource(input)` Remote client | `POST /api/migration/sources/test` `server:write` |
| Inspect a server's Docker and return the adoptable stack — read-only, changes nothing. | `migrations.scan(input)` Remote client | `POST /api/migration/scan` `server:write` |
| Reveal explicitly requested environment values for an authorized import. | `migrations.revealEnv(input)` Remote client | `POST /api/migration/reveal-env` `server:write` |
| Read Compose configuration from a repository for import. | `migrations.repoCompose(input)` Remote client | `POST /api/migration/repo-compose` `server:read` |
| Create an Openship project from the selected discovered services. | `migrations.adopt(input)` Remote client | `POST /api/migration/adopt` `server:write` · Self-hosted |
| Refresh an imported project from its source. | `migrations.reimport(input)` Remote client | `POST /api/migration/reimport` `server:write` · Self-hosted |
| Preview a migration plan. | `migrations.preview(input)` Remote client | `POST /api/migration/preview` `server:write` |
| Start a server migration from the reviewed plan. | `migrations.start(input)` Remote client | `POST /api/migration/migrate` `server:write` |
| Import a discovered project. | `migrations.moveProject(input)` Remote client | `POST /api/migration/project` `server:write` |
| List active server migration sessions. | `migrations.active(input)` Remote client | `GET /api/migration/active` `server:read` |
| List migration history. | `migrations.listRuns(input)` Remote client | `GET /api/migration/runs` `server:read` |
| Disconnect an idle migration source without deleting its external server or workloads. | `migrations.removeSource(id)` Remote client | `DELETE /api/migration/sources/:serverId` `server:write` |
| Read migration progress and state. | `migrations.get(id)` Remote client | `GET /api/migration/migrations/:id` `server:read` |
| Switch traffic to the prepared migration target. | `migrations.cutover(id, input)` Remote client | `POST /api/migration/migrations/:id/cutover` `server:write` |
| Request cancellation of a migration. | `migrations.cancel(id)` Remote client | `POST /api/migration/migrations/:id/cancel` `server:write` |
| Answer a pending migration prompt, including edge takeover consent. | `migrations.respond(id, input)` Remote client | `POST /api/migration/migrations/:id/respond` `server:write` |
| Resume an interrupted migration. | `migrations.resume(id, input)` Remote client | `POST /api/migration/migrations/:id/resume` `server:write` |
| Clean up resources created on the migration target. | `migrations.cleanupTarget(id)` Remote client | `POST /api/migration/migrations/:id/cleanup-target` `server:write` |
| Delete an eligible migration record. | `migrations.remove(id)` Remote client | `DELETE /api/migration/migrations/:id` `server:write` |
| Stream migration progress. | `migrations.events(id, options?)` Remote client | `GET /api/migration/migrations/:id/stream` `server:read` |
| Stream server-discovery progress. | `migrations.scanEvents(input, options?)` Remote client | `GET /api/migration/scan/stream` `server:write` |
{/* api-operations:end */}
---
# Services
URL: https://openship.io/docs/api/services.md
Manage project services, containers, and environment variables.
import { TypeTable } from 'fumadocs-ui/components/type-table';
A **service** is one runnable unit inside a project: a container in a docker-compose stack, or a sub-app in
a monorepo. Both live in the same table (discriminated by `kind`), so this API covers listing and editing
services, syncing them from a `docker-compose` file, starting/stopping/restarting their containers,
resolving compose drift, and setting per-service environment variables. In the dashboard this is a project's
**Services** tab; from the terminal it's [`openship service`](/docs/cli/projects).
These operations are available with supported self-hosted and Cloud providers. A fixed organization
scope requires a direct compatible Cloud connection; see [Cloud compatibility](/docs/api/sdk/compatibility#cloud).
Service and deployment responses mask non-empty `buildArgs` values as `••••••••`, just like
`environment`. This also covers retained deployment snapshots and Compose drift previews. Empty strings
stay empty and `null` still means inherit from the build environment. On write, echoing a mask keeps
that key's stored value; a mask without a stored source is dropped. `buildArgs` remains a whole-map
replacement: omit a key to remove it, or send `{}` to clear the map.
For literal build args, responses also include `buildArgsFingerprints`, keyed by argument name. After
rotating a literal value, compare the fingerprint in the service write response with the same service's
fingerprint in deployment history (`meta.composeServices[]`) or build status (`composeServices[]`).
Equal fingerprints mean the stored literal values match; a rotation changes the fingerprint without
returning either value. They are HMAC-SHA256 values scoped to the project, service name and argument key,
so they cannot be computed offline or compared across services. Rotating the instance's auth secret
also changes them.
Fingerprints describe the stored build configuration, not a running container. Inherited (`null`) and
interpolated args have no fingerprint because their effective values depend on the build environment.
Snapshots remain intact internally for rollback; existing history is masked when read, without a migration.
Source scans also mask build arguments by default. An authorized editing scan with `includeEnv: true`
includes source values so the deploy form can edit them; it requires write access and, for GitHub sources,
permission to read the repository's full contents.
## Share a service between projects
A service can stay in its owning project and be connected to several other projects. This reuses the
existing instance and its data. In the dashboard, open the service and choose **Use in a project**, or
choose **Add service → Connect existing** from the consuming project's Services tab. Shared services
appear there with their source project; the owner can see which projects use each service.
Use the existing project connection API to create these links:
```ts
const { outputs } = await ship.projects.getAppConnection("source_project");
const output = outputs.find(item => item.sourceServiceId === "svc_database");
if (!output?.value) throw new Error("Configure and deploy the source database first.");
await ship.projects.connectBundle("consumer_project", {
sourceProjectId: "source_project",
items: [{ outputId: output.id, envKey: "DATABASE_URL" }],
mode: "internal",
});
```
The caller needs write access to both projects in the same organization. Private service connections
require Docker projects on the same server. Credentials are stored as secret environment variables and
refreshed from the source on normal consumer deployments. Disconnecting removes that project's link;
the source service and other consumers remain. Disconnect all consumers before deleting a shared service
or its owning project.
## Add a service
A service row is a union: `kind: "compose"` uses the container fields (image, build, ports…), while
`kind: "monorepo"` uses the sub-app build fields (rootDirectory, framework…). Both field sets are accepted
and optional; the `kind` decides which subset is the source of truth. Unknown keys are rejected.
```ts
const result = await ship.services.create("proj_123", {
name: "db",
kind: "compose",
image: "postgres:16",
ports: ["5432:5432"],
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/services" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"db","kind":"compose","image":"postgres:16","ports":["5432:5432"]}'
```
**Compose fields** (used when `kind` is `compose`):
', description: 'Compose environment defaults baked into the service. On update this map is merged, not replaced, and accepts nulls — see Update a service.' },
volumes: { type: 'string[]', description: 'Volume mappings (max 50 entries, each ≤500 chars).' },
command: { type: 'string', description: 'Override the container command (max 1000).' },
advanced: { type: 'object', description: 'Extended Compose settings, including healthcheck, readiness and extraHosts (hostname to IPv4/IPv6 address or Docker host-gateway). Unknown keys are rejected; null removes an individual setting.' },
exposed: { type: 'boolean', description: 'Whether this service is publicly routed.' },
exposedPort: { type: 'string', description: 'Container port to expose publicly (max 50).' },
domain: { type: 'string', description: 'Free subdomain label for this service (max 255).' },
customDomain: { type: 'string', description: 'A custom domain to route to this service (max 255).' },
domainType: { type: '"free" | "custom"', description: 'Which kind of domain the service uses.' },
restart: { type: '"no" | "always" | "on-failure" | "unless-stopped"', description: 'Container restart policy.' },
enabled: { type: 'boolean', description: 'Whether the service is included in deploys.' },
sortOrder: { type: 'number', description: 'Display/ordering position (≥0).' },
}}
/>
**Monorepo sub-app fields** (used when `kind` is `monorepo`):
## Update a service
Every field is optional — send only what changes. Accepts the same compose and monorepo fields as create,
**except `kind`**: switching a row's kind is a destructive operation, so delete the service and re-create it
under the new kind instead.
Two fields are **merged** onto their stored value instead of replacing it — `environment` and `advanced`,
the endpoint's keyed maps:
| You send | Result |
| --- | --- |
| the key is absent | the stored value is kept |
| `{"KEY": "value"}` | that one key is set; every other key is untouched |
| `{"KEY": null}` | that one key is removed |
| `{"environment": null}` | every variable is removed |
| `{"environment": {}}` | nothing changes |
Env values read back masked as `••••••••` (`GET /:serviceId` never returns plaintext). Echo the sentinel to
keep a value unchanged, or send a real string to replace it. **Omitting a key never deletes it** — a delete
has to be spelled `null`. To read a value explicitly, use [reveal](#reveal-environment-values).
Every other field replaces its stored value wholesale, `ports`, `volumes`, `dependsOn` and
`publicEndpoints` included, so send the complete list for those.
```ts
const result = await ship.services.update("proj_123", "svc_456", {
restart: "unless-stopped",
enabled: true,
});
console.log(result);
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/projects/proj_123/services/svc_456" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"restart":"unless-stopped","enabled":true}'
```
## Sync from docker-compose
Explicitly replace Compose service configuration with the supplied parsed services, adding or updating
rows and removing services absent from the list. The CLI's `service sync` command reads and validates
the file before submitting this request. Ordinary redeploys automatically merge repo changes with
saved overrides; they do not require this replacement operation.
```
POST /api/projects/:id/services/sync
```
## Resolve compose drift
These endpoints resolve pending reviews saved by older versions. Routine redeploys now preserve
explicit overrides and automatically apply other source changes, clearing old review records.
Accepting a legacy review applies source configuration while preserving saved environment values.
```
POST /api/projects/:id/services/:serviceId/drift/accept # accept source config, preserve saved env
POST /api/projects/:id/services/:serviceId/drift/keep # keep your edits, stop flagging
```
## Container actions
```ts
await ship.services.restart("proj_123", "svc_123");
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/services/svc_123/restart" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Start, stop, or restart the running container for a single service. These act on the service's
active-deployment container.
```
POST /api/projects/:id/services/:serviceId/start
POST /api/projects/:id/services/:serviceId/stop
POST /api/projects/:id/services/:serviceId/restart
```
Use `GET /api/projects/:id/services/containers` (`openship service containers -p my-stack`) to list the
running containers across the whole stack.
## Environment variables
`GET .../environment` returns the effective saved configuration: shared project
values, Compose values and service overrides. Each row has a source, and secrets
are masked. It defaults to the active deployment's environment, or production
before the first deployment. Add `inspectRuntime=true` to compare with the owned
Docker container; a failed inspection leaves the saved variables in the response.
```ts
const state = await ship.services.getEnvironment("proj_123", "svc_456", {
inspectRuntime: true,
});
console.log(state.status, state.changedKeys);
```
Use `PATCH .../env` for partial edits. Send only changed overrides in `upserts`,
and explicit removals in `deletes`. Existing overrides require their `sourceId`
from the read; `null` means creating an override. Stale IDs return
`ENVIRONMENT_CHANGED` without applying the request.
```ts
const currentEnvironment = await ship.services.getEnvironment("proj_123", "svc_456");
await ship.services.mergeEnvVars("proj_123", "svc_456", {
environment: currentEnvironment.environment,
upserts: [{
key: "LOG_LEVEL",
value: "info",
sourceId: currentEnvironment.variables.find(row => row.key === "LOG_LEVEL")?.sourceId ?? null,
}],
deletes: [],
});
```
`GET .../env` lists only service override rows (secret values masked).
`PUT .../env` **replaces** those overrides for one environment — send every
override you want to keep. Neither endpoint represents the inherited Compose or
shared project layers.
```
GET /api/projects/:id/services/:serviceId/env
PUT /api/projects/:id/services/:serviceId/env
GET /api/projects/:id/services/:serviceId/environment
PATCH /api/projects/:id/services/:serviceId/env
```
```ts
const result = await ship.services.setEnvVars("proj_123", "svc_456", {
environment: "production",
vars: [
{
key: "DATABASE_URL",
value: "postgres://…",
isSecret: true,
},
],
});
console.log(result);
```
```bash
curl -X PUT "$OPENSHIP_URL/api/projects/proj_123/services/svc_456/env" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"environment":"production","vars":[{"key":"DATABASE_URL","value":"postgres://…","isSecret":true}]}'
```
', description: 'The full set of vars (0–100). key 1–256 chars, value ≤10000, isSecret defaults to false.', required: true },
}}
/>
`PUT .../env` overwrites the service override set with exactly what you send.
Use `PATCH .../env` when changing individual values so unrelated overrides remain intact.
### Reveal environment values
Add `source: "effective"` to reveal named values from the complete saved view.
For recovery, use `source: "runtime"` with the `containerId` returned by runtime
inspection and names from `recoverableKeys`. Recovery excludes image defaults
and keys already saved in Openship. It returns values without persisting them;
save the selected recovered values with `mergeEnvVars`. A changed container
returns `ENVIRONMENT_RUNTIME_CHANGED`.
The dashboard uses one environment editor. Imported Compose values are visible immediately; **Demo mode**
blurs them like IP addresses. Saved values start masked, and clicking a row's eye reveals only that value.
**Show values** is the explicit action for revealing all saved rows. Revealing does not save or overwrite
configuration.
SDK and REST requests name 1–500 keys, each up to 512 characters. Only requested keys that exist are
returned. Reading masked configuration does not grant permission to reveal it.
```ts
const environment = await ship.services.revealEnv("proj_123", "svc_456", {
keys: ["POSTGRES_PASSWORD"],
});
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/services/svc_456/env-reveal" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"keys":["POSTGRES_PASSWORD"]}'
```
The returned values are under `environment`.
This reads saved Compose configuration and requires service write access. Add
`environment: "production"`, `"preview"`, or `"development"` to read the service's variables for that
environment instead.
For an import editor, request values with the initial scan. This avoids a second source read when the
editor opens:
| Source | SDK | REST API |
| --- | --- | --- |
| Git or local scan | `deployments.prepare({ ...prepareInput, includeEnv: true })` | `POST /api/deployments/prepare` with `includeEnv: true` |
| Uploaded snapshot | `sources.scan("session_123", { includeEnv: true })` | `POST /api/projects/folder/scan/session_123` with `{ "includeEnv": true }` |
| Local directory | `projects.scanLocal({ path: "/srv/app", includeEnv: true })` | `POST /api/projects/scan` with the same body |
Ordinary scans remain masked. `includeEnv: true` requires the scan's write permission and, for Git,
whole-repository content read access. Local paths are self-hosted only. Demo mode only changes the browser
display; it does not change API permissions or returned values.
## Errors
The payload failed validation (unknown key, wrong type, or a value over its length limit). Unknown keys are
rejected outright — check field names against the tables above. On create, a `kind: "monorepo"` service must
carry a `rootDirectory`.
The `:serviceId` doesn't belong to this project (or was deleted), or the project `:id` isn't in your
organization. List the project's services with `GET /api/projects/:id/services` to get valid ids.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Stream log events for a service. | `services.streamLogs(projectId, serviceId, input?, options?)` | `GET /api/projects/:id/services/:serviceId/logs/stream` `project:service:read` |
| List services belonging to a project. | `services.list(id)` | `GET /api/projects/:id/services` `project:service:list` |
| Add a service definition to a project. | `services.create(id, input)` | `POST /api/projects/:id/services` `project:service:write` |
| Synchronize service definitions from Compose source. | `services.sync(id, input)` | `POST /api/projects/:id/services/sync` `project:service:write` |
| List active project containers. | `services.activeContainers(id)` | `GET /api/projects/:id/services/containers` `project:read` |
| Read one service definition and state. | `services.get(parentId, id)` | `GET /api/projects/:id/services/:serviceId` `project:service:read` |
| Update service configuration. | `services.update(parentId, id, input)` | `PATCH /api/projects/:id/services/:serviceId` `project:service:write` |
| Remove a service and its selected resources. | `services.remove(parentId, id)` | `DELETE /api/projects/:id/services/:serviceId` `project:service:admin` |
| Accept a legacy source review while preserving saved environment values. | `services.acceptDrift(parentId, id)` | `POST /api/projects/:id/services/:serviceId/drift/accept` `project:service:write` |
| Keep the current configuration when resolving drift. | `services.keepDrift(parentId, id)` | `POST /api/projects/:id/services/:serviceId/drift/keep` `project:service:write` |
| Read the effective saved service environment and optionally compare it with Docker. | `services.getEnvironment(parentId, id, input?)` | `GET /api/projects/:id/services/:serviceId/environment` `project:service:read` |
| Save named service overrides without replacing unrelated values. | `services.mergeEnvVars(parentId, id, input)` | `PATCH /api/projects/:id/services/:serviceId/env` `project:service:write` |
| Read service environment overrides with masked secrets. | `services.listEnvVars(parentId, id, input?)` | `GET /api/projects/:id/services/:serviceId/env` `project:service:read` |
| Apply service environment variable changes. | `services.setEnvVars(parentId, id, input)` | `PUT /api/projects/:id/services/:serviceId/env` `project:service:write` |
| Reveal authorized service environment values. | `services.revealEnv(parentId, id, input)` | `POST /api/projects/:id/services/:serviceId/env-reveal` `project:service:write` |
| Apply saved runtime environment by replacing the service container using its current image, without a build. | `services.applyEnvironment(parentId, id)` | `POST /api/projects/:id/services/:serviceId/apply-env` `project:service:write` |
| Read persistent-volume sizes for the service. | `services.volumeSizes(parentId, id)` | `GET /api/projects/:id/services/:serviceId/volume-sizes` `project:service:read` |
| Start the service runtime. | `services.start(parentId, id)` | `POST /api/projects/:id/services/:serviceId/start` `project:service:write` |
| Stop the service runtime. | `services.stop(parentId, id)` | `POST /api/projects/:id/services/:serviceId/stop` `project:service:write` |
| Restart the service runtime. | `services.restart(parentId, id, input?)` | `POST /api/projects/:id/services/:serviceId/restart` `project:service:write` |
| Read recent service runtime logs. | `services.runtimeLogs(parentId, id, input?)` | `GET /api/projects/:id/services/:serviceId/logs` `project:service:read` |
| Execute an authorized command in the service runtime. | `services.exec(parentId, id, input)` | `POST /api/projects/:id/services/:serviceId/exec` `project:service:write` |
{/* api-operations:end */}
---
# Audit log
URL: https://openship.io/docs/api/audit.md
Read and filter organization activity.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Audit API is a read-only feed of the append-only audit log for your active organization: an event per
significant action (logins, member changes, deployments, settings edits, and more), newest first. In the
dashboard this is the **Audit** page; there's no dedicated CLI command — reach it through
[`openship api`](/docs/cli/access).
## List audit events
Every event is scoped to your active organization. Access is gated by role: owners and admins always see the
log, plain members are denied, and restricted users need an explicit `audit:read` grant on the org-level
`audit` resource. See [permissions & roles](/docs/security/auth).
### Query parameters
All parameters are optional. Choose **one** pagination mode: pass `cursor` (keyset) *or* `page`/`perPage`
(offset). Cursor mode is recommended for anything that streams pages — it survives concurrent writes without
shifting rows; page mode powers the dashboard's "Showing 1–50 of N" count.
```ts
const result = await ship.audit.list();
console.log(result);
```
```bash
# Cursor mode — newest 50 deployment-failure events
curl -G "$OPENSHIP_URL/api/audit" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
--data-urlencode "cursor=" \
--data-urlencode "limit=50" \
--data-urlencode "eventType=deployment.failed"
```
### Response
Each event row carries `id`, `eventType`, `resourceType`, `resourceId`, `before`/`after` JSON snapshots
(mutation events only; otherwise null), `ipAddress`, `userAgent`, and `createdAt`. Rows are enriched with an
`actor` object (`{ id, email, name }`) resolved from `actorUserId`, or `null` for system-emitted events.
The pagination envelope depends on the mode:
- **Cursor mode** → `{ data, pageInfo: { hasNextPage, endCursor } }`. Pass `endCursor` back as `cursor` for
the next page; there is no `total`.
- **Offset mode** → `{ data, total, page, perPage }`.
## Errors
Your role can't read the audit log. Members are denied by default; ask an owner/admin to grant `audit:read`
on the org's `audit` resource, or view the log from an admin account. See
[permissions & roles](/docs/security/auth).
Filters that match nothing return `200` with an empty `data` array. Double-check `eventType` spelling
(it's the exact dot-namespaced tag) and that `resourceId` belongs to your organization. Retention is
org-configurable (default 90 days), so events older than the window are pruned and won't appear.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Read filtered, paginated audit events. | `audit.list(input?)` | `GET /api/audit` `audit:read` |
| Read available audit filter values. | `audit.facets(input?)` | `GET /api/audit/facets` `audit:read` |
| Read audit retention settings. | `audit.getSettings()` | `GET /api/audit/settings` `audit:read` |
| Change audit retention settings. | `audit.updateSettings(input)` | `PATCH /api/audit/settings` `audit:write` |
{/* api-operations:end */}
---
# Jobs
URL: https://openship.io/docs/api/jobs.md
Create command jobs, run them, and inspect schedules and results.
A job runs a command on one or more authorized servers. Jobs can run manually, on a cron schedule, once
at a specified time, or in response to configured events. Self-hosted jobs target connected servers;
Cloud jobs target the organization's managed servers, using the same operations and scheduler.
Job methods take the job's **`key`**. Run methods take a **run ID**. Writing a command job also requires
administration access to every target server. The same target permission protects configuration,
run history and output. Cloud does not expose internal system jobs, even to customer administrators.
Cloud users can share a managed server with projects or create a dedicated server with its own
subscription. Commands use that server's capacity and usage allowance. An active subscription,
available balance and a running server are required; executing a job never provisions a server.
Manual billing refusals return `CLOUD_BILLING_BLOCKED` with the target `workspaceId` and `serverId`.
Scheduled attempts record failures in their run history.
## Create a command job
```ts
const job = await ship.jobs.create({
label: "Check Node version",
serverId: "srv_123",
command: "node --version",
scheduleType: "manual",
timeoutMs: 10_000,
});
console.log(job.key);
```
```bash
curl -X POST "$OPENSHIP_URL/api/jobs" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"label":"Check Node version","serverId":"srv_123","command":"node --version","scheduleType":"manual","timeoutMs":10000}'
```
| Field | Type | Use |
| --- | --- | --- |
| `label` | `string` | Required; 1–120 characters. |
| `command` | `string` | Required; command to execute, at most 10,000 characters. |
| `serverId` / `serverIds` | `string` / `string[]` | Target server or up to 50 servers. |
| `scheduleType` | `manual`, `recurring`, or `once` | Choose how the job is scheduled. |
| `cronExpression` | `string` | Cron expression for a recurring job. |
| `runAt` | `string` | ISO timestamp with a timezone for a one-time job. |
| `timeoutMs` | `number` | Execution timeout, 1,000–86,400,000 ms. |
| `retry` | `object` | `maxAttempts` (1–10) and `backoffSeconds` (0–3,600). |
| `env` / `secrets` | `Record` | Environment values; secrets are encrypted and masked in reads. |
| `dependsOn` | `string[]` | Up to 50 prerequisite job keys. |
| `triggerEvents` | `string[]` | Up to 50 event IDs from `triggerEvents()`. |
| `notifyConfig` | `object` | Channel IDs and states: `running`, `success`, or `failed`. |
`update(key, input)` accepts partial configuration plus `enabled`. System jobs only accept
`cronExpression` and `enabled`, and cannot be removed. Secret updates replace the supplied secret map.
## Run and inspect
```ts
const submitted = await ship.jobs.run("job_key");
console.log(submitted.runId, submitted.summary);
```
```bash
curl -X POST "$OPENSHIP_URL/api/jobs/job_key/run" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Submission can return a `runId` or an immediate summary. Use `getRun(runId)` to inspect execution status,
attempt, output, errors, and timing. `listRuns(key, { limit })` returns history; `limit` is 1–1,000.
```ts
for await (const event of ship.jobs.streamRun("run_123")) {
console.log(event);
}
```
```bash
curl -N "$OPENSHIP_URL/api/jobs/runs/run_123/stream" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Native scheduling
An owned native installation does not start scheduling by default. Set `jobs: { enabled: true }` in its
startup configuration only when it should own that work. Running one job manually and enabling recurring
scheduling are separate actions. See [background work limits](/docs/api/sdk/compatibility#current-limits).
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Stream live output from a job run. | `jobs.streamRun(id, options?)` | `GET /api/jobs/runs/:runId/stream` `job:read` |
| List available system and custom jobs. | `jobs.list()` | `GET /api/jobs` `job:read` |
| Create a custom command job with schedule and target configuration. | `jobs.create(input)` | `POST /api/jobs` `job:write` |
| List events that can trigger custom jobs. | `jobs.triggerEvents()` | `GET /api/jobs/trigger-events` `job:read` |
| Read scheduled backup policies alongside jobs. | `jobs.backupSchedules()` | `GET /api/jobs/backup-schedules` `job:read` |
| Read a job’s configuration and recent runs. | `jobs.get(id)` | `GET /api/jobs/:key` `job:read` |
| Change a schedule or custom job configuration. | `jobs.update(id, input)` | `PATCH /api/jobs/:key` `job:write` |
| Delete a custom job; system jobs can be disabled instead. | `jobs.remove(id)` | `DELETE /api/jobs/:key` `job:write` |
| Trigger a job immediately. | `jobs.run(id)` | `POST /api/jobs/:key/run` `job:write` |
| Read a job’s run history. | `jobs.listRuns(id, input?)` | `GET /api/jobs/:key/runs` `job:read` |
| Read a recorded run, result, and captured output. | `jobs.getRun(id)` | `GET /api/jobs/runs/:runId` `job:read` |
{/* api-operations:end */}
---
# Health
URL: https://openship.io/docs/api/health.md
Check installation availability and SDK protocol support.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Health API is how anything outside Openship checks that an instance is alive and learns how it's set
up — its version, auth mode, and which cloud (if any) it targets. Load balancers and Docker health checks
hit `GET /api/health`; the CLI and dashboard read `GET /api/health/env` to decide which login flow to show.
From the terminal it's the [`openship status`](/docs/cli/run) command. Both routes are available on every
instance (self-hosted, desktop, and cloud).
## Liveness probe
```
GET /api/health
```
Returns `200` with a fixed body as long as the process is serving requests. Use it as a container or
load-balancer health check — it touches no database and never requires auth.
```bash
curl "$OPENSHIP_URL/api/health"
# → {"status":"ok","timestamp":"2026-07-19T04:29:00.000Z"}
```
## Deployment info
Static, cache-friendly description of how the instance is configured. Clients read this to pick the right
login flow and to reach the correct cloud endpoints — the dashboard uses these values rather than a
hard-coded table. Reads that depend on the database (`teamMode`, migration fields) fall back to safe
defaults if the settings table is unavailable mid-migration, so this route stays up.
The response shape:
```ts
const result = await ship.system.info();
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/health/env"
```
## Errors
These routes never return an auth or permission error — a failure means the process isn't reachable
(wrong host/port, container still starting, or the instance is down). `openship status` reports this as
`Cannot reach the API at `. Confirm the instance is running and the URL is correct, then retry.
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Read installation and deployment-mode information. | `system.info()` | `GET /api/health/env` `Public` |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Liveness probe — returns `{ status, timestamp }`. | HTTP only | `GET /api/health` `Public` |
{/* api-operations:end */}
---
# Backup destinations
URL: https://openship.io/docs/api/backup-destinations.md
Configure and verify storage for backups.
import { TypeTable } from 'fumadocs-ui/components/type-table';
A backup destination is a reusable storage target — an S3-compatible bucket, an SFTP server, a local
filesystem path, or another Openship server — that [backup policies](/docs/api/backups) write their archives
to. This API creates and manages those targets and runs a **preflight** that proves a destination is
actually reachable (it writes, reads back, and deletes a probe object). Credentials are encrypted at rest;
serialized destinations never return secret values, only `hasX` flags showing which are configured.
This module is available on both self-hosted and cloud instances. The `local` destination kind is
self-hosted only — it is rejected in cloud mode and, on self-hosted, must be explicitly enabled (see below).
## Create a destination
```ts
const result = await ship.backupDestinations.create({
name: "prod-s3",
kind: "s3_compatible",
bucket: "my-backups",
region: "us-east-1",
accessKeyId: "AKIA...",
secretAccessKey: "...",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/backup-destinations" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"prod-s3","kind":"s3_compatible","bucket":"my-backups","region":"us-east-1","accessKeyId":"AKIA...","secretAccessKey":"..."}'
```
Required fields depend on `kind`:
- **`s3_compatible`** — `bucket`, `accessKeyId`, and `secretAccessKey`.
- **`sftp`** — `sshHost`, `sshUser`, and one of `sftpPassword` / `sftpPrivateKey`.
- **`openship_server`** — `serverId` (a server in your org).
- **`local`** — `endpoint` (an absolute path inside `BACKUP_LOCAL_ROOT`).
## Update a destination
Send only the fields you want to change. For credentials, `undefined` (omitted) leaves the stored value
unchanged, `null` clears it, and a string replaces it. The `kind` cannot be changed after creation.
```ts
const result = await ship.backupDestinations.update("bkd_123", {
pathPrefix: "nightly/",
isDefault: true,
});
console.log(result);
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/backup-destinations/bkd_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"pathPrefix":"nightly/","isDefault":true}'
```
## Preflight (verify connectivity)
Proves the destination works by writing, reading back, and deleting a small probe object. On success it
stamps `lastVerifiedAt`; on failure it records the error in `lastVerifyError`.
```ts
const result = await ship.backupDestinations.preflight("bkd_123");
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/backup-destinations/bkd_123/preflight" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Preflight returns `200` with `{"ok": false, "reason": "..."}` when the target is unreachable or
misconfigured — the reason (bad credentials, DNS failure, permission denied) is in the body, not the HTTP
status. A `404` here means the `:id` doesn't belong to your organization.
## Errors
The body is missing a field required for its `kind` (e.g. an S3 destination without a `bucket` or
credentials), the `name` is blank / over 80 chars or duplicates an existing destination, or you passed an
unsupported `kind`. `http_upload` is defined but not yet supported.
A `local` destination requires `BACKUP_ALLOW_LOCAL_DESTINATION=true` and a configured `BACKUP_LOCAL_ROOT`,
and the `endpoint` must resolve to an absolute path inside that root. Both the root and the endpoint are
symlink-resolved before the check, so a symlink that escapes the root is rejected. `BACKUP_LOCAL_ROOT`
itself must be a dedicated directory — not `/`, `/var`, `/var/lib`, Openship's own state directory, or
anything inside a system tree such as `/etc` or `/var/lib/docker`. Local destinations are always rejected
in cloud mode.
The `:id` doesn't belong to your organization (or was deleted). List your destinations with
`GET /api/backup-destinations` to get valid IDs.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List backup storage destinations. | `backupDestinations.list()` | `GET /api/backup-destinations` `backup_destination:list` |
| Create a backup destination. | `backupDestinations.create(input)` | `POST /api/backup-destinations` `backup_destination:write` |
| Test destination configuration before saving it. | `backupDestinations.preflightDraft(input)` | `POST /api/backup-destinations/preflight` `backup_destination:write` |
| List backup history across storage destinations. | `backupDestinations.history(input?)` | `GET /api/backup-destinations/history` `backup_destination:list` |
| List backup runs stored in one destination. | `backupDestinations.runs(id, input?)` | `GET /api/backup-destinations/:id/runs` `backup_destination:read` |
| Read a destination with credentials protected. | `backupDestinations.get(id)` | `GET /api/backup-destinations/:id` `backup_destination:read` |
| Read destination storage usage. | `backupDestinations.usage(id)` | `GET /api/backup-destinations/:id/usage` `backup_destination:read` |
| Update destination settings. | `backupDestinations.update(id, input)` | `PATCH /api/backup-destinations/:id` `backup_destination:write` |
| Remove an eligible destination. | `backupDestinations.remove(id)` | `DELETE /api/backup-destinations/:id` `backup_destination:admin` |
| Test a saved destination and record its verification state. | `backupDestinations.preflight(id)` | `POST /api/backup-destinations/:id/preflight` `backup_destination:write` |
{/* api-operations:end */}
---
# Data transfer
URL: https://openship.io/docs/api/data-transfer.md
Export, review, and import installation or project data.
import { TypeTable } from 'fumadocs-ui/components/type-table';
## Instance location
Use **Settings → Instance → Instance location** to move an entire controller between Desktop and a
server. `/api/system/instance/*` uses one durable handoff in both directions: pause and drain the
source, verify the encrypted snapshot, retire the source, then activate the receiver. Resume uses the
same saved snapshot; it never reactivates stale source data. These operations require the instance
administrator, while pairing a Desktop grants only its signed-in user's existing permissions.
`POST /api/system/instance/provision` accepts `{ serverId, access: "desktop" | "browser", domain: { kind: "custom" | "free", hostname }, confirmed: true }`.
Optional `mapping` contains
`sourceServerId` and `connectionServerId` for a verified SSH connection to the source host.
The normal deployment engine installs the compatible API image with persistent storage; `browser`
also installs the dashboard. Server preparation completes before the source is paused.
See [Move your Openship instance](/docs/guides/migrate-control-plane) for prerequisites, credential
handling, API addresses, cancellation and recovery. Archive import below is for data recovery and
does not retire another controller.
## Earlier team-mode migration endpoints
These routes remain for clients using the earlier team-mode workflow and require an **instance
administrator**. New instance moves use the handoff above. Forward requests require
`teamMode === "single_user"`; switch-back requires an earlier team mode.
`POST /api/system/migration/start`, `client.instance.migrateToServer()` and
`openship system migration start` remain disabled with **501 `SERVER_MIGRATION_UNAVAILABLE`**.
They do not start the new handoff or copy any data. Use **Settings → Instance → Instance location**
to review the destination and confirm a move.
The earlier preflight and disabled start endpoint share a body:
```
POST /api/system/migration/start
```
- `POST /api/system/migration/start-cloud` — Path B, migrate to Openship Cloud. Body: `{ allowNonEmptyTarget?: boolean }`.
- `POST /api/system/migration/start-tunnel` — Path C, expose via an edge tunnel. Body: `{ slug: string }` (required).
- `POST /api/system/migration/switch-back` — reverse any of them. Body: `{ abandonRemote?: boolean }`.
Reversing to single-user mode revokes teammate access. The remote keeps a copy for a 30-day grace period so
you can recover if you change your mind.
## Instance and project data transfer
Export the entire instance or a dependency-complete selection of projects and environments. These
routes require **instance administrator** access (`requireInstanceAdmin()` plus a handler-level check).
A workspace owner role alone does not grant access to instance credentials.
```
POST /api/system/data-transfer/export
```
```
POST /api/system/data-transfer/import
```
Project imports remap ownership to the active request workspace. They omit instance accounts/settings,
reuse matching server connections, and skip existing projects by default. Overwrite replaces the selected
projects, including removing destination-only records in the selected categories and clearing credentials
that were cleared at the source. Categories excluded from the import are retained. Shared dependencies are kept unless
`overwriteDependencies` is explicitly enabled. Source local hosts require an explicit `serverMappings`
entry (`local` for a project without a server row). Cloud projects require the same connected cloud
account. A project archive cannot be used with `wipe`.
Use the chunk-upload endpoints for large files. After uploading, POST `{ selection }` to the session's
`preview` endpoint. It returns `projects`, `servers`, `availableServers`, row counts, `rowsRemoved`, `warnings`, and
`blockers` without consuming the upload. POST `{ mode, passphrase, selection }` to
`/api/system/data-transfer/import/session/:sessionId/finalize/stream` to apply. Validation is repeated
inside the import transaction. A failed review or password attempt retains the uploaded chunks.
New instance and project exports use envelope version 4 and contain **unencrypted JSON**, including
environment values, SSH keys, tokens, deployment snapshots, and inline Compose configuration. No
password is required; a `passphrase` supplied by an older export client is ignored. Set
`includeSecrets: false` explicitly to omit credentials. Imports still accept versions 1–3, including
legacy password-protected files, and encrypt restored credentials with the destination instance's key.
New archives with tables or fields the destination cannot store are rejected before any data changes;
update the destination instead of losing those fields. Volume data, source folders, and host TLS files
remain on their server.
In project imports, loopback server connections require explicit mapping. Backup policies that point at source-local storage
or a changed backup host are disabled until the operator verifies the destination storage. Direct transfer
supports whole-instance exports; project selections use the file review and import endpoints.
The import body is capped at **500 MB** (**413 `PAYLOAD_TOO_LARGE`** above it). A malformed file or a wrong
or missing password for a legacy sealed archive returns **400**. Project dependency/mapping conflicts return **409
`PROJECT_IMPORT_REQUIRES_REVIEW`**; whole-instance merge collisions return **409 `PK_COLLISION`**. Select
project scope and explicit overwrite options to resolve project conflicts. A concurrent migration/import
returns **503 `BUSY`**.
## SDK and CLI
Remote `client.instance.previewExport`, `exportData` and `importData` use the existing instance-admin
handlers. An organization-bound or scoped credential cannot export other workspaces by omitting its
organization. The SDK does not retry an import whose response is lost.
```ts
const preview = await client.instance.previewExport();
const archive = await client.instance.exportData();
// Store privately: current exports include plaintext credentials.
const result = await destination.instance.importData({ file: archive, mode: "merge" });
```
Import requires an explicit `mode` in the SDK. `selection` supports project IDs, conflict choices,
server mappings and included resources. Database rows and secret envelopes are opaque to the client;
the controller owns archive validation and restoration.
Use `openship system data-transfer` for JSON exports/imports. Direct-transfer pairing and chunk upload
remain the dashboard's recovery protocol. Legacy `instance` team-mode migration calls retain the API's
capability restrictions; `migrations` is the separate workload move/copy API.
{/* api-operations:start */}
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Team-migration readiness check (read-only). | `instance.preflightMigration(input)` Remote client | `POST /api/system/migration/preflight` `settings:admin` · Self-hosted |
| Earlier server migration (501 unavailable; use Instance location). | `instance.migrateToServer(input)` Remote client | `POST /api/system/migration/start` `settings:admin` · Self-hosted |
| Migrate → Openship Cloud. | `instance.migrateToCloud(input?)` Remote client | `POST /api/system/migration/start-cloud` `settings:admin` · Self-hosted |
| Expose this instance via an edge tunnel. | `instance.exposeTunnel(input)` Remote client | `POST /api/system/migration/start-tunnel` `settings:admin` · Self-hosted |
| Reverse a migration back to single-user. | `instance.switchBack(input?)` Remote client | `POST /api/system/migration/switch-back` `settings:admin` · Self-hosted |
| Preview a project selection and its dependencies (instance administrator). | `instance.previewExport(input?)` Remote client | `POST /api/system/data-transfer/preview` `settings:admin` · Self-hosted |
| Export the instance or selected projects (instance administrator). | `instance.exportData(input?)` Remote client | `POST /api/system/data-transfer/export` `settings:admin` · Self-hosted |
| Import an export file, ≤500 MB, with scope and conflict options (instance administrator). | `instance.importData(input)` Remote client | `POST /api/system/data-transfer/import` `settings:admin` · Self-hosted |
| Receive one chunk of an authorized direct transfer. | HTTP only | `PUT /api/system/data-transfer/direct/chunk/:sessionId/:index` `Handler authentication` · Self-hosted |
| Finalize a received direct transfer and stream progress. | HTTP only | `POST /api/system/data-transfer/direct/chunk/:sessionId/finalize/stream` `Handler authentication` · Self-hosted |
| Keep a direct chunk-transfer session alive. | HTTP only | `POST /api/system/data-transfer/direct/chunk/:sessionId/heartbeat` `Handler authentication` · Self-hosted |
| Open a direct chunk-transfer upload. | HTTP only | `POST /api/system/data-transfer/direct/chunk/init` `Handler authentication` · Self-hosted |
| Receive a direct instance transfer. | HTTP only | `POST /api/system/data-transfer/direct/receive` `Handler authentication` · Self-hosted |
| Send an instance to an authorized destination. | HTTP only | `POST /api/system/data-transfer/direct/send` `settings:admin` · Self-hosted |
| Send an instance and stream transfer progress. | HTTP only | `POST /api/system/data-transfer/direct/send/stream` `settings:admin` · Self-hosted |
| Create a direct-transfer session. | HTTP only | `POST /api/system/data-transfer/direct/session` `settings:admin` · Self-hosted |
| Open a chunked file-import session. | HTTP only | `POST /api/system/data-transfer/import/session` `settings:admin` · Self-hosted |
| Upload one file-import chunk. | HTTP only | `PUT /api/system/data-transfer/import/session/:sessionId/chunk/:index` `settings:admin` · Self-hosted |
| Apply a reviewed file import and stream progress. | HTTP only | `POST /api/system/data-transfer/import/session/:sessionId/finalize/stream` `settings:admin` · Self-hosted |
| Preview an uploaded file's selection, conflicts, and server mappings. | HTTP only | `POST /api/system/data-transfer/import/session/:sessionId/preview` `settings:admin` · Self-hosted |
| List exportable projects and instance row counts (instance administrator). | HTTP only | `GET /api/system/data-transfer/preview` `settings:admin` · Self-hosted |
### Instance location
| Operation | SDK | REST API |
| --- | --- | --- |
| Show connection instructions for an API-only instance. | HTTP only | `GET /` `Handler authentication` · Self-hosted |
| Show how to sign in to an API-only instance through Desktop. | HTTP only | `GET /login` `Handler authentication` · Self-hosted |
| Show the invitation address to open in Desktop; no invitation data is exposed. | HTTP only | `GET /accept-invite/:id` `Handler authentication` · Self-hosted |
| Read this installation’s controller role and handoff progress (instance administrator or trusted Desktop recovery). | HTTP only | `GET /api/system/instance` `Handler authentication` · Self-hosted |
| Read the active installation identity and protocol version without account data. | HTTP only | `GET /api/system/instance/identity` `Handler authentication` · Self-hosted |
| Check portable credentials and source-host bindings before moving (instance administrator, read-only). | HTTP only | `POST /api/system/instance/preflight` `settings:admin` · Self-hosted |
| Create a ten-minute source or receiver capability for a whole-instance handoff (instance administrator). | HTTP only | `POST /api/system/instance/offer` `settings:admin` · Self-hosted |
| Start a reviewed move using the other instance’s code; existing workloads stay on their hosts. | HTTP only | `POST /api/system/instance/move` `settings:admin` · Self-hosted |
| Deploy API-only or API plus dashboard on a selected server through the normal deployment engine, then hand off control. | HTTP only | `POST /api/system/instance/provision` `settings:admin` · Self-hosted |
| Resume the saved handoff; a retired source never falls back to its stale data. | HTTP only | `POST /api/system/instance/resume` `Handler authentication` · Self-hosted |
| Cancel before retirement and restore the receiver only after source confirmation. | HTTP only | `POST /api/system/instance/cancel` `Handler authentication` · Self-hosted |
| Connect Desktop with a one-use device code without copying instance data. | HTTP only | `POST /api/system/instance/connect` `settings:admin` · Self-hosted |
| Connect Desktop to a confirmed API address; remote sign-in is still required. | HTTP only | `POST /api/system/instance/connect-address` `settings:admin` · Self-hosted |
| Resume an unrelated paused local instance; a migrated source must use a reverse handoff. | HTTP only | `POST /api/system/instance/disconnect` `settings:admin` · Self-hosted |
| Pull the latest remote instance back into Desktop with remote administrator authorization. | HTTP only | `POST /api/system/instance/return` `settings:admin` · Self-hosted |
| Move current Desktop data back to the previously paired server installation. | HTTP only | `POST /api/system/instance/move-previous` `settings:admin` · Self-hosted |
| Issue a ten-minute device code for the signed-in user’s own permissions. | HTTP only | `POST /api/system/instance/pair` `Handler authentication` · Self-hosted |
| Atomically exchange the one-use code for its issuing user’s remote device session. | HTTP only | `POST /api/system/instance/pair/claim` `Handler authentication` · Self-hosted |
| Bind a provisioned receiver to one handoff using its installation secret; does not activate it. | HTTP only | `POST /api/system/instance/bootstrap` `Handler authentication` · Self-hosted |
| Capability-authenticated bind, freeze, stage, prepare, retire, activate, complete or abort; activation requires source retirement proof. | HTTP only | `POST /api/system/instance/peer/:id/:action` `Handler authentication` · Self-hosted |
| Download an authenticated encrypted snapshot chunk for the bound handoff. | HTTP only | `GET /api/system/instance/peer/:id/chunks/:index` `Handler authentication` · Self-hosted |
| Verify and store an encrypted snapshot chunk for the bound receiver. | HTTP only | `PUT /api/system/instance/peer/:id/chunks/:index` `Handler authentication` · Self-hosted |
{/* api-operations:end */}
---
# Container images
URL: https://openship.io/docs/api/images.md
Browse container images for project services.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Images API returns the **build-image catalog** — the curated list of ready-made service images
(PostgreSQL, Redis, and friends) you pick from when adding a service to a project. In the dashboard this is
the image grid in the **Add service** modal; it's a read-only lookup, so there's nothing to create or edit.
The module is available on every deploy mode (self-hosted, cloud, and desktop), but the catalog itself is
served by Openship Cloud. On a **SaaS** instance it uses the master catalog; on a **self-hosted** instance
with a cloud account linked it uses your org's cloud token. On a self-hosted instance with **no** cloud
link, the endpoint returns an empty list with `cloudConnected: false` rather than an error — the dashboard
falls back to the "Custom image" tile. Results are cached in memory for a few minutes.
## List images
Returns the catalog for your organization. Both filters are optional and applied by the upstream catalog;
omit them to get everything.
```
GET /api/images
```
```bash
curl "$OPENSHIP_URL/api/images" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
# With filters:
curl "$OPENSHIP_URL/api/images?search=postgres&category=database" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The response is `{ "success": true, "images": [ … ] }`. Each entry describes one catalog image; common fields
are `id` (slug you pick), `name` (display name), `image` (the Docker image string), `description`,
`category`, `logo`, `tags`, `ports`, and `defaultEnv` (suggested env keys). Additional fields returned by the
upstream catalog are passed through unchanged for forward compatibility.
## Errors
Not an error. On a self-hosted instance with no cloud account linked, the response is
`{ "success": true, "images": [], "cloudConnected": false }`. Link a cloud account to populate the catalog,
or supply a custom image directly on the service.
The upstream catalog call failed. The response is `{ "success": false, "error": "…" }`. Retry after a
moment; the result is cached once fetched.
No valid session cookie or bearer token was supplied. Create a token with
[`openship token create`](/docs/cli/access) and send it as `Authorization: Bearer `.
## Operations
{/* api-operations:start */}
| Operation | REST API |
| --- | --- |
| List available build/service images, optionally filtered by `?search=` and `?category=`. | `GET /api/images` `Authenticated` |
{/* api-operations:end */}
---
# Source files
URL: https://openship.io/docs/api/sources.md
Stage generated files or a directory, inspect the source, and deploy it.
Source sessions hold uploaded application files until deployment. The SDK accepts a directory or an
in-memory file map. REST accepts a compressed archive through a short-lived upload session.
## Deploy generated files
The SDK's `deploy()` helper combines staging, detection, project selection, and deployment submission.
Use it when your application or AI workflow produces files:
```ts
const submitted = await ship.deploy({
name: "generated-site",
source: {
type: "files",
files: { "index.html": "
Hello from Openship
" },
},
});
const outcome = await ship.deployment(submitted.deployment_id).wait({ timeoutMs: 120_000 });
if (!outcome.success) throw new Error(outcome.message ?? outcome.status);
```
File keys are relative paths; values may be strings or `Uint8Array` data. Use
`{ type: "directory", path: "/absolute/path/to/site" }` for a directory. With a remote client, files are
packed on the calling machine. A native directory must be inside an allowed `policy.sourceRoots` entry.
| `deploy()` option | Use |
| --- | --- |
| `source` | Required file map or absolute directory path. |
| `name` | Suggested project name. |
| `projectId` | Deploy into an existing authorized project. |
| `environment` | `production` or `preview`. |
| `serverId` | Authorized execution server, including a Cloud workspace's returned `serverId`; omit to use the configured target. |
| `serviceIds` | Selected detected services. |
| `onStep` | Source-workflow progress callback. |
| `signal` | Abort supported source work; a submitted deployment requires explicit cancellation. |
The result contains `deployment_id`, `project_id`, and optional `configDiagnostics`. Submission and
readiness are separate. See [deployment outcomes](/docs/api/deployments#wait-decisions-and-cancellation).
## Upload a source folder
For a custom uploader, open a session bound to an existing authorized project:
```ts
const session = await ship.sources.open({ projectId: "proj_my_site" });
console.log(session.sessionId, session.upload);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/folder/session" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"projectId":"proj_my_site"}'
```
For a credential restricted to projects it creates, create the project first with `gitProvider: "upload"`
and its destination `serverId`. Pass the resulting `projectId` to the session and subsequent
`projects.ensure()` call. Omitting `projectId` opens an unbound session and requires wildcard project
write permission. A desktop MCP connection can use a controller-local path instead; see
[deploy a desktop folder on Cloud](/docs/api/mcp#deploy-a-desktop-folder-on-cloud).
The response includes `sessionId`, `expiresAt`, and `upload` instructions:
| Upload field | Use |
| --- | --- |
| `absoluteUrl`, `method` | Destination and HTTP method for the archive. |
| `headers` | Required upload headers. |
| `requiresAuth` | Send your bearer credential only when required. |
| `withCredentials` | Whether a browser upload needs credentials. |
Send a gzip-compressed tar archive to the returned URL with the supplied headers and authentication.
Cloud and self-hosted instances share `POST /api/projects/folder/upload/:sessionId`, with a 300 MB limit.
Source files are staged privately and prepared on the selected execution server for deployment.
The SDK can perform both session creation and upload for you:
```ts
const staged = await ship.sources.stage({
projectId: "proj_my_site",
name: "my-site",
source: { type: "directory", path: "/absolute/path/to/site" },
});
console.log(staged.sessionId, staged.expiresAt);
```
Directory packing excludes `.git`, `node_modules`, and `.DS_Store`. It enforces path, entry, and size
limits and rejects escaping symlinks and special files. A system `tar` executable is not required by the SDK.
## Inspect an uploaded source
```ts
const scan = await ship.sources.scan("session_123", { includeEnv: true });
console.log(scan.stack, scan.buildCommand, scan.configDiagnostics);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/folder/scan/session_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"includeEnv":true}'
```
Detection returns the stack, package manager, commands, output paths, service definitions, and any
configuration diagnostics. Inspect errors before submitting a deployment. Environment values are
masked by default. The example requests editable values in the scan response with `includeEnv: true`;
see [Reveal environment values](/docs/api/services#reveal-environment-values).
To finish a custom flow, use `projects.ensure()` to record the chosen configuration, then
`deployments.buildAccess()` with `projectId` and `uploadSessionId`. The shared fields are documented in
[projects](/docs/api/projects) and [deployments](/docs/api/deployments#deploy-wizard-buildaccess).
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Package and stage generated files or an allowed directory. | `sources.stage(input, options?)` | [Upload workflow](/docs/api/sources#upload-a-source-folder) |
| Open a folder upload session and return its upload instructions. | `sources.open(input?)` | `POST /api/projects/folder/session` `project:write` |
| Detect build configuration from a staged source session. | `sources.scan(id, options?)` | `POST /api/projects/folder/scan/:sessionId` `project:write` |
| Reveal explicitly requested source values after authorization. | `sources.reveal(id, input)` | `POST /api/projects/folder/scan/:sessionId/env-reveal` `project:write` |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Upload the gzipped source archive (Cloud and self-hosted, 300 MB limit). | HTTP only | `POST /api/projects/folder/upload/:sessionId` `project:write` |
{/* api-operations:end */}
---
# Provider credentials
URL: https://openship.io/docs/api/credentials.md
Store and verify organization-owned registry and DNS credentials.
Provider credentials let Openship pull private images or update DNS. A credential belongs to one
organization. Reads expose public fields and masked secret indicators; creating, changing, verifying,
or removing a credential requires administration access.
## Discover supported providers
Read provider definitions before building a credential form. Each definition includes its ID, capability,
selector requirements, and field keys. Use those keys in the `values` object when creating a credential.
```ts
const providers = await ship.credentials.listProviders();
console.log(providers);
```
```bash
curl "$OPENSHIP_URL/api/credentials/providers" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Create or update a credential
| Field | Type | Use |
| --- | --- | --- |
| `provider` | `string` | Required on creation; an ID from the provider catalog, at most 64 characters. |
| `name` | `string` | Required on creation; a display name of 1–100 characters. |
| `selector` | `string` or `null` | Provider-specific registry or account selector. |
| `values` | `Record` | Required on creation; public and secret fields defined by the provider. |
Updates accept `name`, `selector`, and `values`. The provider cannot be changed. Use values from your
credential form or secret store; masked values returned by reads are not replacement secrets.
## Verify a saved credential
```ts
const credential = await ship.credentials.verify("cred_123");
console.log(credential.status, credential.lastError);
```
```bash
curl -X POST "$OPENSHIP_URL/api/credentials/cred_123/verify" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Verification returns the credential's status, `lastVerifiedAt`, and `lastError`. Check that status before
using the credential for a deployment. See [DNS providers](/docs/api/dns) for the DNS connection workflow.
## Private HTTPS registries
Self-hosted Openship can verify registries on a private network. The registry certificate must match
its hostname, and the Openship API process must trust its issuing CA. For an internal CA, mount the
CA's PEM file into the API container and set `NODE_EXTRA_CA_CERTS` to that path. For example, add this
to a Compose override alongside your installation's existing configuration:
```yaml
services:
api:
environment:
NODE_EXTRA_CA_CERTS: /etc/openship/registry-ca.pem
volumes:
- ./registry-ca.pem:/etc/openship/registry-ca.pem:ro
```
Recreate the API container with the override so the runtime loads the CA at startup. Docker daemons
on servers that pull the images need their own registry CA configuration. Adding trust to the API
does not configure those servers. Openship Cloud rejects private network registry targets.
Use the release's pinned Bun runtime, currently **1.3.14**, when running the API under Bun. Bun 1.3.3
and 1.3.10 can reject a valid hostname certificate on Openship's pinned-IP HTTPS path. Bun 1.4.0 has
an upstream regression in asynchronous WebSocket upgrades, which affects terminals. The API image,
release runtime pin, and network regression tests use 1.3.14; Node 22 is also covered for development
and desktop. Rebuild or update the API image to apply the runtime fix permanently.
Registry authentication realms are checked separately from TLS. Credentials are sent only to the
registry's origin (scheme, hostname, and port) or the supported Docker Hub and GitLab.com authentication
origins. For private GitLab on port `5050` advertising a token endpoint on port `443`, expose the token
endpoint through the registry origin and configure GitLab to advertise that URL. Trusting its CA or
updating Bun does not authorize a different authentication origin.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List provider credential types and required fields. | `credentials.listProviders()` | `GET /api/credentials/providers` `settings:read` |
| List stored credentials with secrets masked. | `credentials.list()` | `GET /api/credentials` `settings:read` |
| Store a provider credential. | `credentials.create(input)` | `POST /api/credentials` `settings:admin` |
| Read one masked credential. | `credentials.get(id)` | `GET /api/credentials/:id` `settings:read` |
| Rename, re-scope, or rotate a credential. | `credentials.update(id, input)` | `PATCH /api/credentials/:id` `settings:admin` |
| Remove a credential. | `credentials.remove(id)` | `DELETE /api/credentials/:id` `settings:admin` |
| Check the credential against its provider and record the result. | `credentials.verify(id)` | `POST /api/credentials/:id/verify` `settings:admin` |
{/* api-operations:end */}
---
# Issues and health
URL: https://openship.io/docs/api/issues.md
Read authorized issues, inspect workload health, and request fresh checks.
Issues combine deployment problems, incidents, domain failures, component health, and update advisories.
Results are filtered to resources the caller can see.
## List issues
```ts
const result = await ship.issues.list({ status: "open" });
console.log(result.issues, result.counts);
```
```bash
curl "$OPENSHIP_URL/api/issues?status=open" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
`status` is `open` or `resolved`. The result contains `issues`, `counts`, and the selected `status`.
Each issue includes its severity, source, target, message, and any supported resolution action.
Counts are grouped as `outage`, `actionRequired`, `advisory`, and `total`.
## Clear resolved history
Desktop and self-hosted organization owners/admins can call `ship.issues.clearHistory()`
(or `DELETE /api/issues/history`). The response is `{ deleted: number }`. This permanently
removes resolved incidents in the current organization, including history beyond the feed
limit. Active incidents, later recoveries, other organizations, audit logs and notifications
remain. The list response exposes `canClearHistory` for the current caller; read-only and
restricted credentials cannot use this operation. The dashboard requires confirmation,
and `openship monitoring clear-history --yes` exposes the same operation from the CLI.
## Inspect workload health
```ts
const health = await ship.issues.health();
console.log(health.workloads, health.currentScan);
```
```bash
curl "$OPENSHIP_URL/api/issues/health" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The health snapshot includes workload observations, scan timing, and watcher capabilities. It does not
start a continuous watcher. `scanHealth()` requests a fresh one-time check where the host supports it;
it refreshes snapshots without opening or resolving incidents. Native scheduling remains disabled
unless explicitly configured.
## Refresh issue sources
`rescan()` starts the broader rescan pipeline on self-hosted instances and requires an instance
administrator with job-write access. `rescanStatus()` reads the latest scan's stage statuses, summaries,
and failures. A completed stage can still report gaps such as unreachable servers or an offline desktop.
Use `rescan({ healthOnly: true })` to run the existing container/server health watcher and reconcile
incidents without component updates or domain reconciliation. The REST equivalent accepts
`{"healthOnly":true}` in the body of `POST /api/issues/rescan`. Omitting the input keeps the full rescan
behavior. If a scan is already running, the request returns that existing session; follow its progress
with `rescanStatus()`.
A disconnected desktop cannot establish remote server health. The Monitoring page requests a fresh
health check on desktop reconnection, and an unreachable-server incident resolves only after the
daemon answers successfully.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Read visible active or resolved issues and their suggested actions. | `issues.list(input?)` | `GET /api/issues` `project:list` |
| Read issue counts by severity. | `issues.summary()` | `GET /api/issues/summary` `project:list` |
| Read cached workload health snapshots. | `issues.health()` | `GET /api/issues/health` `project:list` |
| Refresh current workload health without enabling the scheduler. | `issues.scanHealth()` | `POST /api/issues/health/scan` `project:list` |
| Run applicable issue checkers, or only container/server health. | `issues.rescan(input?)` | `POST /api/issues/rescan` `job:write` · Self-hosted |
| Read the status of an issue rescan. | `issues.rescanStatus()` | `GET /api/issues/rescan/status` `job:read` · Self-hosted |
| Permanently clear resolved incident history in the current organization; preserves active incidents and later recoveries. Owner/admin only. | `issues.clearHistory()` | `DELETE /api/issues/history` `project:admin` · Self-hosted |
{/* api-operations:end */}
---
# Projects
URL: https://openship.io/docs/api/projects.md
Create and configure projects, source settings, and environments.
import { TypeTable } from 'fumadocs-ui/components/type-table';
A project combines source code, build configuration, environment variables, domains, and deployment
history. Create a project record first, then [submit a deployment](/docs/api/deployments).
Local filesystem and edge administration operations require self-hosted capabilities. For Cloud, connect
to the Cloud API directly. [Fixed scopes do not forward through an owner's Cloud link](/docs/api/sdk/compatibility#cloud).
## Create a project
Create a project from a git repo or a local path, baking the build config into the project row. For an
uploaded folder, use the [source upload flow](/docs/api/sources) instead. Only `name` is required —
everything else is auto-detected or defaulted.
```ts
const result = await ship.projects.create({
name: "marketing-site",
gitOwner: "acme",
gitRepo: "site",
gitBranch: "main",
framework: "nextjs",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"marketing-site","gitOwner":"acme","gitRepo":"site","gitBranch":"main","framework":"nextjs"}'
```
`POST /api/projects` only records the project and its config. Trigger the first build with the
[Deployments API](/docs/api/deployments) (`POST /api/deployments`) or `openship deploy`.
## Scale a stateless application on a cluster
Self-hosted projects can target a [ready server cluster](/docs/api/servers).
Saving the target requires fleet administration. Choose a registry repository for source builds;
cluster nodes pull immutable release images using the saved registry credentials.
This supports a single application or worker whose instances can start on any selected server.
Project-owned shared volumes can persist files across instances; node-local bind mounts and
Compose conversion require a separate migration. PostgreSQL and Redis use their own managed
database lifecycle and replication.
```ts
const current = await ship.projects.getClusterWorkload("proj_123");
await ship.projects.setClusterTarget("proj_123", {
clusterId: "cluster_123",
config: { replicas: 3, imageRepository: "ghcr.io/acme/api" },
expectedUpdatedAt: current.updatedAt,
stateless: true,
});
// Deploy the project through the existing Deployments API.
// After that release is active, change its replicas without rebuilding:
const live = await ship.projects.getClusterWorkload("proj_123");
if (live.activeDeploymentId && live.activeClusterId === live.clusterId) {
const scale = await ship.projects.scaleClusterWorkload("proj_123", {
replicas: 4,
expectedDeploymentId: live.activeDeploymentId,
expectedUpdatedAt: live.updatedAt,
});
console.log(scale.deploymentId); // Follow the normal deployment progress stream.
}
```
Replica changes are configuration releases. They reuse the active image, wait for ready pods and
use the existing update/rollback history. Allow capacity for the old and new releases together.
`status` and `observedAt` describe the last observation; saved `config` describes future intent.
OpenShip Edge currently enters through the first cluster control server. Automatic gateway
failover and policy-driven autoscaling are not implemented.
### Share application files
Enable shared storage on the server cluster first. Use `createClusterVolume` to create a project
volume, then add its name and mount path to the cluster configuration and deploy. Each release
retains its reviewed volume identities. `listClusterVolumes` and `streamClusterVolumeEvents`
report attachment health, independent copies, expansion and backups.
Shared-file backups use the cluster's configured external destination. Schedules can run hourly
or daily. `listClusterVolumeBackups` includes archives whose original volume was deleted;
restore into a new volume and verify its contents before attaching it to the application.
Disconnect and deploy before deleting a volume. External backups survive volume removal.
### Add, import or recover a database
Create PostgreSQL or Redis through `createClusterDatabase`, then inspect progress until ready.
Database instances and Redis shards scale independently of application replicas. A Redis shard
change requires a verified backup and explicit review.
`listClusterDatabaseImports` returns eligible backups of this project's existing PostgreSQL or
Redis services. Use a selected backup with `importFrom`, or recover a managed database archive
with `restoreFrom`. A PostgreSQL 17-to-18 upgrade uses `copyFrom` to build a separate database.
Each path preserves the source. You can prepare imported databases before changing the app's
cluster target; it must later select the same cluster.
Verify the recovered data, then explicitly save or replace the managed application connection
with both databases' current sequences. Redeploy to use it. For a final cutover, pause source
writes and take a fresh recovery point; writes after capture are not copied automatically.
See the [database workflow](/docs/guides/mcp-clusters-and-scaling#database-and-backup-workflows).
## Update a project
The update body is a **partial** of the [create body](#create-a-project) — send only the fields you want
to change. Every field above is accepted and optional here.
```ts
const result = await ship.projects.update("proj_123", {
buildCommand: "pnpm build",
gitBranch: "release",
});
console.log(result);
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/projects/proj_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"buildCommand":"pnpm build","gitBranch":"release"}'
```
## Link a git repo
Attach (or re-point) a GitHub repository to an existing project. When `branch` is omitted, the repo's
default branch is used.
```ts
const result = await ship.projects.linkRepo("proj_123", {
owner: "acme",
repo: "site",
branch: "main",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/git/link" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"owner":"acme","repo":"site","branch":"main"}'
```
Related git routes: `POST /api/projects/:id/branch` (change the deploy branch),
`POST /api/projects/:id/auto-deploy` (toggle deploy-on-push), `GET /api/projects/:id/branches`, and
`GET /api/projects/:id/commit-status` (is the deployed commit behind remote HEAD?). See the
[GitHub API](/docs/api/github) for connecting the GitHub App itself.
## Connect a custom domain
A shortcut that adds a domain to the project and marks it primary in one call. For the full domain
lifecycle (DNS preview, verification, SSL), use the [Domains API](/docs/api/domains).
```ts
const result = await ship.projects.connectDomain("proj_123", {
domain: "app.example.com",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/connect" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"domain":"app.example.com"}'
```
## Environment variables
```
GET /api/projects/:id/env
PATCH /api/projects/:id/env
```
`GET` lists variables for the project with secret values masked. Writes go through a **merge**: only the
keys you name are touched — `upserts` are inserted/updated, `deletes` are removed, and every other
variable (including untouched masked secrets) is left intact.
```ts
const result = await ship.projects.mergeEnvVars("proj_123", {
environment: "production",
upserts: [
{
key: "DATABASE_URL",
value: "postgres://…",
isSecret: true,
},
],
deletes: ["OLD_FLAG"],
});
console.log(result);
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/projects/proj_123/env" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"environment": "production",
"upserts": [{"key":"DATABASE_URL","value":"postgres://…","isSecret":true}],
"deletes": ["OLD_FLAG"]
}'
```
The old destructive `PUT /:id/env` was removed — it could wipe or corrupt masked secrets. Always send a
diff via the merge `PATCH`.
## Resources
```
GET /api/projects/:id/resources
PATCH /api/projects/:id/resources
POST /api/projects/:id/resources
```
Read or update the CPU/RAM/disk allotment (separately for production and build), sleep behavior, and listen
port. `POST` is an alias of `PATCH`. All fields are optional; send only what you want to change.
```ts
const result = await ship.projects.updateResources("proj_123", {
production: {
cpuCores: 1,
memoryMb: 1024,
},
sleepMode: "always_on",
});
console.log(result);
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/projects/proj_123/resources" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"production":{"cpuCores":1,"memoryMb":1024},"sleepMode":"always_on"}'
```
Sleep mode also has its own shortcut route: `POST /api/projects/:id/sleep-mode`.
## Create an environment
```
POST /api/projects/:id/environments
```
## Folder uploads
See [Source files](/docs/api/sources) to upload a folder or deploy generated code.
## Transfer to / from cloud
```
POST /api/projects/:id/transfer/to-cloud † self-hosted only
POST /api/projects/:id/transfer/to-self-hosted † self-hosted only
```
Promote a local project to Openship Cloud, or pull a cloud project back to this instance. These are
meaningless on the SaaS (it *is* the cloud) and return `404` there. Both require `project:admin`.
```ts
const result = await ship.projects.transferToCloud("proj_123");
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/transfer/to-cloud" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Retry routing with logs
Routing repair can include SSH and certificate issuance. Use the streaming operation to follow its
progress without the ordinary request timeout:
```ts
for await (const event of ship.projects.retryRoutingStream("proj_123")) {
console.log(event.event, event.data);
}
```
The HTTP equivalent is `POST /api/projects/:id/routing/retry/stream` with an SSE response. Log events
contain the server's messages. A terminal `complete` event carries `status: "completed"` or
`status: "failed"`; a disconnected stream alone does not establish success. Cancelling the stream
stops log delivery while an accepted repair continues under the project's runtime lock.
The first `session` event includes a `sessionId`. Pass it to
`ship.projects.retryRoutingStream(id, { sessionId })`, or use
`GET /api/projects/:id/routing/retry/stream?sessionId=...`, to replay retained logs and follow the
same repair. Reconnecting requires `project:read` and never starts another repair. The project info
response includes the latest session as `project.routingRetry` so the dashboard can restore the log
after a refresh. Completed logs are retained in the running engine for up to 30 minutes, subject to
the retention limit; they do not survive an API restart.
Starting requires `project:write`. Concurrent start requests join the project's active repair.
For an uncertain start response, reuse `options.idempotencyKey` (the `idempotencyKey` query parameter
over HTTP) so a repeated request also rejoins a completed, retained session. Use a new key only
when intentionally starting another repair.
## Errors
A field is missing or out of range (e.g. `name` empty, a `cpuCores` above 4, or `git/link` without
`owner`/`repo`). The response names the offending field.
Your token or role lacks the route's tag — deleting needs `project:admin`, writes need `project:write`.
See the [permission model](/docs/security/auth).
The `:id` doesn't belong to your organization (or was deleted). A self-hosted-only route (marked **†**)
also returns `404` when called on Openship Cloud. List your projects with `GET /api/projects` to get valid
IDs.
## Operations
{/* api-operations:start */}
### Lifecycle
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the project overview and summary counts. | `projects.getHome()` | `GET /api/projects/home` `project:list` |
| Create a project record from explicit configuration. | `projects.create(input)` | `POST /api/projects` `project:write` |
| Create or select a project during source import. | `projects.ensure(input)` | `POST /api/projects/ensure` `project:write` |
| Return a page of accessible projects. | `projects.list(input?)` | `GET /api/projects` `project:list` |
| Read one project and its active deployment ID. | `projects.get(id)` | `GET /api/projects/:id` `project:read` |
| Update project configuration. | `projects.update(id, input)` | `PATCH /api/projects/:id` `project:write` |
| Tear down the project and remove its records; inspect the returned steps. | `projects.remove(id, input?)` | `DELETE /api/projects/:id` `project:admin` |
| Enable the project runtime. | `projects.enable(id)` | `POST /api/projects/:id/enable` `project:write` |
| Disable the project runtime. | `projects.disable(id)` | `POST /api/projects/:id/disable` `project:write` |
| Inspect resources that project deletion would affect. | `projects.deletionPreview(id)` | `GET /api/projects/:id/deletion-preview` `project:read` |
### Source and deployment
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the project’s detailed information. | `projects.getInfo(id)` | `GET /api/projects/:id/info` `project:read` |
| Read linked Git source information. | `projects.getGitInfo(id)` | `GET /api/projects/:id/git` `project:read` |
| List branches available from the linked source. | `projects.listBranches(id, input?)` | `GET /api/projects/:id/branches` `project:read` |
| Link a Git repository to the project. | `projects.linkRepo(id, input)` | `POST /api/projects/:id/git/link` `project:write` |
| Configure a release image as the deployment source. | `projects.setReleaseImageSource(id, input)` | `PUT /api/projects/:id/release-image-source` `project:write` |
| Enable or disable automatic deployment triggers. | `projects.setAutoDeploy(id, input)` | `POST /api/projects/:id/auto-deploy` `project:write` |
| Choose the domain used for the project webhook. | `projects.setWebhookDomain(id, input)` | `POST /api/projects/:id/webhook-domain` `project:write` |
| Read a page of the project’s deployments. | `projects.listDeployments(id, input?)` | `GET /api/projects/:id/deployments` `project:deployment:list` |
| Read the project’s current deployment session. | `projects.deploymentSession(id)` | `POST /api/projects/:id/deployment-session` `project:read` |
| Clear authorized build cache for the project. | `projects.clearBuildCache(id)` | `POST /api/projects/:id/clear-build` `project:admin` · Self-hosted |
| Inspect retained rollback capacity. | `projects.getRollbackCapacity(id)` | `GET /api/projects/:id/rollback-capacity` `project:read` |
| Check deployment port requirements. | `projects.checkPorts(id)` | `POST /api/projects/:id/port-check` `project:read` |
| Check the configured build output. | `projects.checkOutput(id)` | `POST /api/projects/:id/output-check` `project:read` |
| Read actions that need a deployment or routing decision. | `projects.getPendingActions(id)` | `GET /api/projects/:id/pending-actions` `project:read` |
| Compare source and deployed commit status. | `projects.getCommitStatus(id)` | `GET /api/projects/:id/commit-status` `project:read` |
| Select the default Git branch. | `projects.setBranch(id, input)` | `POST /api/projects/:id/branch` `project:write` |
| Scan an allowed local source directory. | `projects.scanLocal(input)` | `POST /api/projects/scan` `project:write` · Self-hosted |
| Import an allowed local project. | `projects.importLocal(input)` | `POST /api/projects/import` `project:write` · Self-hosted |
| List discoverable local projects. | `projects.listLocal()` | `GET /api/projects/local` `project:list` · Self-hosted |
### Cluster scaling
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the selected cluster, active release and observed replicas. | `projects.getClusterWorkload(id)` | `GET /api/projects/:id/cluster` `project:read` · Self-hosted |
| Save a ready self-hosted cluster target, application configuration and optional shared-file mounts. Requires fleet administration and the current project timestamp. | `projects.setClusterTarget(id, input)` | `PATCH /api/projects/:id/cluster` `project:write` · Self-hosted |
| Apply a replica count through a deployment using the active immutable image. Requires active deployment and project timestamp preconditions. | `projects.scaleClusterWorkload(id, input)` | `POST /api/projects/:id/cluster/scale` `project:write` · Self-hosted |
### Cluster databases
| Operation | SDK | REST API |
| --- | --- | --- |
| List the project's operator-managed databases and saved observations. Available on self-hosted OpenShip. | `projects.listClusterDatabases(id)` | `GET /api/projects/:id/cluster/databases` `project:read` · Self-hosted |
| List eligible PostgreSQL and Redis backup imports from this project. Requires project administrator access; source backups and running services are preserved. | `projects.listClusterDatabaseImports(id)` | `GET /api/projects/:id/cluster/databases/imports` `project:read` · Self-hosted |
| Read saved database progress, or refresh the operator's instances, volumes and archive status with observe. Does not start or retry setup. | `projects.getClusterDatabase(id, input)` | `POST /api/projects/:id/cluster/databases/inspect` `project:read` · Self-hosted |
| Create PostgreSQL or Redis on a ready server cluster with a stable request UUID. Recover a database archive, import an existing project backup or create an upgraded PostgreSQL copy. Requires fleet administration; the source is preserved. | `projects.createClusterDatabase(id, input)` | `POST /api/projects/:id/cluster/databases` `project:write` · Self-hosted |
| Apply supported resource, replica or backup settings with the current sequence. Redis shard changes require explicit review and a verified backup; PostgreSQL major upgrades use a new database copy. | `projects.updateClusterDatabase(id, input)` | `PATCH /api/projects/:id/cluster/databases` `project:write` · Self-hosted |
| Resume a failed or interrupted database operation from its saved intent. The previous controller is fenced and accepted operator resources are inspected before reuse. | `projects.retryClusterDatabase(id, input)` | `POST /api/projects/:id/cluster/databases/retry` `project:write` · Self-hosted |
| Request a PostgreSQL or Redis archive at the configured S3 destination. Native controllers and Jobs own execution; retry reuses the accepted backup request. | `projects.backupClusterDatabase(id, input)` | `POST /api/projects/:id/cluster/databases/backup` `project:write` · Self-hosted |
| Stop a disconnected database with name and sequence confirmation. deleteData=false retains persistent disks; true explicitly reclaims owned storage. S3 archives are kept. | `projects.removeClusterDatabase(id, input)` | `DELETE /api/projects/:id/cluster/databases` `project:write` · Self-hosted |
| Save a private database URL in the project environment, or explicitly replace another managed database binding using both current sequences. Set envKey to null to disconnect. Redeploy to apply the reviewed change. | `projects.connectClusterDatabase(id, input)` | `POST /api/projects/:id/cluster/databases/connect` `project:write` · Self-hosted |
| Subscribe to replayable database progress snapshots over SSE. Reconnection only reads saved state and never repeats a mutation. | `projects.streamClusterDatabaseEvents(id, options?)` | `GET /api/projects/:id/cluster/databases/stream` `project:read` · Self-hosted |
### Shared files
| Operation | SDK | REST API |
| --- | --- | --- |
| Read shared file volumes, independent copies, attachment health and backup status. | `projects.listClusterVolumes(id)` | `GET /api/projects/:id/cluster/volumes` `project:read` · Self-hosted |
| List project file archives, including backups whose original volume was deleted. | `projects.listClusterVolumeBackups(id)` | `GET /api/projects/:id/cluster/volumes/backups` `project:read` · Self-hosted |
| Create a replicated shared volume or restore an archive into a new one using a stable request ID. Attach it through cluster configuration and deploy. | `projects.createClusterVolume(id, input)` | `POST /api/projects/:id/cluster/volumes` `project:write` · Self-hosted |
| Grow a shared volume using its current resourceVersion. Observe status until expansion completes; shrinking is unsupported. | `projects.resizeClusterVolume(id, input)` | `PATCH /api/projects/:id/cluster/volumes` `project:write` · Self-hosted |
| Save a file-volume backup to the cluster's configured external destination using a stable request ID. Pause application writes when consistency requires it. | `projects.backupClusterVolume(id, input)` | `POST /api/projects/:id/cluster/volumes/backup` `project:write` · Self-hosted |
| Schedule hourly or daily file backups with a retained archive count, or choose manual to stop the schedule. | `projects.scheduleClusterVolumeBackups(id, input)` | `PATCH /api/projects/:id/cluster/volumes/backups` `project:write` · Self-hosted |
| Permanently delete a project file archive after confirming its exact backup name. The source volume is preserved. | `projects.removeClusterVolumeBackup(id, input)` | `DELETE /api/projects/:id/cluster/volumes/backups` `project:write` · Self-hosted |
| Delete an unmounted volume with resourceVersion, name and data-deletion confirmation. Disconnect and redeploy first; external archives are preserved. | `projects.removeClusterVolume(id, input)` | `DELETE /api/projects/:id/cluster/volumes` `project:write` · Self-hosted |
| Subscribe to current file-volume and archive snapshots over SSE without repeating mutations on reconnect. | `projects.streamClusterVolumeEvents(id, options?)` | `GET /api/projects/:id/cluster/volumes/stream` `project:read` · Self-hosted |
### Environments and settings
| Operation | SDK | REST API |
| --- | --- | --- |
| List the project’s environments. | `projects.listEnvironments(id)` | `GET /api/projects/:id/environments` `project:read` |
| Create an environment from the supplied configuration. | `projects.createEnvironment(id, input)` | `POST /api/projects/:id/environments` `project:write` |
| Read environment variables with secrets masked. | `projects.listEnvVars(id, input?)` | `GET /api/projects/:id/env` `project:read` |
| Upsert and delete named environment variables. | `projects.mergeEnvVars(id, input)` | `PATCH /api/projects/:id/env` `project:write` |
| Read resource limits and sleep settings. | `projects.getResources(id)` | `GET /api/projects/:id/resources` `project:read` |
| Change resource allocations. | `projects.updateResources(id, input)` | `PATCH /api/projects/:id/resources` `project:write` |
| Set the project’s sleep behavior. | `projects.setSleepMode(id, input)` | `POST /api/projects/:id/sleep-mode` `project:write` |
| Change deployment options. | `projects.setOptions(id, input)` | `POST /api/projects/:id/options` `project:write` |
| Read whether a project clone token is configured. | `projects.getCloneToken(id)` | `GET /api/projects/:id/clone-token` `project:read` |
| Set, rotate, or clear the project clone token. | `projects.updateCloneToken(id, input)` | `PATCH /api/projects/:id/clone-token` `project:admin` |
### Routing and monitoring
| Operation | SDK | REST API |
| --- | --- | --- |
| Repair project routing and verify pending domains and HTTPS. | `projects.retryRouting(id)` | `POST /api/projects/:id/routing/retry` `project:write` |
| Repair routing with live logs and a terminal success or failure event. | `projects.retryRoutingStream(id, options?)` | `POST /api/projects/:id/routing/retry/stream` `project:write` |
| Read active runtime roles, replica status, and restart counts. | `projects.getRuntimeRoles(id)` | `GET /api/projects/:id/roles` `project:read` |
| Read recent runtime logs; optionally select a role, replica, and active deployment. | `projects.runtimeLogs(id, input?)` | `GET /api/projects/:id/logs` `project:read` |
| List the project’s edge route rules. | `projects.listRouteRules(id)` | `GET /api/projects/:id/route-rules` `project:read` · Self-hosted |
| Add an edge route rule. | `projects.createRouteRule(id, input)` | `POST /api/projects/:id/route-rules` `project:write` · Self-hosted |
| Update an edge route rule using its typed input. | `projects.updateRouteRule(id, input)` | `PATCH /api/projects/:id/route-rules/:ruleId` `project:write` · Self-hosted |
| Remove the specified edge route rule. | `projects.removeRouteRule(id, input)` | `DELETE /api/projects/:id/route-rules/:ruleId` `project:write` · Self-hosted |
| Read open and resolved health incidents. | `projects.getIncidents(id)` | `GET /api/projects/:id/incidents` `project:read` · Self-hosted |
| Attach a domain to the project. | `projects.connectDomain(id, input)` | `POST /api/projects/:id/connect` `project:write` |
| Read the project’s edge configuration. | `projects.getEdgeConfig(id)` | `GET /api/projects/:id/edge-config` `project:read` · Self-hosted |
| Obtain an authorized server-log stream token. | `projects.getServerLogStreamToken(id, input?)` | `GET /api/projects/:id/server-logs/stream-token` `project:read` |
| Read recent request/server logs. | `projects.recentServerLogs(id, input?)` | `GET /api/projects/:id/server-logs/recent` `project:read` |
| Stream project runtime log events. | `projects.streamRuntimeLogs(id, input?, options?)` | `GET /api/projects/:id/logs/stream` `project:read` |
| Stream project request/server log events. | `projects.streamServerLogs(id, input?, options?)` | `GET /api/projects/:id/server-logs/stream` `project:read` |
| Read active role definitions and the revision required to configure them. | `projects.getRuntimeRoleConfiguration(id)` | `GET /api/projects/:id/roles/configuration` `project:read` |
| Apply a role configuration revision from the active image while preserving web and unchanged replicas. | `projects.configureRuntimeRoles(id, input)` | `POST /api/projects/:id/roles/configuration` `project:write` |
### Connections, storage, and apps
| Operation | SDK | REST API |
| --- | --- | --- |
| List the project’s outgoing resource connections. | `projects.listConnections(id)` | `GET /api/projects/:id/connections` `project:read` |
| List writable projects and apps for a connection, including cluster IDs for native database placement. | `projects.listConnectionCandidates(id)` | `GET /api/projects/:id/connections/candidates` `project:write` |
| List projects consuming this project’s outputs. | `projects.listConnectionConsumers(id)` | `GET /api/projects/:id/connections/consumers` `project:read` |
| Connect an output to a target secret environment variable. Native database outputs require source and target write access and the same organization and cluster; ownership stays with the source. | `projects.createConnection(id, input)` | `POST /api/projects/:id/connections` `project:write` |
| Save a group of compatible resource connections and encrypted environment values in one transaction. Native database links reconcile private namespace access before reporting success; a failed reconciliation can be retried with the same inputs. | `projects.connectBundle(id, input)` | `POST /api/projects/:id/connections/bundle` `project:write` |
| Remove a resource connection. | `projects.removeConnection(id, input)` | `DELETE /api/projects/:id/connections/:linkId` `project:admin` |
| Read the project’s object-storage binding. | `projects.getStorage(id)` | `GET /api/projects/:id/storage` `project:read` |
| Bind a configured storage bucket. | `projects.bindStorage(id, input)` | `POST /api/projects/:id/storage` `project:write` |
| Remove the storage binding. | `projects.unbindStorage(id)` | `DELETE /api/projects/:id/storage` `project:admin` |
### Cloud transfer
| Operation | SDK | REST API |
| --- | --- | --- |
| Request a Cloud transfer; fixed scopes currently require unavailable tenant mapping. | `projects.transferToCloud(id)` | `POST /api/projects/:id/transfer/to-cloud` `project:admin` · Self-hosted |
| Request a transfer from Cloud; fixed-scope Cloud mapping limits apply. | `projects.transferToSelfHosted(id)` | `POST /api/projects/:id/transfer/to-self-hosted` `project:admin` · Self-hosted |
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Inspect manual cache mounts or remove selected mounts after a successful managed-cache deployment. | `projects.buildCacheMigration(id, input)` | `POST /api/projects/:id/build-cache/migration` `project:write` |
| Enable or disable automatic same-repository pull request environments. | `projects.configurePreviews(id, input)` | `POST /api/projects/:id/previews` `project:write` |
| Read preview configuration, deployment URLs and reconciliation errors. | `projects.listPreviews(id)` | `GET /api/projects/:id/previews` `project:read` |
| Atomically move literal command variables into the selected environment without overwriting conflicting values. | `projects.migrateCommandEnvironment(id, input)` | `POST /api/projects/:id/env/migrate-commands` `project:write` |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Update resources (POST alias of the PATCH). | HTTP only | `POST /api/projects/:id/resources` `project:write` |
| Read edge readiness for the project. | HTTP only | `GET /api/projects/:id/routing/edge-status` `project:read` |
| Replay and follow an existing routing repair using its sessionId; never starts a repair. | `projects.retryRoutingStream(id, { sessionId })` | `GET /api/projects/:id/routing/retry/stream` `project:read` |
| Answer an edge setup prompt for the project. | HTTP only | `POST /api/projects/:id/routing/ensure-edge/respond` `project:write` |
| Stream edge setup for the project. | HTTP only | `POST /api/projects/:id/routing/ensure-edge/stream` `project:write` |
{/* api-operations:end */}
---
# Backups and restores
URL: https://openship.io/docs/api/backups.md
Create backup policies, inspect runs, and restore data.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Backups API manages a project's backup **policies** (what to back up and on what schedule), the **runs**
they produce, and the **restores** that put a run's data back. It pairs with the
[Backup Destinations API](/docs/api/backup-destinations) (where backups are stored) — in the dashboard this
is the project's **Backups** tab, and from the terminal it's the [`openship backup`](/docs/cli/projects)
command.
The routes are split across a few prefixes: policy **creation and listing** are project-scoped
(`/api/projects/:projectId/backup-policies`), while an **existing** policy, run, or restore is addressed by
its own id (`/api/backup-policies/:id`, `/api/backup-runs/:id`, `/api/backup-restores/:id`). The inbound
`POST /api/webhooks/backup` trigger lives on its own unauthenticated prefix. Available on both self-hosted
and cloud instances; the project-scoped policy and run routes proxy to Openship Cloud for cloud projects.
## Create a backup policy
A policy binds a project (optionally a single service) to a [destination](/docs/api/backup-destinations),
plus an optional schedule and retention rules. The request body is read inline (there is no TypeBox schema
file for this module); `destinationId` is the only required field.
```ts
const result = await ship.backups.createPolicy("proj_123", {
destinationId: "dst_abc",
cronExpression: "0 3 * * *",
retainCount: 7,
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/backup-policies" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"destinationId":"dst_abc","cronExpression":"0 3 * * *","retainCount":7}'
```
## Update a policy
`PATCH` accepts only the allow-listed fields below — `projectId`, `serviceId`, and `createdBy` cannot be
changed, and the webhook token is controlled through the `enableWebhook` / `rotateWebhookToken` flags rather
than written directly. Unknown fields are dropped.
```
PATCH /api/backup-policies/:policyId
```
## Trigger a backup manually
```ts
const run = await ship.backups.run("policy_123");
console.log(run);
```
```bash
curl -X POST "$OPENSHIP_URL/api/backup-policies/policy_123/run" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Kicks off a run for the policy immediately. Returns `{ data: { runId } }` — follow it with the run stream.
```ts
const result = await ship.backups.run("bkp_abc");
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/backup-policies/bkp_abc/run" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Protect a run from retention
Retention prune drops runs past a policy's `retainCount` / `retainDays`. Lock a run to keep it, or release
the lock so it becomes eligible again.
```
POST /api/backup-runs/:runId/protect
```
## Stage and apply a restore
Restoring is two steps. **Prepare** stages the restore and returns a one-time `confirmationToken`; **apply**
echoes that token back to actually run the (destructive) restore. This guards against accidental
re-submits.
```
POST /api/backup-runs/:runId/restore/prepare
```
The response is `{ data: { restoreId, confirmationToken } }`. Pass both to apply:
```
POST /api/backup-restores/:restoreId/apply
```
Cancel a staged or in-flight restore with `POST /api/backup-restores/:restoreId/cancel`
(`openship backup restore cancel rst_123`).
## Live progress (SSE)
Both runs and restores expose a Server-Sent Events channel that emits a `snapshot` event with the current
row immediately, then live `transition` / `progress` events, and a final `complete` event. Terminal
statuses are `succeeded`, `failed`, `cancelled`, and `server_error`; the stream closes once one is reached
(or right away if the row is already terminal).
```
GET /api/backup-runs/:runId/stream
GET /api/backup-restores/:restoreId/stream
```
## Trigger a backup by webhook
`POST /api/webhooks/backup` is the one **unauthenticated** route — the per-policy webhook token *is* the
credential, sent as a bearer header (enable it via `enableWebhook` on the policy). There is no request body.
On success it returns `{ data: { runId } }`; every failure returns an opaque `404` so a probe can't tell a
bad token from a disabled policy. The route is rate-limited to blunt trigger-flood abuse.
```
POST /api/webhooks/backup
```
```bash
curl -X POST "$OPENSHIP_URL/api/webhooks/backup" \
-H "Authorization: Bearer $POLICY_WEBHOOK_TOKEN"
```
## Errors
`createPolicy` / `updatePolicy` validate the cron up front so an unparseable schedule can't silently disable
the policy. Fix the expression (e.g. `0 3 * * *`) and retry.
Applying a restore without the exact token returned by `restore/prepare` is rejected. Re-run prepare to get
a fresh token if you've lost it.
The `:id` doesn't belong to your organization (or was deleted) — the same opaque `404` the webhook returns
for a bad token. List runs with `GET /api/projects/:projectId/backup-runs` to get valid IDs.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Stream backup execution progress. | `backups.streamRun(id, options?)` | `GET /api/backup-runs/:runId/stream` `backup_destination:backup_run:read` |
| Stream restore progress. | `backups.streamRestore(id, options?)` | `GET /api/backup-restores/:restoreId/stream` `backup_destination:backup_restore:read` |
| List backup policies for the requested source. | `backups.listPolicies(id)` | `GET /api/projects/:projectId/backup-policies` `project:write` |
| Create a backup policy and retention configuration. | `backups.createPolicy(id, input)` | `POST /api/projects/:projectId/backup-policies` `project:write` |
| List recorded backup runs using typed filters. | `backups.listRuns(id, input?)` | `GET /api/projects/:projectId/backup-runs` `project:write` |
| Change a backup policy. | `backups.updatePolicy(id, input)` | `PATCH /api/backup-policies/:policyId` `backup_destination:backup_policy:write` |
| Remove a backup policy. | `backups.removePolicy(id)` | `DELETE /api/backup-policies/:policyId` `backup_destination:backup_policy:write` |
| Trigger a policy’s backup now. | `backups.run(id, input?)` | `POST /api/backup-policies/:policyId/run` `backup_destination:backup_policy:write` |
| Read a backup run and its result. | `backups.getRun(id)` | `GET /api/backup-runs/:runId` `backup_destination:backup_run:read` |
| Protect or unprotect a run from retention pruning. | `backups.protectRun(id, input?)` | `POST /api/backup-runs/:runId/protect` `backup_destination:backup_run:write` |
| Stage and validate a restore without applying it. | `backups.prepareRestore(id, input?)` | `POST /api/backup-runs/:runId/restore/prepare` `backup_destination:backup_run:admin` |
| Read a restore session and its confirmation requirements. | `backups.getRestore(id)` | `GET /api/backup-restores/:restoreId` `backup_destination:backup_restore:read` |
| Apply a prepared restore using the required confirmation. | `backups.applyRestore(id, input)` | `POST /api/backup-restores/:restoreId/apply` `backup_destination:backup_restore:admin` |
| Request cancellation of a restore. | `backups.cancelRestore(id)` | `POST /api/backup-restores/:restoreId/cancel` `backup_destination:backup_restore:admin` |
{/* api-operations:end */}
---
# Service terminal
URL: https://openship.io/docs/api/service-terminal.md
Issue access tickets and open a service shell.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Service terminal API gives you a live shell inside a service's running container — the same PTY you get
from the dashboard's **Terminal** tab on a service. You first mint a short-lived ticket over normal HTTP,
then open a WebSocket that carries the ticket and streams keystrokes and output. It works in both
deployment modes: on self-hosted instances it's a `docker exec` into the container; on Openship Cloud it's
a shell in your Oblien workspace. The runtime is chosen automatically from the service's active deployment.
## Mint a ticket
```
POST /api/services/terminal/ticket
```
Returns `{ success: true, token, expiresIn }`. The `token` is single-use and expires after `expiresIn`
seconds — mint it right before opening the socket. This route resolves the service and 404s early (before you
burn a WebSocket attempt) if it doesn't exist, isn't yours, or has no active deployment yet.
```bash
curl -X POST "$OPENSHIP_URL/api/services/terminal/ticket" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serviceId":"svc_123"}'
```
There's no working CLI shell yet — `openship service exec` is a stub that prints "coming soon" (the CLI
ships no WebSocket client). Use the dashboard's service **Terminal** tab, which drives these endpoints.
## Open the WebSocket
```
GET /api/services/terminal/ws/:serviceId
```
Connect a WebSocket to this path. Because HTTP middleware that returned `401` would abort the handshake, this
route is public at the HTTP layer and authenticates inside the upgrade instead. Two things gate it:
- **Origin** — the request `Origin` must be in the instance's trusted-origins allowlist, or the socket closes
with `4403`.
- **Identity** — pass the ticket from `/ticket` as a WebSocket **subprotocol**, prefixed with
`openship.terminal.v1+` (e.g. `openship.terminal.v1+`). If no ticket is present, Openship falls back
to the session cookie (dashboard case). To resume a parked session, add a second subprotocol prefixed with
`openship.terminal.resume+`.
Once open, the wire protocol is:
- **Binary frames** are raw PTY bytes — send keystrokes as binary; stdout/stderr arrive as binary.
- **Text frames are JSON control messages.** Client → server: `{"type":"resize","cols":N,"rows":N}`
(cols clamped 1–1000, rows 1–500), `{"type":"ping"}`, `{"type":"close"}`. Server → client:
`{"type":"ready","sessionId","resumeToken","resumed"}` on connect, `{"type":"exit","code","signal"}` when
the shell ends, `{"type":"error","code","message"}`, and `{"type":"pong"}` (also sent as a heartbeat every
~25s).
```bash
# Mint a ticket, then connect with websocat, passing it as a subprotocol:
websocat "wss://your-host/api/services/terminal/ws/svc_123" \
--protocol "openship.terminal.v1+$TICKET" \
-H "Origin: $OPENSHIP_URL"
```
## Errors
The WebSocket signals failures by sending an `{"type":"error"}` frame and then closing with a specific code:
No valid ticket or session, no active organization, or the ticket's service doesn't match the path
`:serviceId`. Mint a fresh ticket (they're single-use and short-lived) and connect immediately.
The service isn't in your active organization, you lack admin on its project, or it has no running container
yet (still deploying, or the project has no active deployment). List services with the
[Services API](/docs/api/services) to confirm it's live.
The service's runtime doesn't offer an interactive shell (`not_supported`), or the `:serviceId` was missing.
You've hit the per-user concurrent-session cap. Close an existing terminal and retry.
The request `Origin` isn't in the trusted-origins allowlist. Connect from the dashboard's own host.
## Operations
## SDK and CLI
Use `client.terminal.openService(serviceId, { origin, onData })` for the same authenticated terminal
protocol as server terminals. The session supports `write`, `resize`, `close`, and a `closed` promise
with the confirmed exit result. See [terminal transport](/docs/api/terminal#sdk-and-cli).
`openship service terminal --project ` opens an interactive PTY. Use `openship service exec "..." --project `
for scripts; it preserves the remote command's exit status.
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Mint a one-shot, short-lived WebSocket auth ticket for a service. | `terminal.openService(id, options)` Remote client | `POST /api/services/terminal/ticket` `terminal:write` |
| WebSocket upgrade — auth happens inside the handshake (ticket subprotocol or session cookie). | `terminal.openService(id, options)` | `GET /api/services/terminal/ws/:serviceId` `Handler authentication` |
{/* api-operations:end */}
---
# Domains and TLS
URL: https://openship.io/docs/api/domains.md
Attach hostnames, verify DNS, and manage certificates.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Domains connect hostnames to a project and track DNS verification and TLS certificates. The SDK takes a
project ID as the first argument when creating or listing domains; REST includes it in the body or query.
## Add a domain
```ts
const result = await ship.domains.create("proj_123", {
hostname: "app.example.com",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/domains" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"projectId":"proj_123","hostname":"app.example.com"}'
```
as a SEPARATE domain — its own row, DNS record, verification and certificate, created as a 301 to the bare domain. The response carries its id in `www` (or the reason it could not be claimed in `wwwError`), and `records` includes its DNS record.', default: 'false' },
redirectTo: { type: 'string', description: 'Answer a redirect to another domain of the SAME project instead of serving the app. Must be one of the project\'s own hostnames; self-targets and loops are refused. Available on Cloud and self-hosted deployments.' },
redirectStatus: { type: 'number', description: 'Redirect code used with redirectTo: 301, 302, 307 or 308.', default: '301' },
}}
/>
After adding, you must point your DNS at Openship and then **verify**. Use `POST /api/domains/preview`
(or `openship domain preview `) to see the exact records to add at your DNS provider first.
## Preview required DNS
Side-effect-free: pass a hostname, get back the records to create. `POST` is used only so the hostname
travels in the body.
```ts
const result = await ship.domains.preview({
hostname: "app.example.com",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/domains/preview" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"hostname":"app.example.com"}'
```
The response's `mode` tells you which setup applies: `selfhosted` (an A record to your server), `cloud`
(a CNAME to Openship Cloud), or `external` (a TXT record only — you front TLS yourself).
## Verify a domain
```ts
const verification = await ship.domains.verify("dom_123");
console.log(verification);
```
```bash
curl -X POST "$OPENSHIP_URL/api/domains/dom_123/verify" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Once DNS is in place, verify it. Openship Cloud checks its routing and ownership records. Self-hosted
verification obtains or reuses the certificate on the deployment server. Domains with external ingress
keep TLS at their upstream proxy.
## Wildcard HTTPS and manual TXT
Wildcard and DNS-01 domains on self-hosted targets use the same operations in the dashboard, SDK and MCP.
Deploy and enable the project first. An external ingress or uploaded certificate keeps its existing TLS flow.
```ts
// "automatic" uses a connected DNS provider. "manual" generates a real ACME TXT.
const attempt = await ship.domains.startDnsChallenge("dom_123", { mode: "manual" });
const current = await ship.domains.dnsChallenge("dom_123");
// Once current.status is "waiting", publish current.record at the DNS provider.
// Then explicitly ask Openship to check it:
await ship.domains.checkDnsChallenge("dom_123", { attemptId: attempt.id });
```
Start and check return **202** with `{ data: attempt }`; they do not hold the HTTP request open for
certificate issuance. Read `GET /api/domains/:id/dns/challenge` until the result settles. It returns
`{ data: null }` before any attempt. The safe attempt includes `id`, `domainId`, `mode`, `status`,
`record`, `expiresAt`, `logs`, `error`, `createdAt` and `updatedAt`. It never includes private keys,
account credentials or serialized ACME orders.
`preparing`, `checking`, `installing` and `cancelling` represent running work. `waiting` needs the operator's
TXT; stop polling until they act. `completed`, `failed`, `cancelled` and `expired` are settled results.
A missing TXT or retryable validation/install error keeps the same order in `waiting` with its error.
Repeated starts reuse an active attempt; check and cancel require its current `attemptId` and reject
a stale ID with **409**. An installation that has already started cannot be cancelled.
Manual renewal uses `startDnsChallenge(id, { mode: "manual", force: true })` and a fresh TXT value.
`cancelDnsChallenge(id, { attemptId })` discards an unfinished manual attempt without removing existing TLS.
Connected-provider mode renews automatically when the SSL job is enabled. See the
[wildcard guide](/docs/guides/custom-domains#wildcard-domains) for DNS names, record cleanup and renewal steps.
## Errors
The DNS records aren't resolving yet, or don't match. DNS can take minutes to hours to propagate. Confirm
the records match `preview` exactly, then retry. The response's `cnameVerified` / `txtVerified` flags tell
you which check is still failing.
The `:id` doesn't belong to your organization (or was deleted). List your domains with `GET /api/domains`
to get valid IDs.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Stream domain verification progress. | `domains.verifyStream(id, input?, options?)` | `POST /api/domains/:id/verify/stream` `domain:write` |
| List domains using the supplied filters. | `domains.list(id)` | `GET /api/domains` `domain:list` |
| Attach a domain using the requested project and routing configuration. | `domains.create(id, input)` | `POST /api/domains` `domain:write` |
| Read one domain record. | `domains.get(id)` | `GET /api/domains/:id` `domain:read` |
| Remove a domain and its routing binding. | `domains.remove(id)` | `DELETE /api/domains/:id` `domain:admin` |
| Run domain verification. | `domains.verify(id, input?)` | `POST /api/domains/:id/verify` `domain:write` |
| Read DNS records required by a domain. | `domains.records(id, input?)` | `GET /api/domains/:id/records` `domain:read` |
| Preview DNS changes before applying them. | `domains.dnsPlan(id, input?)` | `GET /api/domains/:id/dns/plan` `domain:read` |
| Apply the authorized DNS plan. | `domains.dnsApply(id, input?)` | `POST /api/domains/:id/dns/apply` `domain:write` |
| Read the saved DNS certificate attempt, TXT record, deadline and logs. | `domains.dnsChallenge(id)` | `GET /api/domains/:id/dns/challenge` `domain:read` |
| Start automatic provider setup or a manual TXT challenge; reuse an active attempt. Self-hosted targets only. | `domains.startDnsChallenge(id, input)` | `POST /api/domains/:id/dns/challenge` `domain:write` |
| Check the saved attempt's TXT, complete ACME validation and install HTTPS on the serving host. | `domains.checkDnsChallenge(id, input)` | `POST /api/domains/:id/dns/challenge/check` `domain:write` |
| Cancel a manual DNS certificate attempt before installation starts; retain existing certificates. | `domains.cancelDnsChallenge(id, input)` | `POST /api/domains/:id/dns/challenge/cancel` `domain:write` |
| Select the project’s primary domain. | `domains.setPrimary(id)` | `POST /api/domains/:id/primary` `domain:write` |
| Request certificate renewal for a domain record. | `domains.renewSsl(id)` | `POST /api/domains/:id/renew` `domain:write` |
| Check the domain’s current certificate. | `domains.verifySsl(id)` | `POST /api/domains/:id/verify-ssl` `domain:write` |
| Install a supplied certificate and private key. | `domains.uploadCert(id, input)` | `POST /api/domains/:id/certificate` `domain:write` · Self-hosted |
| Preview domain connection requirements. | `domains.preview(input)` | `POST /api/domains/preview` `domain:read` |
| Request renewal for eligible certificates. | `domains.renewAllSsl()` | `POST /api/domains/renew-all` `domain:write` |
| Verify pending domains visible to the caller. | `domains.verifyPending(input?)` | `POST /api/domains/verify-pending` `domain:write` |
{/* api-operations:end */}
---
# Billing
URL: https://openship.io/docs/api/billing.md
Read plans and manage subscriptions, credits, and usage.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Billing covers plans, subscriptions, credits, and usage. Plan listing is public on every installation.
Openship defines its prices, namespace credits, limits and checkout copy. Oblien
collects the payment and applies the saved offer on payment and renewal. Each
subscription owns a managed server and maps to an immutable provider namespace.
Account operations require configured Cloud billing. Self-hosted HTTP routes can proxy a connected user's
Cloud billing account; fixed SDK scopes require a direct compatible Cloud API connection.
See [Cloud compatibility](/docs/api/sdk/compatibility#cloud).
## Select the billing owner
Pass `workspaceId` on billing inputs (as a query parameter for reads and in the
JSON body for writes). It selects one managed server's subscription, balance,
usage, checkout and portal. The server's `cloud.id` is this billing selector;
application placement uses `serverId`. Omission is valid when the organization
has a single managed server. Multiple servers require an explicit choice.
Reads do not create a server or buy a plan. See the
[managed server lifecycle](/docs/api/servers#managed-cloud-servers).
Shared Docker placement uses host measurements for live usage. Provider
namespace allocation is its purchased host capacity, not project storage use.
Resize that host through `servers.previewResize` and `servers.resize`.
### Actions budget
`billing.getActionsBudget()` reads the organization's separate prepaid workflow
budget. It has no `workspaceId` selector and cannot spend a managed server's
monthly allowance. The response includes dollar conversion units, available and
used provider credits, live usage rates, estimated VM minutes, runner readiness,
and recent deposits. CPU, measured memory and transfer consume the same balance.
Amounts retain sub-cent precision; divide by `unitsPerDollar` for display. An
unavailable balance or estimate is `null`, not zero.
`getActionsPurchase({ purchaseId })` verifies the saved payment with the provider.
Verified fulfillment updates deposit history; Oblien owns the spendable balance
and usage debits. Payment recovery enables the Cloud runner profiles separately;
confirmed deposits remain visible while setup retries. Workflow permissions do
not grant access to these billing reads or writes. Responses exclude provider
credentials and payment URLs; checkout URLs are returned only by explicit purchase
operations. Purchases require Cloud billing configuration and valid live rates;
check `purchasesAvailable` before offering checkout. See
[Cloud Actions funding](/docs/guides/actions#cloud-actions-funding).
## List plans
```ts
const catalog = await ship.billing.listPlans();
console.log(catalog.plans);
```
```bash
curl "$OPENSHIP_URL/api/billing/plans"
```
Public on every deploy mode. The response is the resolved pricing catalog: one
entry per tier in display order, with prices in the currency's **minor units**
(cents), the numeric limits enforcement reads, and finished localized feature
strings.
Pass `?locale=` — or send an `Accept-Language` header — to pick the
language. An unsupported tag falls back to its base language, then to English;
the locale that was actually used comes back in the response.
The envelope is `{ data: { provider: "oblien", locale, annual, ui, plans, custom } }`. `annual.enabled` reports
whether annual terms are published; read the actual yearly price from each plan.
`ui` carries the short labels a pricing UI needs — the `/mo` suffix, the
"Custom" and "Free" words, the "Most popular" badge — already translated, because
a marketing site may have no dictionary of its own.
`custom` supplies the supported resource ranges and additional monthly rates.
When it is absent, that API does not offer self-service Custom configurations.
Each entry in `plans` looks like:
Two conventions matter when you render this:
- **`price.monthly` is in cents**, and `null` means the tier is priced per
contract — pair it with `contactSales` and render the `ui.custom` label rather
than a number.
- **A `null` application limit means "uncapped"**, never zero. An absent traffic
capacity is unknown; custom offers do not inherit platform traffic tiers. `annual.enabled` is
`false` while annual terms are unpublished, and every `price.annual` is `null`
to match — keep annual affordances hidden while it is.
Prices, credits, packs and limits come from Openship's server catalog in
`@repo/core`. The API, dashboard and [pricing page](/pricing) read the same
published catalog. Monthly paid plans are $5 / $20 / $39 / $99; annual checkout is
hidden until explicit yearly terms are published. Linked local installations
read the SaaS public catalog without sending local credentials.
New checkouts send a generic Oblien `offer`. It contains the server-selected
price, credits, grace and VM caps; versioned metadata records the Openship plan,
application limits, organization and immutable namespace. Customers cannot
submit their own price, offer or namespace. Existing Oblien catalog subscriptions
remain readable, while all new purchases use Openship's catalog.
The payment funds the reseller's Oblien wallet. It does not change the reseller
account's platform subscription. Each customer subscription belongs to its
namespace. Renewals use the saved offer and application limits, so catalog edits
do not change existing customers' terms. Grace defaults to zero and can be
configured in the catalog. Credits are independent of USD price and are not a
promise of fixed CPU minutes.
Each subscription purchases one managed server with its advertised CPU, RAM
and disk. Projects and services share that server, with no count cap on new
paid offers. Container limits are ceilings inside the server, not additional
VM reservations. Oblien enforces the saved offer's host limits. Openship does
not rewrite saved purchase terms on renewal.
## Quote Custom resources
Use `billing.quoteCustomPlan` (`GET /api/billing/subscription/quote`) to calculate
a monthly offer. The input is `cpuCores`, `memoryMb` and `diskGb`; resource ranges
come from the catalog. This permission-gated read does not reserve capacity,
create a server, or start checkout.
```ts
const quote = await ship.billing.quoteCustomPlan({
cpuCores: 1,
memoryMb: 4096,
diskGb: 50,
});
console.log(quote.priceCents, quote.monthlyCredits, quote.breakdown);
// After the customer reviews the monthly terms:
const { checkoutUrl } = await ship.billing.createSubscription({
workspaceId: 'cws_...',
planTierId: quote.basePlanTierId,
interval: 'monthly',
custom: { resources: quote.resources, quoteReference: quote.reference },
idempotencyKey: crypto.randomUUID(),
});
```
Custom uses the least expensive retail bundle plus any extra resources. The
selected allocation stays exact, even when a larger bundle supplies a discount.
Checkout recalculates every term. A changed price, resource selection or
fingerprint returns `BILLING_QUOTE_CHANGED`; fetch and review a fresh quote before
retrying. Client-supplied prices, credits and provider identities are rejected.
Paid state identifies Custom with `plan.configuration` and
`subscription.configuration`. `offerReference` identifies the saved terms;
`tier` remains the base bundle used for application allowances. Display the
saved plan's name, price and resource limits, rather than its current catalog
bundle. Renewals preserve that saved contract.
After a changed subscription is paid, existing server resources are applied
through `servers.previewResize` and `servers.resize`. Review the affected
projects and confirm their restart. Payment alone does not restart an existing
server. Disk shrink is rejected before checkout and resize. New subscriptions
continue through the existing managed-server provisioning flow.
## Subscription and usage
```ts
const state = await ship.billing.getState({ workspaceId: 'cws_...' });
console.log(state);
```
```bash
curl "$OPENSHIP_URL/api/billing/state?workspaceId=cws_..." \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
`GET /state` is the snapshot the dashboard's Billing screen renders in one call:
the active tier, the period you're in, the credit balance, and how much of the
plan's capacity is in use. `GET /usage` returns the metered series behind the
usage chart. `GET /subscription` returns the entitlement tier/status/period and
a `subscription` object, or `null` if never subscribed. The object includes
`tier`, `status`, `interval` (`monthly` or `annual`), `currentPeriod`,
`cancelAtPeriodEnd`, `canceledAt`, and an optional `pendingChange`. A scheduled cancellation can still have
an active entitlement until the paid period ends.
`billing.getCreditAlerts()` (`GET /api/billing/credit-alerts`) reads credit state
across the current organization's managed servers without selecting one. Its
`items` identify each subscription and preserve Oblien's alert state and
thresholds. `unavailableWorkspaceIds` identifies failed reads; those balances
are unknown, not zero. The read does not provision servers or buy credits.
`POST /subscription` accepts `{ planTierId, interval, workspaceId?, idempotencyKey?, custom? }` and returns
`{ checkoutUrl }`. Use a stable request key when retrying the same purchase.
This starts a new subscription only when the selected server has no live
subscription. Existing contracts, including those scheduled to cancel, return
`409 BILLING_PLAN_CHANGE_UNAVAILABLE`; they must not be replaced at full price.
Use the plan-change operations below for a live reseller subscription. A browser
return URL does not grant access: signed Oblien events and fresh entitlement
reads confirm the current plan.
### Change an existing server's plan
```ts
const quote = await ship.billing.previewSubscriptionChange({
workspaceId: 'cws_...',
planTierId: 'pro',
idempotencyKey: crypto.randomUUID(),
});
// Present quote.current/next, amountDueNow, effectiveAt and resize to the user.
// Only after explicit payment and affected-project restart confirmation:
const change = await ship.billing.confirmSubscriptionChange({
workspaceId: 'cws_...',
quoteId: quote.id,
confirmRestart: true,
});
const latest = await ship.billing.getSubscriptionChange({
workspaceId: 'cws_...', changeId: change.id,
});
// If the user cancels a pending, cancelable change:
// await ship.billing.cancelSubscriptionChange({ workspaceId: 'cws_...', changeId: change.id });
```
| Operation | Route | Permission |
| --- | --- | --- |
| Preview | `POST /api/billing/subscription/change/preview` | `billing:write` |
| Confirm | `POST /api/billing/subscription/change` | `billing:admin` |
| Status | `GET /api/billing/subscription/change?workspaceId=...&changeId=...` | `billing:read` |
| Cancel | `POST /api/billing/subscription/change/cancel` | `billing:admin` |
Preview and confirmation also require write access to the server and affected
projects. The backend derives the provider namespace and trusted retail offer.
Custom changes accept the same `custom: { resources, quoteReference }` selection
as checkout. They preserve the existing interval; Custom is monthly only.
Amounts are USD cents, as for other billing prices.
Higher prices are prorated and activate after confirmed payment. Lower or equal
prices are scheduled for the next paid renewal. `queued`, `payment_pending`,
`scheduled` and other pending states do not grant the new plan. A validated
`paymentUrl` may be shown while payment is pending. Only `applied` confirms the
new terms; `serverUpdate` distinguishes pending/queued capacity work from a
required fresh restart review. The existing server operation supplies progress
and recovery. Disks cannot shrink in place.
Quotes expire in at most ten minutes. Use a new preview key after expiry or a
changed quote. Retry an uncertain confirmation with the same `quoteId`; Openship
persists its provider retry key before acceptance. Signed events and background
recovery continue it after navigation or a restart. No client-supplied price,
namespace, credits or metadata is accepted. MCP exposes preview and status;
payment confirmation stays in Billing.
`POST /cancel` stops renewal at period end and returns `{ cancelAt, subscription }`.
`POST /resume` undoes a scheduled cancellation and returns `{ subscription }`.
Both are safe to repeat. Cancellation preserves the paid period; it does not
delete resources. An ended subscription requires a new checkout.
Cancel an existing pending plan change before canceling or resuming renewal.
```ts
await ship.billing.cancelSubscription();
const { subscription } = await ship.billing.getSubscription();
console.log(subscription?.cancelAtPeriodEnd);
await ship.billing.resumeSubscription();
```
## Recover unfinished payments
```ts
const pending = await ship.billing.listCheckouts({ workspaceId: 'cws_...' });
```
Cloud can omit `workspaceId` to list unfinished payments across the current
organization. The connected desktop and self-hosted dashboard can also use Cloud
inventory IDs or list the account's payments without creating local execution links.
Explicit local links retain their local server and workspace IDs. Locally scoped
SDK and automation callers must use an authorized local link; their credentials do
not grant access to the owner's Cloud inventory.
Listing reads saved offers and provider status; it does not replay a purchase.
Each item includes its recovery `id`, server, saved price, state, `canResume`
and `canCancel`.
After the customer chooses an action, call `resumeCheckout({ workspaceId, id })`
or `cancelCheckout({ workspaceId, id })`. Both require the exact item and server.
Resume reuses the original request and payment URL. A `ready` result includes
`checkoutUrl`; redirect to it unchanged and keep it out of logs and analytics.
Cancellation uses the matching provider capacity quote. `canceling` means the
outcome is still pending: retry the same operation, without starting another
checkout or deleting the server. `expired` confirms that the checkout is closed.
`processing` means payment has been submitted and must be verified separately.
Cancellation does not cancel an existing paid subscription. Payments without a
supported cancellation action can be resumed, allowed to expire, or referred to support.
## Verify a checkout
```ts
const checkout = await ship.billing.getCheckout({ checkoutId: 'cs_...' });
```
`GET /api/billing/checkout?checkoutId=cs_...` requires `billing:read`. Openship
resolves the current organization's namespace before asking Oblien about that
specific session. Another organization's checkout cannot be read. The response
contains `id`, `kind`, `status`, `paymentStatus`, `fulfilled`,
`fulfillmentStatus` and `creditsGranted` (milli-credits), without reseller wallet
or payment-provider identifiers.
The success URL includes `session_id`. A return URL or a previously active
subscription is not proof of the new payment. The dashboard verifies payment
and completed fulfillment. Credit purchases require a positive net credit grant;
monthly subscriptions require the expected saved offer and paid capacity, and
the welcome waits for the managed server to be ready.
Unfinished delivery stays pending, while refunds, disputes and failures are
shown explicitly. Webhook events and fresh provider reads remain authoritative.
## Resource usage
```ts
const resources = await ship.billing.getResources();
if (resources.compute.status === "available") {
console.log(resources.compute.cpuHours, resources.compute.memoryGbHours);
}
if (resources.edge.status === "available") {
console.log(resources.edge.bandwidthGb, resources.edge.limits.bandwidthGb);
console.log(resources.edge.requests);
}
```
```bash
curl "$OPENSHIP_URL/api/billing/resources" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Requires `billing:read`. Openship resolves the authenticated organization's
namespace; callers do not supply a namespace or another customer's account.
The REST response wraps the resource snapshot in `{ data }`.
`compute` reports vCPU-hours, memory GB-hours, disk I/O GB, and network GB across
builds and running apps in the billing period. These measurements consume the
shared Cloud allowance; they are not separate included runtime-hour quotas.
`edge` reports request counts, inbound and outbound bandwidth, total bandwidth,
and the monthly bandwidth limit in `limits.bandwidthGb`. Each group includes
its own `period`, since edge allowances reset monthly even on annual plans.
Read each group's `status` before displaying its measurements. An unavailable
provider returns `"unavailable"` and `null` measurements for that group while
the other group can remain available. A `null` measurement does not mean zero
usage or unlimited resources. `measuredAt` identifies the snapshot time.
## Managed server capacity
Each subscription purchases one managed server. Container CPU and memory caps
share that server; they do not allocate a new VM per project. Read measured
usage and review an upgrade through the [server API](/docs/api/servers).
A resize preview names the affected projects, and applying it requires explicit
restart confirmation. The worker preserves stopped applications and verifies
the provider allocation before reporting completion.
## Top-ups and the portal
`GET /topup-packs` lists the one-shot credit packs from the same catalog;
`POST /topup` opens Checkout for one. Credits bought this way sit on top of the
plan's allowance; only the unused purchased remainder survives renewal.
Top-up eligibility in checkout and billing state requires an active or trialing
paid subscription and a current Oblien entitlement of `active` or `credit_exhausted`. An expired or
past-due entitlement cannot qualify through a stale active subscription record;
an unavailable entitlement read blocks the purchase.
A top-up cannot increase resource/project/build limits or activate a subscription.
Openship never resets or grants credits itself.
`POST /portal` returns `{ portalUrl }` for this organization's invoices, payment
methods, and cancellation. It requires `billing:admin`, like cancel/resume,
because the hosted portal can stop renewal. It never exposes the API-key owner's
billing portal. Shared legacy billing must be separated before management or
purchases can proceed.
Portal/cancel/resume remain available when new purchases are disabled. The
`capabilities` object in billing state reports which actions are available.
Organization deletion still requires support to coordinate provider billing
closure and resource cleanup.
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the plan catalog, optionally localized. | `billing.listPlans(input?)` | `GET /api/billing/plans` `Handler authentication` |
| Read current billing state. | `billing.getState(input?)` | `GET /api/billing/state` `billing:read` |
| Read provider credit alerts across the organization's managed servers, with unavailable subscriptions identified separately. | `billing.getCreditAlerts()` | `GET /api/billing/credit-alerts` `billing:read` |
| Verify a checkout and its credit delivery for this organization. | `billing.getCheckout(input)` | `GET /api/billing/checkout` `billing:read` |
| List unfinished server payments with saved offer terms and verified recovery actions. Does not start a payment or expose hosted URLs. | `billing.listCheckouts(input?)` | `GET /api/billing/checkouts` `billing:read` |
| Resume the exact saved checkout, or report that it was submitted or expired. Browser payment authorization is still required. | `billing.resumeCheckout(input)` | `POST /api/billing/checkout/resume` `billing:write` |
| Request provider-confirmed cancellation of an unfinished capacity checkout. Unknown outcomes remain tracked and retryable. | `billing.cancelCheckout(input)` | `POST /api/billing/checkout/cancel` `billing:admin` |
| Read compute usage, edge traffic, and bandwidth limits. | `billing.getResources(input?)` | `GET /api/billing/resources` `billing:read` |
| Read subscription and renewal state. | `billing.getSubscription(input?)` | `GET /api/billing/subscription` `billing:read` |
| Quote a Custom server's monthly price and usage allowance without purchasing it. | `billing.quoteCustomPlan(input)` | `GET /api/billing/subscription/quote` `billing:read` |
| Start hosted checkout for a new or ended server subscription. | `billing.createSubscription(input)` | `POST /api/billing/subscription` `billing:write` |
| Save an expiring provider quote with proration, effective date and affected-project restart review; no charge. | `billing.previewSubscriptionChange(input)` | `POST /api/billing/subscription/change/preview` `billing:write` |
| Confirm a saved plan-change quote and restart consent. Upgrades activate after payment; downgrades wait for paid renewal. | `billing.confirmSubscriptionChange(input)` | `POST /api/billing/subscription/change` `billing:admin` |
| Read the selected server's provider plan-change and capacity-update status. | `billing.getSubscriptionChange(input)` | `GET /api/billing/subscription/change` `billing:read` |
| Cancel a pending, cancelable change while preserving the underlying subscription. | `billing.cancelSubscriptionChange(input)` | `POST /api/billing/subscription/change/cancel` `billing:admin` |
| Stop subscription renewal at the end of the paid period. | `billing.cancelSubscription(input?)` | `POST /api/billing/cancel` `billing:admin` |
| Resume a scheduled subscription renewal. | `billing.resumeSubscription(input?)` | `POST /api/billing/resume` `billing:admin` |
| Create a credit top-up checkout. | `billing.createTopup(input)` | `POST /api/billing/topup` `billing:write` |
| List available credit packs. | `billing.listTopupPacks()` | `GET /api/billing/topup-packs` `billing:read` |
| Create a billing portal session. | `billing.createPortal(input?)` | `POST /api/billing/portal` `billing:admin` |
| Read billable usage for the requested period. | `billing.getUsage(input?)` | `GET /api/billing/usage` `billing:read` |
| Read detailed allowance allocation and consumption. | `billing.listAllowanceDetail(input?)` | `GET /api/billing/allowances` `billing:read` |
### Actions budget
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the separate prepaid Actions balance, runner rates and recent deposits. Amounts use unitsPerDollar; no namespace or checkout is created. | `billing.getActionsBudget()` | `GET /api/billing/actions` `billing:read` |
| Reconcile an owned Actions purchase with its verified provider receipt. Returns payment state without a payment URL. | `billing.getActionsPurchase(input)` | `GET /api/billing/actions/purchase` `billing:read` |
| Start a prepaid Actions checkout with an approved deposit and idempotency key. Requires configured Cloud billing and valid live usage rates. | `billing.createActionsCheckout(input)` | `POST /api/billing/actions/checkout` `billing:write` |
| Resume the original Actions checkout without creating another payment. Requires configured Cloud billing and valid live usage rates. | `billing.resumeActionsCheckout(input)` | `POST /api/billing/actions/checkout/resume` `billing:write` |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Receive authenticated Oblien billing events. | HTTP only | `POST /api/billing/oblien-webhook` `Handler authentication` |
| Retired Stripe webhook; returns 410 without changing billing. | HTTP only | `POST /api/billing/webhook/stripe` `Handler authentication` |
{/* api-operations:end */}
---
# Updates
URL: https://openship.io/docs/api/updates.md
Inspect available project updates and apply them through the deployment workflow.
Updates compare a project's deployed version with its upstream source. Listing does not redeploy anything.
Only projects visible to the caller are included.
## Find available updates
```ts
const updates = await ship.updates.list({ behindOnly: true });
console.log(updates);
```
```bash
curl "$OPENSHIP_URL/api/updates?behind=1" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The SDK's `behindOnly` boolean maps to REST's `behind=1` filter. Omit it to include projects that are
already current or do not support upstream comparison.
## Refresh upstream information
```ts
const scan = await ship.updates.scan();
console.log(scan.scanned, scan.supported);
```
```bash
curl -X POST "$OPENSHIP_URL/api/updates/scan" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The scan returns `scanned` and `supported` counts. Upstream results are cached; the deployed side is read
from current project state when updates are listed.
## Apply an update
```ts
const submitted = await ship.updates.apply("proj_123");
console.log(submitted.deployment_id, submitted.project_id);
```
```bash
curl -X POST "$OPENSHIP_URL/api/updates/proj_123/apply" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Applying uses the existing deployment workflow with an update trigger. It returns deployment and project
IDs, not proof that the new version is ready. [Follow the deployment](/docs/api/deployments#wait-decisions-and-cancellation)
and handle its final outcome.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List update status; behindOnly filters to available updates. | `updates.list(input?)` | `GET /api/updates` `updates:read` |
| Refresh the organization’s update scan. | `updates.scan()` | `POST /api/updates/scan` `updates:write` |
| Apply an available update to the specified project ID. | `updates.apply(id)` | `POST /api/updates/:projectId/apply` `project:write` |
{/* api-operations:end */}
---
# Authentication
URL: https://openship.io/docs/api/auth.md
Browser sessions, OAuth discovery, and authentication handoffs.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Auth API is how Openship signs users in and keeps their session. Almost everything here is served by
[Better Auth](https://better-auth.com) through a single catch-all — email/password sign-in and sign-up, OAuth,
the organization/member/invitation endpoints, and the MCP OAuth authorization server. A small set of
**desktop-only** endpoints sit in front of it to bootstrap a zero-auth local session and hand off cloud sign-in
to the downloadable app.
This module is consumed almost entirely by the dashboard (and, in desktop mode, the Electron host) — you rarely
call it directly. For programmatic API access, mint a personal access token instead
([`openship token create`](/docs/cli/access)) and use it as a bearer header. See the
[API overview](/docs/api) and [Auth & sessions](/docs/security/auth) for the full model.
## The Better Auth catch-all
The last route, `GET|POST /api/auth/*`, forwards the raw request to Better Auth's handler. Everything a normal
sign-in flow needs lives here — there is no separate schema in this module because Better Auth owns the request
and response shapes. The endpoints it serves (all under `/api/auth`) include:
- **Credentials** — `POST /sign-in/email`, `POST /sign-up/email`, and `POST /sign-out`. Passwords are
8–128 characters. Email verification and password reset use codes through
`POST /email-otp/send-verification-otp`, `POST /email-otp/verify-email`, and
`POST /email-otp/reset-password`; delivery requires working instance mail or Cloud mail.
- **OAuth** — `POST /sign-in/social` and `GET /callback/:provider` for GitHub and Google (each enabled only
when its client ID/secret is set).
- **Passkeys** — `GET /passkey/generate-register-options`, `POST /passkey/verify-registration`,
`GET /passkey/generate-authenticate-options`, `POST /passkey/verify-authentication`,
`GET /passkey/list-user-passkeys`, and `POST /passkey/delete-passkey`. Use the Better Auth browser
client to perform the WebAuthn ceremony; raw credentials are never a substitute for it.
- **Two-factor authentication** — `POST /two-factor/enable` returns an authenticator URI and recovery
codes after checking the current password. `POST /two-factor/verify-totp` confirms enrollment or a
pending login. `POST /two-factor/verify-backup-code` consumes a recovery code. Disabling protection
(`POST /two-factor/disable`) and replacing codes (`POST /two-factor/generate-backup-codes`) require
the current password. OAuth-only accounts can add their first password through
`POST /account-security/set-password` with a recent authenticated session.
- **Organizations** — `/organization/*`: create, `set-active`, `list`, `invite-member`, `accept-invitation`,
`update-member-role`, `remove-member`, `leave`, and more. Member-listing reads are additionally shielded so
restricted/member roles can't read admin-tier data.
- **MCP OAuth 2.1** — `/mcp/authorize`, `/mcp/token`, `/mcp/register` (dynamic client registration),
`/mcp/get-session`, plus discovery at `/.well-known/oauth-authorization-server` and
`/.well-known/oauth-protected-resource` (also re-served at the origin root). See the [MCP API](/docs/api/mcp).
Better Auth's organization plugin only carries the role label (`owner`, `admin`, `member`, or `restricted`).
The actual authorization for the rest of the API is resolved against resource grants — see
[Permissions](/docs/security/permissions).
For an account with 2FA enabled, a primary sign-in returns `{ "twoFactorRedirect": true }` instead of
a usable session. Preserve the signed challenge cookie and submit an authenticator or recovery code;
only successful verification issues the session. Social callbacks redirect to the dashboard's
`/two-factor` page and resume their validated destination after verification. Account security endpoints
are available only where local accounts are hosted, including Openship Cloud's account service and
self-hosted VPS installations. See [Auth & sessions](/docs/security/auth#two-factor-authentication).
## Get the current session
```
GET /api/auth/get-session
```
Returns the active session and user as JSON, or `401` when unauthenticated. In zero-auth desktop mode
(self-hosted onboarding, no password), a miss triggers an inline bootstrap: Openship provisions the local admin
user, mints a session, sets the cookie on the response, and returns it — so the dashboard's first navigation
succeeds instead of looping to `/login`.
```bash
curl "$OPENSHIP_URL/api/auth/get-session" \
-H "Cookie: openship.session_token="
```
## Desktop session bootstrap
`GET /api/auth/desktop-login` mints a session for the zero-auth local admin and redirects to the dashboard.
It is called once, right after self-hosted onboarding completes; if the instance isn't in zero-auth mode it
redirects to `/login` instead. No request body.
## Cloud sign-in handoff (desktop)
When the downloadable app signs in "with Cloud", the Electron host runs a PKCE flow and the API brokers it. The
sequence is: register the nonce, open the system browser, poll, then claim.
```
POST /api/auth/desktop-auth-start
```
Guarded by the internal shared-token middleware — only the Electron host may register a nonce. Validated inline
(there is no TypeBox schema module for auth); all three fields are required strings:
The remaining steps take query parameters, not bodies:
- `GET /api/auth/cloud-callback?code=&state=` — the cloud provider redirects here. With `state`
it runs the desktop PKCE exchange and resolves the pending nonce; without `state` it runs the simpler browser
exchange and sets the cookie directly. `code` is required.
- `GET /api/auth/desktop-auth-poll?nonce=` — Electron polls until the status is `resolved`, then opens
the claim URL. `nonce` is required.
- `GET /api/auth/desktop-claim?code=` — exchanges the one-time claim code for a session cookie (set via
the `Set-Cookie` header for cross-version Electron reliability) and redirects to the dashboard. `code` is
required.
## Errors
`GET /api/auth/get-session` returns this when there's no valid session and the instance is not in zero-auth
mode. Sign in through the dashboard, or send a valid session cookie / bearer token.
`POST /api/auth/desktop-auth-start` rejects a body that's missing any of the three fields. The poll and claim
routes return `400` similarly when their required query parameter is absent, and claim returns `400 Claim
expired` once the one-time code has been used or has timed out.
`POST /api/auth/*` shares a 10/min per-IP bucket. Sign-in/sign-up loops that hammer it will be throttled before
the default API limit fires.
## Operations
{/* api-operations:start */}
| Operation | REST API |
| --- | --- |
| Handle browser sessions and authentication through Better Auth. | `GET /api/auth/*` `Handler authentication` |
| Complete a browser-bound Cloud repository authorization; ordinary GitHub sign-in callbacks remain handled by Better Auth. | `GET /api/auth/callback/github` `Handler authentication` |
| Handle sign-in, account, and session mutations through Better Auth. | `POST /api/auth/*` `Handler authentication` |
| Exchange a cloud auth `code` for a local session cookie. | `GET /api/auth/cloud-callback` `Handler authentication` |
| Electron polls this by `nonce` until the cloud sign-in resolves. | `GET /api/auth/desktop-auth-poll` `Handler authentication` |
| Register a `(nonce, state, PKCE verifier)` tuple before the system browser opens. | `POST /api/auth/desktop-auth-start` `Internal operator` |
| Exchange a one-time claim `code` for a session cookie, then redirect. | `GET /api/auth/desktop-claim` `Handler authentication` |
| Mint a session for the zero-auth local admin and redirect to the dashboard. | `GET /api/auth/desktop-login` `Handler authentication` |
| Return the current session; in zero-auth desktop mode, bootstrap one on first hit. | `GET /api/auth/get-session` `Handler authentication` |
| Read a safe preview of a team invitation. | `GET /api/auth/invitation-preview/:id` `Handler authentication` |
| Read the public keys used to verify MCP OAuth tokens. | `GET /api/auth/mcp/jwks` `Handler authentication` |
| Read the identity associated with an MCP OAuth token. | `GET /api/auth/mcp/userinfo` `Handler authentication` |
| Accept an invitation through the browser session boundary. | `POST /api/auth/organization/accept-invitation` `Handler authentication` |
| Cancel a pending invitation through the browser session boundary. | `POST /api/auth/organization/cancel-invitation` `Handler authentication` |
| Invite a member through the browser session boundary. | `POST /api/auth/organization/invite-member` `Handler authentication` |
| Leave the active organization. | `POST /api/auth/organization/leave` `Handler authentication` |
| Reject a pending invitation through the browser session boundary. | `POST /api/auth/organization/reject-invitation` `Handler authentication` |
| Remove a member through the browser session boundary. | `POST /api/auth/organization/remove-member` `Handler authentication` |
| Update a member role through the browser session boundary. | `POST /api/auth/organization/update-member-role` `Handler authentication` |
| Handle sign-up with the installation's account-creation policy. | `POST /api/auth/sign-up/*` `Handler authentication` |
| Discover the OAuth authorization server. | `GET /.well-known/oauth-authorization-server` `Public` |
| Discover the OAuth authorization server. | `GET /.well-known/oauth-authorization-server/api/mcp` `Public` |
| Discover the OAuth authorization server. | `GET /.well-known/oauth-authorization-server/api/proxy/api/mcp` `Public` |
| Discover OAuth metadata for this protected resource. | `GET /.well-known/oauth-protected-resource` `Public` |
| Discover OAuth metadata for this protected resource. | `GET /.well-known/oauth-protected-resource/api/mcp` `Public` |
| Discover OAuth metadata for this protected resource. | `GET /.well-known/oauth-protected-resource/api/proxy/api/mcp` `Public` |
| Close a completed browser authentication handoff. | `GET /auth/callback/close` `Browser callback` |
| Complete the GitHub App browser handoff using installation state. | `GET /auth/callback/install` `Browser callback` |
{/* api-operations:end */}
---
# GitHub
URL: https://openship.io/docs/api/github.md
Connect GitHub accounts, repositories, and App sources.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The GitHub API connects an Openship instance to GitHub — via the Openship GitHub App, an OAuth account,
or the local `gh` CLI — and then lets you browse the accounts, repositories, branches and files you can
deploy from. It also manages the push webhooks that drive [auto-deploy](/docs/guides/deploy-from-github).
In the dashboard this is the **GitHub** connection card in Settings and the repo picker in the deploy wizard.
This module is mounted on every instance. The local identity routes and every `/api/github/sources` route
are self-hosted only and return 404 on Openship Cloud. Source management additionally requires the active
workspace's `owner` role.
## Connection state
`GET /api/github/home` is the dashboard's single entry point: it returns `{ state, accounts, repos }` in one
round trip, filtered to the accounts and repos your member role is allowed to see.
`GET /api/github/status` is narrower — the Settings card's data source — returning `{ state, accounts,
installUrl, cloudUnreachable, customSourcesConfigured }`. The last field tells clients that App lifecycle
controls belong to the workspace source manager rather than the legacy Openship App connection.
```ts
const result = await ship.github.getHome();
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/github/home" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Connect
Starts or advances the connection flow. The response is intentionally mode-agnostic — the frontend just
reacts to the `flow` field:
- `{ connected: true }` — already connected, nothing to do.
- `{ connected: false, flow: "redirect", url }` — open `url` (OAuth handoff or GitHub App install).
- `{ connected: false, flow: "installations", state, installations, installUrl }` — let the user select an existing installation, or open `installUrl` to install on another account.
- `{ connected: false, flow: "device_code", userCode, verificationUri, ... }` — self-hosted device login.
- `{ connected: false, flow: "token", message }` — collect a personal token using the method's declared credential scope.
- `{ connected: false, flow: "terminal", command, message }` — run `command` (e.g. `gh auth login`) yourself.
The optional body field `source` (`"oauth"` | `"cli"`) forces a specific path when the dashboard shows both
the "Connect Openship App" and "Use gh CLI" buttons; omit it to let the server pick based on the instance's
auth mode.
On Openship Cloud, repository authorization is separate from the GitHub identity used to sign in.
The same GitHub user can authorize repository access for multiple Openship accounts. This never moves
or disconnects another account's sign-in link. Existing installations are discovered through that user's
GitHub authorization and verified again when selected.
For a redirect with `completion: "attempt"`, poll `github.pollConnect({ state })` using the returned
state until it completes or reports an error. An existing connected installation does not mean a new
attempt succeeded. A `flow: "installations"` response is completed with
`github.claimInstallation({ state, installationId: String(id) })` after the user selects it.
Cloud also supports a personal token in **Settings → Git**; the Library's **Other connection methods**
link opens that page.
```ts
const result = await ship.github.connect({
source: "oauth",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/github/connect" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"source":"oauth"}'
```
## Disconnect
```
POST /api/github/disconnect
```
Body (or `?source=`): `source` is `"oauth"`, `"cli"`, or `"all"` (default `"all"`). This drops Openship's
stored credentials for that source; it does **not** uninstall the GitHub App — that happens only when you
remove it from github.com (Openship reacts to the uninstall webhook).
On Cloud, disconnecting `oauth` clears repository authorization and cancels its pending connection
attempts. It preserves the account's GitHub sign-in method and any separately saved personal token.
This endpoint does not delete a workspace-owned source. Use `DELETE /api/github/sources/:id` for that
explicit owner-only operation.
## Workspace-owned GitHub App sources
These endpoints are available only on self-hosted instances. All reads are sanitized: private keys, client
secrets, webhook secrets, and their encrypted envelope are never returned.
### List sources
Returns `{ data, configuration }`. `configuration` contains `publicReady`, `publicUrl`, `setupUrl`, and
`webhookUrl`. Each source in `data` contains public App metadata, health, default status, and its claimed
installations.
### One-click manifest
Start the GitHub.com flow with:
The response contains `{ url, manifest }`. Submit `manifest` as a JSON string in a form field named
`manifest` to `url`; the dashboard does this automatically. GitHub redirects to the configured setup page
with `code` and `state`, which must be sent to:
```text
POST /api/github/sources/manifest/convert
{ "code": "…", "state": "…" }
```
Conversion consumes the user/workspace-bound state exactly once, encrypts GitHub's generated credentials,
and returns `{ data, installUrl }`.
### Manual registration and GitHub Enterprise Server
```text
POST /api/github/sources/manual
```
The API signs an App JWT and verifies `/app` before saving the source. It returns `{ data, installUrl }`.
`PATCH /api/github/sources/:id` accepts the same identity and endpoint fields, all optional. Omitted secret
fields retain their existing encrypted values. App ID or API URL cannot change while the source has claimed
installations. `POST .../verify` refreshes public App metadata and marks bad credentials as needing attention.
Making a source default atomically rebinds existing projects for every GitHub owner installed on that source.
Deleting a source promotes another active source when possible and rebinds affected projects; projects with no
replacement lose their installation binding and auto-deploy is disabled. Deleting locally does not uninstall
the GitHub App itself.
## Create a repository
```ts
const result = await ship.github.createRepo({
name: "my-app",
private: true,
owner: "acme",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/github/repos" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"my-app","private":true,"owner":"acme"}'
```
Returns `201` with `{ data }` (the created repository).
## Browse repos, branches and files
List repos for the connected account (`?owner=` narrows to one account), or for a named org via
`GET /api/github/orgs/:org/repos`. Both return `{ data: [...] }` filtered to repos your role may see.
File browsing reads directly from GitHub:
- `GET /api/github/repos/:owner/:repo/files` — directory listing. Query: `path` (default repo root) and
`branch`.
- `GET /api/github/repos/:owner/:repo/file` — one file's contents. Query: `file` (default `package.json`)
and `branch`. `.json` files are parsed and returned as JSON.
```ts
const result = await ship.github.getFile({
owner: "acme",
repo: "my-app",
file: "package.json",
branch: "main",
});
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/github/repos/acme/my-app/file?file=package.json&branch=main" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Webhooks
`POST /api/github/repos/:owner/:repo/webhooks` registers the Openship push webhook on the repo (or reuses an
existing one) so pushes trigger auto-deploy. It takes **no request body** — the target repo comes from the
path. `GET` lists the repo's hooks. To remove one, `DELETE` with the hook id:
```
DELETE /api/github/repos/:owner/:repo/webhooks
```
## Clone token
`GET /api/github/repos/:owner/:repo/clone-token` mints a short-lived (under an hour) GitHub App installation
token and returns `{ token, cloneUrl, command }` — a ready-to-run `git clone`. This is the same credential
the build pipeline clones with, and is available only when the Openship GitHub App is installed for the owner.
## Errors
Returned by the repo-listing routes when no usable GitHub source (App installation, OAuth account, or `gh`
CLI) is configured. Connect first with `POST /api/github/connect`, then retry.
`clone-token` needs a GitHub App installation for the owner. In `gh` CLI or PAT modes there is no
installation token, so this route 409s. Install the Openship GitHub App on that account to use clone tokens.
On a self-hosted instance connected to Openship Cloud, GitHub OAuth and App-install URLs are resolved
through openship.io. If the SaaS is unreachable, `connect` returns 503 rather than a dead install link. Check
network / the cloud connection in Settings, then retry.
An instance configured with its [own self-hosted GitHub App](/docs/guides/self-hosted-github-app) does not
use this cloud proxy; `GITHUB_AUTH_MODE=auto` selects the complete local App configuration first.
The `:owner/:repo` isn't visible to the active GitHub source (private, not granted to your member role, or
does not exist). Confirm the repo appears in `GET /api/github/home` first.
## Operations
{/* api-operations:start */}
### Connect
| Operation | SDK | REST API |
| --- | --- | --- |
| Read GitHub connection status. | `github.getStatus(input?)` | `GET /api/github/status` `github:read` |
| Read the GitHub overview for the current identity. | `github.getHome()` | `GET /api/github/home` `github:read` |
| Start GitHub authorization or select an accessible App installation. Repository access is separate from Cloud sign-in. | `github.connect(input?)` | `POST /api/github/connect` `github:write` |
| Claim an authorized GitHub App installation. | `github.claimInstallation(input)` | `POST /api/github/installations/claim` `github:write` |
| Read local Git identity availability. | `github.getLocalStatus()` | `GET /api/github/local-status` `github:read` · Self-hosted |
| Poll the returned state for one connection attempt, or omit state for a self-hosted device flow. | `github.pollConnect(input?)` | `GET /api/github/connect/poll` `github:read` |
| Configure the installation’s GitHub token. | `github.setInstanceToken(input)` | `POST /api/github/instance-token` `github:admin` · Self-hosted |
| Disconnect a GitHub identity or source association. | `github.disconnect(input?)` | `POST /api/github/disconnect` `github:admin` |
### Repositories and source
| Operation | SDK | REST API |
| --- | --- | --- |
| List accessible repositories. | `github.listRepos(input?)` | `GET /api/github/repos` `github:list` |
| List repositories in a GitHub organization. | `github.listOrgRepos(input)` | `GET /api/github/orgs/:org/repos` `github:list` |
| Read repository metadata. | `github.getRepo(input)` | `GET /api/github/repos/:owner/:repo` `github:read` |
| Create a repository through the configured GitHub identity. | `github.createRepo(input)` | `POST /api/github/repos` `github:write` |
| Delete an authorized repository. | `github.deleteRepo(input)` | `DELETE /api/github/repos/:owner/:repo` `github:admin` |
| List repository branches. | `github.listBranches(input)` | `GET /api/github/repos/:owner/:repo/branches` `github:list` |
| Obtain an authorized repository clone credential. | `github.getCloneToken(input)` | `GET /api/github/repos/:owner/:repo/clone-token` `github:read` |
| Detect build configuration in a repository. | `github.detectStack(input)` | `GET /api/github/repos/:owner/:repo/detect` `github:read` |
| List repository files at a path. | `github.listFiles(input)` | `GET /api/github/repos/:owner/:repo/files` `github:list` |
| Read a repository tree. | `github.listTree(input)` | `GET /api/github/repos/:owner/:repo/tree` `github:list` |
| Read repository file content. | `github.getFile(input)` | `GET /api/github/repos/:owner/:repo/file` `github:read` |
### Webhooks
| Operation | SDK | REST API |
| --- | --- | --- |
| List repository webhooks. | `github.listWebhooks(input)` | `GET /api/github/repos/:owner/:repo/webhooks` `github:list` |
| Register a repository webhook for deployment events. | `github.registerWebhook(input)` | `POST /api/github/repos/:owner/:repo/webhooks` `github:write` |
| Delete a repository webhook. | `github.deleteWebhook(input)` | `DELETE /api/github/repos/:owner/:repo/webhooks` `github:admin` |
### GitHub App sources
| Operation | SDK | REST API |
| --- | --- | --- |
| List configured GitHub App sources. | `github.listSources()` | `GET /api/github/sources` `github:admin` · Self-hosted |
| Start GitHub App manifest registration. | `github.beginManifest(input)` | `POST /api/github/sources/manifest` `github:admin` · Self-hosted |
| Convert a completed GitHub App manifest. | `github.convertManifest(input)` | `POST /api/github/sources/manifest/convert` `github:admin` · Self-hosted |
| Register an existing GitHub App source. | `github.createManualSource(input)` | `POST /api/github/sources/manual` `github:admin` · Self-hosted |
| Change a GitHub App source’s configuration. | `github.updateSource(id, input)` | `PATCH /api/github/sources/:id` `github:admin` · Self-hosted |
| Verify source credentials with GitHub. | `github.verifySource(id)` | `POST /api/github/sources/:id/verify` `github:admin` · Self-hosted |
| Select the default GitHub App source. | `github.setDefaultSource(id)` | `POST /api/github/sources/:id/default` `github:admin` · Self-hosted |
| Create an installation URL for a GitHub App source. | `github.createInstallUrl(id)` | `POST /api/github/sources/:id/install` `github:admin` · Self-hosted |
| Remove a GitHub App source. | `github.deleteSource(id)` | `DELETE /api/github/sources/:id` `github:admin` · Self-hosted |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| GitHub OAuth callback — browser navigates here, no session yet. | HTTP only | `GET /api/github/connect/redirect` `Handler authentication` |
{/* api-operations:end */}
---
# Tokens and MCP clients
URL: https://openship.io/docs/api/tokens.md
Create scoped access tokens and manage MCP client consent.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Tokens API manages the credentials that authenticate you to Openship: **personal access tokens** (PATs)
for the CLI and direct API calls, and the **MCP client** bindings created when an AI assistant connects over
OAuth. In the dashboard this is the **Settings → Access** area; from the terminal it's the
[`openship token`](/docs/cli/access) command. Every route is self-scoped — you only ever see and manage your
own tokens and clients.
## Create a token
Mints a new PAT and returns the plaintext secret in `data.token` **exactly once** — it is hashed at rest and
can never be retrieved again. List responses only ever show the short `tokenPrefix`.
```ts
const result = await ship.tokens.create({
name: "deploy-bot",
readOnly: false,
grants: [
{
resourceType: "project",
resourceId: "proj_123",
permissions: ["read", "write"],
},
],
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/tokens" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"deploy-bot","readOnly":false,"grants":[{"resourceType":"project","resourceId":"proj_123","permissions":["read","write"]}]}'
```
Send **exactly one** of `grants` (scoped) or `fullAccess: true` (unscoped). An empty or omitted
`grants` with no `fullAccess` returns `400 TOKEN_SCOPE_REQUIRED`; sending both returns
`400 AMBIGUOUS_TOKEN_SCOPE`.
Openship used to treat an empty `grants` as full access. That made "I want no limits" and "my scoped
selection came out empty" the same request — and it failed open for the dangerous one, so a caller
that meant to restrict a token could silently receive full access. Intent is now explicit.
Each entry in `grants` is a **TokenGrant**:
The response's `data.token` (an `opsh_pat_…` string) is shown once and never again. `GET /api/tokens` only
returns the prefix. If you lose it, revoke the token and mint a new one.
Every grant is validated against your own access before the token is created. An unknown `resourceType`
returns `400 INVALID_RESOURCE_TYPE`; granting access you don't hold yourself returns `403 GRANT_EXCEEDS_ACCESS`.
### The "projects it creates" scope
To hand an agent (e.g. an MCP client) the ability to **create new projects and fully manage only the ones
it creates** — with zero visibility into anything else — give it a single `create` grant on the project
collection:
```json
{ "name": "agent", "grants": [{ "resourceType": "project", "resourceId": "*", "permissions": ["create"] }] }
```
`create` is collection-only: it authorizes `POST /api/projects` and lets the token **list** projects
(filtered to its own), but grants **no** read/write/admin on any existing project. Each project the token
creates auto-adds a `{ project, , [read, write, admin] }` grant, so it fully controls its own work and
nothing else. In the dashboard this is the **"Only projects it creates"** option on the MCP authorize screen.
## List tokens
```ts
const tokens = await ship.tokens.list();
console.log(tokens);
```
```bash
curl "$OPENSHIP_URL/api/tokens" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Returns your tokens with no secret material — each row carries `id`, `name`, `tokenPrefix`, `readOnly`,
`scoped`, `expiresAt`, `lastUsedAt`, `revokedAt`, and `createdAt`.
## Revoke a token
```ts
await ship.tokens.revoke("pat_123");
```
```bash
curl -X DELETE "$OPENSHIP_URL/api/tokens/pat_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The `:id` isn't one of your own tokens (or was already removed). List your tokens with `GET /api/tokens`
to get valid IDs.
## MCP clients
When an AI assistant connects to Openship over OAuth, the consent page records what that client is allowed to
do, then Openship issues it scoped access tokens that run through the **same** scoped-principal path as a PAT.
These routes back that flow and the **Settings → Access → Connected clients** list.
### Authorize a client
Called by the OAuth consent page (browser cookie session) before a token is issued. It persists the user's
chosen read-only flag and resource grants as the client's binding. Grants are validated `⊆` your own access,
identical to token creation. Re-authorizing overwrites the binding's grants wholesale.
```
POST /api/tokens/mcp-authorize
```
Missing `clientId` returns `400 CLIENT_ID_REQUIRED`; an `organizationId` you're not a member of returns
`403 ORG_NOT_A_MEMBER`. Invalid or over-broad grants fail the same way as token creation
(`400 INVALID_RESOURCE_TYPE` / `403 GRANT_EXCEEDS_ACCESS`).
Scope intent is explicit here too: an empty `grants` without `fullAccess: true` returns
`400 TOKEN_SCOPE_REQUIRED`, and sending both returns `400 AMBIGUOUS_TOKEN_SCOPE`. An unscoped binding
lets the client act with your own role, so it can never be reached by omission.
### List connected clients
```
GET /api/tokens/mcp-clients
```
Returns one entry per OAuth binding with `clientId`, `name`, `organizationId`, `organizationName`,
`readOnly`, `scoped`, `grantCount`, `authorizedAt`, and `lastUsedAt`.
### Disconnect a client
Revokes the client's issued tokens first (stopping it immediately), then drops the scope binding, its grants,
and the recorded consent so a reconnect re-prompts. Scoped to you — a client shared across users keeps working
for everyone else.
```
DELETE /api/tokens/mcp-clients/:clientId
```
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List your tokens without exposing their secrets. | `tokens.list()` | `GET /api/tokens` `settings:read` |
| Create a token; its secret is returned once. | `tokens.create(input)` | `POST /api/tokens` `settings:write` |
| Authorize or explicitly re-scope an MCP client binding. | `tokens.authorizeMcpClient(input)` | `POST /api/tokens/mcp-authorize` `settings:write` |
| List your authorized MCP clients. | `tokens.listMcpClients()` | `GET /api/tokens/mcp-clients` `settings:read` |
| Revoke a token by its token ID. | `tokens.revoke(id)` | `DELETE /api/tokens/:id` `settings:write` |
| Read one MCP client authorization. | `tokens.getMcpClient(id)` | `GET /api/tokens/mcp-clients/:clientId` `settings:read` |
| Revoke an MCP client authorization. | `tokens.disconnectMcpClient(id)` | `DELETE /api/tokens/mcp-clients/:clientId` `settings:write` |
{/* api-operations:end */}
---
# Webhooks
URL: https://openship.io/docs/api/webhooks.md
Create incoming actions and inspect provider deliveries.
Incoming hooks trigger a saved deployment or job action. Provider webhooks receive signed events from
services such as GitHub. Both record deliveries, but their authentication protocols differ.
## Create an incoming hook
```ts
const hook = await ship.webhooks.create("proj_123", {
name: "Deploy site",
actionType: "deploy",
authMode: "token",
});
console.log(hook.id, hook.url);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/incoming-webhooks" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"name":"Deploy site","actionType":"deploy","authMode":"token"}'
```
| Field | Use |
| --- | --- |
| `actionType` | Required: `deploy` or `job`. |
| `name` | Display name; defaults to `Webhook`. |
| `authMode` | `token` (default), `hmac`, or `none`; `none` is not allowed for jobs. |
| `actionConfig.serviceId` / `serviceIds` | Restrict a deploy action to services within this project. |
| `actionConfig.jobKey` | Required for a job action. |
The returned hook includes its URL and, where authorized, a secret. Store that secret securely.
Job hooks require project-write, job-write, and administration access to every job target server.
## Invoke an authorized action
Use this operation when your integration is already authenticated with Openship:
```ts
const result = await ship.webhooks.invoke("proj_123", "hook_123");
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/projects/proj_123/incoming-webhooks/hook_123/invoke" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
An external sender instead calls the hook's returned URL using its token or HMAC authentication.
The dispatch rechecks the saved execution identity, current membership, and any saved credential limits.
It does not replace the caller with the organization owner.
Hooks that lack saved authority return `requiresReauthorization: true`. An authorized editor can rotate
the hook or update it with `{ enabled: true }` to reauthorize it. Authority changes rotate the credential;
update external senders to use the new secret.
## Read deliveries
`deliveries(projectId)` lists a project's events. `hookDeliveries(projectId, hookId)` selects one hook;
`listDeliveries()` lists events visible across the selected organization. Pagination filters access
before selecting the page.
## Dispatch a provider webhook
```
POST /api/webhooks/:provider
```
There is no Openship-defined request body: the body is the provider's **raw event payload**, read verbatim
so the signature can be checked byte-for-byte. GitHub deliveries carry these headers, which the dispatcher
relies on:
| Header | Purpose |
|---|---|
| `X-Hub-Signature-256` | HMAC-SHA256 of the raw body (`sha256=…`). Required — a missing or wrong value is rejected. |
| `X-GitHub-Event` | Event type (`push`, `installation`, `check_run`, `ping`, …). Selects the handler. |
| `X-GitHub-Delivery` | Unique delivery id. Used for idempotency — a redelivered id is claimed once and dropped on repeat. |
The dispatcher:
1. Looks up the provider named in the path. Unregistered → `404 { "error": "Webhook provider '…' is not configured" }`.
2. Verifies the signature. Invalid or missing → `401`.
3. Parses the JSON body. Malformed → `400`.
4. Runs the handler and **always responds `200`** for a verified delivery — even if the handler throws, the
error is returned in the body (`{ "success": false, "error": "…" }`) rather than as a `4xx/5xx`. Returning
an error status would make GitHub retry and risk duplicate deployments.
```bash
# GitHub sends this automatically. Illustrative manual delivery — the signature
# must be a valid HMAC-SHA256 of the exact body using the project's webhook secret:
curl -X POST "$OPENSHIP_URL/api/webhooks/github" \
-H "Content-Type: application/json" \
-H "X-GitHub-Event: ping" \
-H "X-GitHub-Delivery: $(uuidgen)" \
-H "X-Hub-Signature-256: sha256=" \
-d '{"zen":"Keep it simple."}'
```
### Signature verification (GitHub)
GitHub deliveries are verified with a **per-project** secret. The dispatcher peeks at `repository.full_name`
in the payload, finds the project(s) linked to that `owner/repo`, and checks the signature against the
project's stored `webhookSecret`. If no per-project secret resolves (legacy hooks, installation/ping events
that have no owning project), it falls back to the instance's `GITHUB_WEBHOOK_SECRET`. A delivery with no
resolvable secret cannot be verified and is rejected — there is no unsigned path, even self-hosted.
### Provider registration
`github` is registered on the dispatcher at startup, so `POST /api/webhooks/github` is always live. `stripe`
is an accepted `:provider` name but is **not** wired to the unified dispatcher by default; Stripe billing
events are received at `/api/billing/webhook/stripe` in cloud mode instead. Posting to
`/api/webhooks/stripe` when no Stripe provider is registered returns `404 … is not configured`.
## How a GitHub push becomes a deploy
When a verified `push` event arrives, the handler maps it to deployments like this:
- **Branch pushes only.** The `ref` must start with `refs/heads/`; tag pushes and branch deletions are
acknowledged and ignored.
- **Match projects by repo + branch.** It finds every project linked to the pushed `owner/repo`, then keeps
those where **auto-deploy is enabled** and the project's configured branch (or, if unset, the repository's
default branch) equals the pushed branch.
- **Attribute to the org owner.** Webhooks have no human actor, so the deployment is audited against the
organization owner (who owns the GitHub App installation).
- **Smart per-service routing.** For monorepo/compose projects, the changed files in the push decide which
services rebuild; unaffected pushes can be skipped entirely. Single-app projects always rebuild. A pending
"rebuild everything next time" flag forces a full deploy once.
- **Idempotency.** The `X-GitHub-Delivery` id is claimed persistently, so an at-least-once redelivery of the
same push is dropped instead of deploying twice.
- **Cloud forwarding.** On a self-hosted box, if no local project matches but a linked **cloud** project owns
the repo/branch, the push is forwarded to Openship Cloud so the cloud copy redeploys.
Deep dive on wiring and edge cases: [Auto-deploy on push](/docs/guides/auto-deploy).
## Errors
The `X-Hub-Signature-256` header is absent, or the HMAC doesn't match the stored secret. This is expected
for hand-crafted requests; genuine GitHub/Stripe deliveries are signed. If real deliveries fail, the webhook
secret on the project (or `GITHUB_WEBHOOK_SECRET`) no longer matches what the provider is signing with —
re-link the repository to reset it.
The `:provider` isn't `github`/`stripe`, or the named provider isn't registered on this instance (e.g.
`stripe` on a self-hosted box). Check the path and use `/api/webhooks/github` for GitHub.
The signature verified but the body didn't parse as JSON. Confirm the provider is sending
`Content-Type: application/json` and the payload isn't truncated (the 5 MB body cap applies).
A verified delivery whose handler threw still returns `200` — on purpose, so GitHub doesn't retry into a
duplicate deploy. The failure detail is in the response body; check your instance logs for the
`[Webhook] github handler error` entry.
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| List the project’s incoming webhooks. | `webhooks.list(id)` | `GET /api/projects/:id/incoming-webhooks` `project:read` |
| Create an incoming hook with an authorized action and authentication mode. | `webhooks.create(id, input)` | `POST /api/projects/:id/incoming-webhooks` `project:write` |
| List project webhook deliveries. | `webhooks.deliveries(id, input?)` | `GET /api/projects/:id/webhook-deliveries` `project:read` |
| Update a hook and reauthorize its action when requested. | `webhooks.update(parentId, id, input)` | `PATCH /api/projects/:id/incoming-webhooks/:hookId` `project:write` |
| Rotate hook credentials and reauthorize execution. | `webhooks.rotate(parentId, id)` | `POST /api/projects/:id/incoming-webhooks/:hookId/rotate` `project:write` |
| Remove an incoming hook. | `webhooks.remove(parentId, id)` | `DELETE /api/projects/:id/incoming-webhooks/:hookId` `project:write` |
| Read one hook’s delivery history. | `webhooks.hookDeliveries(parentId, id, input?)` | `GET /api/projects/:id/incoming-webhooks/:hookId/deliveries` `project:read` |
| Invoke the hook’s saved action through the SDK. | `webhooks.invoke(parentId, id)` | `POST /api/projects/:id/incoming-webhooks/:hookId/invoke` `project:write` |
| Read webhook deliveries visible in the organization. | `webhooks.listDeliveries(input?)` | `GET /api/settings/webhook-deliveries` `settings:read` |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Receive a provider webhook (`github` or `stripe`), verify its signature, and dispatch it. | HTTP only | `POST /api/webhooks/:provider` `Handler authentication` |
| Trigger a backup from an inbound webhook (bearer token is the credential). | HTTP only | `POST /api/webhooks/backup` `Handler authentication` |
| Authenticate an incoming hook and dispatch its saved action. | HTTP only | `POST /api/webhooks/incoming/:id` `Handler authentication` |
{/* api-operations:end */}
---
# Analytics
URL: https://openship.io/docs/api/analytics.md
Read project traffic, deployment statistics, and resource usage.
Analytics report traffic, deployment outcomes, and runtime usage for resources the caller can access.
Project methods take a project ID in the SDK; REST uses `?projectId=`. Server methods take a server ID.
## Read request traffic
`overview` returns the cumulative summary and time-series periods together. Use `summary` or `periods`
when you only need one. `geo` adds geographic, path, and status-code breakdowns where available.
```ts
const traffic = await ship.analytics.overview("proj_123", {
from: "2026-09-01T00:00:00Z",
to: "2026-09-02T00:00:00Z",
});
console.log(traffic.summary, traffic.periods);
```
```bash
curl "$OPENSHIP_URL/api/analytics/overview?projectId=proj_123&from=2026-09-01T00:00:00Z&to=2026-09-02T00:00:00Z" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
| Input | Applies to | Use |
| --- | --- | --- |
| `domain` | Summary, periods, overview, and geo | Limit results to one tracked hostname. |
| `from`, `to` | Periods, overview, and geo | Ordered ISO date range, at most 366 days. |
The project ID is required. An inaccessible or missing project is not included in results. Fixed
organization scopes do not forward through an owner's Cloud link; see [Cloud compatibility](/docs/api/sdk/compatibility#cloud).
## Read deployment statistics
```ts
const stats = await ship.analytics.deploymentStats("proj_123");
console.log(stats.successfulDeployments, stats.failedDeployments);
```
```bash
curl "$OPENSHIP_URL/api/analytics/deployments?projectId=proj_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Statistics include totals, success and failure counts, average build duration, and daily counts.
`dashboard()` returns project and deployment counts for the caller's organization.
## Read runtime usage
`resources` returns an aggregate plus per-service usage, capacity, timestamp, and a `supported` flag.
`usage` and `containerInfo` read the active runtime and can return `null` when it is unavailable.
```ts
const usage = await ship.analytics.resources("proj_123");
console.log(usage.supported, usage.overall, usage.services);
```
```bash
curl "$OPENSHIP_URL/api/analytics/resources?projectId=proj_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Use `usageHistory(projectId, { from, to, serviceKey })` for time buckets. All three filters are optional;
the result reports its `granularityMinutes` and selected `serviceKey`.
### Live usage
```ts
for await (const event of ship.analytics.streamUsage("proj_123", {
signal: AbortSignal.timeout(30_000),
})) {
console.log(event);
}
```
```bash
curl -N "$OPENSHIP_URL/api/analytics/usage/stream?projectId=proj_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The REST endpoint returns Server-Sent Events. An active deployment with a running container is required.
Pass an abort signal or stop iteration to close an SDK stream.
## Control path collection
```ts
await ship.analytics.setPathsCollection("proj_123", { enabled: true });
```
```bash
curl -X POST "$OPENSHIP_URL/api/analytics/paths-collection/proj_123" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"enabled":true}'
```
This changes collection settings and requires write access. Other analytics methods read data.
## Server analytics
Server analytics require `server:read` access and a tracked `domain`. Persisted buckets and daily geo
data remain readable when a server is offline; live analytics require a reachable management API.
```ts
const buckets = await ship.analytics.serverBuckets("srv_123", { domain: "app.example.com" });
console.log(buckets);
```
```bash
curl "$OPENSHIP_URL/api/analytics/server/srv_123?domain=app.example.com" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
| Method | Additional input | Result |
| --- | --- | --- |
| `serverBuckets` | Optional `from`, `to` | Persisted minute buckets; range values accept ISO timestamps or epoch minutes. |
| `serverGeo` | Optional `day` in `YYYYMMDD` format | Daily country totals. |
| `serverLive` | None | Live edge analytics. |
Every method above also requires `domain`. Missing domain returns `400`; an unreachable live source can
return `502`.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Stream current resource usage. | `analytics.streamUsage(projectId, options?)` | `GET /api/analytics/usage/stream` `analytics:read` |
| Read summary statistics for the selected scope and period. | `analytics.summary(id, input?)` | `GET /api/analytics` `analytics:read` |
| List supported analytics periods. | `analytics.periods(id, input?)` | `GET /api/analytics/periods` `analytics:read` |
| Read aggregate traffic and application analytics. | `analytics.overview(id, input?)` | `GET /api/analytics/overview` `analytics:read` |
| Read geographic traffic statistics. | `analytics.geo(id, input?)` | `GET /api/analytics/geo` `analytics:read` |
| Read deployment outcome statistics. | `analytics.deploymentStats(id)` | `GET /api/analytics/deployments` `analytics:read` |
| Read current workload resource usage. | `analytics.usage(id)` | `GET /api/analytics/usage` `analytics:read` |
| Read analytics runtime/container information. | `analytics.containerInfo(id)` | `GET /api/analytics/container` `analytics:read` |
| Read configured resource allocations. | `analytics.resources(id)` | `GET /api/analytics/resources` `analytics:read` |
| Read historical resource usage. | `analytics.usageHistory(id, input?)` | `GET /api/analytics/usage/history` `analytics:read` |
| Enable or disable request-path collection. | `analytics.setPathsCollection(id, input)` | `POST /api/analytics/paths-collection/:projectId` `project:write` |
| Read server traffic buckets. | `analytics.serverBuckets(id, input)` | `GET /api/analytics/server/:serverId` `server:read` |
| Read geographic server-request statistics. | `analytics.serverGeo(id, input)` | `GET /api/analytics/server/:serverId/geo` `server:read` |
| Read current server traffic data. | `analytics.serverLive(id, input)` | `GET /api/analytics/server/:serverId/live` `server:read` |
| Read the analytics dashboard aggregate. | `analytics.dashboard()` | `GET /api/analytics/dashboard` `analytics:read` |
{/* api-operations:end */}
---
# API overview
URL: https://openship.io/docs/api.md
Control Openship with the Node.js SDK or REST API.
Create projects, deploy code, and operate your installation from an application or script. Each resource
has one reference page: shared behavior and fields, with **SDK** and **REST API** tabs for examples.
## Start here
| Your application needs to… | Use |
| --- | --- |
| Control an existing self-hosted or Cloud installation | [Remote SDK client](/docs/api/sdk/client) or [REST API](/docs/api/http) |
| Run Openship inside a Node application | [Native SDK](/docs/api/sdk/native) |
| Run commands from a terminal or CI | [CLI](/docs/cli) |
Ship SDK ships in `openship` 0.8.0 and later. Start with `npm install openship` and the
[SDK guide](/docs/api/sdk).
## Make a request
Use a token that can read projects in your organization. The SDK returns the application result;
REST returns the endpoint's JSON response.
```ts title="list-projects.mts"
import { OpenshipClient } from "openship";
const token = process.env.OPENSHIP_TOKEN;
const organizationId = process.env.OPENSHIP_ORGANIZATION_ID;
if (!token || !organizationId) throw new Error("Set a token and organization ID");
const ship = new OpenshipClient({
baseUrl: "https://ship.example.com",
token,
organizationId,
});
const projects = await ship.projects.list({ page: 1, perPage: 20 });
console.log(projects.data);
```
```bash
export OPENSHIP_URL="https://ship.example.com"
export OPENSHIP_ORGANIZATION_ID="org_123"
# Set OPENSHIP_TOKEN to your personal access token.
curl "$OPENSHIP_URL/api/projects?page=1&perPage=20" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "X-Organization-Id: $OPENSHIP_ORGANIZATION_ID" \
-H "X-Openship-Scope: fixed"
```
### Example conventions
Resource examples use `ship` for a configured remote client or [native user scope](/docs/api/sdk/identity).
Replace IDs such as `proj_123` with your own. REST examples use the URL and token above; a token's
organization binding applies to every request. To pin an organization independently of defaults,
include the two scope headers shown above. [Older APIs must support fixed scopes](/docs/api/sdk/compatibility#fixed-organization-scopes).
Named SDK methods unwrap response envelopes where applicable. For example, `projects.get(id)` returns a
project, while its REST endpoint returns `{ data: project }`. IDs may be method arguments in the SDK
and URL, query, or body fields in REST; the code tabs show that mapping.
## Applications
| Resource | Use |
| --- | --- |
| [Projects](/docs/api/projects) | Configuration, environments, connections, and storage bindings |
| [Source files](/docs/api/sources) | Generated code, folder uploads, and source detection |
| [Deployments](/docs/api/deployments) | Builds, progress, decisions, cancellation, and rollback |
| [Services](/docs/api/services) | Containers and services within a project |
| [App catalog](/docs/api/apps) | Templates and application settings |
| [GitHub](/docs/api/github) | Accounts, repositories, and GitHub App sources |
## Networking
| Resource | Use |
| --- | --- |
| [Domains and TLS](/docs/api/domains) | Hostnames, DNS verification, and certificates |
| [DNS providers](/docs/api/dns) | DNS credentials and zone checks |
| [Webhooks](/docs/api/webhooks) | Incoming actions and provider deliveries |
| [Edge administration](/docs/api/edge) | Discover and import existing edge sites |
| [Server terminal](/docs/api/terminal) / [service terminal](/docs/api/service-terminal) | Interactive WebSocket sessions |
## Operations
| Resource | Use |
| --- | --- |
| [Analytics](/docs/api/analytics) | Traffic and resource usage |
| [Issues and health](/docs/api/issues) | Problems, health snapshots, and rescans |
| [Updates](/docs/api/updates) | Available versions and update deployment |
| [Jobs](/docs/api/jobs) | Commands, schedules, and run history |
| [Backups](/docs/api/backups) / [destinations](/docs/api/backup-destinations) | Policies, archives, and restores |
| [Notifications](/docs/api/notifications) | Channels, subscriptions, and deliveries |
| [Notices](/docs/api/notices) | Public installation announcements |
| [Audit log](/docs/api/audit) | Organization activity |
## Access and infrastructure
| Resource | Use |
| --- | --- |
| [Tokens](/docs/api/tokens) / [permissions](/docs/api/permissions) | Credentials, members, invitations, and grants |
| [Provider credentials](/docs/api/credentials) | Registry and DNS provider secrets |
| [User settings](/docs/api/settings) | Build, deploy, routing, and Git defaults |
| [Servers](/docs/api/servers) / [installation settings](/docs/api/system) | Hosts, components, setup, and administration |
| [Health](/docs/api/health) / [container images](/docs/api/images) | Installation metadata and image catalog |
| [Mail](/docs/api/mail) | Self-hosted email services |
| [Migration](/docs/api/migration) / [data transfer](/docs/api/data-transfer) | Server adoption, moves, imports, and exports |
| [Cloud](/docs/api/cloud) / [billing](/docs/api/billing) | Cloud connections, plans, and usage |
| [Authentication](/docs/api/auth) / [MCP](/docs/api/mcp) | Browser login and agent protocols |
For transport details, see [HTTP basics](/docs/api/http). For errors, providers, and current native/Cloud
limits, see [SDK errors](/docs/api/sdk/errors) and [compatibility](/docs/api/sdk/compatibility).
---
# User settings
URL: https://openship.io/docs/api/settings.md
Read and update your build, deploy, routing, and Git preferences.
User settings apply to the authenticated user. There is no settings ID to select. References to servers
are checked against the current organization and access grants; an inaccessible default server is hidden.
Use [installation settings](/docs/api/system) for instance-wide configuration.
## Personal appearance
`GET /api/settings/appearance` returns `{ "appearance": null }` for an unset preference, or an appearance library. `PUT /api/settings/appearance` accepts the same wrapper. Pass `null` to clear the saved appearance. Both endpoints operate exclusively on the authenticated user and retain the existing settings permissions; there is no user ID selector. Other settings and credentials are preserved.
```ts
const { appearance } = await ship.settings.getAppearance();
await ship.settings.setAppearance({ appearance });
// Clear the saved personal appearance.
await ship.settings.setAppearance({ appearance: null });
```
A library has `version: 1`, an `active` preset (`light`, `dim`, `dark`, `system`) or custom theme ID, and `themes`. Each theme contains `version: 1`, `id`, `name`, `base`, `tokens`, `typography` and optional embedded `fonts`. Missing token overrides inherit the base theme. Token references may use registered variables of the same type and must not form cycles. Unknown tokens, executable CSS, remote font references, unsupported versions and excessive payloads are rejected.
```json
{
"version": 1,
"active": "ocean",
"themes": [{
"version": 1,
"id": "ocean",
"name": "Ocean",
"base": "dim",
"tokens": { "--th-bg-page": "#142333", "--radius": "12px" },
"typography": {
"sans": "system", "mono": "systemMono",
"size": 16, "monoSize": 13, "lineHeight": 1.5, "weight": 400
},
"fonts": []
}]
}
```
The same library JSON can be exported, imported and reset from the CLI. `set` also accepts a single theme exported by the dashboard and merges it by ID into the current library.
```bash
openship --json settings appearance get > appearance.json
openship settings appearance set appearance.json
openship settings appearance reset
```
Font choices are `gellix`, `system`, `serif` or `custom` for the interface and `mono`, `systemMono` or `custom` for monospace. A custom choice requires a matching font asset with `role`, `name` and base64 WOFF2 `data`. Each font is limited to 256 KiB; the full library is limited to 1 MiB and 32 themes. All clients validate the same schema. Existing instances receive a nullable column through an additive migration; older users retain their default appearance.
## Read preferences
```ts
const settings = await ship.settings.get();
console.log(settings.buildMode, settings.defaultDeployTarget);
```
```bash
curl "$OPENSHIP_URL/api/settings" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The result includes build and route strategy, deploy defaults, transfer preferences, and Git options.
`cloneToken` reports `hasToken`, `setAt`, and `asDefault`; it never contains the token value.
## Set build and routing defaults
```ts
await ship.settings.setBuildMode({ buildMode: "server" });
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/settings/build-mode" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"buildMode":"server"}'
```
| Method | Input | Values |
| --- | --- | --- |
| `setBuildMode` | `buildMode` | `auto`, `server`, or `local`. |
| `setRouteStrategy` | `routeStrategy` | `auto`, `loopback-port`, or `container-ip`. |
`update({ buildMode })` also creates or updates the settings row; it maps to `PUT /api/settings`.
Route strategy controls how the edge reaches an application. Provider constraints still apply; for
example, container-IP routing is unsupported on Docker Desktop.
## Set a deployment destination
```ts
await ship.settings.setDeployDefaults({
defaultDeployTarget: "server",
defaultServerId: "srv_123",
});
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/settings/deploy-defaults" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"defaultDeployTarget":"server","defaultServerId":"srv_123"}'
```
`defaultDeployTarget` is `server`, `cloud`, or `null`. A server target requires an accessible
`defaultServerId`. Other targets clear that server reference. Pass `null` to clear a default; omit a
field to retain its value. `local` is derived from the project at deployment time and is not a selectable
default destination.
## Manage clone credentials
```ts
await ship.settings.setCloneCredentials({ token: "ghp_example", asDefault: true });
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/settings/clone-credentials" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"token":"ghp_example","asDefault":true}'
```
Use a real Git token from your secret store. The token is encrypted and never returned. Omit `token` to
leave it unchanged; send `null` or an empty string to clear it. `asDefault` controls whether it is used
automatically for clones.
`setCloneStrategy({ preference })` accepts `prompt`, `local`, or `remote-with-token`.
`setGitForwarding({ enabled })` controls forwarding the local Git identity to an authorized build server
for the clone. See [Git authentication](/docs/guides/git-authentication).
## Set transfer preferences
```ts
await ship.settings.setTransferPreferences({
transferMode: "auto",
transferCompression: "zstd",
});
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/settings/transfer" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"transferMode":"auto","transferCompression":"zstd"}'
```
Both fields are optional. `transferMode` accepts `auto`, `stream`, `direct`, or `rsync`;
`transferCompression` accepts `auto`, `zstd`, `gzip`, or `none`. These are defaults for migration volume
transfers; target capabilities determine the effective transport.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the current user’s preferences and defaults. | `settings.get()` | `GET /api/settings` `settings:read` |
| Update user settings. | `settings.update(input)` | `PUT /api/settings` `settings:write` |
| Choose where builds run by default. | `settings.setBuildMode(input)` | `PATCH /api/settings/build-mode` `settings:write` |
| Choose the default routing strategy. | `settings.setRouteStrategy(input)` | `PATCH /api/settings/route-strategy` `settings:write` |
| Set the default deployment target and resources. | `settings.setDeployDefaults(input)` | `PATCH /api/settings/deploy-defaults` `settings:write` |
| Configure credentials for source cloning. | `settings.setCloneCredentials(input)` | `PATCH /api/settings/clone-credentials` `settings:write` |
| Choose how source is transferred to build servers. | `settings.setCloneStrategy(input)` | `PATCH /api/settings/clone-strategy-preference` `settings:write` |
| Set source transfer preferences. | `settings.setTransferPreferences(input)` | `PATCH /api/settings/transfer` `settings:write` |
| Configure forwarding of Git identity to build servers. | `settings.setGitForwarding(input)` | `PATCH /api/settings/forward-git` `settings:write` |
| Read the authenticated user’s saved appearance and portable theme library. | `settings.getAppearance()` | `GET /api/settings/appearance` `settings:read` |
| Save or reset personal appearance, validated tokens and embedded WOFF2 fonts. | `settings.setAppearance(input)` | `PUT /api/settings/appearance` `settings:write` |
{/* api-operations:end */}
---
# MCP
URL: https://openship.io/docs/api/mcp.md
Call Openship tools through Model Context Protocol.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The MCP API is a single **Model Context Protocol** endpoint that lets AI agents (Claude, Cursor, and any
MCP-compatible client) drive Openship as a set of tools. Each tool maps onto a permission-tagged REST route,
and every call re-runs the full auth and permission stack — so an agent only ever sees and does what its
token allows. For client setup (OAuth flow, config snippets), see the [MCP overview](/docs/mcp).
Available on both self-hosted and Openship Cloud (mounted in the shared route set).
## How authentication works
A missing or invalid bearer returns **`401`** with a `WWW-Authenticate` header pointing at
`/.well-known/oauth-protected-resource/api/mcp`, so OAuth-2.1 MCP clients can discover the authorization server and
start the PKCE flow. Self-hosted clients using `/api/proxy/api/mcp` receive metadata for that path instead,
with a matching resource identifier. A valid credential resolves the caller's effective capability — this is used only to
**filter `tools/list`** so the endpoint doesn't advertise tools the token can't use.
The capability is **not** the authorization gate. Every `tools/call` builds an internal HTTP request and
dispatches it through the real Hono app, forwarding the caller's bearer, so routing, validation, auth, and
the per-resource permission check all run exactly as they do over HTTP. A read-only token can only reach
GET tools; a scoped token stays confined to the projects, servers, and repositories it was granted.
The endpoint is rate-limited per-IP (the `mcp` policy: 300 requests/minute) because even an unauthenticated
probe costs a credential lookup.
## Request body (JSON-RPC 2.0 envelope)
The `POST` body is a single JSON-RPC 2.0 message (batching was removed in protocol `2025-06-18` — an array
body returns `-32600`).
### Methods
| Method | Result |
|---|---|
| `initialize` | Negotiates the protocol version (default `2025-06-18`; also speaks `2025-03-26` and `2024-11-05`) and returns capabilities, server information, and instructions identifying the current workspace and how to select a destination. |
| `ping` | Returns `{}`. |
| `tools/list` | Returns the tools the caller's token can actually use (filtered by read-only flag, role, and grants). |
| `tools/call` | Dispatches the named tool through the real API and returns its response as JSON text content. |
| `prompts/list` | Returns the guided-flow catalog — one entry per multi-step workflow including deployment, clustering/scaling, backups and migration. |
| `prompts/get` | Returns a named prompt's guidance as a user message, with tool references resolved to their live tool names and any `arguments` interpolated. |
| `notifications/initialized` | Acknowledged only (notification, no reply → `202`). |
## List available tools
```
POST /api/mcp
```
```bash
curl -s "$OPENSHIP_URL/api/mcp" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list"}'
```
The tool set is derived from Openship's permission-tagged routes that opt in with an `mcp` block; the
credential/auth surfaces (`tokens`, `auth`, `mcp` itself) are never exposed.
## Discover and select a workspace
An Openship workspace or workgroup is an **organization** in the API. Call
`get_permissions_workspaces` with `{}` to discover workspace names and IDs before creating an app or a
Compose project. This tool is available to read-only and restricted credentials too.
```json
{
"jsonrpc": "2.0",
"id": 2,
"method": "tools/call",
"params": { "name": "get_permissions_workspaces", "arguments": {} }
}
```
The response's `data` includes `currentOrganizationId`, `boundOrganizationId`, `canSwitchOrganization`,
`readOnly`, and `workspaces`. Each workspace includes `organizationId`, `name`, `slug`, `isTeam`, and
the effective `role`. Empty workspaces are included. An organization-bound credential only sees its
own workspace; an unbound credential can discover its user's memberships. An explicitly fixed request
scope returns only the selected workspace.
Use the selected ID at the **top level** of every tool call in the flow:
```json
{
"jsonrpc": "2.0",
"id": 3,
"method": "tools/call",
"params": {
"name": "post_apps",
"arguments": {
"organizationId": "org_target",
"body": { "templateId": "redis", "name": "Cache" }
}
}
}
```
The same `organizationId` argument applies to Compose scanning, `post_projects_ensure`, services,
deployment, and status tools. It fixes that call's scope and does not persist a workspace switch.
If the user has several available workspaces and has not specified a destination, the agent should ask
which workspace to use before creating resources.
Current PATs and OAuth connections are bound to the organization where they were authorized.
`boundOrganizationId` identifies that boundary. Selecting another organization returns `TOKEN_ORG_SCOPE`;
the user needs a token or authorization in the destination workspace. Invalid or inaccessible IDs fail
instead of falling back to the default workspace.
This ID selects a request scope; it does **not** transfer an existing app between organizations.
`get_system_servers_destinations` lists authorized execution servers, a separate concept. Select a
`serverId` when creating or importing a project; changing where it runs does not move its records to
another Openship instance. Cross-organization app transfer is not currently exposed.
## Deploy a desktop folder on Cloud
Use the MCP connection on the machine that holds the source folder. A connected managed server lets
that desktop instance build and run the app on Cloud while keeping its project records local:
1. Discover the local `organizationId` with `get_permissions_workspaces` and pass it on every call.
2. Call `get_system_servers_destinations` and select a managed server. If it is not connected, an
administrator can use `get_system_servers_managed_available` and
`post_system_servers_managed_connect`. Use the returned **local** `serverId`.
3. Call `post_projects_import` with `body: { name, localPath, serverId }`. The path must be readable by
the desktop controller. For an existing project already assigned to that server, reuse its ID.
4. Call `post_deployments_build_access` with `body: { projectId, buildStrategy: "server" }`, then poll
`get_deployments_by_id` and its logs. Source location and build location are separate: a local
folder can be built on a managed server. `buildStrategy: "local"` is not supported on managed servers.
This flow requires project creation/write and destination server write permissions. It does not require
`transfer_to_cloud` or access to the MCP client's OAuth bearer token.
To manage projects whose records live in Cloud, authorize a separate MCP connection to
`https://api.openship.io/api/mcp` and discover the Cloud organization there. A local credential cannot
use the owner's Cloud account link to access those records. `CLOUD_SCOPE_UNAVAILABLE` also applies when
`organizationId` is omitted; removing it does not widen the credential's permissions.
A remote Cloud controller cannot read a folder on the MCP client's machine. Use a git repository or
the [authenticated source upload flow](/docs/api/sources#upload-a-source-folder) through an SDK, CLI,
or browser. A credential restricted to its own projects must create the project first and pass its
`projectId` to the upload session and subsequent `ensure` call. An unbound upload session requires
wildcard project write permission. OAuth tokens remain in the MCP client.
Explicit project promotion is a separate configuration transfer. With receipt support on both
instances, retrying after a lost response or failed local cleanup confirms the original import and
retries teardown without importing again. A changed source, changed Cloud connection, or an older
duplicate without a matching receipt stops cleanup and requires review of both copies. An older
Cloud API without the promotion endpoint rejects the request before importing.
## Call a tool
`params.name` is the tool name from `tools/list`; `params.arguments` carries any path parameters, a
`query` object and/or JSON `body` when declared by the tool’s schema (including guarded `DELETE` operations), and an optional
`organizationId` (sent as `X-Organization-Id` together with `X-Openship-Scope: fixed`).
```bash
curl -s "$OPENSHIP_URL/api/mcp" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"jsonrpc":"2.0","id":2,"method":"tools/call",
"params":{"name":"get_projects","arguments":{}}}'
```
The result wraps the underlying API response as text content, with `isError: true` when the dispatched
request failed.
## Guided flows (prompts)
`tools/list` is flat — it tells an agent what each tool does, one call at a time, but not how the multi-step
flows chain together. The **prompts** catalog fills that gap: each prompt is a short, ordered playbook for a
workflow, referencing the exact tool names to call in sequence. MCP clients surface them as slash-commands /
starters, so they also serve as the discoverable entry points into a flow.
```bash
curl -s "$OPENSHIP_URL/api/mcp" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"jsonrpc":"2.0","id":3,"method":"prompts/get",
"params":{"name":"deploy-from-git","arguments":{"repo":"acme/widgets"}}}'
```
| Prompt | What it walks you through |
|---|---|
| `openship-overview` | The tool groups, each flow's entry point, and how permission scoping (incl. per-repo GitHub grants) shapes what you can see and do. |
| `deploy-from-git` | Connect/verify GitHub → pick a repo → detect the stack → create the project → deploy → watch. Optional `repo` / `branch` arguments. |
| `deploy-a-folder` | The 4-step folder-upload flow, including the out-of-band tarball upload that is deliberately **not** an MCP tool (raw binary can't cross JSON-RPC). |
| `install-catalog-app` | Browse the catalog → install → handle the `flowHref` that wizard apps (e.g. mail) return instead of installing in-band. |
| `cluster-and-scale` | Private network → k3s → deploy → scale up/down → recover/clean up. Self-hosted. |
| `cluster-database` | Create → observe → connect → PostgreSQL backup/restore-to-new → cleanup. Self-hosted. |
| `backup-and-restore` | Destination/preflight → policy → run → prepare restore → explicit apply → verify. |
| `migrate-docker-project` | Scan/map → preview → migrate → handle prompts/partial transfers → verify → explicit cutover. Self-hosted. |
Every prompt starts with workspace discovery and selection guidance. Tool references resolve against
the live registry, so a renamed route never leaves a prompt pointing at a stale tool name.
## Input and workflow contracts
Use `tools/list` as the source of truth for required fields. Path parameters are top-level, nonempty
strings. The exact values `.` and `..` are rejected so URL normalization cannot select a different
route; names containing dots, such as `.github`, remain valid. Endpoint query parameters belong in
`query`; payloads belong in `body`. Invalid or missing required arguments return
`INVALID_TOOL_ARGUMENTS` before dispatch. Optional all-default bodies are sent as `{}`.
Validation errors report field paths without echoing submitted values.
A successful call may only have **accepted** asynchronous work. Follow the returned run/deployment/operation
ID with the corresponding JSON status tool and inspect its final state. Live SSE streams and binary
uploads stay on HTTP. The job output tool returns captured output; it does not open a live stream.
Concurrency and recovery guards remain mandatory: `revision` for network/cluster configuration,
`sequence` or `expectedSequence` for durable operations, and `expectedDeploymentId` plus
`expectedUpdatedAt` for application scaling. Reuse an operation's `requestId` for the same intent after
a lost response; re-read state before retrying a conflict.
See the [generated tool catalog](/docs/api/mcp-tools) for descriptions, permissions, availability and
intentional exclusions across every route. The [cluster/scaling guide](/docs/guides/mcp-clusters-and-scaling)
covers the full lifecycle and its current limits. Policy-driven autoscaling is not implemented.
## Errors
No bearer, or one that's expired/revoked. The response carries a `WWW-Authenticate` header so OAuth clients
can start discovery; PAT clients should mint a fresh token with `openship token create`.
Expected. This is a request/response server with no server→client stream, so `GET` is not supported — always
`POST` your JSON-RPC message.
`-32700` is a JSON parse error; `-32600` is an invalid envelope or a batch (array) body, which this server
does not accept. `-32601` means the JSON-RPC method is unknown, and `-32602` means the tool name in
`tools/call` doesn't exist.
`tools/list` succeeded but a specific `tools/call` reports `404` — that's the token's scope working as
intended: it wasn't granted that project, server, or repository.
## Operations
{/* api-operations:start */}
| Operation | REST API |
| --- | --- |
| Returns `405` — this server never pushes messages, so there is no SSE stream to open. | `GET /api/mcp` `Handler authentication` |
| Stateless Streamable-HTTP JSON-RPC 2.0 endpoint. Authenticates the bearer itself, then handles `initialize`, `ping`, `tools/list`, and `tools/call`. | `POST /api/mcp` `Handler authentication` |
{/* api-operations:end */}
---
# Servers
URL: https://openship.io/docs/api/servers.md
Register and operate servers through the SDK or REST API.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Servers identify where Openship builds and runs applications. The same `serverId`
is used for Cloud-managed instances and connected SSH/local hosts. Responses
include `capabilities`; offer only the actions supported by that server. The
`terminalSessionLimit` field reports the supported concurrent host shell count.
Server administration requires a server grant. Shared host access can affect all
projects on that host. Connected hosts use their SSH configuration for deployment
access. Managed Cloud servers expose their own SSH and Runtime API controls below;
Openship continues to manage their base image and edge infrastructure.
## Managed Cloud servers
The normal Cloud flow creates the first shared server automatically when a
customer chooses a plan or creates a project. To create an additional server:
```ts
const purchaseKey = crypto.randomUUID();
const managed = await ship.servers.createManaged({ name: "Production", idempotencyKey: purchaseKey });
const checkoutKey = crypto.randomUUID();
const checkout = await ship.billing.createSubscription({
workspaceId: managed.id,
planTierId: "pro",
interval: "monthly",
idempotencyKey: checkoutKey,
});
```
Complete checkout through the [billing workflow](/docs/api/billing). Verified
payment queues server setup. Use `managed.serverId` for project placement,
server usage, terminal access and lifecycle operations. `managed.id` is the
subscription owner identifier used only for billing.
Keep the creation key and checkout key for retries after an uncertain response.
Creation reuses the same server within your organization, including its current
name; a deleted purchase cannot be recreated with its old key.
Self-hosted and desktop installations can use these same managed servers after
connecting an Openship Cloud account. Create a new server with `createManaged`,
or list and link an existing server:
```ts
const available = await ship.servers.availableManaged();
const selected = available.servers[0];
if (selected) {
const linked = await ship.servers.connectManaged({ serverId: selected.id });
console.log(linked.serverId); // This installation's deployment destination.
}
```
Linking requires administration of the server in Cloud and permission to add a
server locally. The link pins the Cloud API, account and organization. Changing
the connected account cannot silently redirect existing projects. Project
configuration stays on the installation that created it; the managed server's
subscription and host lifecycle remain controlled by Cloud.
`servers.ensure(id)`, `resize(id, input)`, `retry(id)` and `removeManaged(id, input)`
queue durable work. Poll `servers.get(id)` and read `managed.operation` for logs,
errors and retry timing. An HTTP 202 means accepted; inspect operation completion
before claiming readiness. Reads never create or resume a server.
`servers.usage(id)` returns measured host usage and accessible projects. Missing
measurements are `null`; purchased disk capacity is never substituted for bytes
used. `servers.previewResize(id)` returns the current and purchased sizes, affected
projects and a revision. After approval, send that revision with
`confirmRestart: true` and an idempotency key to `servers.resize`.
Reuse the same resize key after an uncertain response. A changed plan or project
membership requires a fresh preview. Disk shrinking requires migration. Deleting
a managed server also requires billing administration, no projects, no unsettled
checkout and an ended subscription. Deleting one project never deletes a shared
server or its siblings.
Cloud includes projects registered by linked installations when checking whether
a server is empty or safe to resize. A linked installation must finish or recover
its active operation before another controller can change that server. Cloud
cannot report complete service counts or build minutes for projects whose records
live on another installation; those billing counters are `null` rather than a
partial total. Host measurements and provider billing remain available.
`servers.getNetworkSettings(id)` reads internet access and route-managed ingress
ports. Pass `{ details: true }` to also read outbound rules, IP diagnostics and
the revision required when editing rules.
`updateNetworkSettings(id, { internetAccess, expectedInternetAccess, confirm: true })`
changes outbound internet. To edit the destination allowlist too, include `egress`
and the `expectedRevision` from the read. Disabling internet affects external APIs
and builds for every project. Ingress, domains and private connectivity remain managed by
project routing. Host terminals use the normal authenticated terminal endpoint;
the provider supports one host terminal session per managed server at a time.
Use these same operations through [MCP](/docs/api/mcp-tools), checking permissions,
capabilities and operation results. See the [managed server guide](/docs/guides/cloud-workspaces)
for deployment, capacity and recovery behavior.
## Register a server
On self-hosted Openship, register a machine you own as an SSH deployment target. Responses never include SSH secrets — passwords and key passphrases
are encrypted at rest and only decrypted inside the SSH client. See the
[custom servers guide](/docs/guides/custom-servers).
```ts
const result = await ship.servers.create({
sshHost: "203.0.113.10",
sshUser: "root",
sshAuthMethod: "agent",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/system/servers" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"sshHost":"203.0.113.10","sshUser":"root","sshAuthMethod":"agent"}'
```
`PATCH /api/system/servers/:id` takes the same fields, all optional — only the keys you send are changed.
## Managed server access and native processes
Use the Openship `serverId`, not an Oblien VM ID. Each operation resolves that
server's organization, subscription and namespace. API-key read-only restrictions
and server resource permissions apply equally to native SDK, HTTP SDK and REST.
The API and dashboard must be from a release that includes these operations.
Existing server-list and server-detail response shapes are unchanged.
`managedInfo`, `managedSshStatus`, `managedRuntimeStatus` and `managedWorkloads`
are safe reads and never start a VM. Credentials, logs and all changes require
**`server:admin`**. Gateway credentials grant full access to every project on that
server. They do not grant access to another server, namespace or the reseller account.
```ts
const info = await ship.servers.managedInfo("srv_123");
const processes = await ship.servers.managedWorkloads("srv_123");
const access = await ship.servers.managedRuntimeCredential("srv_123", { confirm: true });
// Store access.token as a secret; access.endpoint is the Runtime API origin.
```
```bash
curl -H "Authorization: Bearer $OPENSHIP_TOKEN" "$OPENSHIP_API/api/system/servers/srv_123/managed/info"
curl -X POST -H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H 'Content-Type: application/json' \
--data '{"confirm":true}' \
"$OPENSHIP_API/api/system/servers/srv_123/managed/runtime-api/credential"
```
Credential responses are `private, no-store`. Runtime reveal does not enable a
disabled API; use `enableManagedRuntime` explicitly. The Runtime API powers Openship,
so there is no managed-server disable operation. `rotateManagedRuntimeCredential`
requires `expectedRevision` from the current credential plus `confirm: true`.
A stale revision returns `409 MANAGED_RUNTIME_TOKEN_CHANGED`; reveal the current
token instead of repeatedly rotating after an uncertain response. SSH connection
responses include host, port, username, temporary password, expiry and host-key
fingerprint. SSH public-key replacement accepts one public key and affects root
access to the server; private keys are rejected.
`getNetworkSettings(id, { details: true })` (REST: `?details=true`) adds
`egress`, `revision`, `ingressAll`, `privateIp`, `outboundIp` and `outboundMode`.
Omitting this option preserves the original two-field response for existing clients.
Send `expectedInternetAccess`, `expectedRevision`, `internetAccess`,
`egress` and `confirm: true` to change outbound destinations. Use `*` alone for all
hosts, or up to 50 hostnames/IPs. When disabling internet, omit `egress`; the
provider clears it. Writes with `expectedRevision` return the detailed response;
older internet-only writes retain the original response.
A changed policy returns `409 SERVER_NETWORK_SETTINGS_CHANGED`.
The operation patches outbound fields only; routing, private peers and proxy
credentials keep their owning control flows.
A manual workload runs inside the shared server as root and consumes its existing
resources. It creates neither a project nor a public route. Creation accepts a
name, shell command, absolute `workingDirectory`, `environment` entries of the
form `KEY=value`, and a `restartPolicy` of `never`, `on-failure` or `always`.
It saves the process **stopped**. Reuse its `idempotencyKey` with the identical
request after a timeout; changing the payload under that key returns a conflict.
Then use `controlManagedWorkload` with `start`, `stop` or `delete` and `confirm: true`.
Only processes created as manual workloads can be changed here; application and
platform workloads return `409 MANAGED_WORKLOAD_PROTECTED`. Logs require a tail
of 1–500 lines and return at most 64 KiB. Lists omit commands and environments and
show `unknown` when live process status cannot be observed.
Mutations participate in the managed server's existing activity lock. Active
builds, terminal sessions, migrations or lifecycle operations may delay/refuse
changes. Resume, resize, subscription changes and image selection retain their
existing workflows; these access controls do not bypass billing or replace the VM.
## Server health check & install
```ts
const health = await ship.servers.check("srv_123", { components: ["docker"] });
console.log(health.ready, health.missing);
```
```bash
curl -X POST "$OPENSHIP_URL/api/system/check" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123","components":["docker"]}'
```
Test a connection before saving, check what a saved server has installed, then install or remove components.
These routes identify the server by `serverId` in the **body** (not a URL param), and each handler runs its
own per-server `server:admin` (or `server:read`) check.
`POST /api/system/test-connection` opens an ephemeral SSH connection from body credentials and returns
`{ ok, message }` — nothing is persisted. It requires the caller be an org owner/admin.
Returns `{ components, ready, missing }`.
`POST /api/system/remove` mirrors `install` for a single removable component. `POST /api/system/install/stream`
takes `{ serverId, components: string[], config? }` and returns a **Server-Sent Events** stream
(`progress`, `log`, `complete`, `end`); it returns **409 `install_in_progress`** if a session is already
running.
`install/stream` and `monitor/stream` are event streams. Read `GET /api/system/install/session` to poll a
running session's state instead, or `GET /api/system/install/stream?id=` to re-attach after a page
reload.
`GET /api/system/monitor/stream?serverId=` emits a `stats` event every few seconds with CPU %, memory,
disk, uptime, and load average gathered over SSH — `openship server monitor `.
## Per-server rate limiting
Read or update the OpenResty request rate limit for a server. OpenResty on the target server is the source of
truth; the API parses and rewrites its `ratelimit.conf`.
```
PATCH /api/system/servers/:id/rate-limit
```
## Port-forward tunnels
Desktop-only. Forward a remote server port to `localhost` on the operator's machine, VS Code style. Every
handler additionally asserts desktop mode; on a non-desktop instance they refuse.
```
POST /api/system/servers/:id/tunnels
```
Start / stop / delete a saved tunnel with `POST .../tunnels/:tunnelId/start`, `.../stop`, and
`DELETE .../tunnels/:tunnelId`. A started tunnel returns the actually-bound `localPort` and a
`http://localhost:` URL.
## Server clusters and private networking
On a self-hosted OpenShip instance, private networks connect 2–16 registered Linux
servers over an existing private IPv4 network or a managed WireGuard mesh. Read
`ship.servers.networkCapabilities()` for the available provider profiles and your
management permissions. Local and desktop self-hosted controllers support
network inventory and manual network checks. Oblien-managed Cloud does not offer
this infrastructure management.
Compute clusters are separate records that group selected servers on an existing
private network. Use the `*Network` methods and `/api/system/networks` for networking,
and `*ComputeCluster` methods and `/api/system/compute-clusters` for those groups.
The older `*Cluster` methods and `/api/system/clusters` URLs remain compatibility
aliases for private networks.
For existing networks, create saves configuration; verify starts a separate, persisted operation.
Reuse the same `requestId` when retrying an unchanged creation request. Update,
verify, and remove require the network's current `revision`. Concurrent edits
return a conflict, and active verification blocks configuration changes.
```ts
const network = await ship.servers.createNetwork({
requestId: crypto.randomUUID(),
name: "Production EU",
network: {
mode: "native",
cidrs: ["10.20.0.0/24"],
mtu: 1400,
probePort: 51821,
},
members: [
{ serverId: "srv_a", providerId: "hetzner-dedicated", privateIp: "10.20.0.2" },
{ serverId: "srv_b", providerId: "hetzner-dedicated", privateIp: "10.20.0.3" },
],
});
const verification = await ship.servers.verifyNetwork({
networkId: network.id,
revision: network.revision,
});
console.log(verification.id, verification.status);
```
Subscribe to the read-only SSE endpoint `GET /api/system/networks/stream` for
verification progress, including after reconnecting. Use
`ship.servers.getNetwork({ networkId })` to read a saved snapshot. Reports contain
per-direction TCP, UDP, MTU, UDP round-trip latency, packet loss, and jitter
results. Managed WireGuard reports also contain per-peer handshake observations.
Hosts need Linux, Python 3, iproute2, a persistent
machine identity, and working private interfaces and routes. The chosen probe
port must permit TCP and UDP between members. The inspector
`ship.servers.inspectNetwork(serverId)` reads interfaces without configuring them.
Temporary authenticated listeners bind to the selected private addresses and
expire locally if cleanup loses contact. Runs expire after four minutes;
successful observations are considered stale after fifteen minutes. The probe
tests its selected port and packet size. Encryption and application-port access
are not verified.
After a verification has finished, optionally measure a selected connection in
both directions using the same endpoint:
```ts
const network = await ship.servers.getNetwork({ networkId: "network_id" });
const speedTest = await ship.servers.verifyNetwork({
networkId: network.id,
revision: network.revision,
speedTest: { sourceServerId: "srv_a", targetServerId: "srv_b" },
});
```
Speed tests first check connectivity, then transfer at most 32 MiB or for three
seconds per direction. `report.throughput` records receiver-confirmed bytes,
elapsed time, and Mbps, or a specific transfer error. Ordinary verification does
not send bulk traffic. Both servers must belong to the private network; a different test
cannot start while a verification is active. Repeating an active request for the
same pair reuses its run. Progress and final results use the same SSE stream.
Network reads require fleet-wide server read access. Management requires
fleet-wide server admin access, with each member also authorized. Removing an
adopted private network removes OpenShip's inventory records; servers and the
externally managed network remain. Managed networks use the reviewed cleanup
flow below. Membership and active operations must be settled before removing a
server. A private network connects hosts; a [compute cluster](#compute-clusters)
with a ready runtime can run [application replicas and databases](/docs/api/projects#scale-a-stateless-application-on-a-cluster).
[Shared storage](#share-files-across-servers) is enabled separately. Provider
API/VLAN provisioning remains outside the managed-network setup.
### Managed private networks
Managed networking creates an encrypted WireGuard mesh with automatically
allocated private addresses. Start server preparation to check infrastructure,
install missing tools, and create a reviewable plan:
```ts
const preparation = await ship.servers.prepareManagedNetwork({
requestId: crypto.randomUUID(),
name: "Production mesh",
members: [
{ serverId: "srv_a", providerId: "hetzner-dedicated" },
{ serverId: "srv_b", providerId: "custom" },
],
});
console.log(preparation.id, preparation.status, preparation.hosts);
for await (const event of ship.servers.managedNetworkPreparationEvents(preparation.id)) {
if (event.event === "snapshot") {
const { run } = JSON.parse(event.data);
console.log(run.sequence, run.status, run.hosts);
}
}
```
The subscription sends a complete saved `snapshot` on connect and whenever progress
changes, then `complete` before closing for a settled attempt. The dashboard reconnects
with backoff after a dropped connection. SDK callers can reattach using the same
method; a reconnect never starts work. Replace local state with each snapshot instead
of appending its logs. The monotonic `sequence` also protects against late responses.
`ship.servers.getManagedNetworkPreparation({ preparationId })` remains available for
a single saved-state read. When its status is `ready`, use its `operationId` to
read the network plan. Retry a failed or interrupted preparation by calling
`prepareManagedNetwork` with the same input and request ID. Already healthy tools
are checked and reused. `listManagedNetworkPreparations()` lists recent work that
still needs attention or review. No tunnel changes start during preparation.
To discard a stopped preparation, call
`discardManagedNetworkPreparation({ preparationId, sequence })` with its latest
progress sequence. An unapplied plan can be discarded with
`discardManagedNetworkPlan({ operationId, planHash })`. Both require fleet
administration. The preparation and any unapplied plan close in one transaction
and disappear from pending setup; existing servers, services, and installed tools
are retained. Cancelled records remain readable for diagnostics and prevent late
retries from reviving discarded work. Active preparation must finish first.
To remove one server from an unfinished **initial cluster setup**, call
`removeManagedNetworkPreparationMember({ preparationId, serverId, sequence, requestId })`.
For an initial network operation, use
`removeManagedNetworkOperationMember({ operationId, serverId, sequence, planHash, requestId })`.
At least two servers must remain. Use a new UUID for `requestId`, then reuse it if
the response is lost. A different selection requires a different request.
Both methods require fleet administration and return `{ preparation, operation }`.
The original records link to the replacement through `replacementPreparationId`;
settings and diagnostics remain available, and the original request cannot resume.
Before network apply, removal cancels the old selection and saves the remaining
servers in a paused (`pending`) preparation. After a partial apply, it also has a
`cleanupOperationId`. OpenShip reuses rollback to restore this attempt's network
changes on **all original hosts**, including peer entries for the removed server.
The server, its workloads, disks, other networks, and shared installed tools remain.
The pending preparation stream stays open while cleanup runs; subscribe to the
cleanup operation for per-host progress. An unreachable or externally modified
host keeps cleanup and reservations open. Retry that operation with
`action: "rollback"` after resolving the problem. Once all hosts acknowledge
rollback, preparation remains paused. Explicitly call `prepareManagedNetwork` with
the replacement's saved input to retry; it rejects the request until cleanup is
complete. Removal, cleanup retries, and stream reconnection do not start preparation.
The resulting network plan always requires a fresh review and apply.
Established clusters use their existing reviewed membership-change workflow.
For hosts that already meet the prerequisites, `planManagedNetwork` accepts the
same input and performs read-only inspection without installing packages.
After review, pass that operation ID and hash to
`ship.servers.applyManagedNetwork({ operationId, planHash, action: "apply" })`.
Plans expire after fifteen minutes and reject changes to the cluster revision,
host identities, or inspected networking. Subscribe with
`ship.servers.managedNetworkOperationEvents(operationId)` for durable progress;
`getManagedNetworkOperation({ operationId })` provides a single state read.
The same operation supports `action: "resume"` or `action: "rollback"` after an
interruption. Active work is idempotent and cannot be started twice.
Once network changes have started, discard is blocked. Use `action: "rollback"`
to clean up an unfinished new cluster or restore an existing cluster's previous
network. Every host must acknowledge cleanup before inventory and reservations
are released. An unreachable host keeps recovery open; retry rollback when access
is restored. A restored existing cluster can then use the reviewed removal flow.
`ship.servers.clusterEvents()` streams overview snapshots containing `clusters` and
`preparations`. All three subscription methods accept `{ signal }` to disconnect a
viewer without cancelling setup. Streams use saved database state, validate fleet
read permission again during the subscription, and reconcile every fifteen seconds
to detect another controller's updates and expired worker leases.
Hosts require Linux with WireGuard kernel support, Python 3.8+, iproute2, systemd,
and root or passwordless sudo. Preparation automatically installs missing
Python 3.8+, iproute2 (4.15+), and WireGuard tools (1.0+) through the shared toolchain.
It verifies installation before inspection. Kernel, init-system, and privilege
problems stop at a named step; OpenShip does not replace kernels or reboot hosts.
Installed tools remain installed if the later network operation rolls back. Supported
firewalls are no active host firewall, raw iptables, or nftables with standard
`inet filter input/output` chains and no additional filtering IPv4 input/output
base chains. UFW, firewalld, and unsupported nftables layouts fail inspection.
Provider firewalls must allow the reviewed transport ports (default 51820/UDP).
Transport uses reachable IPv4 endpoints with no relay or automatic NAT traversal.
IPv6 SSH management works when explicit IPv4 transport endpoints are supplied.
Preparation checks local prerequisites and routes; it does not prove UDP access
between hosts. After Apply, the `transport` step stages WireGuard endpoints and
owned host firewall rules. The `handshake` step tests every peer before `configure`
assigns private addresses and routes. Failures retain per-peer endpoints and ports
and restore the previous configuration. Provider firewall or NAT changes require
administrator action before an explicit retry.
Private keys stay on their hosts. Each host has a persistent twenty-minute
rollback timer, so incomplete setup can restore even if the controller disconnects
or the host reboots. OpenShip changes only its own interface, peer routes, and
firewall rules. The transport stage uses the same receipt and rollback timer;
successful promotion preserves the verified interface and keys. Handshakes and
every directed TCP/UDP/MTU check must succeed before
commit. Committed networking restarts locally without the controller. Unreachable
or externally edited hosts retain their claims until recovery is confirmed.
For managed edits, include `clusterId` and `revision` in a new plan. Membership,
transport endpoints/ports, MTU, and `rotateKeys` can change; existing addresses and
the allocated subnet remain stable. To remove a managed cluster, plan with
`intent: "remove"` and review its host cleanup before applying. These network
operations do not drain workloads or migrate their data.
## Compute clusters
Create a compute cluster by selecting servers already attached to a private network.
The network and compute-cluster memberships are independent. Reuse the same
`requestId` to retry an unchanged create request; updates and removals require the
compute cluster's current `revision`.
```ts
const cluster = await ship.servers.createComputeCluster({
requestId: crypto.randomUUID(),
name: "Production EU",
networkId: "network_id",
serverIds: ["srv_a", "srv_b"],
});
console.log(cluster.id, cluster.networkId, cluster.serverIds);
```
`removeComputeCluster({ clusterId, revision })` removes this grouping and retains
its servers and private network. `ship.servers.infrastructure(serverId)` reports
the networks and compute cluster associated with a server.
### Managed K3s setup
Creating a pool does not install software. Start its separate runtime operation
after connecting the selected servers to their private network:
```ts
const runtime = await ship.servers.setupClusterRuntime({
clusterId: "cluster_id",
revision: 1,
requestId: crypto.randomUUID(),
});
console.log(runtime.status);
const abort = new AbortController();
for await (const event of ship.servers.clusterRuntimeEvents("cluster_id", { signal: abort.signal })) {
console.log(event.data);
abort.abort(); // Close the subscription when leaving the setup view.
break;
}
```
Setup installs missing tools, pins and checksum-verifies K3s, configures private
host firewall rules, joins the servers, and checks actual pod traffic, Services
and DNS. One control server is used for one/two-member pools; larger pools use
three controls and additional workers. Initial support requires Linux
amd64/arm64, systemd, root or passwordless sudo, disabled swap, and unfiltered or
raw iptables host firewalls. Provider private-network ACLs remain the operator's
responsibility; the dashboard lists exact private peer ports. These ports should
not be exposed publicly.
Read saved progress with `getClusterRuntime({ clusterId })`; it returns `null`
before setup. Retry an interrupted or failed operation explicitly using
`retryClusterRuntime({ clusterId, sequence })`. The retry retains the pinned
version/configuration and reconciles host state. Reconnecting to SSE never starts
or retries installation. Runtime streams remain open to observe later changes;
cancel them when leaving the page. Snapshots contain dated verification, not
continuous workload monitoring.
`removeClusterRuntime({ clusterId, sequence })` starts owned cleanup. Application
workloads, persistent volumes and additional operators must be removed first.
Cleanup preserves the private network and existing Docker applications, and can
resume after a partial removal. Removing the pool or changing its members/network
is blocked while a runtime remains installed or unfinished.
Once setup is ready, select the cluster from a project's topology to run the
application across its servers, or add managed PostgreSQL and Redis databases.
Existing project deployments move only when you select the new target and deploy.
### Share files across servers
Use **Share storage** on the cluster to prepare independent copies on at least two
servers. The setup installs required tools, checks the selected empty directories,
configures shared storage and verifies a write/read across servers. It never
formats disks. Its technical implementation is shown in collapsed details.
`setupClusterStorage` accepts the reviewed disks, copy count and a stable request ID.
Read `getClusterStorage` or subscribe to `clusterStorageEvents` until setup is ready.
After an interruption, inspect the saved error and explicitly retry with the latest
sequence. Use `observe: true` when reading status for current capacity and disk health.
Choose an external backup destination to enable recoverable file archives. Projects
can then create, mount, expand, back up and restore their own shared volumes.
Replicated copies keep files available inside the cluster; an external backup
provides a recovery point after deletion or data corruption.
Disconnect and remove project volumes before removing shared storage. Empty-storage
cleanup preserves external archives and the cluster's other storage classes. Remove
shared storage before removing the cluster runtime.
## Operations
{/* api-operations:start */}
### Managed containers
| Operation | SDK | REST API |
| --- | --- | --- |
| Apply a managed container configuration. | `servers.applyContainer(id, input, options?)` | `POST /api/system/servers/:id/containers/:component/apply/stream` `server:write` · Self-hosted |
| Stream a managed-container apply session. | `servers.containerApplyEvents(id, input, options?)` | `GET /api/system/servers/:id/containers/:component/apply/stream` `server:read` · Self-hosted |
| List managed containers across accessible servers. | `servers.listAllContainers()` | `GET /api/system/containers` `server:read` · Self-hosted |
| Refresh managed-container state across accessible servers. | `servers.scanAllContainers()` | `POST /api/system/containers/scan` `server:write` · Self-hosted |
| List managed containers with available updates. | `servers.containersBehind()` | `GET /api/system/containers/behind` `server:read` · Self-hosted |
| List managed-container health or configuration issues. | `servers.containerIssues()` | `GET /api/system/containers/issues` `server:read` · Self-hosted |
| Read currently active container apply sessions. | `servers.applyingContainers()` | `GET /api/system/containers/applying` `server:read` · Self-hosted |
| Apply requested managed-container changes across servers. | `servers.applyAllContainers(input?)` | `POST /api/system/containers/apply-all` `server:write` · Self-hosted |
| List one server’s managed containers. | `servers.listContainers(id)` | `GET /api/system/servers/:id/containers` `server:read` · Self-hosted |
| Refresh one server’s managed-container state. | `servers.scanContainers(id)` | `POST /api/system/servers/:id/containers/scan` `server:write` · Self-hosted |
| Read a container’s active apply session. | `servers.containerApplySession(id, input)` | `GET /api/system/servers/:id/containers/:component/apply/session` `server:read` · Self-hosted |
### Components and installation
| Operation | SDK | REST API |
| --- | --- | --- |
| Read an installation session. | `servers.getInstallSession(input?)` | `GET /api/system/install/session` `server:read` · Self-hosted |
| Answer a pending installation prompt. | `servers.respondToInstall(input)` | `POST /api/system/install/respond` `server:admin` · Self-hosted |
| Submit installation of selected components. | `servers.installComponents(id, input, options?)` | `POST /api/system/install/stream` `server:admin` · Self-hosted |
| Stream installation progress. | `servers.installEvents(input?, options?)` | `GET /api/system/install/stream` `server:read` · Self-hosted |
| List the server’s managed components. | `servers.listModules(id)` | `GET /api/system/servers/:id/modules` `server:read` · Self-hosted |
| Refresh managed-component state. | `servers.scanModules(id)` | `POST /api/system/servers/:id/modules/scan` `server:write` · Self-hosted |
| Apply a managed component’s configuration. | `servers.applyModule(id, input)` | `POST /api/system/servers/:id/modules/:module/apply` `server:write` · Self-hosted |
| Install one managed component. | `servers.installComponent(id, input)` | `POST /api/system/install` `server:admin` · Self-hosted |
| Remove a managed component. | `servers.removeComponent(id, input)` | `POST /api/system/remove` `server:admin` · Self-hosted |
### Server lifecycle
| Operation | SDK | REST API |
| --- | --- | --- |
| Stream server monitoring data. | `servers.monitor(id, options?)` | `GET /api/system/monitor/stream` `server:read` |
| List accessible connected or managed servers with their supported capabilities. | `servers.list()` | `GET /api/system/servers` `server:list` |
| Register an SSH server. | `servers.create(input)` | `POST /api/system/servers` `server:write` · Self-hosted |
| Test the supplied SSH connection configuration. | `servers.testConnection(input)` | `POST /api/system/test-connection` `server:write` · Self-hosted |
| Read the private networks and compute cluster associated with a server. | `servers.infrastructure(id)` | `GET /api/system/servers/:id/infrastructure` `server:read` · Self-hosted |
| Read server details, managed plan, live provider state and durable operation progress. | `servers.get(id)` | `GET /api/system/servers/:id` `server:read` |
| Read server reachability. | `servers.reachability(id)` | `GET /api/system/servers/:id/reachability` `server:read` |
| Change registered server configuration. | `servers.update(id, input)` | `PATCH /api/system/servers/:id` `server:write` |
| Inspect workloads affected by removing the server. | `servers.deletionPreview(id)` | `GET /api/system/servers/:id/deletion-preview` `server:read` · Self-hosted |
| Remove a server using the requested workload cleanup policy. | `servers.remove(id, input?)` | `DELETE /api/system/servers/:id` `server:admin` · Self-hosted |
| Execute an authorized command on the server. | `servers.exec(id, input)` | `POST /api/system/servers/:id/exec` `server:admin` |
| Run a server health check. | `servers.check(id, input?)` | `POST /api/system/check` `server:admin` |
| Scan ports on an authorized server. | `servers.scanPorts(id)` | `POST /api/system/servers/:id/ports/scan` `server:read` |
### Private networks
| Operation | SDK | REST API |
| --- | --- | --- |
| Read infrastructure availability, provider profiles, and supported network operations. | `servers.networkCapabilities()` | `GET /api/system/networks/capabilities` `server:read` · Self-hosted |
| List organization-owned private networks and their latest verification. | `servers.listNetworks()` | `GET /api/system/networks` `server:read` · Self-hosted |
| Read a private network, its server attachments, and verification report. | `servers.getNetwork(input)` | `GET /api/system/networks/:id` `server:read` · Self-hosted |
| Save an existing private network using an idempotent request ID. | `servers.createNetwork(input)` | `POST /api/system/networks` `server:admin` · Self-hosted |
| Update idle native-network inventory using its current revision; invalidate earlier verification. | `servers.updateNetwork(input)` | `PATCH /api/system/networks/:id` `server:admin` · Self-hosted |
| Verify private connectivity, latency, and loss; optionally measure bounded throughput for a selected pair. | `servers.verifyNetwork(input)` | `POST /api/system/networks/:id/verify` `server:admin` · Self-hosted |
| Remove unused native-network inventory at the current revision, preserving servers and external networks. | `servers.removeNetwork(input)` | `DELETE /api/system/networks/:id` `server:admin` · Self-hosted |
| Revise the private connection policy of stopped setup using its current progress sequence and an idempotent request ID. | `servers.reviseManagedNetworkAccess(input)` | `PATCH /api/system/networks/preparations/:preparationId/connections` `server:admin` · Self-hosted |
| Prepare missing networking tools on selected servers, retain per-step logs, and produce a reviewable plan. Repeat the same request to retry a failed preparation. | `servers.prepareManagedNetwork(input)` | `POST /api/system/networks/preparations` `server:admin` · Self-hosted |
| Read saved prerequisite checks, installation logs, failures, and the resulting network operation. | `servers.getManagedNetworkPreparation(input)` | `GET /api/system/networks/preparations/:preparationId` `server:read` · Self-hosted |
| Discard stopped setup and its unapplied plan using the current progress sequence. Installed tools and servers are retained; completed network cleanup is required once apply has started. | `servers.discardManagedNetworkPreparation(input)` | `DELETE /api/system/networks/preparations/:preparationId` `server:admin` · Self-hosted |
| Remove one server from stopped initial setup and save a paused replacement selection. Preparation starts only on explicit retry; diagnostics, services, data, and installed tools are retained. | `servers.removeManagedNetworkPreparationMember(input)` | `DELETE /api/system/networks/preparations/:preparationId/members/:serverId` `server:admin` · Self-hosted |
| Remove a server from an unfinished initial network operation. Restore its changes on the original hosts and save the remaining selection, paused until preparation is explicitly retried. | `servers.removeManagedNetworkOperationMember(input)` | `DELETE /api/system/networks/operations/:operationId/members/:serverId` `server:admin` · Self-hosted |
| List recent server preparations that still need attention or network review. | `servers.listManagedNetworkPreparations()` | `GET /api/system/networks/preparations` `server:read` · Self-hosted |
| Subscribe to saved preparation snapshots and completion. Reconnecting only reads progress; it never restarts preparation. | `servers.managedNetworkPreparationEvents(id, options?)` | `GET /api/system/networks/preparations/:preparationId/stream` `server:read` · Self-hosted |
| Subscribe to durable network apply, verification, and recovery progress. | `servers.managedNetworkOperationEvents(id, options?)` | `GET /api/system/networks/operations/:operationId/stream` `server:read` · Self-hosted |
| Subscribe to private-network overview and unfinished preparation snapshots. | `servers.clusterEvents(options?)` | `GET /api/system/networks/stream` `server:read` · Self-hosted |
| Inspect servers and persist a reviewable WireGuard plan without changing host networking. | `servers.planManagedNetwork(input)` | `POST /api/system/networks/plans` `server:admin` · Self-hosted |
| Read a managed network plan, per-host progress, verification, and recovery state. | `servers.getManagedNetworkOperation(input)` | `GET /api/system/networks/operations/:operationId` `server:read` · Self-hosted |
| Apply an approved network plan, resume an interrupted operation, or restore its previous network. | `servers.applyManagedNetwork(input)` | `POST /api/system/networks/operations/:operationId/apply` `server:admin` · Self-hosted |
| Discard an unapplied plan and its stopped preparation atomically. Active or unresolved host changes must be recovered through the network operation. | `servers.discardManagedNetworkPlan(input)` | `DELETE /api/system/networks/operations/:operationId` `server:admin` · Self-hosted |
| Inspect a server’s machine identity and private interfaces without changing its network. | `servers.inspectNetwork(id)` | `POST /api/system/servers/:id/network/inspect` `server:admin` · Self-hosted |
### Compute clusters
| Operation | SDK | REST API |
| --- | --- | --- |
| List organization-owned compute clusters and their private networks. | `servers.listComputeClusters()` | `GET /api/system/compute-clusters` `server:read` · Self-hosted |
| Read a compute cluster, its selected servers, and private network. | `servers.getComputeCluster(input)` | `GET /api/system/compute-clusters/:id` `server:read` · Self-hosted |
| Group selected servers on an existing private network using an idempotent request ID. | `servers.createComputeCluster(input)` | `POST /api/system/compute-clusters` `server:admin` · Self-hosted |
| Update a compute cluster and its selected servers using the current revision. | `servers.updateComputeCluster(input)` | `PATCH /api/system/compute-clusters/:id` `server:admin` · Self-hosted |
| Remove compute-cluster inventory at the current revision, retaining its servers and private network. | `servers.removeComputeCluster(input)` | `DELETE /api/system/compute-clusters/:id` `server:admin` · Self-hosted |
### Cluster runtime
| Operation | SDK | REST API |
| --- | --- | --- |
| Read saved K3s setup, verification and cleanup progress; null before setup. | `servers.getClusterRuntime(input)` | `GET /api/system/compute-clusters/:id/runtime` `server:read` · Self-hosted |
| Start automated K3s setup with the compute-cluster revision and an idempotent request ID. | `servers.setupClusterRuntime(input)` | `POST /api/system/compute-clusters/:id/runtime` `server:admin` · Self-hosted |
| Resume failed or interrupted setup or removal using its current progress sequence. | `servers.retryClusterRuntime(input)` | `POST /api/system/compute-clusters/:id/runtime/retry` `server:admin` · Self-hosted |
| Remove the owned runtime after verifying an empty cluster, retaining Docker services and networking. | `servers.removeClusterRuntime(input)` | `DELETE /api/system/compute-clusters/:id/runtime` `server:admin` · Self-hosted |
| Subscribe to saved runtime progress through read-only, replayable SSE. | `servers.clusterRuntimeEvents(id, options?)` | `GET /api/system/compute-clusters/:id/runtime/stream` `server:read` · Self-hosted |
### Shared storage
| Operation | SDK | REST API |
| --- | --- | --- |
| Read saved storage setup and capacity, or request current disk and volume health with observe=true. | `servers.getClusterStorage(input)` | `GET /api/system/compute-clusters/:id/storage` `server:read` · Self-hosted |
| Enable shared storage across reviewed cluster servers and empty directories. Installs prerequisites without formatting disks; a stable request ID avoids duplicate setup. | `servers.setupClusterStorage(input)` | `POST /api/system/compute-clusters/:id/storage` `server:admin` · Self-hosted |
| Explicitly resume failed or interrupted setup or removal using its current sequence. | `servers.retryClusterStorage(input)` | `POST /api/system/compute-clusters/:id/storage/retry` `server:admin` · Self-hosted |
| Configure an external backup destination using the current storage sequence. An existing destination is preserved so its archives remain recoverable. | `servers.configureClusterStorageBackup(input)` | `PATCH /api/system/compute-clusters/:id/storage/backup` `server:admin` · Self-hosted |
| Remove an empty storage installation using its latest sequence. Persistent or retained volumes block removal; external archives are preserved. | `servers.removeClusterStorage(input)` | `DELETE /api/system/compute-clusters/:id/storage` `server:admin` · Self-hosted |
| Subscribe to saved storage setup and removal progress through replayable SSE. | `servers.clusterStorageEvents(id, options?)` | `GET /api/system/compute-clusters/:id/storage/stream` `server:read` · Self-hosted |
### Legacy network methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Compatibility method for private-network capabilities; prefer networkCapabilities. | `servers.clusterCapabilities()` | `GET /api/system/clusters/capabilities` `server:read` · Self-hosted |
| Compatibility method for private-network inventory; prefer listNetworks. | `servers.listClusters()` | `GET /api/system/clusters` `server:read` · Self-hosted |
| Read private-network details using the legacy clusterId input; prefer getNetwork. | `servers.getCluster(input)` | `GET /api/system/clusters/:id` `server:read` · Self-hosted |
| Create private-network inventory using the legacy method; prefer createNetwork. | `servers.createCluster(input)` | `POST /api/system/clusters` `server:admin` · Self-hosted |
| Update private-network inventory using the legacy clusterId input; prefer updateNetwork. | `servers.updateCluster(input)` | `PATCH /api/system/clusters/:id` `server:admin` · Self-hosted |
| Verify private-network connectivity using the legacy clusterId input; prefer verifyNetwork. | `servers.verifyCluster(input)` | `POST /api/system/clusters/:id/verify` `server:admin` · Self-hosted |
| Remove native-network inventory using the legacy clusterId input; prefer removeNetwork. | `servers.removeCluster(input)` | `DELETE /api/system/clusters/:id` `server:admin` · Self-hosted |
### Git credentials
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the server’s GitHub authentication status. | `servers.githubStatus(id)` | `GET /api/system/servers/:id/github` `server:read` · Self-hosted |
| Start GitHub authentication for a server. | `servers.connectGitHub(id)` | `POST /api/system/servers/:id/github/connect` `server:write` · Self-hosted |
| Poll a server’s GitHub authentication flow. | `servers.pollGitHubConnection(id)` | `GET /api/system/servers/:id/github/connect/poll` `server:read` · Self-hosted |
| Store a GitHub token for a server. | `servers.setGitHubToken(id, input)` | `PUT /api/system/servers/:id/github/token` `server:write` · Self-hosted |
| Generate a GitHub SSH key on the server. | `servers.generateGitHubKey(id)` | `POST /api/system/servers/:id/github/ssh-key` `server:write` · Self-hosted |
| Select repository deploy keys for server clones. | `servers.useGitHubDeployKeys(id)` | `PUT /api/system/servers/:id/github/deploy-key-mode` `server:write` · Self-hosted |
| Remove the server’s GitHub authentication. | `servers.disconnectGitHub(id)` | `DELETE /api/system/servers/:id/github` `server:write` · Self-hosted |
### Networking
| Operation | SDK | REST API |
| --- | --- | --- |
| List the server’s port-forward configurations. | `servers.listTunnels(id)` | `GET /api/system/servers/:id/tunnels` `server:read` · Self-hosted |
| Create or update a port-forward configuration. | `servers.saveTunnel(id, input)` | `POST /api/system/servers/:id/tunnels` `server:write` · Self-hosted |
| Start an authorized port forward. | `servers.startTunnel(id, input)` | `POST /api/system/servers/:id/tunnels/:tunnelId/start` `server:write` · Self-hosted |
| Stop a port forward. | `servers.stopTunnel(id, input)` | `POST /api/system/servers/:id/tunnels/:tunnelId/stop` `server:write` · Self-hosted |
| Remove a port-forward configuration. | `servers.removeTunnel(id, input)` | `DELETE /api/system/servers/:id/tunnels/:tunnelId` `server:write` · Self-hosted |
| Read per-server request rate-limit configuration. | `servers.getRateLimit(id)` | `GET /api/system/servers/:id/rate-limit` `server:read` · Self-hosted |
| Update per-server request rate limits. | `servers.updateRateLimit(id, input)` | `PATCH /api/system/servers/:id/rate-limit` `server:admin` · Self-hosted |
### Managed servers
| Operation | SDK | REST API |
| --- | --- | --- |
| Create a server identity without purchasing or provisioning resources. | `servers.createManaged(input)` | `POST /api/system/servers/managed` `server:admin` |
| List servers available through the connected Cloud account without creating resources or copying projects. | `servers.availableManaged()` | `GET /api/system/servers/managed/available` `server:admin` |
| Link an existing Cloud server to this organization after verifying its administrator and account identity; return the local serverId for deployments. | `servers.connectManaged(input)` | `POST /api/system/servers/managed/connect` `server:admin` |
| Measure host usage and accessible project disk data separately from provisioned capacity. | `servers.usage(id)` | `GET /api/system/servers/:id/usage` `server:read` |
| Queue idempotent provisioning or resume of the subscribed Docker host. | `servers.ensure(id)` | `POST /api/system/servers/:id/ensure` `server:write` |
| Retry a failed server operation using its saved provider identity and recovery checkpoint. | `servers.retry(id)` | `POST /api/system/servers/:id/retry` `server:admin` |
| Preview purchased capacity and projects that may restart, without changing the host. | `servers.previewResize(id)` | `GET /api/system/servers/:id/resize` `server:read` |
| Queue a reviewed resize with a revision, request key and explicit restart confirmation. | `servers.resize(id, input)` | `POST /api/system/servers/:id/resize` `server:admin` |
| Remove an empty server after its subscription ends and provider cleanup is confirmed. | `servers.removeManaged(id, input)` | `DELETE /api/system/servers/:id/managed` `server:admin` |
| Read outbound internet and route-managed ingress without starting the server; request details for egress rules, IP diagnostics and a revision. | `servers.getNetworkSettings(id, input?)` | `GET /api/system/servers/:id/network-settings` `server:read` |
| Change outbound internet after confirming its effect on every project; preserve ingress and private connectivity. | `servers.updateNetworkSettings(id, input)` | `PATCH /api/system/servers/:id/network-settings` `server:admin` |
### Observe
| Operation | SDK | REST API |
| --- | --- | --- |
| Read accessible deployment servers, including linked managed servers, with their capabilities and readiness. | `servers.destinations()` | `GET /api/system/servers/destinations` `server:list` |
### Managed server controls
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the current outbound connection and revision without proxy credentials. Does not start the managed server. | `servers.managedOutbound(id)` | `GET /api/system/servers/:id/managed/outbound` `server:read` |
| List available managed outbound IPs and countries for this owned server, without credentials or internal pool identifiers. | `servers.managedOutboundOptions(id)` | `GET /api/system/servers/:id/managed/outbound/options` `server:read` |
| Apply a reviewed managed IP or custom public IPv4 HTTP/HTTPS proxy using expectedRevision and confirm:true. Changes outgoing connections for all projects; preserves internet policy, ingress and routes. Credentials are never returned or audited. | `servers.setManagedOutbound(id, input)` | `PATCH /api/system/servers/:id/managed/outbound` `server:admin` |
| Read the selected managed server image, operating system, lifecycle and purchased allocation. Does not start the VM or return its raw configuration. | `servers.managedInfo(id)` | `GET /api/system/servers/:id/managed/info` `server:read` |
| Read a bounded tail of managed server boot logs. Requires server admin; logs may contain application output. | `servers.managedBootLogs(id, input)` | `POST /api/system/servers/:id/managed/boot-logs` `server:admin` |
| Read SSH enablement and public connection instructions for this managed server. Never returns passwords. | `servers.managedSshStatus(id)` | `GET /api/system/servers/:id/managed/ssh` `server:read` |
| Enable or disable SSH with explicit confirmation and expected enablement. Changes all SSH users on this server. | `servers.setManagedSsh(id, input)` | `PATCH /api/system/servers/:id/managed/ssh` `server:admin` |
| Replace the root authorized public key on this server. Accepts one OpenSSH public key; never a private key. Requires confirmation. | `servers.setManagedSshKey(id, input)` | `PUT /api/system/servers/:id/managed/ssh/key` `server:admin` |
| Set the root SSH password on this managed server. Requires confirmation. The password is never returned or audited. | `servers.setManagedSshPassword(id, input)` | `PUT /api/system/servers/:id/managed/ssh/password` `server:admin` |
| Issue a short-lived SSH connection for this managed server. Requires server admin and confirmation. Treat its password as a secret. | `servers.managedSshConnection(id, input)` | `POST /api/system/servers/:id/managed/ssh/connection` `server:admin` |
| Read the managed server Runtime API status without enabling it or returning a token. | `servers.managedRuntimeStatus(id)` | `GET /api/system/servers/:id/managed/runtime-api` `server:read` |
| Enable the Runtime API used by Openship for deployments and server management. Requires server admin and active server entitlement. | `servers.enableManagedRuntime(id, input)` | `POST /api/system/servers/:id/managed/runtime-api/enable` `server:admin` |
| Reveal the current workspace-only Runtime API credential. Requires server admin and confirmation. Does not enable the service or issue an account/namespace token. | `servers.managedRuntimeCredential(id, input)` | `POST /api/system/servers/:id/managed/runtime-api/credential` `server:admin` |
| Rotate the Runtime API credential after reviewing the current revision. Invalidates prior tokens and sessions. A stale revision cannot repeat a successful rotation. | `servers.rotateManagedRuntimeCredential(id, input)` | `POST /api/system/servers/:id/managed/runtime-api/rotate` `server:admin` |
| List native managed processes with live status, capped at 100 entries. Distinguishes manual, project and system workloads; does not return environments or commands. | `servers.managedWorkloads(id)` | `GET /api/system/servers/:id/managed/workloads` `server:read` |
| Read bounded logs for a process on this managed server. Requires server admin. Process ID is scoped to the server. | `servers.managedWorkloadLogs(id, input)` | `POST /api/system/servers/:id/managed/workloads/logs` `server:admin` |
| Create a stopped manual native process on this server. Reuse the same idempotency key after an uncertain response. Commands and environment are admin-only and not audited. Start it explicitly after creation. | `servers.createManagedWorkload(id, input)` | `POST /api/system/servers/:id/managed/workloads` `server:admin` |
| Start, stop or delete a manual process created by the server controls. Requires confirmation. Project and platform processes must use their own lifecycle controls. | `servers.controlManagedWorkload(id, input)` | `POST /api/system/servers/:id/managed/workloads/control` `server:admin` |
### Legacy network URLs
| Operation | SDK | REST API |
| --- | --- | --- |
| Compatibility alias for `POST /api/system/networks/preparations`. | HTTP only | `POST /api/system/clusters/network-preparations` `server:admin` · Self-hosted |
| Compatibility alias for `GET /api/system/networks/preparations/:preparationId`. | HTTP only | `GET /api/system/clusters/network-preparations/:preparationId` `server:read` · Self-hosted |
| Compatibility alias for `DELETE /api/system/networks/preparations/:preparationId`. | HTTP only | `DELETE /api/system/clusters/network-preparations/:preparationId` `server:admin` · Self-hosted |
| Compatibility alias for `DELETE /api/system/networks/preparations/:preparationId/members/:serverId`. | HTTP only | `DELETE /api/system/clusters/network-preparations/:preparationId/members/:serverId` `server:admin` · Self-hosted |
| Compatibility alias for `DELETE /api/system/networks/operations/:operationId/members/:serverId`. | HTTP only | `DELETE /api/system/clusters/network-operations/:operationId/members/:serverId` `server:admin` · Self-hosted |
| Compatibility alias for `GET /api/system/networks/preparations`. | HTTP only | `GET /api/system/clusters/network-preparations` `server:read` · Self-hosted |
| Compatibility alias for `GET /api/system/networks/preparations/:preparationId/stream`. | HTTP only | `GET /api/system/clusters/network-preparations/:preparationId/stream` `server:read` · Self-hosted |
| Compatibility alias for `GET /api/system/networks/operations/:operationId/stream`. | HTTP only | `GET /api/system/clusters/network-operations/:operationId/stream` `server:read` · Self-hosted |
| Compatibility alias for `GET /api/system/networks/stream`. | HTTP only | `GET /api/system/clusters/stream` `server:read` · Self-hosted |
| Compatibility alias for `POST /api/system/networks/plans`. | HTTP only | `POST /api/system/clusters/network-plans` `server:admin` · Self-hosted |
| Compatibility alias for `GET /api/system/networks/operations/:operationId`. | HTTP only | `GET /api/system/clusters/network-operations/:operationId` `server:read` · Self-hosted |
| Compatibility alias for `POST /api/system/networks/operations/:operationId/apply`. | HTTP only | `POST /api/system/clusters/network-operations/:operationId/apply` `server:admin` · Self-hosted |
| Compatibility alias for `DELETE /api/system/networks/operations/:operationId`. | HTTP only | `DELETE /api/system/clusters/network-operations/:operationId` `server:admin` · Self-hosted |
| Compatibility alias for `PATCH /api/system/networks/preparations/:preparationId/connections`. | HTTP only | `PATCH /api/system/clusters/network-preparations/:preparationId/connections` `server:admin` · Self-hosted |
{/* api-operations:end */}
---
# App catalog
URL: https://openship.io/docs/api/apps.md
Browse templates, prepare installations, and configure apps.
import { TypeTable } from 'fumadocs-ui/components/type-table';
An **app** is a JSON definition that installs a set of containers as a project in one click — with
its images, wiring, generated secrets, curated settings form, and connection card already described.
This API covers browsing the catalog, installing, adding your organization's own custom apps, and
reading or updating an installed app afterwards.
In the dashboard this is the **Apps** tab. The definition format is documented in the
[App catalog JSON reference](/docs/reference/app-catalog), and authoring workflow in
[Add an app](/docs/guides/add-an-app).
These operations are available with supported self-hosted and Cloud providers. A fixed organization
scope requires a direct compatible Cloud connection; see [Cloud compatibility](/docs/api/sdk/compatibility#cloud).
## List the catalog
```
GET /api/apps/catalog
```
The runtime catalog is the copy **bundled** in your build, overlaid by a live fetch of the curated
catalog from the Openship repo (refreshed on a 10-minute TTL, stale-while-revalidate), plus your
organization's custom apps. A failed fetch or an offline instance simply keeps serving the last-good
copy, so the overlay can never break the catalog.
The overlay is fetched over HTTPS from Openship's own repository — repo-curated, with **no signing**
and no user uploads in that channel — and **every entry is shape-validated before it can drive an
install**, using the same strict validator as the bundled set. Your organization's custom apps are a
separate, always-unverified channel.
Because the overlay can be **ahead of your instance**, entries carry compatibility flags:
Each entry also carries `hosting` (`"experimental"` marks a stack that runs but is heavy or not
production-grade upstream) and, for the few apps that declare one, `minResources` — the host floor
you can check with [host-fit](#check-a-destination) before installing. Apps marked `unlisted` are
absent from this list by design: they stay installable by id, reached through another app's wizard.
## Get one app
```
GET /api/apps/catalog/:id
```
Returns the full definition — services, config fields, endpoints, settings, connection. Curated apps
win over custom ones: a custom app can never shadow a verified id (also enforced at upload).
This is **config metadata only, never secrets** — generated values are minted at install, so nothing
sensitive exists to return yet.
The response also carries a `draft` alongside `data`: this organization's **open, never-deployed**
draft of the same app, if one exists.
An install request for the same name **adopts that draft** rather than starting clean. So a client
must render the draft's stored configuration, not the app's defaults — otherwise Install silently
changes what the operator set up last time.
## Check a destination
```
GET /api/apps/catalog/:id/host-fit?deployTarget=server&serverId=
```
On self-hosted destinations, this compares the machine with the app's
[`minResources`](/docs/reference/app-catalog) recommendation. On Openship Cloud, it previews
the workspace allocation against the current plan. Pass `projectId` to include a draft's
saved resource settings; access to that project is required.
```json
{
"data": {
"minResources": { "memoryMb": 8192, "cpuCores": 4 },
"capacity": { "cpuCores": 2, "memoryMb": 2048, "source": "docker" },
"fit": {
"ok": false,
"memory": { "needed": 8192, "available": 2048 },
"cpu": { "needed": 4, "available": 2 }
}
}
}
```
A measured shortfall never blocks a self-hosted installation or redeployment. Cloud plan
allowances are checked again before deployment is queued, and the provider checks live
namespace capacity when allocating resources. See [Host requirements](/docs/reference/app-catalog).
A server ID must be accessible in the current organization. Cloud targets and machines that cannot be
probed can report `capacity.source: "unknown"` with `fit.ok: true`; that means no measured capacity
comparison was available, not that the host capacity was verified.
## Install an app
For a `template` app, installation creates or updates a project draft and returns `projectId`. Submit a
[deployment](/docs/api/deployments) for that project to run it. A `flow` app returns `flowHref` for its
setup wizard.
```ts
const result = await ship.apps.install({
templateId: "ghost",
name: "my-blog",
routes: [
{
service: "ghost",
port: 2368,
mode: "custom",
customDomain: "blog.acme.com",
},
],
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/apps" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H 'Content-Type: application/json' \
-d '{
"templateId": "ghost",
"name": "my-blog",
"routes": [
{ "service": "ghost", "port": 2368, "mode": "custom", "customDomain": "blog.acme.com" }
]
}'
```
', description: 'Values for the app configFields, keyed by env key. Generated secrets are filled server-side.' },
routes: { type: 'RouteChoice[]', description: 'One entry per endpoint you decided to expose. Max 40.' },
}}
/>
Each `routes` entry:
Public hostnames come **only** from `routes`. A service with no entry gets **no public route** — a
hostname is never invented on your behalf. Omit `routes` entirely and the app installs port-only,
which is a perfectly good outcome for a database or an internal tool.
## Custom apps
```
POST /api/apps/custom
GET /api/apps/custom
DELETE /api/apps/custom/:appId
```
`POST` accepts a full [app definition](/docs/reference/app-catalog) as the request body. The body is
gated here only as "must be a JSON object" — the authoritative validation runs in the service and is
the **same strict check** as the curated catalog, shape plus every referential rule.
Four constraints are enforced:
- **Always unverified.** `verified` and `available` are set by the server, so a file claiming
`"verified": true` is ignored.
- **`kind` must be `template`.** Flow apps are rejected.
- **The `id` cannot shadow a built-in app.**
- **Validation errors are returned with the offending detail**, including a distinct message when the
definition targets a newer catalog `schemaVersion` than the instance supports.
A custom app installs through the normal services pipeline with the same in-container boundary as any
project you deploy yourself — no new privilege.
## Curated settings
```
GET /api/projects/:id/app-settings
PATCH /api/projects/:id/app-settings
```
`GET` returns the app's settings schema together with current values, so a client can render the
form without knowing the app. `PATCH` applies a safe env merge — only the keys you send are touched:
Empty-string semantics differ by field kind, which matters when a form re-submits untouched inputs:
| Field | `value: ""` means |
|---|---|
| Non-secret | Clear the override, reverting to the app default |
| Secret | Leave the stored value **unchanged** |
Fields marked `requiresRedeploy` in the definition take effect only after a redeploy; the response
and the dashboard both surface that.
## Connection details
```
GET /api/projects/:id/app-connection
```
Resolves the app's connection outputs against the running services — public URLs, generated keys,
composed connection strings — and returns them ready to use, including any labeled
[variants](/docs/reference/app-catalog#connection) such as a public versus internal-network form.
It returns **fully decrypted** credentials — service-role JWTs, database passwords embedded in
`postgres://…` URLs — which bypass database row-level security. The env listing can mask secrets at
`project:read`; this surface cannot, so it sits above the read tier on purpose. A read-only grant or
a `project:read` MCP token must not be able to exfiltrate live credentials. Treat the response as
secret material.
## MCP exposure
Every route in this module is also exposed as an [MCP](/docs/api/mcp) tool, so an AI agent can browse
the catalog, install an app, and read its settings and connection details. Tool exposure is an
**opt-in allowlist** — a route becomes a tool only when its spec declares an `mcp` block — and the
module-level hard-deny list covers only `tokens`, `auth`, and `mcp`. `apps` is not on it.
Every MCP call **re-checks the caller's permissions**, so the tags in the
[operation table](#operations) apply unchanged. What that means in practice:
| Agent token | Can do |
|---|---|
| Read-only (`project:list` / `project:read`) | Browse the catalog, read an installed app's settings schema |
| `project:write` | Also **install apps** and **read decrypted connection credentials** |
Because `app-connection` is a tool and it returns live credentials, a `project:write` agent token can
read an installed app's database passwords and service-role keys. If you are handing a token to an
agent that only needs to inspect things, issue a read-only one.
## Errors
Install validates the app and your routing choices, and returns the reason as the message. Common
ones: the app is still marked coming soon (`available: false`); it needs a newer Openship
(`requiresUpdate`, reported as *Requires Openship ≥ X*); the app id is unknown; a `routes` entry
names a service the app does not declare, or a port that service does not serve; two `routes` entries
target the same service and port; or `mode: "custom"` was sent without a `customDomain`. A missing
`templateId` is rejected the same way.
The uploaded JSON failed the strict schema, and the message carries the offending detail — a bad
enum, a missing required field, or a dangling reference such as a `service` that no declared service
matches. Distinct messages cover the three non-shape rejections: a `flow` app, an `id` that shadows a
built-in, and a definition targeting a newer catalog `schemaVersion` than this instance supports.
From `PATCH /app-settings`: the project is not an app or declares no settings
(*This app has no configurable settings*), a change names a key the app does not define
(*Unknown setting: service.KEY*), a `required` field was cleared, a value failed its `pattern` or
numeric bounds, or the named service does not exist on the project.
A `routes` entry used `mode: "free"` (a managed `*.opsh.io` subdomain) on an instance that is not
connected to Openship Cloud. These carry a `CLOUD_REQUIRED_*` code so a client can turn them into a
connect prompt rather than a dead end. Use `mode: "custom"` with your own hostname, or `mode: "port"`
for no public route.
`GET /api/apps/catalog/:id` returns `{ "error": "Unknown app" }` when the id is neither a curated app
nor one of your organization's custom apps. List valid ids with `GET /api/apps/catalog`.
## Related guides
- [App catalog JSON](/docs/reference/app-catalog) — every field in an app definition
- [Add an app](/docs/guides/add-an-app) — submit a curated app, or upload a custom one
- [Services API](/docs/api/services) — the services an installed app is made of
- [Projects API](/docs/api/projects) — the project an app installs into
## Operations
{/* api-operations:start */}
### Connections, storage, and apps
| Operation | SDK | REST API |
| --- | --- | --- |
| Read curated settings for an installed catalog app. | `projects.getAppSettings(id)` | `GET /api/projects/:id/app-settings` `project:read` |
| Apply curated app setting changes. | `projects.updateAppSettings(id, input)` | `PATCH /api/projects/:id/app-settings` `project:write` |
| Read app connection details; these may include credentials and require write access. | `projects.getAppConnection(id)` | `GET /api/projects/:id/app-connection` `project:write` |
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| List available app templates. | `apps.listCatalog()` | `GET /api/apps/catalog` `project:list` |
| List the organization’s custom app definitions. | `apps.listCustom()` | `GET /api/apps/custom` `project:list` |
| Validate and save a custom app definition. | `apps.saveCustom(input)` | `POST /api/apps/custom` `project:write` |
| Create or update an installation draft and return its project. | `apps.install(input)` | `POST /api/apps` `project:write` |
| Read a template and its accessible installation draft. | `apps.getCatalogEntry(id)` | `GET /api/apps/catalog/:id` `project:list` |
| Preview host recommendations or Cloud plan fit, including an optional draft's saved resources. | `apps.hostFit(id, input?)` | `GET /api/apps/catalog/:id/host-fit` `project:list` |
| Remove a custom catalog definition. | `apps.removeCustom(id)` | `DELETE /api/apps/custom/:appId` `project:write` |
{/* api-operations:end */}
---
# Deployments
URL: https://openship.io/docs/api/deployments.md
Submit builds, follow progress, and manage releases.
import { TypeTable } from 'fumadocs-ui/components/type-table';
A deployment builds and releases a project's configured source. Use this page to submit builds, inspect
progress, handle decisions, and redeploy or roll back. For generated files and folder uploads, start with
[Source files](/docs/api/sources).
The operations apply to self-hosted and Cloud deployments when the selected provider supports them.
[Cloud scope requirements](/docs/api/sdk/compatibility#cloud) still apply.
## Deploy a Git project
Redeploys an already-linked project from its git source. To deploy a **local folder** instead, use the
upload flow that ends at [`/build/access`](#deploy-wizard-buildaccess).
```ts
const result = await ship.deployments.create({
projectId: "proj_123",
branch: "main",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/deployments" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"projectId":"proj_123","branch":"main"}'
```
## Detect build configuration
Side-effect-free: point it at a git repo or a local path and it returns the detected framework, package
manager, and build/start commands so the wizard can pre-fill. Creates nothing.
```
POST /api/deployments/prepare
```
`source: "local"` is rejected with **403** in cloud mode — cloud has no host filesystem to read.
Preparation masks environment values by default. Import editors can request them in the same response with
`includeEnv: true`; see
[Reveal environment values](/docs/api/services#reveal-environment-values).
## Submit an uploaded build [#deploy-wizard-buildaccess]
Create a deployment and start its build. For a folder-upload
deploy, pass `projectId` (from `projects/ensure`) and `uploadSessionId` (from `projects/folder/session`);
for a git project, pass `projectId` and optionally `branch`. Returns `{ success, deployment_id, project_id }`.
```ts
const result = await ship.deployments.buildAccess({
projectId: "proj_123",
branch: "main",
buildStrategy: "server",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/deployments/build/access" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"projectId":"proj_123","branch":"main","buildStrategy":"server"}'
```
', description: 'Runtime env vars { KEY: value }.' },
publicEndpoints: { type: 'PublicEndpoint[]', description: 'Domains/routes; omit to auto-derive a free subdomain from the project slug.' },
buildStrategy: { type: '"server" | "local"', description: 'Where the build runs.' },
deployTarget: { type: '"local" | "server" | "cloud"', description: 'Usually omit for folder uploads — the upload session mode decides.' },
serverId: { type: 'string', description: "Target server id when deployTarget = 'server'." },
runtimeMode: { type: '"bare" | "docker"', description: 'How the app runs on the target.' },
serviceDeploymentMode: { type: '"services" | "single"', description: 'Multi-service (compose/monorepo) or single app.' },
services: { type: 'BuildService[]', description: 'Compose / multi-service definitions (services mode). Omit on a folder upload and the services the scan parsed for that upload session are used.' },
cloudResourceTier: { type: '"unlimited" | "micro" | "low" | "medium" | "high" | "xlarge" | "custom"', description: 'Optional container limits. The default uses the selected server’s available capacity.' },
cloudResourceCustom: { type: '{ cpuCores; memoryMb; diskMb }', description: "CPU/RAM/disk when cloudResourceTier = 'custom'." },
cloneStrategy: { type: '"api-host" | "server"', description: 'Where the repo clone happens.' },
}}
/>
Each `publicEndpoints` entry is `{ port?, targetPath?, domain?, customDomain?, domainType? }` where
`domainType` is `"free"` or `"custom"`. A `services` entry mirrors a compose/monorepo service
(`name`, `image?`, `build?`, `dockerfile?`, `ports`, `dependsOn`, `environment`, `volumes`, and the
optional per-app build fields).
Setting `deployTarget: "cloud"` on a self-hosted instance triggers a promote-to-cloud flow. For a normal
folder upload, leave `deployTarget` unset and let the upload session's mode decide.
## Wait, decisions, and cancellation
A deployment submission returns IDs before the workload is ready. Read persisted build status to decide
whether it succeeded. The SDK's `deployment(id)` handle adds polling and a normalized outcome.
```ts
const outcome = await ship.deployment("dep_123").wait({ timeoutMs: 120_000 });
if (!outcome.success) throw new Error(outcome.message ?? outcome.status);
```
```bash
curl "$OPENSHIP_URL/api/deployments/dep_123/build" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The REST request returns one status snapshot; poll it while the deployment runs. The SDK waits until a
terminal state or a decision is required. `ready` and `no_changes` are successful. Handle failures,
cancellation, partial failure, and rejection explicitly.
`wait()` returns `status`, `success`, `decisionPending`, and `cancellationPending`, with an optional
`prompt`, `message`, or `warning`. Without an `onPrompt` callback it returns `action_required` when a
decision is pending. To connect your own decision UI:
```ts
import type { PromptPayload } from "openship";
export async function waitWithDecisions(
deploymentId: string,
chooseAction: (prompt: PromptPayload) => Promise,
) {
return ship.deployment(deploymentId).wait({
timeoutMs: 120_000,
onPrompt: chooseAction,
});
}
```
Return an action ID offered by the prompt. REST callers submit the same selected action as
`{ "action": "" }` to `POST /api/deployments/:id/build/respond`.
Aborting or timing out a wait stops observation. To cancel execution, call `deployments.cancel(id)` and
inspect the subsequent state. Cancellation can remain pending while work settles; it does not roll back
an already created release.
## Read progress events
```ts
for await (const event of ship.deployments.events("dep_123", {
signal: AbortSignal.timeout(30_000),
})) {
console.log(event);
}
```
```bash
curl -N "$OPENSHIP_URL/api/deployments/dep_123/stream" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
REST returns Server-Sent Events. SDK events contain an event name and serialized data;
[`consumeDeploymentEvents()`](/docs/api/sdk/utilities#deployment-helpers) decodes log chunks.
Use `since` to resume from a known event cursor while it is available. Durable replay across worker
restarts is not implemented. A stream ending does not establish deployment success; read status.
## Redeploy
```ts
const submitted = await ship.deployments.redeploy("dep_123", { useExistingCommit: true });
console.log(submitted.deployment_id);
```
```bash
curl -X POST "$OPENSHIP_URL/api/deployments/dep_123/redeploy" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"useExistingCommit":true}'
```
Re-runs the build. By default it resolves the latest commit on the branch (the auto-redeploy semantic);
send `{ "useExistingCommit": true }` to rebuild against the exact commit the original deployment used.
## Rollback and pin
Rollback restores a previous deployment's artifact/commit as the active release. Pinning marks a
deployment as protected so it isn't reclaimed by the rollback-window cleanup — `POST /:id/pin` defaults to
`{ "pinned": true }`; send `{ "pinned": false }` to unpin.
```
POST /api/deployments/:id/rollback
POST /api/deployments/:id/pin
```
## Cancel a running deploy
```ts
const cancellation = await ship.deployments.cancel("dep_123");
console.log(cancellation);
```
```bash
curl -X POST "$OPENSHIP_URL/api/deployments/dep_123/cancel" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Partial-failure compose deploys: keep or reject
When a multi-service (compose) deploy has some services succeed and others fail, it is held in
`partial_failure` with `decision: pending` ("Action Required"). Resolve it explicitly:
- **Keep** accepts the services that succeeded and leaves the rest on their prior version.
- **Reject** rolls back the changed services to their previous state.
```
POST /api/deployments/:id/keep
POST /api/deployments/:id/reject
```
## SSL status and renew
Both take the domain in the JSON body. `/ssl/status` is a side-effect-free probe (`POST` only so the
hostname travels in the body); `/ssl/renew` re-issues the certificate.
```
POST /api/deployments/ssl/status
POST /api/deployments/ssl/renew
```
```ts
const result = await ship.deployments.sslStatus({
domain: "app.example.com",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/deployments/ssl/status" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"domain":"app.example.com"}'
```
## Errors
Missing a required field (`domain is required`, `source must be 'github' or 'local'`) or the operation
couldn't run (e.g. cancelling a deployment that already finished, or keep/reject on a deployment that
isn't awaiting a decision). The response body carries `{ success: false, error }`.
`prepare` with `source: "local"` (or a folder deploy) isn't available on Openship Cloud — there's no host
filesystem. Use a git source instead.
The `:id` doesn't belong to your organization (or was deleted). List with `GET /api/deployments` to get
valid IDs.
## Operations
{/* api-operations:start */}
### Submit
| Operation | SDK | REST API |
| --- | --- | --- |
| Submit a deployment for a configured project. | `deployments.create(input)` | `POST /api/deployments` `deployment:write` |
| Submit a new deployment based on an existing release. | `deployments.redeploy(id, input?)` | `POST /api/deployments/:id/redeploy` `deployment:write` |
| Detect and prepare source configuration before submission. | `deployments.prepare(input)` | `POST /api/deployments/prepare` `deployment:write` |
| Submit a prepared upload/build workflow. | `deployments.buildAccess(input)` | `POST /api/deployments/build/access` `deployment:write` |
| Start an already prepared deployment. | `deployments.start(id)` | `POST /api/deployments/:id/build` `deployment:write` |
### Observe
| Operation | SDK | REST API |
| --- | --- | --- |
| Read the persisted deployment record. | `deployments.get(id)` | `GET /api/deployments/:id` `deployment:read` |
| Read a page of deployments using project and environment filters. | `deployments.list(input?)` | `GET /api/deployments` `deployment:list` |
| Read captured deployment logs. | `deployments.logs(id, input?)` | `GET /api/deployments/:id/logs` `deployment:read` |
| Read persisted status, pending prompts, and cancellation state. | `deployments.buildStatus(id)` | `GET /api/deployments/:id/build` `deployment:read` |
| Inspect whether rollback needs retained artifacts or a rebuild. | `deployments.restorePlan(id)` | `GET /api/deployments/:id/restore-plan` `deployment:read` |
| Stream deployment progress events. | `deployments.events(id, options?)` | `GET /api/deployments/:id/stream` `deployment:read` |
| Read runtime/container information. | `deployments.containerInfo(id)` | `GET /api/deployments/:id/info` `deployment:read` |
| Read current CPU, memory, disk, and network usage. | `deployments.containerUsage(id)` | `GET /api/deployments/:id/usage` `deployment:read` |
| Read unresolved actions for the deployment. | `deployments.pendingActions(id)` | `GET /api/deployments/:id/pending` `deployment:read` |
### Control
| Operation | SDK | REST API |
| --- | --- | --- |
| Request cancellation and return whether settlement is pending. | `deployments.cancel(id)` | `POST /api/deployments/:id/cancel` `deployment:write` |
| Answer a pending deployment prompt with an offered action ID. | `deployments.respond(id, input)` | `POST /api/deployments/:id/build/respond` `deployment:write` |
| Restore the selected deployment through the rollback workflow. | `deployments.rollback(id)` | `POST /api/deployments/:id/rollback` `deployment:write` |
| Pin or unpin retained rollback artifacts. | `deployments.pin(id, input?)` | `POST /api/deployments/:id/pin` `deployment:write` |
| Accept a release waiting for a keep/reject decision. | `deployments.keep(id)` | `POST /api/deployments/:id/keep` `deployment:write` |
| Reject a held release and restore the prior deployment when possible. | `deployments.reject(id)` | `POST /api/deployments/:id/reject` `deployment:write` |
| Remove an eligible deployment and its retained resources. | `deployments.remove(id)` | `DELETE /api/deployments/:id` `deployment:admin` |
| Restart the deployment’s runtime. | `deployments.restart(id)` | `POST /api/deployments/:id/restart` `deployment:write` |
| Skip the specified advisory port check. | `deployments.skipPortCheck(id, input)` | `POST /api/deployments/:id/skip-port-check` `deployment:write` |
### Certificates
| Operation | SDK | REST API |
| --- | --- | --- |
| Read certificate status for a domain. | `deployments.sslStatus(input)` | `POST /api/deployments/ssl/status` `deployment:read` |
| Request certificate renewal for a domain. | `deployments.renewSsl(input)` | `POST /api/deployments/ssl/renew` `deployment:write` |
{/* api-operations:end */}
---
# Server terminal
URL: https://openship.io/docs/api/terminal.md
Issue access tickets and open a terminal on connected or managed Cloud servers.
import { TypeTable } from 'fumadocs-ui/components/type-table';
The Terminal API opens a live shell (a PTY) on a connected server or a managed Cloud server and streams it to the browser
over a WebSocket — the dashboard's server **Terminal** tab, backed by `xterm.js`. Because a browser can't set
an `Authorization` header on a `WebSocket()`, auth is split into two steps: a normal HTTP call mints a
short-lived, single-use **ticket**, and the WebSocket upgrade presents that ticket inside its
`Sec-WebSocket-Protocol` header.
Use the server's `capabilities.terminal` and `terminalSessionLimit` fields to determine availability and
the concurrent shell limit. Managed Cloud servers support one live host shell at a time through
the provider, covering both Docker and bare projects. SSH servers use the configured per-user limit
(3 by default). Service shells use `/api/services/terminal`.
## Mint a ticket
Opening a PTY is administrative, so the caller must hold `server:admin` on the target server. The endpoint
also confirms the server exists in your organization (returning the same 404 the WebSocket would) before
issuing the token.
```
POST /api/terminal/ticket
```
```bash
curl -X POST "$OPENSHIP_URL/api/terminal/ticket" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"serverId":"srv_123"}'
```
The response carries the one-shot token and its lifetime:
```json
{ "success": true, "token": "", "expiresIn": 30 }
```
The token is consumed the first time it's presented on an upgrade — it cannot be replayed. Mint a fresh
ticket per connection attempt.
`openship server ssh ` is stubbed as "coming soon" — the CLI doesn't bundle a WebSocket client, so
there's no terminal command today. Use the dashboard, or drive the WebSocket directly as shown below.
## Open the WebSocket
```
GET /api/terminal/ws/:serverId
```
Connect to the `wss://` form of this path and pass the ticket as a WebSocket subprotocol. Browsers send
subprotocols in the `Sec-WebSocket-Protocol` header; the value must be the prefix `openship.terminal.v1+`
followed by the token from `/ticket`:
```js
const { token } = await fetch("/api/terminal/ticket", {
method: "POST",
headers: { "Content-Type": "application/json" },
body: JSON.stringify({ serverId }),
}).then((r) => r.json());
const ws = new WebSocket(`wss://your-host/api/terminal/ws/${serverId}`, [
`openship.terminal.v1+${token}`,
]);
```
The upgrade enforces, in order: the request `Origin` must be a trusted origin; a presented ticket must be valid
(same-origin session cookies are accepted only when no ticket is presented); the ticket's `serverId` must match the path; the caller must hold
`server:admin`; the server must exist in the org; and the per-user concurrent-session cap must not be
exceeded. Any failure opens the socket only to send an `error` control frame and close with a `4xxx` code.
### Resuming a parked session
When the socket drops without an explicit close, the shell is **parked** (kept alive) so the client can
reattach. To resume, present a second subprotocol alongside the ticket: `openship.terminal.resume+`,
where `resumeToken` came from the previous `ready` frame. A resume reuses the existing PTY and audit row and
does not count against the session cap.
### Wire protocol
Once open, framing is:
- **Binary frames, both directions** — raw PTY bytes. Client → server bytes are written to the shell's stdin;
server → client bytes are shell stdout/stderr.
- **Text frames** — JSON control messages.
Client → server control messages:
Server → client control messages:
## Errors
`error` frames carry a machine-readable `code`: `ssh_auth`, `ssh_connect`, `server_not_found`, `max_sessions`,
`idle_timeout`, `session_cap`, `resume_failed`, or `server_error`. The accompanying close code is in the
application `4xxx` range.
No valid ticket and no usable session cookie, no resolvable active organization, or the ticket's `serverId`
didn't match the path. Mint a fresh ticket (they're single-use and short-lived) and reconnect.
The upgrade's `Origin` header isn't in the trusted-origins allowlist. WebSocket terminals are expected to be
opened from the dashboard origin.
The `:serverId` doesn't exist in your organization, or the caller lacks `server:admin` on it. The two are
reported identically so server existence can't be probed across tenants.
You've hit the per-user concurrent-terminal cap. Close an existing session (or let a parked one time out)
before opening another. Resumes don't count against the cap.
## SDK and CLI
The remote SDK opens the existing ticket and WebSocket workflow:
```ts
import { OpenshipClient } from "openship";
const client = new OpenshipClient({
baseUrl: "https://ship.example.com",
token: process.env.OPENSHIP_TOKEN,
});
const session = await client.terminal.openServer("srv_123", {
origin: "https://ship.example.com", // Trusted dashboard origin for Node callers.
onData: bytes => process.stdout.write(bytes),
});
session.resize(120, 40);
session.write("pwd\nexit\n");
// session.close() explicitly ends the remote shell.
const exit = await session.closed;
```
The API token is sent only to the HTTP ticket endpoint. The WebSocket uses a one-use ticket in its
subprotocol; credentials are never added to its URL. An explicit resume does not open a replacement
shell if resumption fails. Browser callers use their browser's own Origin header.
Use `openship server ssh ` or `openship server terminal ` interactively. The CLI uses the saved
dashboard origin; override it with `--origin` when necessary. Use `server exec` for noninteractive scripts.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| Mint a one-shot ticket for a WebSocket handshake against a server. | `terminal.openServer(id, options)` Remote client | `POST /api/terminal/ticket` `terminal:write` |
| WebSocket upgrade that opens the remote PTY. | `terminal.openServer(id, options)` | `GET /api/terminal/ws/:serverId` `Handler authentication` |
{/* api-operations:end */}
---
# DNS providers
URL: https://openship.io/docs/api/dns.md
Connect DNS providers and check zones.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Adding a custom domain normally ends with Openship telling you which records to create and waiting for you
to create them. Connect a DNS provider and Openship can preview and apply those records for you without
leaving the page. Applying DNS is always an explicit action: creating a project domain or saving a service
route never changes the provider's zone silently. In the dashboard, credentials live under
**Settings → DNS** and each pending domain's records panel contains the apply action.
Cloudflare is the only provider today. The provider list is served by the API rather than hard-coded in the
dashboard, so `GET /api/dns/providers` is the authoritative answer to "what can I connect?".
## Connect a provider
```ts
const result = await ship.dns.addCredential({
provider: "cloudflare",
name: "Cloudflare production",
apiToken: "cf-...",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/dns/credentials" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"provider":"cloudflare","name":"Cloudflare production","apiToken":"cf-..."}'
```
For Cloudflare, create a token at
[dash.cloudflare.com/profile/api-tokens](https://dash.cloudflare.com/profile/api-tokens) scoped to
**Zone:Zone:Read** and **Zone:DNS:Edit**, limited to the zones you want Openship to manage.
It is encrypted at rest (AES-256-GCM, key derived from `BETTER_AUTH_SECRET`) and no endpoint returns it —
not in full and not as a prefix. `tokenMasked` is a fixed `••••••••`. There is no "reveal"; to change a
token, disconnect the credential and connect a new one.
Rotating `BETTER_AUTH_SECRET` makes stored tokens undecryptable. The credential then reports
`status: "invalid"` the next time Openship tries to use it, and you re-connect it.
## Check a zone
```ts
const result = await ship.dns.verifyZone({
hostname: "app.example.com",
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/dns/verify-zone" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"hostname":"app.example.com"}'
```
The response separates four outcomes, because they call for different actions:
| `status` | `matched` | Meaning |
|---|---|---|
| `matched` | `true` | A connected provider hosts this zone; the domain's records can be previewed and applied from Openship. |
| `none` | `false` | We asked, and no connected provider hosts it. You add the records yourself. |
| `unauthorized` | `false` | A stored token was rejected. Re-connect it — `credentialId` says which. |
| `unavailable` | `false` | The provider could not be reached (rate limit, outage). Unknown, **not** a sign of misconfiguration. |
## Add, preview, and apply a domain
`POST /api/domains` persists a pending domain and returns the records it needs. It does not call the DNS
provider. Service-level custom routes follow the same contract: saving the route creates its pending domain
row, and that row supplies the `:id` used by the shared plan and apply endpoints.
Preview the exact provider changes before writing anything:
```ts
const result = await ship.domains.dnsPlan("dom_123");
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/domains/dom_123/dns/plan" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
```json
{
"data": {
"status": "matched",
"provider": "cloudflare",
"zoneName": "example.com",
"records": [
{ "name": "app.example.com", "type": "A", "action": "create", "desired": "203.0.113.10" }
]
}
}
```
The plan classifies every record as `create`, `update`, `adopt`, `in-sync`, or `conflict`. A conflict is
reported rather than overwritten. `status: "none"` means no connected credential manages the zone, so use
the records returned by `POST /api/domains` (or `GET /api/domains/:id/records`) and add them manually.
Apply the previewed records explicitly:
```ts
const result = await ship.domains.dnsApply("dom_123");
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/domains/dom_123/dns/apply" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
The response reports `applied`, `skipped`, or `failed` for every record. `provisioned` is `true` only when
the matching provider has every actionable record in place; a partial write returns `provisioned: false`
with a reason and the per-record failures.
No verification is triggered by apply. The records are seconds old, a resolver may still be holding a
negative answer for the name, and a failed check burns one of Let's Encrypt's per-hostname validation
failures. The domain stays pending and the `domains:verify-pending` sweep picks it up after its
ten-minute grace window.
## Removing records
Disconnecting a credential does not touch DNS. Removing a *domain* does — but only records Openship created,
identified by the `Managed by Openship` comment it writes on every record.
For an apex domain the record name *is* the zone apex, where your `MX`, SPF `TXT` and `CAA` records also
live. Deleting "every record at this name" would take your mail with it, so Openship deletes only what it
can prove it wrote.
Connecting a domain does repoint an existing record at that name — that is what connecting it means — but
repointing is not adoption: Openship leaves such a record's comment untouched, so it never carries the
`Managed by Openship` marker and removing the domain later will not delete it.
## Errors
| Code | Status | Meaning |
|---|---|---|
| `DNS_UNKNOWN_PROVIDER` | 400 | `provider` is not a name from `GET /api/dns/providers`. |
| `DNS_PROVIDER_NOT_READY` | 400 | The provider rejected the token during the pre-store check. |
| `DNS_RECORD_CONFLICT` | 409 | Several records already answer for that name and type and none are Openship's — a round-robin or multi-host set it will not rewrite. |
| `DNS_API_ERROR` | 502 | The provider's API failed. The upstream status is in the message. |
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| List supported DNS providers and their credential fields. | `dns.listProviders()` | `GET /api/dns/providers` `settings:read` |
| List the organization’s DNS credentials. | `dns.listCredentials()` | `GET /api/dns/credentials` `settings:read` |
| Read a DNS credential with secrets masked. | `dns.getCredential(input)` | `GET /api/dns/credentials/:id` `settings:read` |
| Store a DNS provider credential. | `dns.addCredential(input)` | `POST /api/dns/credentials` `settings:admin` |
| Remove a DNS credential. | `dns.removeCredential(input)` | `DELETE /api/dns/credentials/:id` `settings:admin` |
| Check access to the requested DNS zone. | `dns.verifyZone(input)` | `POST /api/dns/verify-zone` `settings:read` |
### Cloudflare Tunnel ingress
| Operation | SDK | REST API |
| --- | --- | --- |
| Read persisted tunnel connections, optionally filtered by deployment server. | `dns.listIngressConnections(input)` | `GET /api/dns/ingress` `settings:read` |
| Discover accounts, named tunnels and optional reusable Access policies using a saved Cloudflare credential. Requires an organization administrator. | `dns.discoverIngress(input)` | `POST /api/dns/ingress/discover` `settings:admin` |
| Connect or create a named Cloudflare Tunnel on a self-hosted deployment server. Setup continues asynchronously. | `dns.connectIngress(input)` | `POST /api/dns/ingress` `settings:admin` |
| Set automatic enrollment and Access policy defaults for future custom domains. Existing hostnames keep their settings. | `dns.updateIngress(input)` | `PUT /api/dns/ingress/:id` `settings:admin` |
| Retry persisted tunnel setup or cleanup without creating another connection. | `dns.retryIngress(input)` | `POST /api/dns/ingress/:id/retry` `settings:admin` |
| Disconnect a server tunnel and queue ownership-checked cleanup. Existing tunnels and reusable policies are retained. | `dns.removeIngress(input)` | `DELETE /api/dns/ingress/:id` `settings:admin` |
| Read persisted tunnel, DNS and Access status for a project domain. | `dns.getDomainIngress(input)` | `GET /api/dns/ingress/domains/:id` `settings:read` |
| Connect a custom domain to its deployment server tunnel, change its Access policy or request disconnection. | `dns.setDomainIngress(input)` | `PUT /api/dns/ingress/domains/:id` `settings:admin` |
{/* api-operations:end */}
---
# Installation settings
URL: https://openship.io/docs/api/system.md
Read and change self-hosted installation settings and setup.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Installation settings control a self-hosted Openship instance. Resource operations below use the shared
SDK/HTTP interface where available; onboarding, recovery, and remaining setup endpoints are HTTP-only.
See [Servers](/docs/api/servers) for hosts and component installation, [Edge administration](/docs/api/edge)
for existing sites, and [Data transfer](/docs/api/data-transfer) for imports, exports, and team-mode migration.
## Onboarding & setup
`GET /api/system/onboarding` returns `{ configured: boolean }` — `true` once at least one server exists. The
`POST` variant runs the same logic as the internal `/setup` push but only while the instance is unconfigured
(it returns **403 "Instance already configured"** afterward), so first-run flows don't need a token.
```
POST /api/system/onboarding
```
The `POST /api/system/setup` route accepts the same body but is reserved for the desktop app and requires the
`internalAuth` shared token rather than a user session; it can also target an existing server by passing
`serverId`.
## Instance settings
`GET /api/system/settings` returns the instance config (auth mode, tunnel provider, default build mode and
rollback window, invitation mail source, team mode, migration target). `PATCH` updates only the fields you
send. `DELETE` wipes instance settings **and** every server row.
```ts
const result = await ship.system.updateSettings({
defaultBuildMode: "docker",
});
console.log(result);
```
```bash
curl -X PATCH "$OPENSHIP_URL/api/system/settings" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"defaultBuildMode":"docker"}'
```
Setting `authMode: "none"` on anything other than a desktop deployment means anyone who can reach the API acts
as admin. The operator must **both** start the process with `OPENSHIP_ALLOW_ZERO_AUTH=true` (else **403**) and
send `confirm: "I-understand-no-auth"` in the body (else **400**).
## Promote zero-auth to a real login
`POST /api/system/upgrade-to-auth` turns the synthetic zero-auth user into an email/password account and flips
`authMode` from `none` to `local`, keeping the same user id so existing projects, deployments, and audit rows
still resolve. It is only callable while `authMode === "none"` (otherwise **400**).
```
POST /api/system/upgrade-to-auth
```
## Browse the host filesystem
`GET /api/system/browse?path=` lists child directories of a path (defaults to the host's home
directory), flagging which look like deployable projects. Used by the "deploy a local folder" picker.
Returns `{ path, directories: [{ name, path, isProject }] }` — projects first, then alphabetical. Non-directory
paths return **400**, missing paths **404**.
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Browse an authorized host filesystem location. | `system.browse(input?)` | `GET /api/system/browse` `settings:read` · Self-hosted |
| Read database and installation health. | `system.health()` | `GET /api/system/diagnostics` `settings:read` · Self-hosted |
| Read instance settings. | `system.getSettings()` | `GET /api/system/settings` `settings:read` · Self-hosted |
| Change instance settings. | `system.updateSettings(input)` | `PATCH /api/system/settings` `settings:write` · Self-hosted |
| Read SMTP settings with secrets masked. | `system.getEmailSettings()` | `GET /api/system/settings/email` `settings:read` · Self-hosted |
| Configure SMTP delivery for the installation. | `system.updateEmailSettings(input)` | `PUT /api/system/settings/email` `settings:write` · Self-hosted |
| Send a test message using the configured SMTP settings. | `system.sendTestEmail(input)` | `POST /api/system/settings/email/test` `settings:write` · Self-hosted |
| Reset supported instance settings. | `system.resetSettings()` | `DELETE /api/system/settings` `settings:admin` · Self-hosted |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| First-run check — is any server configured yet? | `instance.onboardingStatus()` Remote client | `GET /api/system/onboarding` `Handler authentication` · Self-hosted |
| First-run setup; persists settings and creates the first server. Returns 403 once configured. | `instance.configureOnboarding(input)` Remote client | `POST /api/system/onboarding` `Handler authentication` · Self-hosted |
| Promote a zero-auth instance to email/password login. | `instance.upgradeToAuth(input)` Remote client | `POST /api/system/upgrade-to-auth` `Handler authentication` · Self-hosted |
| Create the initial administrator during authorized bootstrap. | HTTP only | `POST /api/system/bootstrap-admin` `Internal operator` · Self-hosted |
| Exchange the private installation credential for a temporary local CLI admin session; requires X-Internal-Token and refuses Cloud/browser callers. | HTTP only | `POST /api/system/cli-session` `Internal operator` · Self-hosted |
| Begin the installation's Cloud account connection. | HTTP only | `POST /api/system/cloud-connect` `Internal operator` · Self-hosted |
| Read the installation's Cloud connection status. | HTTP only | `GET /api/system/cloud-status` `Internal operator` · Self-hosted |
| Read installation health. | HTTP only | `GET /api/system/health` `Internal operator` · Self-hosted |
| Create an account from an eligible self-hosted invitation. | HTTP only | `POST /api/system/invite-signup` `Handler authentication` · Self-hosted |
| Test a connection during initial onboarding. | HTTP only | `POST /api/system/onboarding/test-connection` `Handler authentication` · Self-hosted |
| Reset the administrator password through the local recovery boundary. | HTTP only | `POST /api/system/reset-admin-password` `Internal operator` · Self-hosted |
| Register the Openship installation as a managed application. | HTTP only | `POST /api/system/self-register` `Internal operator` · Self-hosted |
| Stream installation registration progress. | HTTP only | `GET /api/system/self-register/stream` `Internal operator` · Self-hosted |
| Read instance config for the desktop app. | HTTP only | `GET /api/system/setup` `Internal operator` · Self-hosted |
| Push instance config from the desktop app. | HTTP only | `POST /api/system/setup` `Internal operator` · Self-hosted |
{/* api-operations:end */}
---
# Cloud support
URL: https://openship.io/docs/api/support.md
Submit Cloud support requests, follow private account tickets, and manage the operator queue.
`https://openship.io/support` and `/contact` use the same ticket intake. The
website forwards to `POST /api/cloud/support` on the Cloud API; its default is
`https://api.openship.io`. A development website can select a different Cloud API
with `OPENSHIP_CLOUD_API_URL`. The website needs no SMTP credentials or operator
token, and never forwards browser cookies or claimed client IPs.
The Cloud API stores support tickets and starts the delivery worker only when
`CLOUD_MODE=true`. Local installations expose a customer-only relay through the
existing Cloud connection. Authenticated tickets are private to their creator and Cloud
operators. Anonymous requests remain operator-only. All support records are
excluded from customer, project, and self-hosted instance exports.
## Signed-in ticket center
`https://app.openship.io/support` lists the signed-in customer's tickets, with
topic, Open/Resolved status, subject/reference search, pagination and conversation
history. Support is the final sidebar entry on Cloud and Cloud-connected self-hosted
or desktop installations. It also remains visible for existing Cloud projects when
the connection needs attention. Checkout availability requests
created in the Cloud dashboard appear in the same history.
Browser requests require a session cookie and the usual trusted-origin checks for
writes. The server-side Cloud connection uses its verified user session as a Bearer;
this is a session credential, not an API token. Identity and contact information come from that session.
API tokens, organization ownership and matching an email address do not grant
access. Changing the selected team does not change ticket ownership. Existing
anonymous website submissions are never automatically assigned to an account.
| Method | Path under `/api/cloud/support` | Result |
| --- | --- | --- |
| GET | `/session` | The current support account, or `account: null` on local installations without a personal Cloud link |
| GET | `/mine?status=open&search=build&limit=25` | Own tickets and `nextCursor`; pass it as `before` to load more |
| POST | `/mine` | Save a ticket with `requestId` (UUID), `category`, `subject` and `message`; return a receipt |
| GET | `/mine/` | Own report and customer/support replies |
| POST | `/mine//replies` | Save a reply with `requestId` and `message`; return the conversation |
| PATCH | `/mine/` | Set `status` to `open` or `resolved`; return the conversation |
Categories are `deployment`, `billing`, `account` and `general`. Subjects allow
200 characters and messages 12,000. New tickets are limited to five per account
per 15 minutes; new replies to 30. Retry the same UUID and content after an
uncertain response. Confirmed retries do not create another message or consume
another quota slot. A new customer reply reopens a resolved ticket; retrying an
older reply does not undo a later resolution.
Replies use the existing durable mail outbox: customer replies notify the support
mailbox, while operator replies appear in the conversation and are emailed to the
customer. The dashboard does not expose SMTP attempts, errors, receipts or internal
addresses. Inbound email replies still require the operator's mailbox workflow;
they are not automatically imported into the ticket conversation.
### Connected self-hosted and desktop installations
The local inbox uses the signed-in person's own verified Cloud link. Tickets stay
in Cloud, with the same history and email delivery as `app.openship.io/support`.
The shared organization connection does not give teammates access to its owner's
private tickets. A teammate without a personal link can open Support in Cloud and
sign in there. Disconnected installations offer Settings and Cloud Support links.
The local client reads `/session` first, then sends the returned `account.key` in
`X-Openship-Support-Account` on every ticket request. This value identifies the
connection and is not a credential. The relay rejects old or missing bindings with
`409 SUPPORT_ACCOUNT_CHANGED` and discards responses from a replaced connection.
The UI clears private state when the account changes and keeps drafts after transient
failures. Cloud session credentials stay on the server; only safe customer responses
and rate-limit retry guidance reach the browser.
The local relay validates input and exposes only the six customer endpoints above.
Public intake and operator endpoints remain Cloud-only. Support failures do not
clear the Cloud connection used by deployments. Install the updated Cloud API before
updating connected installations so the session and customer endpoints are available.
## Delivery and mailbox configuration
Provision `support@openship.io` to receive mail. Configure the Cloud API's existing
`SMTP_HOST`, `SMTP_PORT`, `SMTP_USER`, `SMTP_PASS`, and `SMTP_FROM` with a working
sender. For example, after that mailbox is provisioned:
```dotenv
SMTP_HOST=mail.oblien.com
SMTP_PORT=587
SMTP_USER=support@openship.io
SMTP_PASS=
SMTP_FROM=Openship Support
```
Use credentials appropriate to the actual mail server; keep them in deployment
secrets. This is an operator configuration example, not a credential requirement
for the website. Creating a ticket does not depend on SMTP being available.
Each submission atomically saves a `cloud_support_ticket` and two
`cloud_support_message` deliveries: a receipt for the customer, and a notification
to `support@openship.io`. The customer receipt contains a stable reference, no
reflected message text, and `Reply-To: support@openship.io`. The team notification
includes the report and sets Reply-To to the requester. Ordinary inbound email
and email replies arrive in the support mailbox; this API does not ingest IMAP.
The client reuses its request UUID if the response is lost. Identical retries
return the original receipt; different content under the same key returns 409.
Intake validates bounded input and rate-limits new submissions by hashed contact
address across Cloud replicas, in addition to the public per-IP ceiling.
Delivery begins after the database commit. The existing system scheduler runs
`cloud-support:deliver` every minute and resumes pending deliveries after restart.
SQL leases prevent concurrent workers from sending the same claimed message.
Failures back off from one minute to one hour and stop after ten attempts. The
ticket and error state remain available, and an operator can retry delivery.
Accepted mail is not resent during ordinary retries. Like other SMTP outboxes,
delivery is at least once across a crash after SMTP acceptance but before the DB
acknowledgement; a stable Message-ID is reused in that case.
## Operator API
All routes below require `X-Internal-Token` matching the Cloud API's `INTERNAL_TOKEN`.
An organization owner, customer cookie, PAT, or arbitrary ticket reference is
insufficient. Responses are not cached. Do not put this token in client code.
| Method | Path under `/api/cloud/support` | Result |
| ------ | ------------------------------- | ------------------------------------------------------------------------------- |
| GET | `/tickets?status=open&limit=25` | Queue, with `nextCursor`; use `before=` for the next page |
| GET | `/tickets/` | Report, replies, delivery attempts, errors and next attempt times |
| POST | `/tickets//replies` | Save and queue a reply; optionally resolve the ticket atomically |
| PATCH | `/tickets/` | Set `status` to `open` or `resolved` |
| POST | `/tickets//retry` | Retry undelivered mail without stealing active sends or resending accepted mail |
Example listing:
```sh
curl --fail-with-body 'https://api.openship.io/api/cloud/support/tickets?status=open&limit=25' \
-H "X-Internal-Token: $OPENSHIP_INTERNAL_TOKEN"
```
For replies, send JSON with a fresh UUID in `requestId`, the reply in `message`,
and `resolve: true` to close the ticket. Reuse the UUID when retrying an uncertain
response. A 202 response means the reply is saved and queued, not that SMTP has
delivered it. Read the ticket to check `deliveredAt`, `lastError`, and
`nextAttemptAt` for each message.
Deploy the API (including migrations `0152_cloud_support.sql` and
`0167_cloud_support_customers.sql`) before the dashboard.
Then submit a test report from `/support`, check its reference through the operator
API, and verify receipt and team notification in the configured mailboxes.
## Verification
`apps/api/test/modules/cloud-support` covers the website-to-API HTTP request, real
SQL persistence, the shared SMTP sender, recipient rejection and retry, concurrent
submission deduplication, worker lease recovery, operator access, replies,
resolution, pagination, input validation, cross-account isolation, anonymous-ticket
privacy, idempotent customer replies and the local relay. The connection integration
test exercises a real Cloud session through the existing transport and auth middleware,
and rejects PAT access. Dashboard tests cover connected and disconnected navigation,
desktop access, personal versus shared accounts, draft preservation, connection changes
and stale responses after navigation. SMTP tests use
a loopback server; they do not send mail to real customers.
## Operations
{/* api-operations:start */}
| Operation | REST API |
| --- | --- |
| Save a Cloud support ticket and queue acknowledgement and team email. Public intake returns only a receipt and deduplicates retries. | `POST /api/cloud/support` `Handler authentication` |
| List Cloud support tickets with status filtering and cursor pagination. Requires internal operator authority. | `GET /api/cloud/support/tickets` `Internal operator` |
| Read a Cloud ticket, its replies, and email delivery attempts. Requires internal operator authority. | `GET /api/cloud/support/tickets/:id` `Internal operator` |
| Open or resolve a Cloud support ticket. Requires internal operator authority. | `PATCH /api/cloud/support/tickets/:id` `Internal operator` |
| Save and queue an idempotent support reply, optionally resolving the ticket in the same transaction. Requires internal operator authority. | `POST /api/cloud/support/tickets/:id/replies` `Internal operator` |
| Retry undelivered support email while preserving active delivery leases and already accepted messages. Requires internal operator authority. | `POST /api/cloud/support/tickets/:id/retry` `Internal operator` |
| List the signed-in customer’s tickets with status, search and cursor pagination. Uses the personal Cloud session, including on connected local installations. | `GET /api/cloud/support/mine` `Handler authentication` |
| Read the private support account and connection binding. Local installations require the caller’s own verified Cloud link; shared organization credentials never grant private ticket access. | `GET /api/cloud/support/session` `Handler authentication` |
| Save an account-owned Cloud support ticket and queue the existing receipt and team notification. | `POST /api/cloud/support/mine` `Handler authentication` |
| Read the customer’s own conversation without internal delivery metadata. | `GET /api/cloud/support/mine/:id` `Handler authentication` |
| Save an idempotent customer reply, notify support and reopen the conversation. | `POST /api/cloud/support/mine/:id/replies` `Handler authentication` |
| Open or resolve the signed-in customer’s own ticket. | `PATCH /api/cloud/support/mine/:id` `Handler authentication` |
{/* api-operations:end */}
---
# HTTP basics
URL: https://openship.io/docs/api/http.md
Authentication, organization scope, responses, errors, rate limits, and streams.
REST requests use your installation's URL plus `/api`. Authenticate scripts with a personal access
token. [Create a token](/docs/api/tokens) or use the [CLI login guide](/docs/cli/access).
```bash
curl "$OPENSHIP_URL/api/projects" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Use `Content-Type: application/json` for JSON bodies. Send only the fields you are changing in a partial
update. The [resource pages](/docs/api) document request fields and the equivalent SDK calls.
## Authentication
A request proves who it is in exactly one of four ways. Openship checks for a `Bearer` token first, then a
session cookie, then the loopback fallback (only if that mode is enabled).
| Method | What you send | Who uses it |
|---|---|---|
| **Personal access token** | `Authorization: Bearer opsh_pat_…` | CLI, scripts, server-to-server |
| **Session cookie** | httpOnly cookie set at login | The dashboard, in a browser |
| **MCP OAuth** | An OAuth 2.1 access token bound at consent | AI agents connecting to `/api/mcp` |
| **Zero-auth loopback** | Nothing (request from `127.0.0.1`) | Desktop app / opt-in single-user instance |
```bash
curl https://your-host/api/projects \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
A `Bearer` token presented from a browser-trusted origin is rejected (`BEARER_NOT_ALLOWED_FROM_BROWSER`), so an
exfiltrated session token can't be replayed past the httpOnly cookie. A token can be **org-scoped** (rejects a
mismatched `X-Organization-Id` with `TOKEN_ORG_SCOPE`) and **read-only** (rejects mutations with
`TOKEN_READ_ONLY`). MCP OAuth discovery is served at the origin root:
`/.well-known/oauth-authorization-server` and `/.well-known/oauth-protected-resource`.
## Permissions
Authenticated application routes declare a permission tag of the form
`resource:action` — `project:read`, `domain:write`, `deployment:admin` — and sub-resources add a middle segment
(`project:service:write`). Shared operations also enforce access for native SDK callers. The action usually lines up with the HTTP method: `read` (GET one), `write`
(POST/PUT/PATCH), `admin` (DELETE and destructive), `list` (GET a collection).
Access is decided **per organization**. Openship resolves which org you mean from the `X-Organization-Id`
header (falling back to your session default), then checks your role there — `owner`, `admin`, `member`, or
`restricted` (grant-only). The operation tables list the declared route permission. Shared operations also check resource ownership,
current membership, token restrictions, and any additional administrative requirements. See
[Permissions & roles](/docs/security/permissions) for the full model.
## Rate limits
The whole `/api` surface is rate-limited. Unauthenticated requests fall under a per-IP default; authenticated
requests get a more generous per-user budget. Some route groups carry a tighter or looser named policy. Limits
are per rolling minute.
| Policy | Limit | Keyed by | Applies to |
|---|---|---|---|
| `default-anon` | 300 / min | IP | Any unauthenticated route |
| `default-authed` | 3000 / min | user | Any authenticated route |
| `auth-tight` | 10 / min | IP | `POST /api/auth/*` (login, signup, reset) and self-host invite signup |
| `mcp` | 300 / min | IP | `/api/mcp` (tool-call bursts) |
| `webhook-ingress` | 120 / min | source IP | Inbound webhook deliveries |
| `billing-portal` | 20 / min | org | Stripe portal / checkout creation |
Every response carries `X-RateLimit-Limit`, `X-RateLimit-Remaining`, and `X-RateLimit-Reset`. `/api/health` is
never limited (load balancers and SSR poll it). On a self-hosted instance with neither `TRUST_PROXY` nor
`OPENSHIP_PUBLIC_URL` set, requests arriving over loopback skip the ordinary limits — the `auth-tight` login
gate always enforces.
When a bucket is exhausted the request gets a `429` with body `{"error":"Too many requests"}` plus a
`Retry-After` header (seconds). Back off until the window resets rather than retrying immediately.
## Error shape
Errors come back as JSON with a stable shape: a human `error` message and, for typed failures, a machine
`code`. Validation failures add a field-level `details` map.
```json
{ "error": "This access token is read-only", "code": "TOKEN_READ_ONLY" }
```
| Status | Typical `code` | Meaning |
|---|---|---|
| `400` | `VALIDATION_ERROR` | Request body failed the schema — see `details` for the offending fields. |
| `401` | `INVALID_TOKEN`, `BEARER_NOT_ALLOWED_FROM_BROWSER` | Not authenticated, or a bad/expired token (plain `Unauthorized` when no session at all). |
| `403` | `TOKEN_ORG_SCOPE`, `TOKEN_READ_ONLY` | Authenticated but not allowed — wrong org, read-only token, or your role/grants deny the action. |
| `404` | — | Resource doesn't exist, or isn't in your organization (IDOR-safe). |
| `409` | — | Conflict with current state (e.g. a delete already in progress). |
| `429` | — | Rate-limited (see above). |
| `503` | `AUTH_UNAVAILABLE` | The auth backend is unreachable — retry; never treated as "no session". |
| `500` | — | Unhandled server error (`{"error":"Internal server error"}`, no code). |
## Fixed organization scope
Send both `X-Organization-Id: org_123` and `X-Openship-Scope: fixed` to require that exact organization.
Authentication and grants still apply. A token bound to a different organization is rejected.
The remote SDK sends these headers when configured with `organizationId`; it first checks API capability
support. See [scope compatibility](/docs/api/sdk/compatibility#fixed-organization-scopes).
## Streams and retries
Endpoints marked as streams return Server-Sent Events, not a single JSON object. Use `curl -N` or an SSE
client, and close the connection when done. SDK stream methods return async iterables and accept an abort
signal. [Deployment progress](/docs/api/deployments#read-progress-events) shows both interfaces.
A dropped connection does not prove a mutation failed. Inspect the resource or run status before retrying
a create, deploy, or restore. The SDK does not automatically retry mutations.
## Availability
Self-hosted routes are not mounted on the Cloud API. A named SDK method can still require a configured
provider, host capability, or operator authority. HTTP-only rows have no named native operation; a remote
client can use its [HTTP transport](/docs/api/sdk/utilities#http-transport) where authentication permits it.
---
# Notifications
URL: https://openship.io/docs/api/notifications.md
Configure channels, subscriptions, and alert delivery.
import { TypeTable } from "fumadocs-ui/components/type-table";
The Notifications API decides who hears about events like a failed deploy or an expiring SSL cert, and how.
You register **channels** (where alerts go — email, webhook, Slack, Discord, Microsoft Teams, or the in-app bell), toggle
**subscriptions** (which event categories reach each channel), set org-wide **defaults** for new members, and
read **deliveries** (the alert feed behind the bell icon). In the dashboard this is the **Settings →
Notifications** page. Channels, subscriptions, and deliveries are per-user; defaults are per-org.
This module ships on both self-hosted and cloud instances. There is no dedicated `openship` CLI
command — manage notifications from the dashboard or these endpoints directly.
## Categories
Categories are the stable, user-facing event groups (e.g. `deploy.failed`, `backup.failed`,
`domain.expiring`) that subscriptions and defaults key off. They live in code, not the database, so `GET
/api/notifications/categories` is a static registry — each entry has an `id`, `group`, `label`,
`description`, and `defaultEnabled`.
The response also carries a `groups` array (`{ id, label }`, already in display order) that the categories'
`group` field points into — `deployment`, `app_health`, `backups`, `jobs`, `domains`, `members`, `billing`.
The `billing` group and its categories are omitted outside Openship Cloud, where nothing can fire them.
```ts
const result = await ship.notifications.categories();
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/notifications/categories" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Create a channel
A channel is a destination. The `config` object is shape-checked per `kind`; secrets in it (webhook signing
keys, Slack URLs, Telegram bot tokens) are stored encrypted and never returned in full.
```ts
const result = await ship.notifications.createChannel({
kind: "email",
label: "On-call inbox",
config: {
address: "ops@example.com",
},
});
console.log(result);
```
```bash
curl -X POST "$OPENSHIP_URL/api/notifications/channels" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"kind":"email","label":"On-call inbox","config":{"address":"ops@example.com"}}'
```
The `config` shape depends on `kind`:
: form. Required for kind "telegram". Stored encrypted; responses only report botTokenConfigured plus the public botId.',
},
"telegram.chatId": {
type: "string",
description:
'The destination chat: a numeric id (negative for groups/supergroups) or @publicchannel. Required for kind "telegram".',
},
"telegram.messageThreadId": {
type: "string",
description: "Optional forum topic id, to post into one thread of a supergroup.",
},
}}
/>
In Teams, create a **Workflow** with the **"When a Teams webhook request is received"** trigger
and use the URL it generates. Legacy `webhook.office.com` connector URLs are also accepted. The
URL is stored encrypted and comes back as `webhookUrlConfigured` in responses, never in full.
Message **@BotFather** → `/newbot` for the token. A bot can only write to a chat that has already
started it, so send the bot a message (or add it to your group) first. For the chat id, call
`https://api.telegram.org/bot/getUpdates` and read `result[].message.chat.id` — group ids
are negative. Editing a Telegram channel without resending `botToken` keeps the stored one.
New channels start `enabled: true`. An `in_app` channel is `verified` immediately; every other kind starts
unverified and must be verified (via a test send) before it will deliver — flip `verified` with `PATCH`.
## Update a channel
Send only the fields you want to change. Changing `config` on a non-`in_app` channel resets `verified` to
`false`, since the destination may have moved.
```
PATCH /api/notifications/channels/:id
```
## Subscribe a channel to a category
A subscription is one toggle in the (user, org, category, channel) grid. `PUT` is an idempotent upsert — send
the same triple again to flip `enabled`. The `channelId` must be a channel you own.
```ts
const result = await ship.notifications.upsertSubscription({
category: "deploy.failed",
channelId: "chan_123",
enabled: true,
});
console.log(result);
```
```bash
curl -X PUT "$OPENSHIP_URL/api/notifications/subscriptions" \
-H "Authorization: Bearer $OPENSHIP_TOKEN" \
-H "Content-Type: application/json" \
-d '{"category":"deploy.failed","channelId":"chan_123","enabled":true}'
```
## Org defaults
Defaults seed the subscription grid for new members of the org. Setting a default is admin-only
(`notifications:admin`); reading them is not.
```
PUT /api/notifications/defaults
```
## Read the alert feed
`GET /api/notifications/deliveries` returns your recent deliveries in the active org — this is the history
behind the bell icon. `GET /api/notifications/deliveries/unseen-count` powers the badge, and `POST
/api/notifications/deliveries/:id/seen` clears one.
```ts
const result = await ship.notifications.listDeliveries({
unseen: true,
limit: 20,
});
console.log(result);
```
```bash
curl "$OPENSHIP_URL/api/notifications/deliveries?unseen=true&limit=20" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
## Errors
The `kind` isn't one of `email`/`webhook`/`in_app`/`slack`/`discord`/`msteams`/`telegram`, `label`
is missing, or the `config` failed its per-kind check (a malformed email, a non-`http(s)` webhook
URL, a Slack URL that isn't `https://hooks.slack.com/...`, a Discord URL that isn't
`https://discord.com/api/webhooks/...`, a Teams URL that isn't an https Workflow or
`webhook.office.com` URL, or a Telegram token/chat id that isn't in `:` /
numeric-or-`@name` form). Subscriptions need `category`, `channelId`, and a boolean `enabled`;
defaults need `category` and a boolean `defaultEnabled`.
The channel, subscription, or delivery `:id` doesn't belong to you (or was deleted). List your own
with the matching `GET` route to get valid ids.
## Operations
{/* api-operations:start */}
| Operation | SDK | REST API |
| --- | --- | --- |
| List supported notification categories and events. | `notifications.categories()` | `GET /api/notifications/categories` `notifications:read` |
| List configured delivery channels. | `notifications.listChannels()` | `GET /api/notifications/channels` `notifications:read` |
| Create a delivery channel. | `notifications.createChannel(input)` | `POST /api/notifications/channels` `notifications:write` |
| Read notification subscriptions. | `notifications.listSubscriptions()` | `GET /api/notifications/subscriptions` `notifications:read` |
| Create or update a subscription. | `notifications.upsertSubscription(input)` | `PUT /api/notifications/subscriptions` `notifications:write` |
| Read default notification routing. | `notifications.listDefaults()` | `GET /api/notifications/defaults` `notifications:read` |
| Set default notification routing for a category. | `notifications.upsertDefault(input)` | `PUT /api/notifications/defaults` `notifications:admin` |
| Read notification delivery history. | `notifications.listDeliveries(input?)` | `GET /api/notifications/deliveries` `notifications:read` |
| Count notifications the user has not seen. | `notifications.unseenCount()` | `GET /api/notifications/deliveries/unseen-count` `notifications:read` |
| Update channel configuration or rotate credentials. | `notifications.updateChannel(id, input)` | `PATCH /api/notifications/channels/:id` `notifications:write` |
| Test the channel’s delivery configuration. | `notifications.testChannel(id)` | `POST /api/notifications/channels/:id/test` `notifications:write` |
| Remove a delivery channel. | `notifications.removeChannel(id)` | `DELETE /api/notifications/channels/:id` `notifications:write` |
| Remove a subscription. | `notifications.removeSubscription(id)` | `DELETE /api/notifications/subscriptions/:id` `notifications:write` |
| Mark the selected notifications seen. | `notifications.markSeen(id)` | `POST /api/notifications/deliveries/:id/seen` `notifications:write` |
{/* api-operations:end */}
---
# Edge administration
URL: https://openship.io/docs/api/edge.md
Inspect and adopt existing edge sites on a self-hosted installation.
Inspect or adopt sites already managed by the edge proxy on a self-hosted installation. The SDK exposes
site inspection and removal through `ship.system`; imports and installation preflight remain HTTP-only. Use [domains](/docs/api/domains) for project hostnames and
[servers](/docs/api/servers) for edge component installation and updates.
## Inspect existing sites
```ts
const scan = await ship.system.listUntrackedEdgeSites();
console.log(scan.scanned, scan.orphans);
```
```bash
curl "$OPENSHIP_URL/api/system/edge/untracked" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Site inspection and removal require installation administrator authority. Review discovered sites before
importing or removing them. Importing associates supported sites with
Openship projects; removing an untracked site changes the host's edge configuration.
## Installation edge preflight
`POST /api/system/self-edge/preflight` checks the edge configuration needed to expose Openship itself.
It is separate from attaching a domain to an application project.
For the interactive workflow and command options, see the [Edge guide](/docs/guides/the-edge) and
[CLI edge reference](/docs/cli/reference/edge).
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| List edge sites not tracked by project records. | `system.listUntrackedEdgeSites()` | `GET /api/system/edge/untracked` `settings:read` · Self-hosted |
| Remove an authorized untracked edge site. | `system.removeUntrackedEdgeSite(input)` | `POST /api/system/edge/untracked/remove` `settings:admin` · Self-hosted |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Import discovered edge sites. | HTTP only | `POST /api/system/edge/import-sites` `Internal operator` · Self-hosted |
| Check edge readiness for the Openship installation itself. | HTTP only | `POST /api/system/self-edge/preflight` `Internal operator` · Self-hosted |
{/* api-operations:end */}
---
# Cloud
URL: https://openship.io/docs/api/cloud.md
Connect installations to Cloud and use its HTTP control endpoints.
import { TypeTable } from 'fumadocs-ui/components/type-table';
Cloud endpoints connect a self-hosted installation to Openship Cloud and support browser handoffs,
managed routing, and transfers. The self-hosted connection routes and Cloud control-plane routes share
`/api/cloud`; the process mode determines which are available.
There is no named native `cloud` group. To manage Cloud projects through the SDK, use the
[remote client](/docs/api/sdk/client) with the canonical Cloud API and Cloud organization ID.
A local owner's Cloud link does not authorize fixed requests or bound/scoped credentials to manage
Cloud-stored records; see
[Cloud compatibility](/docs/api/sdk/compatibility#cloud).
## Self-hosted endpoints
Present only on a self-hosted instance (not in `CLOUD_MODE`). The cloud connection is **org-owned**: it
belongs to the organization owner, so every member sees the same verdict. Disconnect and connect-finalize
require the `owner` role, not merely a `cloud:admin` grant.
### Check connection status
```
GET /api/cloud/status
```
```bash
curl "$OPENSHIP_URL/api/cloud/status" \
-H "Authorization: Bearer $OPENSHIP_TOKEN"
```
Connecting itself is a browser flow started from the dashboard (**Settings → Cloud**): a popup runs the
PKCE handshake against Openship Cloud, then posts the result to `connect-finalize` below. There is no
dedicated `openship cloud connect` CLI verb.
### Finalize a connection
The dashboard popup reads its PKCE verifier from `localStorage` and posts the returned code here to store
the org's cloud bearer.
```
POST /api/cloud/connect-finalize
```
`connect-finalize` and `disconnect` take over the org's cloud bearer, so they are gated by `requireRole("owner")`
on top of the `cloud:admin` tag. A non-owner with a `cloud:admin` grant still gets `403`.
## Cloud control-plane endpoints
Present only in cloud mode (`CLOUD_MODE`) — i.e. these run on Openship Cloud, not on your self-hosted box.
All tenant-scoped operations forward to Oblien through the **caller's namespace token**; Oblien enforces the
namespace boundary natively, so there is no SaaS-side ownership ledger. The public handoff routes are
reached by browser redirects and authenticated by a signed, single-use token in the URL.
Your self-hosted instance calls the control-plane endpoints for you via its cloud client — you don't wire
them up by hand, and there is no `openship` CLI verb that maps to them one-to-one. The request shapes below
are documented so integrators can reason about the traffic.
### Handoff & code exchange
The connect and desktop-login flows never hand the local instance a browser cookie. Instead a short-lived,
PKCE-bound **handoff code** is minted (`connect-authorize`), then swapped for a dedicated session
(`exchange-code`).
```
POST /api/cloud/connect-authorize
```
```
POST /api/cloud/exchange-code
```
The public `GET` handoff routes take query params, not a body — `desktop-handoff` and `connect-handoff`
expect `redirect`, `state`, and `code_challenge`; `github/install-callback` expects `installation_id`,
`setup_action`, and `state`; `github/oauth-bridge` expects `token`.
GitHub installation links first open Openship's account selection using `flow=select` and
`state`. The user can reconnect an existing installation or continue to GitHub for a new
one. This also works in the external browser used by self-hosted and desktop instances:
the temporary state binds the choice to its initiating user and workspace without requiring
a Cloud browser session. Discovery and selection recheck access, and the installation claim
uses the same verification and transaction as the dashboard picker.
### Deploy proxies (preflight, edge proxy, analytics)
```
POST /api/cloud/preflight
```
```
POST /api/cloud/edge-proxy
```
```
POST /api/cloud/analytics
```
', description: 'Operation-specific query parameters passed through to Oblien.' },
}}
/>
### Dashboard product telemetry
```
POST /api/cloud/telemetry
```
This optional, first-party endpoint accepts only allowlisted dashboard page and checkout-navigation
events. It is separate from the customer traffic analytics relay above and is not an SDK or MCP
operation. It returns `404` unless production Cloud telemetry is explicitly configured.
Requests must come from the configured dashboard Origin, use the browser's cookie session when
signed in, and omit bearer authorization. The server verifies the current session before associating
events with a user or organization. Browser events cannot report payments or other business outcomes;
unrecognized properties and bodies larger than 4 KiB are rejected.
### Pages
`pages` creates a managed static page; the enable/disable/delete actions each take just a slug.
```
POST /api/cloud/pages
```
```
POST /api/cloud/pages/disable (also /enable, /delete)
```
### Invitation relay
Used when a self-hosted operator sets `invitationMailSource = "cloud"` — the SaaS sends the email from its
own infrastructure. Capped at 20/hour per org inside the service.
```
POST /api/cloud/send-invitation
```
### Subgraph transfer & teardown
The ingest/export pair moves an org's or a single project's rows between a self-hosted instance and the SaaS
(team-mode migration and project transfer). Instance-scope dumps are refused.
```
POST /api/cloud/ingest-subgraph
```
```
POST /api/cloud/promote-project
```
Explicit project promotion uses this receipt-aware variant with `{ dump, promotionId }`. The source
persists the transfer ID and original Cloud identity before making the request. Cloud commits the
receipt in the same transaction as the project data. A retry with that receipt returns the original
import counts, allowing the source to retry local cleanup without importing or overwriting again.
Matching project IDs alone do not authorize cleanup; older duplicates without a receipt require
review. Both instances must support this endpoint. An older Cloud API rejects it before importing.
Before local cleanup starts, Openship blocks configuration writes and checks the source snapshot
again. An edit committed before this check preserves the local copy with `TRANSFER_SOURCE_CHANGED`;
edits attempted during cleanup return `PROJECT_TRANSFER_IN_PROGRESS`. Failed cleanup releases this
guard so the project remains editable. New builds admitted after import are preserved, not cancelled
as part of promotion.
Promotion transfers configuration; it does not migrate running workloads or persistent application
data. Deploying a local project on a connected Cloud server uses `serverId` and does not require
promotion. See [the desktop MCP workflow](/docs/api/mcp#deploy-a-desktop-folder-on-cloud).
```
POST /api/cloud/export-subgraph
```
```
POST /api/cloud/teardown-project
```
### GitHub App proxy
Cloud holds the GitHub App private key; self-hosted instances never do. Local hands off `(userId, request)`
and gets resolved data back — it never signs a JWT or sees the App credentials.
```
POST /api/cloud/github/installation-token
```
`installation-token` resolves the installation from the caller's org, not from a client-supplied id — passing
one has no effect. This prevents a caller from minting a token for an installation it doesn't own.
## Errors
`connect-finalize` and `disconnect` require the org `owner` role. A member with only a `cloud:admin` grant is
rejected.
The requested slug is owned by another tenant on the shared cloud zone. Oblien returns `409` and Openship
forwards it. Choose a different slug.
`ingest-subgraph` rejects dumps whose `formatVersion` doesn't match the SaaS (`code: INGEST_FORMAT_MISMATCH`).
Update your local instance and re-dump.
`ingest-subgraph` caps the request body at 50MB (`code: PAYLOAD_TOO_LARGE`) before auth even runs.
Handoff codes are single-use and time-bound; `exchange-code` returns `401` once consumed or expired. The
control-plane `cloud:*` endpoints return `401` when the cloud session bearer is missing or revoked — reconnect
from the dashboard.
## Operations
{/* api-operations:start */}
### Managed server connections
| Operation | REST API |
| --- | --- |
| Verify the connected Cloud user's administration of a server in the exact requested organization before linking an installation. | `POST /api/cloud/servers/:id/authorize` `server:admin` |
| Issue namespace-scoped server credentials after ownership checks; work admission also verifies the subscription. Credentials stay on the installation's server and must not be exposed to a browser. | `POST /api/cloud/servers/:id/connection` `server:admin` |
| Claim durable server activity for a linked installation and synchronize its project registry before execution; a disconnected claim does not expire. | `POST /api/cloud/servers/:id/activity` `server:admin` |
| Release the same user's exact controller and activity claim after work finishes, and update its registered projects. | `POST /api/cloud/servers/:id/activity/release` `server:admin` |
| Read a durable deletion receipt using billing administration, the original organization and exact operationId after the server row has been removed. | `GET /api/cloud/server-deletions/:id` `billing:admin` |
### HTTP endpoints
| Operation | REST API |
| --- | --- |
| The connected cloud account (name, email, avatar). | `GET /api/cloud/account` `cloud:read` |
| Proxy Oblien analytics for a hostname in the caller's namespace. | `POST /api/cloud/analytics` `cloud:write` |
| Capture optional hosted dashboard product events with exact-origin and verified cookie identity checks. | `POST /api/cloud/telemetry` `Handler authentication` |
| Consent page mints a one-time handoff code (cookie session checked inline). | `POST /api/cloud/connect-authorize` `Handler authentication` |
| Complete the connect popup: exchange the PKCE code and store the cloud bearer. | `POST /api/cloud/connect-finalize` `cloud:admin` · Self-hosted |
| Validate connect params, then 302 to the dashboard consent page. | `GET /api/cloud/connect-handoff` `Handler authentication` |
| Poll the local Cloud connection handoff. | `GET /api/cloud/connect-poll` `Handler authentication` |
| OAuth → one-time code → redirect to the desktop app callback. | `GET /api/cloud/desktop-handoff` `Handler authentication` |
| Revoke the current cloud session server-side (idempotent). | `POST /api/cloud/disconnect` `cloud:admin` |
| Sync the managed edge proxy (bind a slug to a target). | `POST /api/cloud/edge-proxy` `cloud:write` |
| Remove an authorized Cloud edge-proxy route. | `POST /api/cloud/edge-proxy/delete` `cloud:write` |
| Begin verification for an edge-proxy domain. | `POST /api/cloud/edge-proxy/verify` `cloud:write` |
| Check edge-proxy domain verification. | `POST /api/cloud/edge-proxy/verify-check` `cloud:write` |
| Exchange a one-time code for user + session (rate-limited). | `POST /api/cloud/exchange-code` `Handler authentication` |
| Export an org- or project-scope subgraph dump (rate-limited). | `POST /api/cloud/export-subgraph` `cloud:admin` |
| Select an existing GitHub installation with flow=select, or atomically claim the workspace-bound attempt after GitHub user-token and App-JWT verification. | `GET /api/cloud/github/install-callback` `Handler authentication` |
| Build an Openship installation-selection URL with a one-time workspace state; existing installations can reconnect without another GitHub setup callback. | `POST /api/cloud/github/install-url` `cloud:write` |
| Mint a short-lived (~60min) installation access token. | `POST /api/cloud/github/installation-token` `cloud:write` |
| List the org owner's GitHub App installations. | `GET /api/cloud/github/installations` `cloud:read` |
| Consume the bridge token and redirect the browser into GitHub OAuth. | `GET /api/cloud/github/oauth-bridge` `Handler authentication` |
| Start GitHub OAuth: return a one-time bridge URL. | `POST /api/cloud/github/oauth-handoff` `cloud:write` |
| Friendly "GitHub connected" close-window page. | `GET /api/cloud/github/oauth-success` `Handler authentication` |
| Cloud-resolved GitHub OAuth identity (login, avatar) for the caller. | `GET /api/cloud/github/user-status` `cloud:read` |
| Ingest an org- or project-scope subgraph dump (rate-limited, 50MB cap). | `POST /api/cloud/ingest-subgraph` `cloud:admin` |
| Import a project and its promotion receipt atomically, or acknowledge the same original import on retry (rate-limited, 50MB cap). | `POST /api/cloud/promote-project` `cloud:admin` |
| Create a Cloud Page (proxy Oblien `pages.create`). | `POST /api/cloud/pages` `cloud:write` |
| Delete a Cloud Page by slug. | `POST /api/cloud/pages/delete` `cloud:write` |
| Disable a Cloud Page by slug. | `POST /api/cloud/pages/disable` `cloud:write` |
| Enable a Cloud Page by slug. | `POST /api/cloud/pages/enable` `cloud:write` |
| Cloud deployment preflight — slug / custom-domain availability. | `POST /api/cloud/preflight` `cloud:write` |
| Run an allowed Pages or routing action after verifying customer namespace ownership. | `POST /api/cloud/resource-proxy` `cloud:write` |
| Read routes or certificates belonging to the caller's Cloud namespace. | `GET /api/cloud/route-registry` `cloud:read` |
| Relay an invitation email via the SaaS mail infrastructure. | `POST /api/cloud/send-invitation` `cloud:write` |
| Openship Cloud connection status for this instance. | `GET /api/cloud/status` `cloud:read` · Self-hosted |
| Delete a project's rows on the SaaS (bring-home / reconcile). | `POST /api/cloud/teardown-project` `cloud:admin` |
| Mint a namespace-scoped Oblien token for the caller's org. | `POST /api/cloud/token` `cloud:write` |
{/* api-operations:end */}
---
# Public notices
URL: https://openship.io/docs/api/notices.md
Read installation announcements and publish them with operator authority.
Notices are installation-wide announcements. Reading active notices is public. Publishing, listing
inactive notices, or deactivating a notice requires a separate [operator capability](/docs/api/sdk/operator).
An organization owner role does not grant that capability.
## Read active notices
```ts
const { advisories } = await ship.notices.list();
console.log(advisories);
```
```bash
curl "$OPENSHIP_URL/api/notices"
```
The response contains active `advisories`, including a title, message, severity, and optional action or
target. Scheduled start and end times determine when a notice appears.
## Publish a notice
The SDK example uses a configured `operator`, available to trusted installation code. The REST example
uses the installation's internal operator token.
```ts
const notice = await operator.notices.create({
title: "Planned maintenance",
message: "Deployments will pause during maintenance.",
severity: "info",
startsAt: "2026-10-01T01:00:00Z",
endsAt: "2026-10-01T01:30:00Z",
});
console.log(notice.id);
```
```bash
curl -X POST "$OPENSHIP_URL/api/notices" \
-H "X-Internal-Token: $OPENSHIP_INTERNAL_TOKEN" \
-H "Content-Type: application/json" \
-d '{"title":"Planned maintenance","message":"Deployments will pause during maintenance.","severity":"info","startsAt":"2026-10-01T01:00:00Z","endsAt":"2026-10-01T01:30:00Z"}'
```
| Field | Use |
| --- | --- |
| `title`, `message` | Required announcement text. |
| `severity` | `critical`, `recommended`, or `info`. |
| `startsAt`, `endsAt` | Optional ISO timestamps limiting visibility. |
| `actionLabel`, `actionUrl` | Optional link shown with the notice. |
| `targetType`, `targetId` | Optional platform, app, project, or mail target. |
`operator.notices.listAll()` includes inactive notices. `operator.notices.remove(id)` deactivates a
notice so it no longer appears in the active feed.
## Operations
{/* api-operations:start */}
### Resource methods
| Operation | SDK | REST API |
| --- | --- | --- |
| Read active public installation announcements. | `notices.list()` | `GET /api/notices` `Handler authentication` |
### HTTP endpoints
| Operation | SDK | REST API |
| --- | --- | --- |
| Publish an installation notice using operator authority. | `operator.notices.create(input)` | `POST /api/notices` `Internal operator` |
| Deactivate an installation notice using operator authority. | `operator.notices.remove(id)` | `DELETE /api/notices/:id` `Internal operator` |
| List all installation notices using operator authority. | `operator.notices.listAll()` | `GET /api/notices/all` `Internal operator` |
{/* api-operations:end */}
---
# Third-party email delivery
URL: https://openship.io/docs/guides/email-webmail/relays.md
Route your mail server's outbound mail through an external SMTP relay.
An SMTP relay is just a middleman that takes the mail your server wants to send and actually delivers it to the
world — instead of your own machine talking straight to Gmail or Outlook.
Relaying is worth setting up because deliverability comes down to IP reputation: a brand-new server IP has none,
so inbox providers are quick to bounce or spam-folder anything it sends. Routing outbound mail through an
established relay provider means it leaves from IPs receiving servers already trust. It also sidesteps port 25,
which most cloud providers block outbound by default — relays send over port 587 instead, so there's no
service-limit exemption to request.
Openship's mail relay handles it natively — go to **Emails → Sending → "Relay via Amazon SES (or any SMTP
relay)"** and choose provider **Custom** for any relay that doesn't have a preset. The same host, port, and
credential fields also work under **Settings → Email**, if you'd rather relay Openship's own notification emails
through the same provider.
Whichever provider you pick, it'll ask you for roughly the same things:
- **DNS records** (SPF, DKIM, sometimes DMARC) added at your domain's DNS provider, so receiving servers can
verify mail claiming to be from your domain actually came from the relay you authorized.
- **Sender registration or verification** — most relays refuse to send on behalf of a From address they don't
recognize, so you register or verify each sender (or your whole domain) before mail flows.
- **SMTP credentials** — a username and password (or API key used as one) scoped to sending mail.
- **Host and port** to plug into Openship's relay form — almost always port `587`.
Oracle Cloud (OCI) Email Delivery is documented next: [OCI Email Delivery](/docs/guides/email-webmail/relay-oci).
## Other providers
OCI is just one option — AWS SES, Resend, Mailgun, SendGrid, and similar providers all follow the same shape:
DNS authentication (SPF/DKIM), sender or domain verification, SMTP credentials, and a host/port you plug into the
same **Emails → Sending** form. If you've set one of these up with Openship, a PR adding a page here for your
provider is welcome.
---
# OCI Email Delivery
URL: https://openship.io/docs/guides/email-webmail/relay-oci.md
Route your Openship mail server's outbound mail through Oracle Cloud (OCI) Email Delivery — free tier, good IP reputation, no PTR chores.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Oracle Cloud's **Email Delivery** service is a solid pick for an [SMTP relay](/docs/guides/email-webmail/relays):
it's free for the first 3,000 emails a month, and because your mail leaves from Oracle's own IP addresses (not a
brand-new cloud IP nobody trusts yet), inbox providers are far less likely to bounce or spam-folder it.
- An **OCI account** (Oracle's free tier covers this).
- A **domain name** you control, where you can add DNS records.
- An **Openship mail server** already set up. If you haven't done that yet, start with
[Email & webmail](/docs/guides/email-webmail) — you'll need it running before there's anything to relay.
## Setup at a glance
### Create an Email Domain and add the DKIM records
In OCI Email Delivery, create an **Email Domain** for your domain. OCI generates DKIM DNS records for it — add
those at your domain's DNS provider. DKIM is a cryptographic signature that receiving mail servers use to
confirm a message really came from your domain, so this step is what makes the rest of the setup trustworthy.
### Add the SPF record
Add the SPF record from [OCI's SPF guide](https://docs.oracle.com/en-us/iaas/Content/Email/Tasks/configurespf.htm)
at your domain's DNS provider. It's a one-line TXT entry that tells the world "Oracle's relay is allowed to send
mail on behalf of this domain" — without it, receiving servers have no way to know Oracle is a legitimate sender
for you.
### Register your approved senders
OCI refuses to relay mail from any From address it doesn't recognize, so register the addresses you'll send
from as **approved senders** — either a specific address, or `@yourdomain.com` to cover the whole domain at
once (only available once DKIM is active). Do this in the OCI Console (navigation menu → **Developer Services**
→ **Email Delivery** → **Approved Senders** → **Create Approved Sender**), or from the CLI:
```bash
oci email sender create --email-address you@yourdomain.com ...
```
### Create SMTP credentials
Create SMTP credentials for an IAM user: OCI Console → **Identity** → **Users** → **SMTP Credentials**. The
password is shown to you exactly once, so copy it somewhere safe the moment it appears — there's no way to
view it again later.
### Point Openship's relay at OCI
In Openship, go to **Emails → Sending → "Relay via Amazon SES (or any SMTP relay)"** and choose provider
**Custom**. Fill in:
- **Host** — `smtp.email..oci.oraclecloud.com` (swap in your OCI region)
- **Port** — `587`
- **Username / Password** — the SMTP credential you just created
The same host, port, and credential also work under **Settings → Email**, if you'd rather relay Openship's own
notification emails through OCI too.
## Gotchas / good to know
- **Approved senders are mandatory, not optional.** OCI's own docs put it plainly: "An approved sender must be
set up for all From: addresses sending mail through Oracle Cloud Infrastructure, or mail is rejected" ([OCI
docs](https://docs.oracle.com/en-us/iaas/Content/Email/Tasks/managingapprovedsenders.htm)). Register each
address individually, or — once DKIM is active for the Email Domain — register the whole domain at once with
an approved sender of the form `@yourdomain.com` ([OCI
docs](https://docs.oracle.com/en-us/iaas/Content/Email/Reference/gettingstarted_topic-Create_an_approved_sender.htm)),
which covers every mailbox in one shot.
- **The SMTP credential password only appears once.** The OCI Console shows it at creation time and never
again — if you lose it, the only fix is regenerating a new one.
- **Port 25 is blocked by default, and that's fine.** OCI blocks outbound port 25 on tenancies created after
June 2021. You can request a service-limits exemption if you need it, but relaying through OCI's SMTP relay on
port 587 sidesteps that wait entirely — and as a bonus, your mail leaves from Oracle's well-reputed IPs
instead of a fresh cloud IP that inbox providers are naturally suspicious of.
- **You can skip the PTR chore.** PTR (reverse DNS) is the record that maps a server's IP back to a hostname,
and large mail providers often junk mail from IPs that don't have one. Because your outbound mail actually
leaves through Oracle's relay IPs — which already have proper PTR records — your own instance's IP never
needs one.
---
# Email & webmail
URL: https://openship.io/docs/guides/email-webmail.md
Connect existing IMAP/SMTP mailboxes through webmail on Cloud, or run and manage your own mail server with Desktop and self-hosted Openship.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Most people rent their email from someone else — Gmail, Outlook, and the like. Openship lets you run the
whole post office yourself: a real mail server on your own machine, with your own domain, that sends and
receives mail and even gives you a webmail inbox in the browser. Think of it as the difference between renting
a PO box and owning the building.
You're not limited to one, either. Each mail server runs on its own host (one mail setup per server), and
Openship keeps them all in a single **Mail servers** list — provision as many as you like and switch between
them from one place. A lone server opens straight into its admin panel; once you have more than one, you land
on the list first.
This is a big, hands-on feature, so this guide stays at the map level: what each screen does and the order you
go through them. The fiddly bits — the exact DNS records and the reverse-DNS setup — are called out where they
happen, because the wizard walks you through those live.
**Emails** is available on Cloud, Desktop and self-hosted Openship. On Cloud, it connects your existing
IMAP/SMTP mailboxes through the webmail app. **Managed email is coming soon**: Cloud application plans
do not provision SMTP/IMAP servers or mailboxes. Mail-server setup and administration remain available
through Desktop and self-hosted Openship. See [Installation](/docs/getting-started/installation).
## Connect existing mailboxes on Cloud
Open **Emails → Connect existing mail server**. The standard webmail app installer asks for your
IMAP and SMTP hosts, the managed server that will run the client, and its public route. You can configure
ports in the backend's advanced fields; IMAP and SMTP connections require TLS. Confirming installation
deploys the webmail app through the normal application pipeline.
Sign in to the deployed webmail with your mailbox email address and password. Your existing provider
keeps the mailboxes and mail delivery; Openship hosts the browser client. Manage that client through
**Apps** or its project page, including domains, settings, logs and redeployment. This flow does not
install a new mail server, change MX records or create a mailbox at your provider.
The remaining steps in this guide apply to mail-server setup on Desktop and self-hosted instances.
- Openship running self-hosted, with at least one **connected server** (a clean Ubuntu or Debian machine is
recommended). See [Connect your own server](/docs/guides/custom-servers) if you don't have one yet.
- A **domain name** you control, where you can edit DNS records.
- **Port 25 open** for outbound mail — some hosting providers block it by default, so check before you start.
- Access to your **VPS provider's panel** (for the reverse-DNS step near the end).
A few words you'll see a lot:
- **Mail server** — the software that actually sends and receives email. Openship installs a well-known stack
(Postfix, Dovecot, and anti-spam tools) for you.
- **Mailbox** — one email account, like `you@yourdomain.com`, with its own password and inbox.
- **DNS records** — public settings for your domain that tell the rest of the internet where your mail lives.
- **Webmail** — an email app you open in a browser, so you don't need to configure a separate mail app.
## Step 1 — Provision a mail server
### Open the Emails page
In the sidebar, click **Emails**. With no mail server set up yet, you land straight on the **Mail Server
Setup** form. If you already run **several** mail servers, you'll see a list of them first — click **Add mail
server** to start another. (With a single existing server, Openship opens it straight to its admin panel; use
the **Add mail server** button there to set up another.)
### Pick a server and a domain
Choose which of your connected servers the mail stack should run on. If you only have one, Openship picks it
for you.
Then fill in two things:
- **Domain** — your bare domain, like `example.com` (no `https://`, no path). Openship shows you that your
mail server will live at `mail.example.com`.
- **Admin Password** — the password for the first mailbox, `postmaster@yourdomain`. You'll use it to log in
after setup. Don't want to think one up? Click **Generate** for a strong random one, then copy it somewhere
safe.
The right-hand panel lists exactly what gets installed — the mail stack, an automatic **Let's Encrypt** SSL
certificate, the DNS records you'll need, and the admin panel — plus the prerequisites (a domain with DNS
access, port 25 open, a clean server).
### Press Start Setup and watch it run
Click **Start Setup**. Openship connects to your server and works through the install one step at a time
(system update, mail stack, SSL, and so on), streaming the logs live — like watching the oven through the
glass door. You don't have to do anything while it runs.
Partway through, it pauses twice to wait for you. Those two pauses are the next two steps.
### Publish your DNS records
The install stops and shows a banner: **Publish DNS records before continuing**. Below it are cards — one per
record (things like MX, SPF, DKIM, and DMARC) — each with a **Copy value** button.
Go to wherever your domain's DNS is managed, add each record, and come back. Then click **I've set the records
- continue**.
Email delivery breaks without these records — they're how Gmail and Outlook decide your mail is real and not
spam. If you host DNS at a supported provider, the banner also offers **Auto-configure DNS**, which pushes the
records for you. Otherwise, copy them in by hand. For a gentler intro to DNS, see [Custom domains](/docs/guides/custom-domains).
### Set reverse DNS (PTR)
Next comes a second banner: **Set reverse DNS (PTR) before continuing**. This one is different — you set it at
your **VPS provider's panel** (Hostinger, DigitalOcean, AWS, and so on), **not** at your DNS provider.
The banner shows your server's IP address and the value to point it at (`mail.yourdomain`). Set it there, wait
a few minutes for it to take effect, then click **I've set the PTRs - continue**.
Normal DNS turns a name into an IP address; reverse DNS (a **PTR** record) turns the IP back into a name. Big
mail providers reject mail from servers whose reverse DNS doesn't match — so this step is not optional.
### Done
Openship finishes the SSL step and the page flips to the **admin panel**. Your mail server is live. It also
offers to send a quick welcome test email so you can confirm mail is flowing.
If you set one up before and Openship lost track of it (for example, you moved to a new computer), you don't
have to reinstall. On the setup form, click **Already have a mail server? Adopt it**, pick the server, and
click **Scan server**. If a mail stack is found, click **Adopt** — it's brought back into the dashboard with
your mailboxes and data left untouched.
## Step 2 — Manage domains and mailboxes
Once a server is provisioned, the **Emails** page becomes its admin panel — your home base for running the mail
server. It's organized into tabs:
- **Overview** — the hostname, the webmail button, mail stats (domains, mailboxes, storage), and quick links.
- **Domains** — add extra domains you want to receive mail for. A new domain accepts mail once its MX record
points at this server.
- **Mailboxes** — create email accounts under a domain. Each one is a login (`name@domain`) with its own
password and quota. This is also where you change the `postmaster` password later.
- **Aliases** — forwarding addresses, and a catch-all for everything else at a domain.
- **Notifications** — get told in a notification channel (Slack, Telegram, Discord, a webhook) when mail
arrives at one of these addresses.
- **Sending** — how outbound mail leaves: direct, or relayed through a provider. **Send test email** lives
here too.
- **DNS** — a reference copy of every record each domain needs, with a **Verify** button that checks whether
they're actually published.
- **Health** — live status of each mail process, refreshed automatically.
- **Backup** — snapshot the mail server (accounts, messages, keys) to one of your backup destinations.
- **Advanced** — the IMAP/SMTP connection settings for wiring up a mail app by hand, plus power-user actions
like restarting the stack or re-running the wizard.
When you add a domain under the **Domains** tab, Openship generates its DNS records (including a fresh DKIM
key). Publish those at your DNS provider — the **DNS** tab shows them and can verify them — before you rely on
that domain for mail.
## Step 3 — Deploy the webmail app
A mail server on its own has no web page — you'd point a mail app at it. Openship can also deploy **Zero**, a
webmail app, so you (and your users) get an inbox in the browser instead.
### Start from the Overview tab
On the admin panel's **Overview** tab, find the mail server card and click **Deploy webmail**. This opens the
**Deploy webmail** screen.
### Choose where it runs and at which address
Two choices:
- **Deploy to** — where the webmail app should run. You can put it on **this mail server**, on **another one of
your servers**, or on one of your managed **Openship Cloud servers**. The shared server picker connects a
selected Cloud server when needed. Redeploying an existing webmail starts with its saved destination.
- **Domain** — the web address people will open to reach the inbox. It defaults to `mail.yourdomain`. Whatever
you pick, its DNS must point at the deploy target — the on-screen hint tells you what's expected for the
option you chose.
The summary panel on the right shows the webmail address and the mail server it connects to.
### Press Deploy webmail
Click **Deploy webmail**. Openship creates a project and a deployment for you and drops you on the standard
**build screen**, which streams the logs live — the same screen you'd see [deploying any app](/docs/guides/deploy-from-github).
When it's done, the Overview card's button changes to **Open webmail**, which opens your inbox in a new tab.
Webmail used to ship as a prebuilt bundle instead of an app, and those older installs can't be redeployed —
they're replaced. The Overview card shows a **Replace webmail** link, and the deploy screen explains what goes
before the button does anything: the old webmail's project, container and sign-in sessions. Your mailboxes,
domains and every message stay on the mail server, untouched — everyone just signs in to the new inbox again.
## CLI
The provisioning flow works from the CLI too. `openship mail webmail` exposes the same deployment workflow;
see the [mail command reference](/docs/cli/reference/mail#openship-mail-webmail) for its options. Every `mail`
command addresses a self-hosted Openship instance, which can deploy the webmail app to a connected Cloud server.
```bash
# Start the install on a server for your domain (streams live)
openship mail setup --domain example.com
# When it pauses for DNS: publish the records, then acknowledge and resume
openship mail dns-ack
openship mail setup --domain example.com --start-step
# When it pauses for reverse DNS: set the PTR, then acknowledge and resume
openship mail ptr-ack
openship mail setup --domain example.com --start-step
# Check where things stand at any time
openship mail status
# Re-adopt an existing install (after losing the dashboard's record of it)
openship mail scan
openship mail adopt
```
When the install pauses, the CLI prints the exact `--start-step` number to resume from. Copy it into the next
`mail setup` command and it picks up right where it left off.
## Troubleshooting
Webmail connects to IMAP from the server running the webmail app. A mailbox working in Gmail or another
client does not prove that this server can reach it. For an Openship-managed mail server, the app settings
should use `mail.` on IMAP port **993** and SMTP port **465**, even for mailboxes on additional
domains or when outgoing mail uses a relay. The webmail address may be different from this backend hostname.
When webmail runs on the mail server itself, Openship maps this backend hostname to Docker's
`host-gateway` in the service configuration. This avoids a host DNS resolver returning a loopback
address inside the container while preserving the hostname used to verify the mail certificate.
The mapping is saved for redeploy and rollback. Cloud and other-server webmail use the mail server's
ordinary DNS address; external-backend settings are left as supplied.
Both IMAP and SMTP honor the container's hostname mappings; SMTP still requires verified TLS before
sending credentials. Existing installs need the updated control plane and webmail image, then
**Mail → Deploy webmail** once to save the mapping. Later project redeploys reuse it.
Connection failures and invalid or expired certificates show a mail-server connection error. “Invalid email
or password” is reserved for a credential rejection from IMAP. Check the webmail host's DNS and network path,
the mail server's client ports, and its certificate; keep TLS verification enabled. After changing a mailbox
password or backend setting, sign in again to refresh the saved session credentials.
Sign-in has a 40-second browser deadline covering verification and session confirmation. If the
connection stalls, the form shows “Sign in timed out” and allows another attempt.
Email is self-hosted only. It appears when Openship is running on your own infrastructure. On a managed/cloud
plan it's hidden on purpose.
This step is a check, not a wall — the install keeps going even when it warns. Direct-to-MX sending needs
outbound port 25. Many hosting providers block it by default, including AWS. You can
finish setup and route sending through an SMTP provider from the **Sending** tab (Amazon SES, and similar),
then use **Sending → Send test email** to confirm mail flows.
On a single-server install the probe runs from the same machine it is testing. An outbound port-25 restriction
can make `mail.example.com:25` time out even when the daemon listens on a non-loopback interface. If all three
client ports complete a TCP handshake and only TCP 25 times out, setup continues with a warning. Connection
refusals, routing errors, missing or loopback-only listeners, and client-port failures still stop setup.
Health keeps inbound SMTP **unverified**. Check TCP 25 from an independent host or send a test message from
another mail provider: open client ports do not prove that other mail servers can reach your inbound SMTP.
If receiving fails, check inbound TCP 25 in the host and provider firewalls. A relay configured in **Sending**
handles outgoing mail only.
This is normal for a brand-new domain — providers are cautious for the first day or two. Make sure your DNS
records (SPF, DKIM, DMARC) and your reverse DNS (PTR) are all published and verified: use the **DNS** tab's
**Verify** button and the **Health** tab. Marking early test messages as "not spam" speeds things up.
DNS changes can take a few minutes (sometimes longer) to spread. Give it time, then re-check on the **DNS**
tab. Double-check you pasted the value exactly and added it to the right domain.
## Related guides
---
# CLI command reference
URL: https://openship.io/docs/cli/reference.md
Every public CLI command, argument, and option, grouped by task.
Use `openship --help` to check the version installed on your machine. `` is required; `[value]` is optional. Aliases appear beside the command name.
## Global options
| Option | Meaning |
| --- | --- |
| `-V, --version` | output the version number |
| `--json` | Machine-readable JSON output (stdout data only) |
| `--context ` | Use a saved connection for this command without changing the default |
| `--api-url ` | Use a remote API for this command; authenticate with OPENSHIP_TOKEN |
| `--local` | Use this machine's installation with its private administrator credential |
| `--organization ` | Use a fixed organization scope for SDK resource commands (remote only) |
| `--native-config ` | Run SDK commands using an explicitly trusted JavaScript configuration |
| `-h, --help` | display help for command |
Put global options before the command, for example `openship --json project list`. See [native mode](/docs/cli/native) before using `--native-config`.
## Connect
| Command | Purpose |
| --- | --- |
| [`openship login`](/docs/cli/reference/login) | Connect to Cloud or self-hosted Openship with a Personal Access Token |
| [`openship logout`](/docs/cli/reference/logout) | Remove the stored Openship token |
| [`openship context`](/docs/cli/reference/context) | Manage connection contexts (list/use/add/rm) |
| [`openship token`](/docs/cli/reference/token) | Manage personal access tokens |
| [`openship access`](/docs/cli/reference/access) | Manage workspaces, members, invitations and resource grants |
| [`openship credential`](/docs/cli/reference/credential) | Manage stored registry and DNS credentials; reads return masked secrets |
| [`openship github`](/docs/cli/reference/github) | Connect GitHub, browse repositories and manage deployment sources |
| [`openship api`](/docs/cli/reference/api) | Make an authenticated request to any Openship API route (like `gh api`) |
## Deploy
| Command | Purpose |
| --- | --- |
| [`openship init`](/docs/cli/reference/init) | Link the current directory to an Openship project (.openship/project.json) |
| [`openship config`](/docs/cli/reference/config) | Author and validate openship.json (declarative deploy config) |
| [`openship deploy`](/docs/cli/reference/deploy) | Trigger a deployment for the current project |
| [`openship deployment`](/docs/cli/reference/deployment) | Manage deployments (list, inspect, redeploy, rollback, …) |
| [`openship logs`](/docs/cli/reference/logs) | View or stream a deployment's logs |
## Applications
| Command | Purpose |
| --- | --- |
| [`openship project`](/docs/cli/reference/project) | Manage Openship projects |
| [`openship app`](/docs/cli/reference/app) | Browse, install, and configure catalog apps |
| [`openship service`](/docs/cli/reference/service) | Manage the services in a compose stack (a multi-service project) |
| [`openship domain`](/docs/cli/reference/domain) | Manage custom domains, DNS verification, and SSL certificates |
| [`openship dns`](/docs/cli/reference/dns) | Manage DNS providers and zone access |
## Operations
| Command | Purpose |
| --- | --- |
| [`openship monitoring`](/docs/cli/reference/monitoring) | Inspect issues and workload health using the platform's monitoring operations |
| [`openship notification`](/docs/cli/reference/notification) | Manage notification channels, subscriptions and deliveries |
| [`openship webhook`](/docs/cli/reference/webhook) | Manage incoming deploy and job webhooks |
| [`openship audit`](/docs/cli/reference/audit) | Inspect audit events and retention settings |
| [`openship analytics`](/docs/cli/reference/analytics) | Read project traffic, deployments and runtime resource measurements |
| [`openship settings`](/docs/cli/reference/settings) | Manage user preferences on the selected Openship instance |
## Cloud
| Command | Purpose |
| --- | --- |
| [`openship billing`](/docs/cli/reference/billing) | Manage Cloud plans, server subscriptions, usage and payment checkouts |
## Infrastructure
| Command | Purpose |
| --- | --- |
| [`openship job`](/docs/cli/reference/job) | Manage self-hosted jobs, schedules, and run logs |
| [`openship server`](/docs/cli/reference/server) | Manage Cloud and self-hosted deployment servers |
| [`openship backup`](/docs/cli/reference/backup) | Manage backups: policies, runs, restores, destinations |
| [`openship edge`](/docs/cli/reference/edge) | Install and manage the OpenResty edge (reverse proxy, TLS, per-route rules) |
| [`openship mail`](/docs/cli/reference/mail) | Self-hosted mail server (iRedMail) setup and admin [self-host] |
| [`openship migration`](/docs/cli/reference/migration) | Discover, import, move and copy Docker workloads between authorized servers, including Cloud |
| [`openship system`](/docs/cli/reference/system) | Instance settings, onboarding, migration, and data transfer |
## Local installation
| Command | Purpose |
| --- | --- |
| [`openship up`](/docs/cli/reference/up) | Start Openship as a persistent service (boot + auto-restart); --foreground to run attached |
| [`openship stop`](/docs/cli/reference/stop) | Stop Openship (started by `openship up`) — it won't restart or return on reboot |
| [`openship status`](/docs/cli/reference/status) | Show the local Openship service (installed/running, ports) and the active context's API health |
| [`openship doctor`](/docs/cli/reference/doctor) | Check database + services health and repair a corrupt local database |
| [`openship open`](/docs/cli/reference/open) | Open the Openship dashboard in your browser |
| [`openship install`](/docs/cli/reference/install) | Download and install the Openship desktop app for this OS |
| [`openship update`](/docs/cli/reference/update) | Update the Openship CLI + bundled server to the latest release |
| [`openship uninstall`](/docs/cli/reference/uninstall) | Remove Openship from this machine: stop it, delete its data (database, certs, edge config), its images, and ~/.openship. Deployed apps are left running. |
| [`openship reset-admin-password`](/docs/cli/reference/reset-admin-password) | Reset the local admin login on THIS machine (no sign-in required) |
## Shell
| Command | Purpose |
| --- | --- |
| [`openship completion`](/docs/cli/reference/completion) | Generate shell completion scripts |
---
# SDK utilities
URL: https://openship.io/docs/api/sdk/utilities.md
Typed inputs, pagination, deployment helpers, and HTTP transport.
These utilities support the resource operations documented under [API](/docs/api).
## Typed inputs and results
Method inputs and results are exported by `openship`. Derive a specific operation's types when writing
a reusable integration:
```ts
import type { ProjectOperations } from "openship";
type CreateProjectInput = Parameters[0];
type Project = Awaited>;
export async function createProject(input: CreateProjectInput): Promise {
return ship.projects.create(input);
}
```
Do not import internal repository packages. The public package exports the operation types, contracts,
and SDK errors. `?` in an operation table marks an optional argument.
## Pagination
`iteratePages()` works with named list methods that return `{ data, total?, page?, perPage? }`:
```ts
import { iteratePages } from "openship";
for await (const project of iteratePages((page) => ship.projects.list(page), { perPage: 50 })) {
console.log(project.id, project.name);
}
```
Pass `signal` to stop iteration. Methods that return a plain array do not need this helper. Access is
checked by the underlying list operation on every page.
## Deployment helpers
Use `ship.deployment(id)` for a handle, or pass an operations object directly:
```ts
import { createDeploymentHandle, waitForDeployment, consumeDeploymentEvents } from "openship";
const handle = createDeploymentHandle(ship.deployments, "dep_123");
const status = await handle.status();
console.log(status.deploymentStatus);
export async function waitForRelease(deploymentId: string) {
return waitForDeployment(ship.deployments, deploymentId, { timeoutMs: 120_000 });
}
export async function printBuildLogs(deploymentId: string, signal: AbortSignal) {
return consumeDeploymentEvents(ship.deployments.events(deploymentId, { signal }), (event) => {
if (event.log) process.stdout.write(event.log);
});
}
```
`createDeploymentHandle()` exposes `id`, `get`, `status`, `wait`, `events`, `cancel`, `respond`, and
`rollback`. It does not own an installation. See [deployment outcomes and decisions](/docs/api/deployments#wait-decisions-and-cancellation).
## Compose normalization
`normalizeComposeServices(document, baseDirectory)` converts **normalized Compose JSON**, such as
`docker compose config --format json`, into the input expected by `services.sync()`.
```ts
import { normalizeComposeServices } from "openship";
const services = normalizeComposeServices(
{
services: { cache: { image: "redis:7" } },
},
"/absolute/path/to/project",
);
await ship.services.sync("proj_123", { services });
```
It validates unsupported mount, build, and namespace settings. Parse YAML and resolve Compose
interpolation before calling this helper. See [services](/docs/api/services#sync-from-docker-compose).
## HTTP transport
Only a remote `OpenshipClient` exposes `http`. Use it for documented endpoints without a named SDK method:
```ts
import type { OpenshipClient } from "openship";
export async function readImageCatalog(client: OpenshipClient) {
return client.http.request("/images");
}
```
`http.request(path, init?)` parses the JSON response body; `T` is your assertion, not runtime validation.
`http.raw(path, init?)` returns a `Response`. `http.events(path, options?)` reads an SSE stream, and
`http.url(path)` constructs an API URL. These helpers retain the client's URL, credential, and scope
restrictions. They do not add native support to an HTTP-only feature.
For error handling, see [SDK errors](/docs/api/sdk/errors).
---
# Users and organizations
URL: https://openship.io/docs/api/sdk/identity.md
Map your application users to Openship and keep each operation inside an authorized organization.
An organization is the resource boundary. A scope selects the organization and carries a verified user
identity. Supplying an organization ID does not grant access to it.
## Remote scopes
```ts title="remote-scopes.mts"
import type { OpenshipClient } from "openship";
export async function listProjectsFor(client: OpenshipClient, organizationId: string) {
return client.scope(organizationId).projects.list();
}
```
The API verifies the bearer credential and checks membership and grants. The client keeps the selected
organization fixed across requests. [Compatible server support](/docs/api/sdk/compatibility#fixed-organization-scopes) is required.
## Native identity adapter
The host supplies `identity.resolve(assertion)`. Return a `VerifiedIdentity` only after authenticating
the assertion; return `null` for an invalid or revoked session.
The SDK calls this adapter again for each operation. It also rereads persisted memberships and grants.
Removing a membership or revoking a host session invalidates an existing scope.
| Value | Supplied by |
| --- | --- |
| Assertion | Your application, such as a session identifier. |
| Verified user and session ID | Your trusted authentication adapter. |
| Organization ID | Your application chooses from organizations the user may access. |
| Roles and resource grants | Openship's persisted membership and permission model. |
For verified PAT/OAuth identities, the adapter may supply `tokenScope` and credential restrictions.
It must authenticate the credential before doing so. See [permissions](/docs/security/permissions).
## Provision a customer workspace
Enable `administration: true` for trusted host code. A namespace is a stable external key mapped to an
Openship organization:
```ts title="customer-workspace.mts"
import type { OwnedShip } from "openship";
export async function provisionCustomer(
ship: OwnedShip,
subject: string,
email: string,
) {
if (!ship.operator) throw new Error("Host administration is disabled");
const person = await ship.operator.ensureIdentity({ issuer: "my-product", subject, email });
const workspace = await ship.operator.ensureNamespace({
issuer: "my-product",
key: subject,
name: "Customer workspace",
ownerUserId: person.user.id,
});
return { person, organizationId: workspace.organizationId };
}
```
Both mappings persist. Email equality alone does not link existing accounts; explicit account linking
uses `userId`. Use `operator.setMembership()` to add or remove members. The final owner cannot be removed.
After your adapter verifies the user's session, call
`ship.scope({ identity: assertion, organizationId })`, then create or deploy projects through that scope.
The scope contains no operator methods.
## Background actions
Some saved actions continue after the initiating request. They use persisted authority and must still
pass current membership and credential checks. An external host session cannot be revalidated after
restart unless your integration synchronizes its revocation with persisted authority. See
[current background limits](/docs/api/sdk/compatibility#current-limits).
---
# Installation operator
URL: https://openship.io/docs/api/sdk/operator.md
Connect external identities and namespaces with explicit installation authority.
An operator is an installation capability for trusted host code. Ordinary `ScopedShip` objects do not
expose it. Enable `administration: true` when [creating a native installation](/docs/api/sdk/native) if
your host needs to provision identities or namespaces.
## Native operator
After startup, use `ownedShip.operator`. It provides these identity-management methods:
| Method | Purpose |
| --- | --- |
| `ensureIdentity({ issuer, subject, email, name?, instanceAdmin? })` | Create or resolve a stable external identity and personal organization. |
| `resolveIdentity({ issuer, subject })` | Read an existing identity mapping, or return `null`. |
| `ensureNamespace({ issuer, key, name, ownerUserId })` | Create or resolve a stable organization mapping. |
| `setMembership({ organizationId, userId, role })` | Set the member role; use `null` to remove membership. |
`issuer` and `subject` must come from your verified identity system. Keep this capability within the host
integration; tenant-supplied IDs do not establish identity. [Identity scopes](/docs/api/sdk/identity) shows
the complete mapping and scope flow.
## Remote operator
`OpenshipOperatorClient` uses an internal installation token and exposes notice administration:
```ts title="operator.mts"
import { OpenshipOperatorClient } from "openship";
const internalToken = process.env.OPENSHIP_INTERNAL_TOKEN;
if (!internalToken) throw new Error("Set OPENSHIP_INTERNAL_TOKEN");
export const operator = new OpenshipOperatorClient({
baseUrl: "https://ship.example.com",
internalToken,
});
```
It accepts the remote transport options except user `token` and `organizationId`. The token can also
be a sync or async provider. It does not expose the native identity-provisioning methods.
## Notices
Both operators provide `notices.listAll()`, `notices.create(input)`, and `notices.remove(id)`.
See [Public notices](/docs/api/notices) for the shared fields and SDK/REST examples.
---
# Install the SDK
URL: https://openship.io/docs/api/sdk/installation.md
Install Ship SDK from npm and use its JavaScript, TypeScript, and CLI entry points.
Requires **Node.js 22 or later**. ESM, CommonJS, and TypeScript declarations are included.
## Install from npm
The `openship` package includes Ship SDK and the CLI starting with **0.8.0**:
```bash
npm install openship
```
If your project has an older CLI-only version, upgrade the local dependency:
```bash
npm install openship@latest
npm ls openship
```
Versions before 0.8.0 do not include the SDK entry points. Upgrading the package does not upgrade
a remote OpenShip server; see [server compatibility](/docs/api/sdk/compatibility#fixed-organization-scopes).
## Test changes from source
Contributors can build and install a local package without publishing it:
1. Build the public package from the repository root:
```bash
bun install --frozen-lockfile
bun run build:sdk
```
2. Create a tarball. Use the filename printed by `npm pack`:
```bash
cd packages/openship
npm pack
```
3. Install that tarball in your Node project:
```bash
npm install /absolute/path/to/openship-0.8.0.tgz
```
Use the actual tarball filename printed by `npm pack`; it follows the checkout's package version.
## Choose an import
| Import | Provides |
| --- | --- |
| `openship` | Native factory, remote clients, deployment helpers, public types, and errors. |
| `openship/client` | Remote clients and HTTP helpers. |
| `openship/native` | Native factory, identity types, lifecycle options, and scoped operations. |
```ts title="imports.mts"
import { createShip, OpenshipClient } from "openship";
import type { ScopedShip, ProjectOperations } from "openship";
```
```js title="imports.cjs"
const { OpenshipClient } = require("openship/client");
const { createShip } = require("openship/native");
```
Imports are passive. An import does not start the CLI, open a database, or create a worker.
## Use the CLI from the same installation
```bash
npx openship --help
```
Installing the dependency locally provides both application imports and the command through `npx` or
npm scripts. A global CLI installation does not replace your application's local dependency.
Continue with [remote setup](/docs/api/sdk/client), [native setup](/docs/api/sdk/native), or the
[runnable example](/docs/api/sdk/examples). See [compatibility](/docs/api/sdk/compatibility) for server requirements.
---
# Lifecycle and configuration
URL: https://openship.io/docs/api/sdk/lifecycle.md
Configure native storage, providers, execution policy, and orderly shutdown.
Keep one native installation open for the lifetime of the application that owns it.
## Lifecycle
| Call | Effect |
| --- | --- |
| `await createShip(options)` | Initialize the owned worker, storage, and providers. |
| `await ship.start()` | Enable operations and any explicitly configured scheduling. |
| `await ship.scope({ identity, organizationId })` | Create an authorized user/organization view. |
| `await ship.close({ mode: "drain" })` | Refuse new mutations, drain owned work, and release resources. |
Use `try/finally` around work or close during your application's shutdown. A scope does not own the
installation. Closing an installation does not delete its database or project configuration.
## Required configuration
| Option | Requirement |
| --- | --- |
| `instanceId` | Stable installation ID; reuse it when reopening. |
| `stateDirectory` | Absolute private directory for source, releases, and provider state. |
| `storage` | Explicit PGlite or PostgreSQL configuration. |
| `encryptionKey` | Persistent UTF-8 secret of 32–4096 bytes. |
| `runtime` | `bare`, `docker`, or `cloud`. |
| `identity` | Trusted identity adapter; see [identity setup](/docs/api/sdk/identity). |
The database is bound to its installation ID and key fingerprint. A different ID or key is rejected
when reopening. Storage never defaults to the CLI's existing database.
## Storage
| Driver | Configuration | Migration behavior |
| --- | --- | --- |
| PGlite | `{ driver: "pglite", dataDir: "/absolute/path/database" }` | Applies bundled migrations by default. |
| In-memory PGlite | `{ driver: "pglite", dataDir: "memory://" }` | Ephemeral state for tests or short-lived installations. |
| PostgreSQL | `{ driver: "postgres", url, migrations: "verify" }` | Verifies migrations by default; choose `"apply"` explicitly to apply them. |
Use `migrations: "verify"` when reopening an already migrated installation. `stateDirectory` and
PGlite's `dataDir` are separate settings. Preserve both and the encryption key for persistent use.
## Providers and policy
| Option | Effect |
| --- | --- |
| `routing` | `"managed"` by default; `"none"` is available with the bare runtime. |
| `cloud` | Explicit Cloud provider credentials and optional hosted configuration. |
| `policy.allowHostExecution` | Allow local builds, host administration, and host SSH facilities. Disabled by default. |
| `policy.sourceRoots` | Absolute directories from which native directory sources may be imported. |
| `policy.allowLocalForwarding` | Allow loopback listeners that forward to authorized remote servers. |
| `administration` | Expose trusted `ship.operator` methods. Disabled by default. |
| `jobs` | Enable the retained job/backup scheduler at startup. Disabled by default. |
| `recovery` | `"none"` or exclusive recovery for an owned, file-backed PGlite process. |
| `diagnostics` | `"inherit"`, `"stderr"`, or `"silent"` engine diagnostics. |
| `environment` | Additional provider settings; reserved storage, identity, and ownership fields cannot be overridden. |
| `caller` | Trusted call attribution: `source` (`"api"` or `"cli"`) and `userAgent`. It does not grant permissions. |
See [compatibility](/docs/api/sdk/compatibility) before enabling scheduling or Cloud forwarding.
## Shutdown deadlines
`close({ mode: "drain", timeoutMs })` limits how long the caller waits. A timeout rejects that wait;
owned work continues draining. Do not delete installation files while it is still closing.
Cancelling a deployment wait also stops observation only. Use `deployment(id).cancel()` to request
execution cancellation and inspect its resulting status.
## Attach to an existing kernel
Advanced hosts that already own a `PlatformKernel` can call `createShip({ platform, identity })`.
This overload returns a synchronous facade. It does not start or close caller-owned resources.
Most integrations should use the owned factory shown in [native setup](/docs/api/sdk/native).
---
# Compatibility and availability
URL: https://openship.io/docs/api/sdk/compatibility.md
Check package availability, API protocol support, provider requirements, and current limits.
## Package availability
Ship SDK is published in **`openship` 0.8.0 and later**. Install it with `npm install openship`;
upgrade an older CLI-only dependency with `npm install openship@latest`. Node.js 22 or later is
required. See [installation](/docs/api/sdk/installation) for the public import paths and local builds.
## Fixed organization scopes
A remote client with `organizationId` checks `/api/health` for this capability before sending a scoped
application request:
```json
{ "sdk": { "protocol": 1, "fixedOrganizationScope": true } }
```
The client sends `X-Organization-Id` and `X-Openship-Scope: fixed`. The API authenticates the caller,
checks current membership and grants, and keeps access inside that organization. Request headers cannot
override the client's configured scope.
An incompatible server causes `SDK_SCOPE_UNSUPPORTED`. Upgrade it. Removing `organizationId` changes
the scope guarantee. A malformed scope header or `fixed` without an organization is rejected with
`400 VALIDATION_ERROR`.
## Cloud
Use the canonical Cloud API, a Cloud credential, and its organization ID. The deployed API must pass
the same capability check; SDK support in a checkout does not establish support on a deployed server.
A self-hosted owner's Cloud account link does not authorize a local credential to manage Cloud-stored
project records. Fixed requests and organization-bound or scoped credentials refuse that forwarding
with `CLOUD_SCOPE_UNAVAILABLE`, including when the caller omits `organizationId`.
Desktop and self-hosted clients can deploy their local projects on a connected managed server: select
its local `serverId` when creating the project and use `buildStrategy: "server"`. Project and server
permissions are checked locally against the verified Cloud server binding. This does not transfer
project records; see the [desktop Cloud workflow](/docs/api/mcp#deploy-a-desktop-folder-on-cloud).
Cloud operations also require the relevant provider and account capabilities.
## Current limits
| Area | Status |
| --- | --- |
| Named operations | The [reference](/docs/api) covers all current native and remote groups. Provider and permission checks still apply. |
| Clusters and scaling | Named operations cover private networks, compute-cluster setup, application replicas, PostgreSQL/Redis databases, shared files, and their backup/recovery flows. Infrastructure management is self-hosted only; a ready runtime and the relevant storage/backup configuration are required. See [servers](/docs/api/servers#compute-clusters) and [projects](/docs/api/projects#scale-a-stateless-application-on-a-cluster). |
| Mail, workload migration and archives | Named remote groups `mail`, `migrations` and `instance` use the existing controllers. They are not native groups. Mail and whole-instance administration require a self-hosted controller. |
| Terminals | Remote `terminal.openServer` and `terminal.openService` use one-use tickets and the server's WebSocket protocol. Node callers supply the trusted dashboard `origin`; scripts can use `servers.exec` or `services.exec`. |
| Account and installation protocols | Browser login/2FA, private support, signed provider callbacks and internal installation bootstrap retain their dedicated credentials. PATs do not bypass session or instance authority. |
| Legacy controller migration | `instance.preflightMigration` and `migrateToServer` preserve the existing API's readiness/unavailable results. Workload `migrations` is a separate, supported workflow. |
| Native CLI | Resource commands support native mode; some commands and system actions require HTTP. See [native CLI support](/docs/cli/native#supported-commands). |
| Background work | Native scheduling is disabled by default. Constrained saved principals for all jobs/backups/scans and distributed scheduler ownership remain incomplete. |
| Dispatch and replay | Durable multi-worker dispatch, idempotent replay, and event replay across restarts remain incomplete. |
| Billing | Account/payment features need configured hosted billing. Full webhook replay and accounting transaction guarantees remain under migration. |
| Cloud record transfers | Require an unscoped local session with transfer permission. Fixed SDK scopes and bound/scoped credentials use a direct Cloud connection for Cloud-stored records, or a connected managed server for locally controlled projects. |
Browser login redirects, session cookies, webhook signatures, and terminal handshakes remain their
respective transport protocols. Native imports do not replace those protocols.
## What has been checked
The public tarball has installed-package checks on Node 22 and 24, including native deployment,
persistence, resource teardown, ESM/CommonJS, declarations, and CLI invocation. See the
[runnable example](/docs/api/sdk/examples). Live provider verification remains a separate release gate.
---
# Runnable examples
URL: https://openship.io/docs/api/sdk/examples.md
Run the installed SDK through a complete local project lifecycle.
The package includes an executable example that uses public imports, real storage, and the shared
deployment pipeline.
## Run the native lifecycle
After [installing `openship`](/docs/api/sdk/installation) in a Node project:
```bash
node node_modules/openship/examples/native-lifecycle.mjs
```
Copy that file into your project to adapt it. The example:
1. Provisions two users and selects their organization scopes.
2. Deploys generated HTML and waits for a ready release.
3. Updates configuration and deploys new files into the same project.
4. Checks deployment history, tenant isolation, and session revocation.
5. Closes and reopens persistent storage, then checks saved configuration and masked secrets.
6. Deletes the project, drains the installation, and removes its temporary state.
Assertions fail the process if a step does not behave as expected. The example creates its own
temporary directory and needs no API credential, Docker daemon, or external database.
## What it verifies
The installed-package checks run this exact file outside the repository on Node 22 and 24 and
typecheck it against the public declarations. Related package probes check release-file contents,
reopening, physical cleanup, ESM/CommonJS imports, and the installed CLI.
The example uses the bare runtime with `routing: "none"`, so it does not serve a public URL.
Live Cloud, Docker, SSH, and public routing are separate integration checks.
## Adapt a smaller workflow
| Task | Example |
| --- | --- |
| Connect to your installation | [Remote client](/docs/api/sdk/client#connect) |
| Deploy your application directory | [Complete remote example](/docs/api/sdk#deploy-your-application) |
| Embed a persistent installation | [Native setup](/docs/api/sdk/native#create-an-installation-and-deploy) |
| Create a customer workspace | [Identity provisioning](/docs/api/sdk/identity#provision-a-customer-workspace) |
| Deploy generated files or a directory | [Deployment workflows](/docs/api/deployments) |
| Handle errors or stream logs | [Results and errors](/docs/api/sdk/errors) |
| Scale apps, databases, and shared files | [Scaling with the SDK](/docs/api/sdk#scale-and-operate) |
| Use the CLI against native storage | [Native CLI](/docs/cli/native) |
---
# Ship SDK
URL: https://openship.io/docs/api/sdk.md
Deploy and manage Openship from JavaScript or TypeScript.
Ship SDK lets you deploy and operate OpenShip from JavaScript or TypeScript. The `openship` package
includes remote clients, an embeddable native engine, and the CLI. Native SDK calls and HTTP
controllers use the same shared core.
## Choose a mode
| Mode | Use when | Start here |
| --- | --- | --- |
| **Remote client** | Openship already runs on a server or in Cloud. | [Connect to an API](/docs/api/sdk/client) |
| **Native SDK** | Your Node application owns storage, providers, and the installation lifecycle. | [Embed Openship](/docs/api/sdk/native) |
Both modes expose the same named operation groups. A configured provider and the caller's permissions
determine which operations can run.
## Install
The SDK is published in **`openship` 0.8.0 and later** and requires Node.js 22 or later:
```bash
npm install openship
```
See [installation](/docs/api/sdk/installation) for ESM, CommonJS, and upgrading an older CLI-only package.
## Deploy your application
Replace the URL with your OpenShip API, set `OPENSHIP_TOKEN` and `OPENSHIP_ORGANIZATION_ID` for an
organization where you can create and deploy projects, and put your application in `./app`.
The installation must already have a configured deployment target.
```ts title="deploy-app.mts"
import { resolve } from "node:path";
import { OpenshipClient } from "openship/client";
const ship = new OpenshipClient({
baseUrl: "https://ship.example.com",
token: process.env.OPENSHIP_TOKEN!,
organizationId: process.env.OPENSHIP_ORGANIZATION_ID!,
});
const run = await ship.deploy({
name: "commerce-api",
source: { type: "directory", path: resolve("./app") },
onStep: console.log,
});
const result = await ship.deployment(run.deployment_id)
.wait({ timeoutMs: 120_000 });
if (!result.success) throw new Error(result.status);
console.log("Ready:", run.project_id);
```
Save this as `deploy-app.mts` and run it with a TypeScript runner such as `npx tsx deploy-app.mts`.
`deploy()` uploads a snapshot of the directory, detects its build configuration, and submits the
deployment. `wait()` checks the saved outcome; a failed, cancelled, or action-required deployment
does not print the success message. Adjust its timeout for your application's build time.
Pass `serverId` to `deploy()` to select a registered server. For later updates, pass
`projectId: run.project_id` to deploy into the same project. See [remote setup](/docs/api/sdk/client)
for token and organization configuration and [deployment decisions](/docs/api/deployments#wait-decisions-and-cancellation)
for handling a request for review.
## A deployment in code
This function accepts either a remote client or a native user scope:
```ts title="deploy-site.mts"
import type { OpenshipClient, ScopedShip } from "openship";
export async function deploySite(ship: OpenshipClient | ScopedShip) {
const submitted = await ship.deploy({
name: "my-site",
source: { type: "files", files: { "index.html": "
Hello from Openship
" } },
});
const outcome = await ship.deployment(submitted.deployment_id).wait({ timeoutMs: 120_000 });
if (!outcome.success) throw new Error(outcome.message ?? outcome.status);
return ship.projects.get(submitted.project_id);
}
```
## Next steps
## Scale and operate
Both clients expose the current named operations in the shared [method reference](/docs/api).
For self-hosted infrastructure, start with a private network and a ready compute cluster:
| Task | Guide |
| --- | --- |
| Connect servers and prepare a cluster | [Private networking](/docs/api/servers#server-clusters-and-private-networking) and [compute clusters](/docs/api/servers#compute-clusters) |
| Run an application across servers | [Application replicas](/docs/api/projects#scale-a-stateless-application-on-a-cluster) |
| Create or grow PostgreSQL and Redis databases | [Database lifecycle](/docs/api/projects#add-import-or-recover-a-database) |
| Share files between application instances | [Cluster storage](/docs/api/servers#share-files-across-servers) and [project volumes](/docs/api/projects#share-application-files) |
| Follow logs, back up, and recover | [Deployment workflows](/docs/api/deployments), [backups](/docs/api/backups), and [errors and streams](/docs/api/sdk/errors) |
Cluster management uses self-hosted servers. Other operations depend on the selected provider and
your permissions. See [compatibility and current limits](/docs/api/sdk/compatibility) for native,
Cloud, and HTTP-only capabilities.
---
# Embed Openship
URL: https://openship.io/docs/api/sdk/native.md
Create a native installation and deploy through shared platform operations.
Use `createShip()` when your Node application owns the installation. It creates an isolated worker,
storage, and providers. Native operations call the shared engine without an API HTTP listener.
## Create an installation and deploy
[Install the SDK](/docs/api/sdk/installation), then set `OPENSHIP_ENCRYPTION_KEY` to a persistent
secret of at least 32 bytes. Keep that key when reopening the database.
```ts title="native.mts"
import { randomUUID } from "node:crypto";
import { resolve } from "node:path";
import { createShip, type VerifiedIdentity } from "openship/native";
const encryptionKey = process.env.OPENSHIP_ENCRYPTION_KEY;
if (!encryptionKey) throw new Error("Set OPENSHIP_ENCRYPTION_KEY");
const sessions = new Map();
const stateDirectory = resolve("./ship-state");
const ship = await createShip({
instanceId: "my-product",
stateDirectory,
storage: { driver: "pglite", dataDir: resolve(stateDirectory, "database") },
encryptionKey,
runtime: "bare",
routing: "none",
policy: { allowHostExecution: true },
administration: true,
identity: { resolve: async (assertion: string) => sessions.get(assertion) ?? null },
});
try {
if (!ship.operator) throw new Error("Host administration is required for this example");
const person = await ship.operator.ensureIdentity({
issuer: "my-product",
subject: "customer-123",
email: "customer@example.com",
});
const assertion = randomUUID();
sessions.set(assertion, { user: person.user, sessionId: assertion });
await ship.start();
const customer = await ship.scope({
identity: assertion,
organizationId: person.personalOrganizationId,
});
const submitted = await customer.deploy({
name: "generated-app",
source: { type: "files", files: { "index.html": "
Hello
" } },
});
const outcome = await customer
.deployment(submitted.deployment_id)
.wait({ timeoutMs: 60_000 });
if (!outcome.success) throw new Error(outcome.message ?? outcome.status);
console.log(submitted.project_id, outcome.status);
} finally {
await ship.close({ mode: "drain" });
}
```
This uses a demo session map. An embedding application should verify assertions through its own
authentication service; see [identities and scopes](/docs/api/sdk/identity).
## Runtime choices
| Choice | Behavior |
| --- | --- |
| `bare` with `routing: "none"` | Build and manage local workloads without setting up managed routing. A static release has no public URL. |
| `bare` or `docker` with managed routing | Use the existing local runtime and edge providers. Host setup requires explicit execution policy. |
| Registered server or Cloud provider | Use configured infrastructure and its capability checks. See [compatibility](/docs/api/sdk/compatibility). |
`allowHostExecution: true` permits host builds. Organization scopes authorize operations; they do not
sandbox generated application code. Choose providers suitable for the workloads your application accepts.
## Continue
- [Lifecycle and configuration](/docs/api/sdk/lifecycle): storage, keys, startup, and shutdown.
- [Users and organizations](/docs/api/sdk/identity): verified identities and tenant scopes.
- [Runnable example](/docs/api/sdk/examples): deploy twice, reopen state, and remove the project.
- [Operator reference](/docs/api/sdk/operator): trusted installation administration.
---
# Connect to an API
URL: https://openship.io/docs/api/sdk/client.md
Configure a remote SDK client for a self-hosted or Cloud Openship API.
Use `OpenshipClient` when the installation already exists. It needs an API URL, a bearer token, and the
organization your integration should operate in. [Install the SDK](/docs/api/sdk/installation) first.
## Connect
```ts title="client.mts"
import { OpenshipClient } from "openship/client";
const token = process.env.OPENSHIP_TOKEN;
const organizationId = process.env.OPENSHIP_ORGANIZATION_ID;
if (!token || !organizationId)
throw new Error("Set OPENSHIP_TOKEN and OPENSHIP_ORGANIZATION_ID");
export const ship = new OpenshipClient({
baseUrl: "https://ship.example.com",
token,
organizationId,
});
const projects = await ship.projects.list({ page: 1, perPage: 20 });
console.log(projects.data);
```
Create a personal access token in **Settings → Tokens** or with the [CLI](/docs/cli/access).
The remote client requires no `start()` or `close()`.
## Options
| Option | Use |
| --- | --- |
| `baseUrl` | HTTP(S) instance URL. `/api` suffixes and reverse-proxy prefixes are supported. |
| `token` | Bearer token, or a sync/async function returning a token for each request. |
| `organizationId` | Fix all application requests to this organization. |
| `timeoutMs` | Request deadline in milliseconds; `0` disables it. Streams have separate abort signals. |
| `userAgent` | Identify your application, for example `my-product/1.0`. |
| `fetch` | Supply a fetch implementation for a custom transport or tests. |
Credentials, query strings, and fragments are not allowed in `baseUrl`. Requests do not follow redirects.
Mutations are submitted once; the client does not automatically retry them.
## Organization scope
`client.scope(organizationId)` creates a new client without changing the original. The token must
already have access to that organization. A token bound to one organization cannot select another.
An explicit organization requires a compatible server. See [fixed scopes](/docs/api/sdk/compatibility#fixed-organization-scopes).
Omitting it uses the API's default/resource-derived scope; it does not provide the same tenant pinning.
## Openship Cloud
Use `https://api.openship.io` as `baseUrl`, your Cloud token, and the Cloud organization's ID.
The deployed Cloud API must support the SDK protocol. A self-hosted Cloud account link does not
currently map a fixed local scope into a Cloud scope; see [Cloud compatibility](/docs/api/sdk/compatibility#cloud).
## Results and additional HTTP endpoints
Named methods return application data: `projects.get(id)` returns a project; `projects.list()` returns
a page containing `data`, `total`, `page`, and `perPage`.
For an endpoint without a named SDK method, use `client.http.request()` or `client.http.raw()`.
These return the HTTP JSON body or `Response`, respectively. They keep the client's URL, credentials,
and scope restrictions. Native scopes do not expose this HTTP transport.
See [errors and streams](/docs/api/sdk/errors), [HTTP helpers](/docs/api/sdk/utilities), and
[operator access](/docs/api/sdk/operator).
---
# Results, errors, and streams
URL: https://openship.io/docs/api/sdk/errors.md
Handle operation failures, deployment outcomes, pagination, and cancellation.
An operation can fail immediately, or it can submit work that later finishes unsuccessfully. Handle
both the call and the final deployment outcome.
## Operation errors
```ts title="operation-errors.mts"
import { OperationError, type OpenshipClient, type ScopedShip } from "openship";
export async function readProject(ship: OpenshipClient | ScopedShip, projectId: string) {
try {
return await ship.projects.get(projectId);
} catch (error) {
if (error instanceof OperationError) {
console.error(error.statusCode, error.code, error.message);
}
throw error;
}
}
```
`OperationError` exposes `statusCode`, `code`, and public `details`. Remote `ApiError` also exposes
`status` and the HTTP response `body`. Input validation can throw `ValidationError`; network,
configuration, and abort failures may be other error types.
| Case | Response |
| --- | --- |
| Invalid input | Fix the reported fields; do not repeat the same input. |
| Missing or inaccessible resource | Check the ID, identity, and organization. Inaccessible resources can appear as `NOT_FOUND`. |
| Expired or revoked identity | Authenticate again through your host or remote login flow. |
| Unsupported fixed scope | Upgrade the API; see [compatibility](/docs/api/sdk/compatibility). |
| Rate limit | Observe the API's retry guidance. |
| Lost mutation response | Inspect stored state before resubmitting; mutations are not retried automatically. |
See [HTTP errors](/docs/api/http#error-shape) for transport status codes.
## Deployment outcomes
`deploy()` returns IDs. `deployment(id).wait()` returns an outcome with `status`, `success`, and any
pending prompt or cancellation. `ready` and `no_changes` are successful outcomes. A failed or
partially failed deployment does not become successful because its log stream ended.
Handle an `action_required` prompt explicitly, or supply an `onPrompt` callback that returns one of
the offered action IDs. See [deployment decisions](/docs/api/deployments#wait-decisions-and-cancellation).
## Streams
Stream methods return async iterables. Pass an abort signal or stop iteration to release a stream:
```ts title="stream-logs.mts"
import { consumeDeploymentEvents, type OpenshipClient, type ScopedShip } from "openship";
export async function watchLogs(
ship: OpenshipClient | ScopedShip,
deploymentId: string,
signal: AbortSignal,
) {
return consumeDeploymentEvents(ship.deployment(deploymentId).events({ signal }), (event) => {
if (event.log) process.stdout.write(event.log);
});
}
```
Aborting a stream or wait does not cancel the underlying workload. Request that separately with
`deployment(id).cancel()`. Durable replay across worker restarts is not currently supported.
## Pagination
```ts title="all-projects.mts"
import { iteratePages, type OpenshipClient, type ScopedShip } from "openship";
export async function allProjects(ship: OpenshipClient | ScopedShip, signal?: AbortSignal) {
const ids: string[] = [];
for await (const project of iteratePages((page) => ship.projects.list(page), {
perPage: 50,
signal,
})) {
ids.push(project.id);
}
return ids;
}
```
Use `iteratePages` with methods returning a page containing `data`. Methods that return plain arrays
do not use this helper. Authorization applies to every page.
---
# up
URL: https://openship.io/docs/cli/reference/up.md
Commands, arguments, and options for openship up.
See the [CLI overview](/docs/cli) for examples. Global flags such as `--json` go before the command; see [global options](/docs/cli/reference#global-options).
## openship up
Start Openship as a persistent service (boot + auto-restart); --foreground to run attached
```text
openship up [options]
```
| Option | Meaning |
| --- | --- |
| `--port ` | API port to listen on (default: 4000, or the next free port if it's taken) |
| `--data-dir ` | Directory for the embedded database |
| `--dashboard-port ` | Dashboard port (default: 3001, or the next free port if it's taken) |
| `--no-ui` | Run the API only — don't download/serve the dashboard |
| `--ui-version
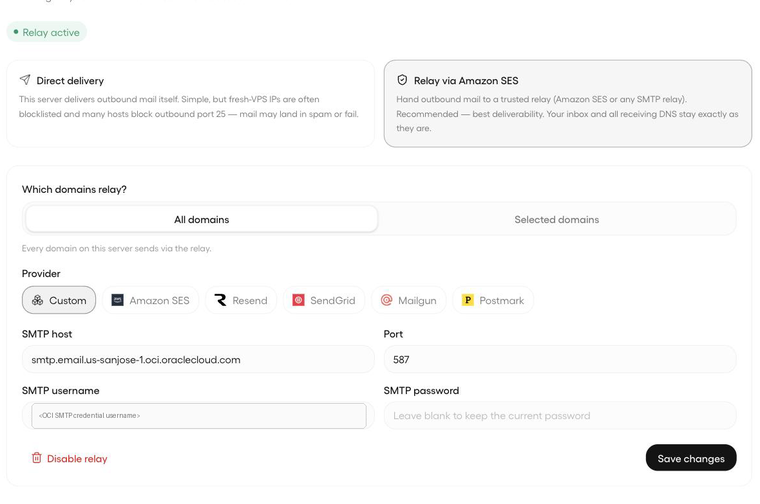 ## Gotchas / good to know
- **Approved senders are mandatory, not optional.** OCI's own docs put it plainly: "An approved sender must be
set up for all From: addresses sending mail through Oracle Cloud Infrastructure, or mail is rejected" ([OCI
docs](https://docs.oracle.com/en-us/iaas/Content/Email/Tasks/managingapprovedsenders.htm)). Register each
address individually, or — once DKIM is active for the Email Domain — register the whole domain at once with
an approved sender of the form `@yourdomain.com` ([OCI
docs](https://docs.oracle.com/en-us/iaas/Content/Email/Reference/gettingstarted_topic-Create_an_approved_sender.htm)),
which covers every mailbox in one shot.
- **The SMTP credential password only appears once.** The OCI Console shows it at creation time and never
again — if you lose it, the only fix is regenerating a new one.
- **Port 25 is blocked by default, and that's fine.** OCI blocks outbound port 25 on tenancies created after
June 2021. You can request a service-limits exemption if you need it, but relaying through OCI's SMTP relay on
port 587 sidesteps that wait entirely — and as a bonus, your mail leaves from Oracle's well-reputed IPs
instead of a fresh cloud IP that inbox providers are naturally suspicious of.
- **You can skip the PTR chore.** PTR (reverse DNS) is the record that maps a server's IP back to a hostname,
and large mail providers often junk mail from IPs that don't have one. Because your outbound mail actually
leaves through Oracle's relay IPs — which already have proper PTR records — your own instance's IP never
needs one.
---
# Email & webmail
URL: https://openship.io/docs/guides/email-webmail.md
Connect existing IMAP/SMTP mailboxes through webmail on Cloud, or run and manage your own mail server with Desktop and self-hosted Openship.
import { Step, Steps } from 'fumadocs-ui/components/steps';
Most people rent their email from someone else — Gmail, Outlook, and the like. Openship lets you run the
whole post office yourself: a real mail server on your own machine, with your own domain, that sends and
receives mail and even gives you a webmail inbox in the browser. Think of it as the difference between renting
a PO box and owning the building.
You're not limited to one, either. Each mail server runs on its own host (one mail setup per server), and
Openship keeps them all in a single **Mail servers** list — provision as many as you like and switch between
them from one place. A lone server opens straight into its admin panel; once you have more than one, you land
on the list first.
This is a big, hands-on feature, so this guide stays at the map level: what each screen does and the order you
go through them. The fiddly bits — the exact DNS records and the reverse-DNS setup — are called out where they
happen, because the wizard walks you through those live.